
In the rapidly evolving landscape of Tech & Innovation, particularly within the domains of AI, autonomous flight, sophisticated mapping, and remote sensing, the Graphics Processing Unit (GPU) stands as a foundational pillar. These specialized processors are not just for rendering video games; they are the workhorses behind complex computations, parallel processing tasks, and the rapid analysis of vast datasets that characterize modern technological advancements. For professionals leveraging GPUs in these critical applications – whether it’s processing gigabytes of drone photogrammetry data, training machine learning models for AI follow mode, or real-time analysis for autonomous navigation – understanding and managing GPU temperature is not merely a technical detail; it is a critical factor directly impacting performance, reliability, and the longevity of high-investment hardware.
The Critical Role of GPUs in Modern Tech & Innovation
GPUs are fundamentally designed for parallel processing, executing numerous calculations simultaneously. This architecture makes them exceptionally adept at tasks that are compute-intensive and highly parallelizable, which are hallmarks of cutting-edge tech innovation.
Powering AI and Autonomous Systems
Artificial Intelligence (AI) and machine learning (ML) models, from deep neural networks enabling sophisticated object recognition for autonomous flight to predictive analytics for optimizing drone flight paths, rely heavily on GPU acceleration. Training these models involves iterating through enormous datasets, performing millions of matrix multiplications and other mathematical operations. A well-performing GPU significantly reduces training times from weeks to days or even hours, accelerating research and development cycles. For real-time applications like AI follow mode or on-board processing for obstacle avoidance, sustained GPU performance is paramount to ensuring instantaneous decision-making and operational safety.
Accelerating Mapping and Remote Sensing
The explosion of drone technology has revolutionized mapping and remote sensing. Drones equipped with high-resolution cameras, LiDAR, and multispectral sensors capture vast amounts of data. Processing this data – whether it’s generating detailed 3D models from photogrammetry, creating orthomosaic maps, or analyzing spectral signatures for agricultural or environmental monitoring – is a computationally arduous task. Software like Pix4D, Agisoft Metashape, and various GIS platforms leverage GPUs to dramatically speed up point cloud generation, meshing, texture mapping, and image stitching. Without efficient GPU processing, these tasks would be prohibitively time-consuming, hindering project timelines and data delivery.
Understanding Optimal GPU Operating Temperatures
For these demanding applications, a GPU operating within its optimal temperature range is crucial for achieving peak performance and ensuring system stability. Straying too far from this ‘sweet spot’ can lead to a cascade of negative consequences.
The ‘Sweet Spot’ for Performance and Longevity
Generally, GPUs are designed to operate safely and effectively within a specific temperature window. For most modern GPUs, an idle temperature might be anywhere from 30°C to 50°C. Under load, such as during intense AI training or photogrammetry processing, temperatures typically range between 60°C and 80°C. Some high-performance cards can safely reach into the low 80s (80-85°C) without immediate concern, though consistently hitting the higher end might suggest room for cooling improvement. The “sweet spot” is usually considered to be in the 65°C to 75°C range under full load, where the GPU can maintain its boost clocks efficiently without thermal throttling or undue stress. Staying within this range ensures the silicon’s longevity and prevents premature degradation of components.
Why Overheating is a Major Concern
Exceeding optimal temperatures for extended periods can lead to several critical issues:
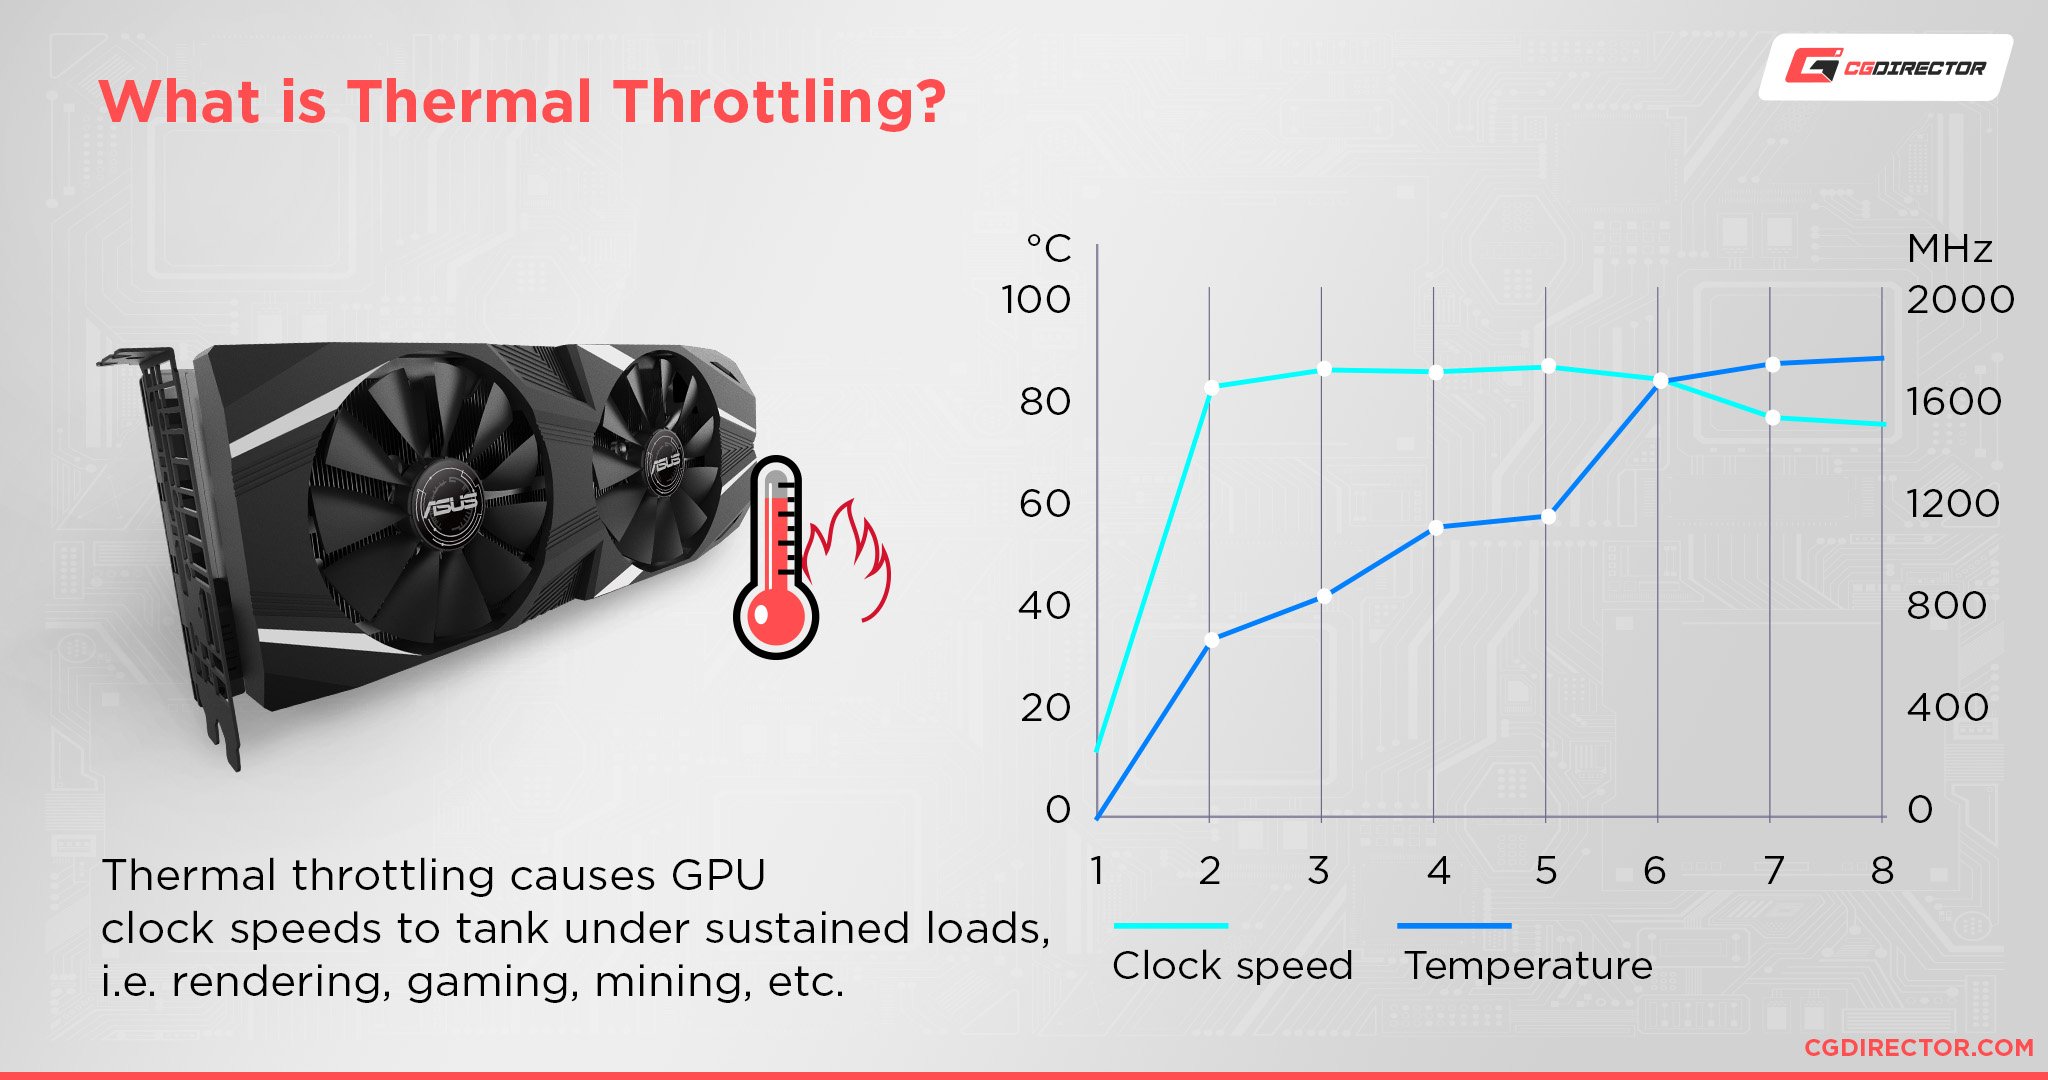
- Thermal Throttling: When a GPU gets too hot, its internal sensors detect the excessive heat and automatically reduce its clock speed (and thus its performance) to lower power consumption and generate less heat. This “thermal throttling” directly impacts project timelines, turning what should be a fast processing job into a prolonged, inefficient one. For real-time applications, it can lead to lag, instability, or even critical failure.
- System Instability and Crashes: Severely overheated GPUs can cause system instability, leading to application crashes, blue screens of death (BSODs), or even complete system shutdowns. In the middle of an intensive AI model training session or a complex photogrammetry render, such interruptions can mean lost progress and significant wasted time.
- Reduced Hardware Lifespan: Prolonged exposure to high temperatures accelerates the degradation of the GPU’s delicate components, including the silicon die, solder joints, and capacitors. This can lead to premature hardware failure, necessitating costly replacements and causing unexpected downtime.
- Data Integrity Issues: While less common, extreme thermal stress can, in rare cases, contribute to errors in computations or data corruption, especially in complex scientific or mapping applications where precision is paramount.
Factors Influencing GPU Temperature in Demanding Workloads
Several interconnected factors dictate a GPU’s operating temperature, especially when pushed to its limits by cutting-edge applications.
Hardware Specifications and Cooling Solutions
The fundamental design of the GPU itself plays a significant role. High-end GPUs, while more powerful, also generate more heat. Their cooling solutions – including heatsinks, fans, vapor chambers, or even liquid cooling systems – are designed to dissipate this heat effectively. A robust, well-engineered cooling system is paramount for GPUs used in continuous, high-load environments typical of AI development or large-scale mapping. The thermal design power (TDP) of the GPU, its core clock speeds, and the quality of its thermal paste and pads all contribute to its inherent thermal characteristics.
Software Workload Intensity and Duration
The nature of the task directly impacts heat generation. Training a deep learning model for hours on end, performing a complex photogrammetry reconstruction of a large area, or running scientific simulations are all examples of workloads that push the GPU to 99-100% utilization. Sustained high utilization generates significantly more heat than intermittent bursts of activity. The efficiency of the software and drivers can also play a role; poorly optimized code might cause unnecessary load, leading to higher temperatures.
Environmental Conditions
The ambient temperature of the room where the workstation or server is located is a crucial, yet often overlooked, factor. A GPU that runs at 70°C in an air-conditioned office might easily hit 85°C or higher in a warmer room with poor ventilation. Dust accumulation within the computer case can also severely impede airflow, acting as an insulating layer that traps heat. Similarly, the overall airflow within the computer case – determined by case design, fan configuration, and cable management – significantly influences how effectively hot air is exhausted and cool air is drawn in.
Best Practices for Maintaining Healthy GPU Temperatures
Proactive management of GPU temperatures is essential for maximizing performance and extending the lifespan of hardware vital to Tech & Innovation projects.
Monitoring and Alert Systems
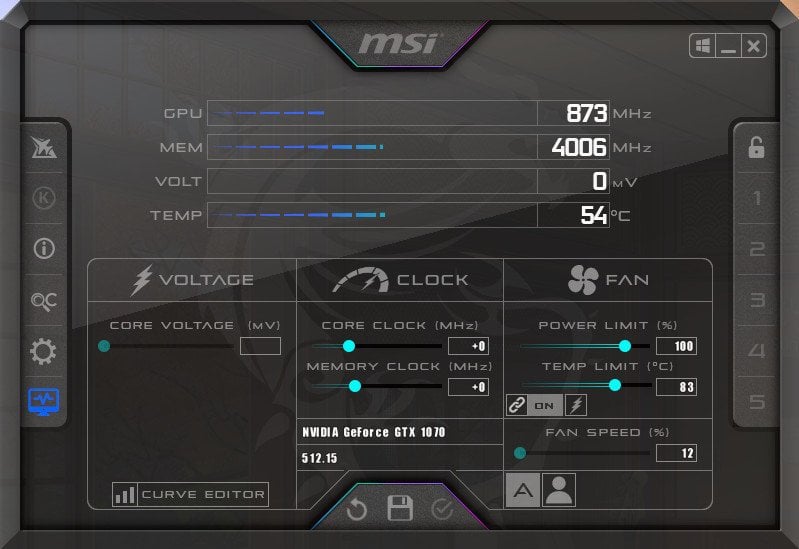
Implementing reliable temperature monitoring is the first step. Software tools such as MSI Afterburner, HWMonitor, GPU-Z, or integrated utilities provided by GPU manufacturers allow users to track real-time temperatures, fan speeds, and clock rates. For server environments, more sophisticated monitoring solutions integrated with system management tools are available. Setting up alerts for critical temperature thresholds can provide early warnings, allowing intervention before problems escalate. Regular checks, especially during and after intensive workloads, can help identify trends and potential issues.
Enhancing Cooling: Hardware Upgrades and Maintenance
- Improved Case Airflow: Ensure the computer case has adequate intake and exhaust fans. Optimize fan placement to create a positive or neutral pressure environment to minimize dust ingress. Good cable management prevents obstruction of airflow.
- Aftermarket Coolers or Liquid Cooling: For GPUs that consistently run hot under demanding loads, upgrading to a high-performance aftermarket air cooler or investing in an All-in-One (AIO) or custom liquid cooling loop can significantly reduce temperatures.
- Thermal Paste and Pads: Over time, thermal paste between the GPU die and its heatsink can dry out and lose effectiveness. Replacing old thermal paste with a high-quality compound, and potentially replacing thermal pads on VRAM chips and VRMs, can yield substantial temperature drops. This is a more advanced maintenance task.
- Regular Cleaning: Dust is a GPU’s silent enemy. Regularly clean dust from heatsinks, fans, and case filters using compressed air. A clean cooling system can operate much more efficiently.
- Environmental Control: Operate hardware in a cool, well-ventilated environment. Consider air conditioning or supplemental fans if ambient temperatures are consistently high.
Optimizing Software and Workflow
- Driver Updates: Keeping GPU drivers updated ensures optimal performance and efficiency, often including thermal management improvements.
- Workload Scheduling: For highly intensive, non-real-time tasks like large photogrammetry processing jobs, schedule them for cooler parts of the day or when other system resources are not heavily utilized.
- Power Limits and Undervolting: Some users choose to undervolt their GPUs – reducing the voltage supplied to the chip without significantly impacting clock speeds. This can lead to substantial temperature reductions with minimal performance loss. Similarly, setting a power limit slightly below the GPU’s maximum can reduce heat output while maintaining much of its performance. This requires careful testing and tuning.
Impact on Project Efficiency and Reliability
The meticulous management of GPU temperatures directly translates into tangible benefits for projects leveraging Tech & Innovation.
Sustained Performance for Large-Scale Data Processing
Projects involving large-scale data processing, such as creating vast 3D models from hundreds of drone images or training complex AI models on petabytes of data, require GPUs to operate at peak performance for extended periods. When temperatures are well-managed, GPUs avoid thermal throttling, allowing them to maintain their boost clocks and process data at maximum speed. This directly accelerates project completion, reduces computational overhead, and allows innovation teams to iterate faster on their designs and analyses. For businesses, this means faster delivery to clients and improved competitiveness.

Ensuring System Stability for Critical Operations
In areas like autonomous systems research or critical remote sensing missions, system stability is non-negotiable. An unexpected system crash due to an overheated GPU can derail months of research, corrupt vital data, or even pose safety risks in testing environments. By ensuring GPUs operate within healthy temperature ranges, professionals can significantly mitigate the risk of hardware-related failures, thus guaranteeing the reliability and continuity of their most critical operations. This robust foundation allows developers and researchers to focus on pushing the boundaries of what’s possible, rather than troubleshooting hardware instability. The health of your GPU is, therefore, not just a hardware concern, but a strategic imperative for the future of Tech & Innovation.