
Web crawling stands as a foundational technology underpinning the vast majority of our digital interactions, yet its inner workings often remain obscured to the casual internet user. At its essence, web crawling is the automated process by which programs, often referred to as web crawlers, spiders, or bots, systematically browse the World Wide Web to discover and index content. This systematic exploration allows for the construction of comprehensive databases of web pages, which are then utilized for a myriad of applications, most notably by search engines to organize and present internet content.
The Core Concept of Web Crawling
A web crawler functions much like an indefatigable librarian, diligently seeking out new books, cataloging their contents, and organizing them for easy retrieval. Its primary directive is to visit web pages, read their content, and follow hyperlinks to other pages, thereby traversing the intricate network of the internet. This continuous discovery process is vital because the web is a dynamic, ever-expanding ecosystem, with new pages appearing and existing ones changing or disappearing daily. Without crawlers, the internet would largely be an unsearchable chaos of isolated information.
The fundamental goal of a general-purpose web crawler is to create a copy of all visited pages for later processing. This processing typically involves parsing the content to extract keywords, understanding the page’s structure, identifying internal and external links, and storing this information in a vast index. This index then forms the searchable database that powers our ubiquitous search engines. Specialized crawlers, however, might have more specific goals, such as monitoring prices, gathering news articles, or mapping social network connections. Regardless of their specific purpose, all crawlers share the common methodology of automated, systematic web traversal.
Mechanics of a Web Crawler
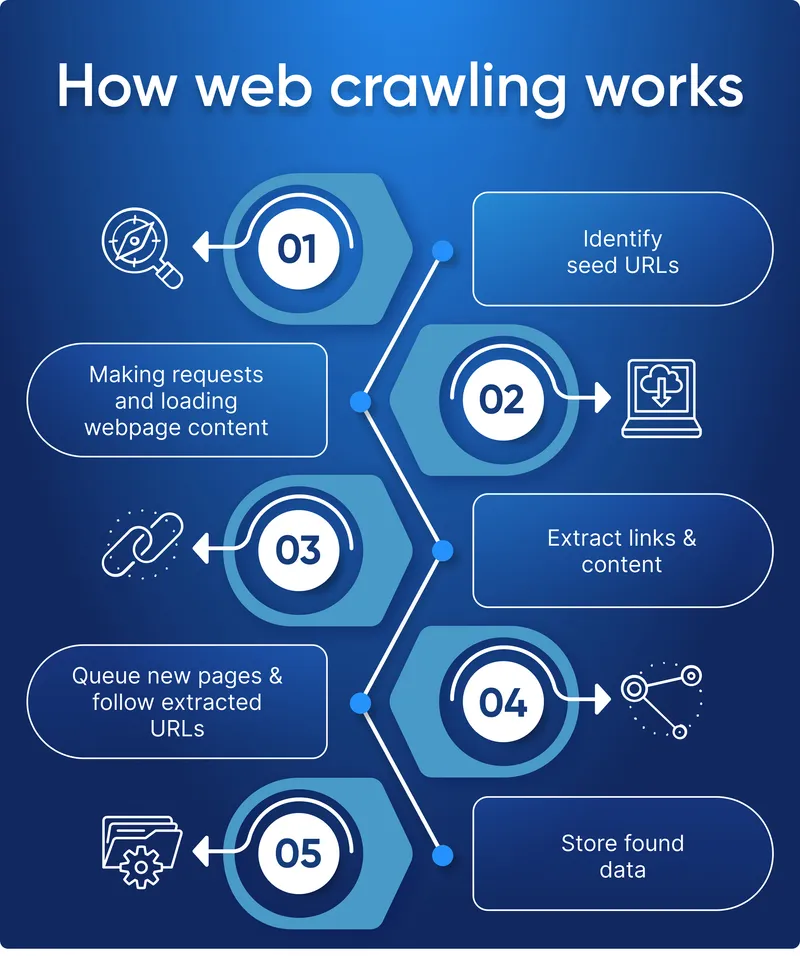
The operation of a web crawler is a sophisticated dance between discovery, retrieval, and indexing. It begins with a set of “seed” URLs – initial web addresses that the crawler is instructed to visit. From these starting points, the crawler fetches the content of each page, typically the HTML source code.
Traversal and Content Extraction
Once a page’s content is downloaded, the crawler parses it to identify all hyperlinks embedded within. These newly discovered URLs are then added to a “frontier” or queue of pages to be visited. Crawlers employ various strategies to decide which links to follow next. Common approaches include:
- Breadth-First Search: Prioritizing pages at the current “depth” before delving deeper into the web graph. This ensures a broad sweep of a website’s structure before getting too granular.
- Depth-First Search: Following a single path of links as far as possible before backtracking. This can be efficient for exploring deeply nested structures but risks getting lost in “crawl traps.”
- Prioritized Crawling: Assigning scores to URLs based on various metrics like estimated importance, freshness, or relevance to a specific topic. This often involves machine learning algorithms to predict the value of a page before it’s even visited.
As content is extracted, it undergoes further processing. This includes stripping out irrelevant formatting, tokenizing words, and identifying key elements like titles, headings, and images. The extracted data, along with metadata about the page (e.g., creation date, last modified date, language), is then stored in a data repository and indexed for rapid querying.
Politeness and Duplicate Detection
Operating on the massive scale of the internet requires crawlers to adhere to certain “politeness” policies to avoid overwhelming web servers. The primary mechanism for this is the robots.txt file, a standard protocol that website owners can use to specify which parts of their site should not be crawled, or to dictate crawl delay times. Responsible crawlers respect these directives, though not all bots do. Additionally, crawlers implement internal mechanisms to limit the rate of requests to a single server, ensuring they don’t inadvertently launch a denial-of-service attack.
Another critical aspect of crawler mechanics is duplicate detection. The web is rife with identical or near-identical content, whether through mirrored sites, syndicated articles, or variations in URLs that lead to the same page. Sophisticated hashing algorithms and content similarity checks are used to identify and avoid indexing redundant information, optimizing storage and processing resources.
Pivotal Applications and Impact
The impact of web crawling extends far beyond merely powering search engines, touching virtually every aspect of the digital economy and information landscape.
Powering Search Engines and Information Retrieval
The most prominent application of web crawling is, undoubtedly, its role in creating and maintaining search engine indices. Google, Bing, DuckDuckGo, and countless others rely on vast fleets of crawlers to continuously scour the web, discovering billions of pages, updating their information, and discarding outdated content. Without this tireless exploration, the ability to find relevant information on the internet would be severely limited, making the web an unwieldy and impractical resource. Crawlers are responsible for the initial discovery of content, which is then analyzed and ranked by search engine algorithms to deliver relevant results.
Data Mining and Business Intelligence
Beyond general search, web crawling is a vital tool for data mining. Businesses leverage specialized crawlers to gather competitive intelligence, such as monitoring competitors’ pricing strategies, product launches, or marketing campaigns. Market researchers use crawlers to collect vast datasets for trend analysis, sentiment analysis, and demographic studies. For example, crawlers can aggregate product reviews across various e-commerce platforms to gauge public perception or identify emerging consumer preferences. This data provides invaluable insights for strategic decision-making and product development.
Web Archiving and Preservation
Web archiving is another critical application, particularly for preserving digital history and cultural heritage. Organizations like the Internet Archive (with its Wayback Machine) deploy massive crawling operations to capture snapshots of websites over time. This ensures that even if a website goes offline or changes significantly, its historical versions remain accessible. This preservation effort is essential for researchers, historians, and the general public, providing a digital record of our evolving online world.
Cybersecurity and Content Management
In the realm of cybersecurity, crawlers can be deployed to monitor the web for phishing sites, malware distribution, or intellectual property infringement. By systematically scanning for specific patterns or content, security firms can identify and flag malicious sites, helping to protect users. For website owners, crawlers can perform vital functions like identifying broken links, checking for content plagiarism, or ensuring internal site structure is optimized, contributing to better user experience and search engine optimization (SEO).
Challenges and Ethical Considerations
Despite its utility, web crawling presents significant technical challenges and raises complex ethical and legal questions.
Technical Hurdles
The sheer scale, dynamic nature, and inherent “messiness” of the web pose immense technical hurdles. The web is constantly changing, with pages being created, updated, or deleted by the second. Crawlers must contend with:
- Dynamic Content: Many modern websites heavily rely on JavaScript to render content, making it difficult for traditional crawlers that primarily process static HTML. Modern crawlers often need to execute JavaScript, which is computationally intensive.
- Crawl Traps: Websites can contain infinite loops of dynamically generated URLs or very deep directory structures that can trap a crawler indefinitely, consuming resources without yielding valuable data.
- Anti-Crawling Measures: Many websites employ sophisticated techniques to detect and block crawlers, such as CAPTCHAs, IP blocking, or obfuscated HTML, necessitating advanced circumvention strategies.
- Data Volume: The amount of data collected is staggering, requiring massive storage, processing power, and efficient indexing systems.
Ethical and Legal Landscape
The ethical and legal implications of web crawling are increasingly scrutinized. While crawling publicly accessible information is generally considered acceptable, the line becomes blurred when considering:
robots.txtCompliance: Whilerobots.txtis a widely accepted standard, it is advisory, not legally binding. Crawlers that ignore these directives can be seen as unethical or even malicious.- Terms of Service Violations: Many websites explicitly forbid automated scraping or crawling in their terms of service. Violating these terms, particularly for commercial gain, can lead to legal action.
- Data Privacy and Copyright: Crawling and indexing personal data, especially sensitive information, raises significant privacy concerns, particularly under regulations like GDPR and CCPA. Similarly, the reproduction and use of copyrighted content obtained through crawling can lead to infringement claims.
- Server Load and Bandwidth: Irresponsible crawling can place a heavy load on target servers, consuming bandwidth and potentially disrupting service for legitimate users, effectively acting as a low-level denial-of-service attack.
Distinguishing between legitimate “crawling” for indexing purposes and more aggressive “scraping” for direct data extraction is crucial, with the latter often carrying greater legal and ethical risks.
The Evolving Landscape: Innovation in Web Crawling
The field of web crawling is continuously evolving, driven by advancements in computing power, artificial intelligence, and the ever-changing nature of the internet itself.
AI and Machine Learning in Crawler Intelligence
One of the most significant areas of innovation is the integration of machine learning (ML) and artificial intelligence (AI) into crawler intelligence. AI algorithms are now employed to:
- Prioritize URL Exploration: Instead of simply following links, ML models can predict the potential value, relevance, or freshness of a URL, guiding the crawler to more important content first and optimizing resource allocation.
- Intelligent Data Extraction: AI-powered parsers can more accurately extract structured data from unstructured or semi-structured web pages, adapting to layout changes and identifying specific entities like product names, prices, or addresses.
- Adaptive Anti-Bot Evasion: ML can help crawlers learn and adapt to anti-bot measures, making them more resilient to detection and blocking, while still striving to respect ethical boundaries.
- Content Quality Assessment: AI can evaluate the quality, originality, and trustworthiness of content during the crawling phase, helping to refine search indices and reduce the inclusion of low-quality or spammy pages.
Distributed and Real-time Architectures
Modern crawlers increasingly leverage distributed computing and cloud infrastructure to handle the immense scale of the web. By distributing the crawling workload across thousands of machines, operations can be scaled horizontally, improving efficiency and speed. Furthermore, the demand for “freshness” in information, especially for news and dynamic content, drives innovation in real-time or near real-time crawling, where changes to high-priority pages are detected and indexed almost immediately.

Semantic Web and Knowledge Graphs
As the web evolves towards a more structured “Semantic Web,” crawlers are also adapting to extract meaning and relationships between data, rather than just keywords. This involves identifying entities, attributes, and their connections to build knowledge graphs – rich, interconnected databases of information. This move allows for more sophisticated query answering and contextual understanding, enhancing the capabilities of future information systems.
The journey of web crawling mirrors the trajectory of the internet itself: from a nascent technology to a complex, indispensable system continually refined by innovation, grappling with ever-present challenges while unlocking new possibilities for information discovery and organization.