The Z-Value: A Cornerstone for Data-Driven Innovation
In the fast-evolving landscape of technology and innovation, data is paramount. From refining AI algorithms to optimizing autonomous systems and validating novel hardware, quantitative analysis underpins progress. Within this analytical toolkit, the z-value, also known as a z-score, emerges as a remarkably versatile and powerful statistical measure. At its core, the z-value quantifies the relationship between an individual data point and the mean of its dataset, expressed in terms of standard deviations. This seemingly simple calculation provides a standardized context, allowing tech professionals and innovators to interpret performance metrics, identify anomalies, and make informed decisions across diverse technological applications.

Understanding the Basics for Tech Professionals
For those immersed in developing and deploying new technologies, understanding the z-value begins with appreciating its role in normalizing data. Imagine a scenario where a team is testing the latency of a new 5G module. Individual latency measurements might fluctuate. The z-value provides a universal yardstick to understand if a particular latency reading is typical, exceptionally good, or alarmingly poor relative to the average performance of that module under specific test conditions.
Mathematically, the z-value (z) for a data point (x) is calculated using the following formula:
$z = (x – mu) / sigma$
Where:
- x is the individual data point (e.g., the execution time of an AI inference, a sensor’s temperature reading, a battery’s discharge rate).
- $mu$ (mu) is the mean (average) of the population or sample from which the data point is drawn (e.g., the average inference time across 10,000 runs, the average temperature from a batch of sensors, the typical discharge rate of a battery model).
- $sigma$ (sigma) is the standard deviation of the population or sample (e.g., the variability in inference times, the spread of temperature readings, the consistency of battery discharge).
A positive z-value indicates the data point is above the mean, while a negative z-value signifies it is below the mean. A z-value of zero means the data point is exactly at the mean. The magnitude of the z-value tells us how many standard deviations away from the mean the data point lies.
Standardizing Data for Meaningful Comparison
One of the most significant contributions of the z-value to technology and innovation is its ability to standardize data from different scales or distributions. Consider a company evaluating two experimental machine learning models. Model A achieves an accuracy of 92% with a standard deviation of 3%, while Model B achieves 88% accuracy with a standard deviation of 1%. Simply comparing raw percentages might suggest Model A is superior. However, by converting a specific test result from each model into a z-score relative to its own baseline performance, we can gain a more nuanced understanding.
For instance, if Model A had a particular test run with 95% accuracy and Model B had a test run with 89% accuracy:
- Model A z-score: $(95 – 92) / 3 = 1$
- Model B z-score: $(89 – 88) / 1 = 1$
Both test runs are one standard deviation above their respective means, indicating similar relative performance within their own operational contexts. This standardization is invaluable when comparing sensor outputs calibrated differently, assessing the impact of new features across varying user bases, or benchmarking prototype performance against diverse existing systems. It allows for “apples-to-apples” comparisons of relative standing, even when the “apples” and “oranges” come from entirely different datasets or measurement units.
Applying the Z-Value in Tech & Innovation Ecosystems
The practical applications of z-scores span numerous domains within tech and innovation, offering granular insights that drive development, quality assurance, and strategic decision-making.
Quality Control and Performance Benchmarking
In manufacturing new components for autonomous vehicles or advanced robotics, precision and consistency are paramount. Suppose a production line for a specific micro-controller aims for a clock speed of 2.0 GHz with minimal variance. Regular testing yields clock speed measurements. By calculating the z-value for each manufactured chip’s actual speed against the desired mean and historical standard deviation, engineers can quickly identify chips that significantly deviate from the norm. Chips with z-scores exceeding a predefined threshold (e.g., |z| > 2 or |z| > 3) might indicate a manufacturing defect, a calibration issue in testing equipment, or a need for process adjustment. This proactive identification is crucial for maintaining product quality and ensuring reliability in mission-critical applications. Similarly, when benchmarking the power efficiency of a new AI processor, z-scores can highlight if a particular test run’s consumption is unusually high or low compared to the processor’s typical performance profile.
Validating AI Models and Autonomous Systems
The performance of AI models, particularly in domains like computer vision, natural language processing, or reinforcement learning for autonomous navigation, is often evaluated through various metrics such as accuracy, F1-score, latency, or object detection confidence. When deploying or updating an AI model, it’s essential to understand if new versions genuinely improve performance or if observed changes are merely due to random fluctuations.
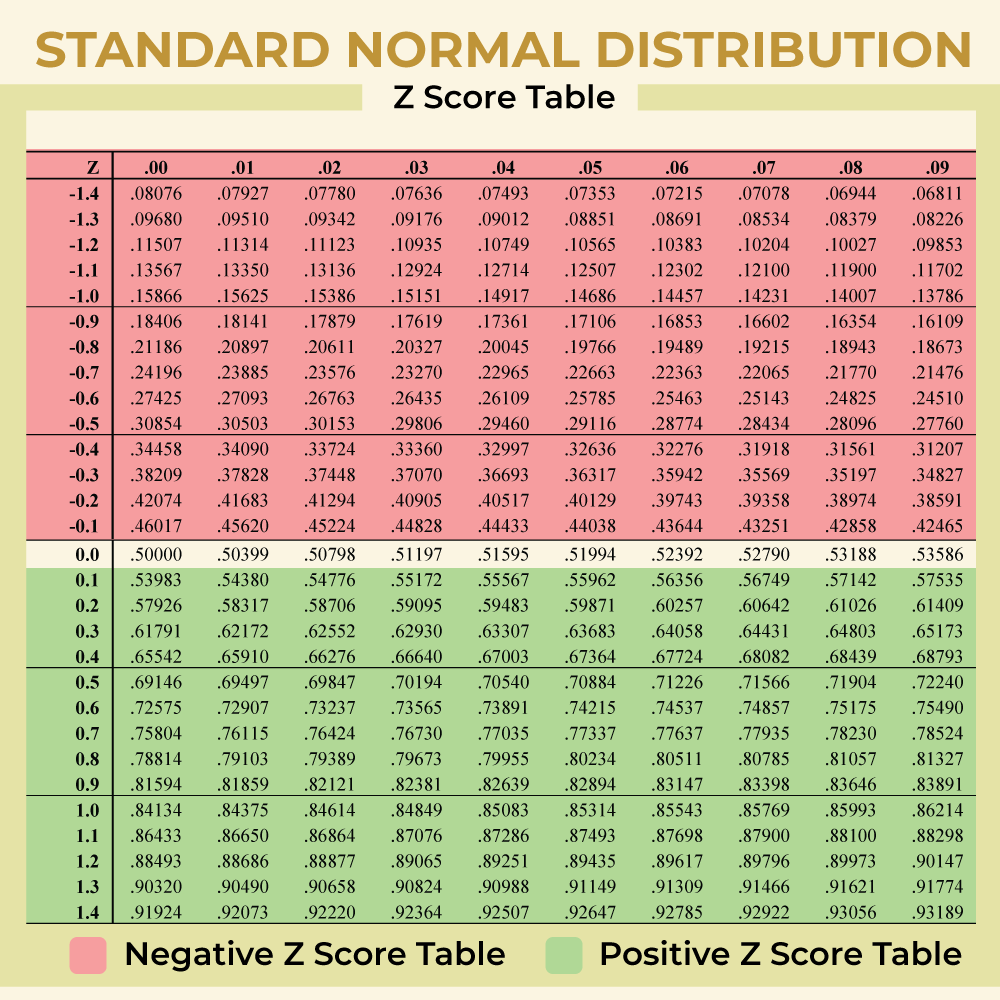
By collecting a distribution of performance scores for both the baseline model and the new iteration, z-scores become instrumental. A significant positive z-score for a new model’s performance metric, relative to the old model’s distribution, suggests a statistically meaningful improvement. Conversely, if an autonomous drone’s obstacle avoidance system suddenly exhibits a higher number of “near misses,” converting this count to a z-score relative to historical data can immediately flag if the current performance is an alarming outlier requiring immediate investigation, rather than just a minor blip. This enables data scientists and engineers to validate improvements, detect regressions, and ensure the robustness of intelligent systems.
Optimizing Sensor Data and Remote Sensing
Modern innovation heavily relies on sensor data – from environmental monitoring via IoT devices to intricate remote sensing platforms for smart agriculture or urban planning. Sensors, however, can be prone to noise, drift, or outright failure. The z-value is an excellent tool for anomaly detection in continuous sensor streams.
For example, a network of smart city sensors monitoring air quality might suddenly report an abnormally high particulate matter reading. If this reading generates a z-score of +4, it strongly indicates either a genuine environmental event requiring attention or a malfunctioning sensor that needs maintenance or replacement. In remote sensing, analyzing satellite imagery for changes in vegetation cover, urban sprawl, or geological shifts involves processing vast datasets. Z-scores can pinpoint areas where pixel values significantly deviate from historical norms, highlighting regions of interest for further analysis, whether it’s identifying illegal deforestation, detecting new construction sites, or monitoring disaster-affected zones. This capability is vital for maintaining data integrity and extracting actionable intelligence from complex sensor networks.
Interpreting Z-Scores: Beyond Raw Data
Understanding the magnitude of a z-score is key to unlocking its full analytical power. A z-score inherently connects to probability, especially when the underlying data is approximately normally distributed.
Identifying Outliers and Anomalies
One of the most common applications of the z-value in tech is identifying outliers. An outlier is a data point that differs significantly from other observations. In innovation, outliers can represent critical events: a breakthrough performance in a prototype, a critical system failure, a data acquisition error, or even malicious activity in a cybersecurity context.
Common thresholds for identifying outliers using z-scores are:
- |z| > 2: Suggests the data point is unusual, lying outside approximately 95% of the data in a normal distribution.
- |z| > 3: Indicates the data point is highly unusual, lying outside approximately 99.7% of the data.
- |z| > 4 or 5: Often considered extremely rare and highly anomalous.
If a new AI-powered anomaly detection system in a network security context reports a connection attempt with a z-score of +4 based on historical traffic patterns, it’s a strong indicator of a potential cyber threat, warranting immediate investigation. Similarly, if a novel material’s stress test results in a tensile strength value with a z-score of -3, it might suggest a critical flaw in the material batch or testing process, demanding immediate re-evaluation.
Hypothesis Testing for New Technologies
When introducing an innovative feature, algorithm, or hardware component, engineers and researchers often want to determine if it genuinely leads to a measurable improvement. This often involves hypothesis testing. The z-value is central to many hypothesis tests, particularly when dealing with sample means and known population standard deviations, or large sample sizes where the sample standard deviation can approximate the population standard deviation.
For example, if a team develops a new algorithm for image compression and wants to test if it’s significantly faster than the existing one, they would measure the processing time for a sample of images using both algorithms. By calculating a test statistic (often a z-score for the difference in means), they can determine the probability of observing such a difference if the new algorithm had no actual effect (the null hypothesis). A low p-value, derived from a large z-score, would lead to the rejection of the null hypothesis, providing statistical evidence that the new algorithm is indeed faster. This rigorous statistical validation is essential for moving innovations from experimental stages to deployment.
Challenges and Best Practices in Z-Value Application
While the z-value is a powerful tool, its effective application in tech and innovation requires attention to certain nuances and best practices.
Ensuring Data Normality and Representativeness
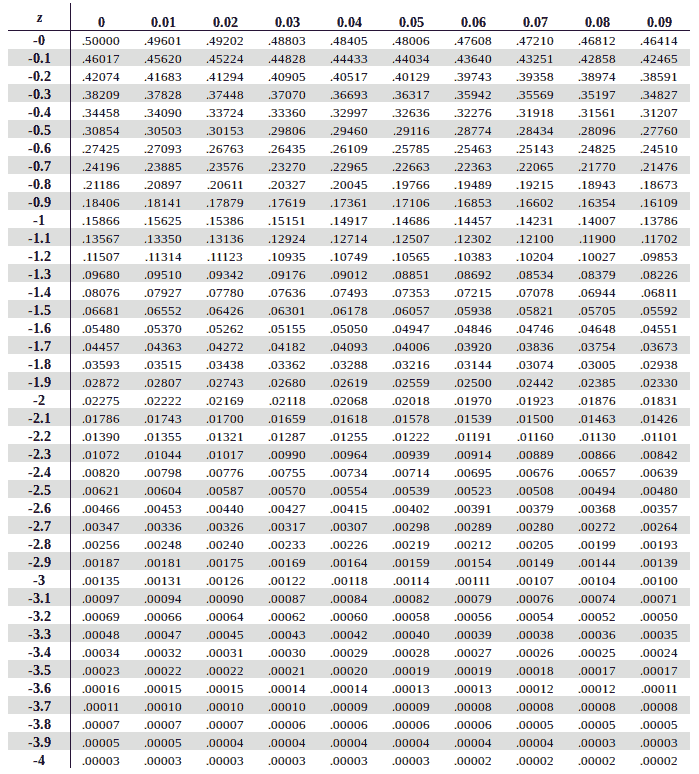
The interpretability of a z-score in terms of probability (e.g., “this is in the top 5% of data”) relies heavily on the assumption that the underlying data distribution is normal or approximately normal. Many natural phenomena and measurement errors tend towards normality, but technological performance data can sometimes be skewed or have other distributions. For significantly non-normal data, simply interpreting z-scores with normal distribution probabilities can be misleading. In such cases, alternative standardization methods or non-parametric statistical tests might be more appropriate. Furthermore, the accuracy of the mean ($mu$) and standard deviation ($sigma$) used in the z-score calculation is critical. These parameters must be derived from a representative sample or the entire population relevant to the technological context being analyzed. Using outdated or unrepresentative baseline data can lead to erroneous conclusions about a new innovation’s performance.
Integrating Z-Scores with Advanced Analytics
In an era of big data and complex AI, z-scores often serve as a foundational element within more sophisticated analytical frameworks. They can be used as a preprocessing step for machine learning algorithms, standardizing features to prevent attributes with larger scales from dominating the learning process. For instance, in training a predictive maintenance model for industrial machinery, sensor readings (e.g., temperature, vibration, pressure) often have vastly different scales. Normalizing these inputs using z-scores ensures that the model learns equally from all features without bias towards higher magnitude values. Z-scores can also be combined with time-series analysis to detect shifts in operational patterns over time for autonomous systems, or integrated into dashboard analytics to provide real-time, context-aware performance indicators for innovative products and services.
Ultimately, the z-value remains an indispensable tool for tech professionals and innovators. By providing a standardized measure of deviation from the norm, it empowers data-driven decision-making, facilitates rigorous quality control, enables the validation of new technologies, and helps to distill actionable insights from the ever-increasing torrent of data generated by the modern world of innovation.