
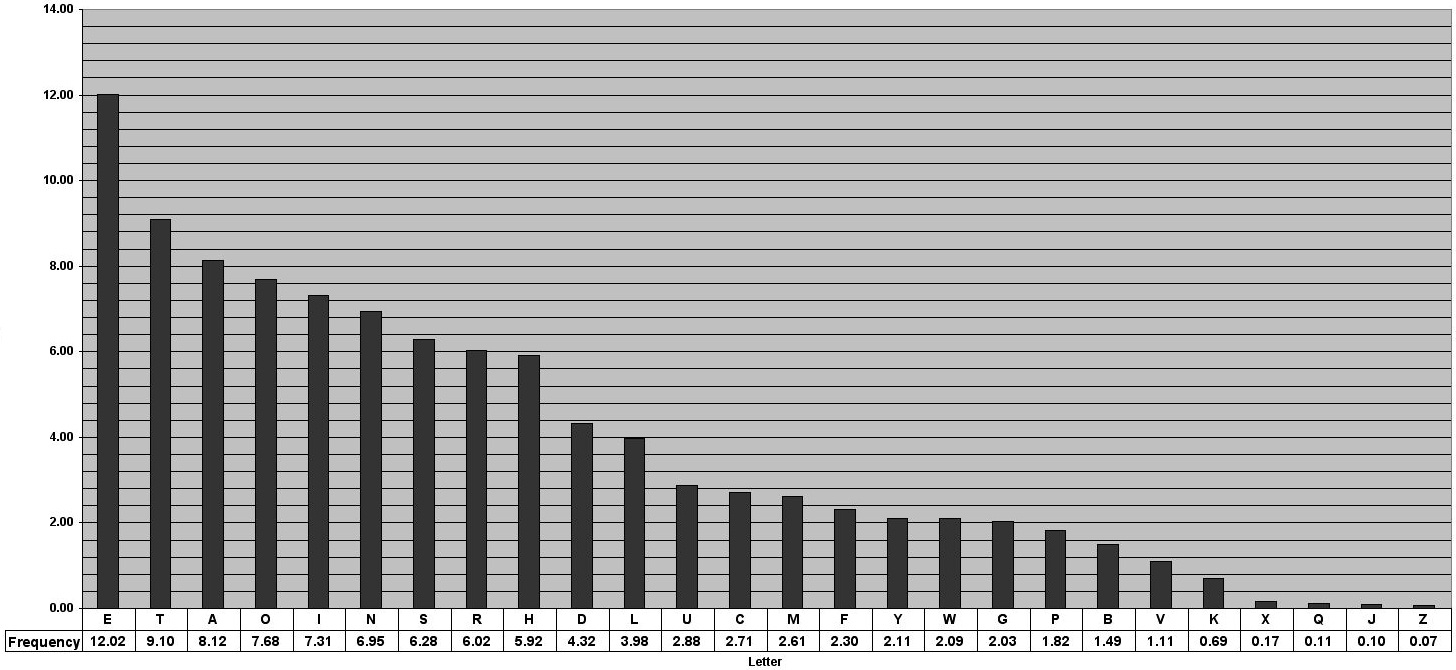
The humble letter ‘E’ stands as the undisputed champion of the English alphabet, appearing with greater frequency than any other character. For centuries, this linguistic quirk has been a fascinating tidbit for word enthusiasts and a crucial tool for cryptographers. However, in the modern era of rapid technological advancement and burgeoning data science, the prevalence of ‘E’ – and the broader concept of character frequency – transcends mere curiosity. It has become a foundational element, an unspoken rule shaping the very algorithms that drive artificial intelligence, optimize data storage, and secure digital communications, placing it squarely at the heart of Tech & Innovation. Understanding this fundamental linguistic pattern offers profound insights into how technology processes, predicts, and interacts with human language.
The Foundational Role of Character Frequency in AI and Data Science
In the digital age, where text is a primary medium of information exchange, the statistical distribution of characters is far from trivial. The commonality of ‘E’ and other letters provides critical data points that algorithms leverage to perform complex tasks, from intelligent text prediction to efficient data compression. This statistical understanding forms the bedrock for numerous innovations in computing.
Natural Language Processing and Predictive Text
Natural Language Processing (NLP), a core discipline within AI, relies heavily on understanding the statistical properties of language. AI models trained on vast corpora of text automatically discern that ‘E’ is the most frequent letter. This knowledge, though often implicitly learned, profoundly impacts their ability to process, generate, and understand human language.
For instance, predictive text systems on smartphones and keyboards anticipate the next word or letter based on probabilistic models informed by character frequencies. When you type “th-“, the system is more likely to suggest “the” because ‘E’ frequently follows ‘H’ in common English words. Similarly, spell checkers identify potential errors by comparing inputted sequences against known character and word patterns. Large Language Models (LLMs) like those powering sophisticated chatbots build upon these foundational principles, learning intricate relationships between characters, words, and contexts, where the statistical prevalence of letters contributes to the models’ ability to generate coherent and grammatically correct text. The implicit understanding of character frequency guides tokenization processes, where text is broken down into smaller units for analysis, and influences the weighting of various linguistic features in embeddings, shaping how words and concepts are represented numerically for AI comprehension.
Data Compression Algorithms
One of the earliest and most impactful applications of character frequency analysis in computing lies in data compression. The goal of compression is to reduce the amount of data needed to store or transmit information without significant loss. Algorithms such as Huffman coding and Shannon-Fano coding achieve this by assigning shorter binary codes to more frequent characters and longer codes to less frequent ones. Given that ‘E’ appears so often, it is typically assigned the shortest possible bit sequence.
Consider a document filled with English text. By identifying ‘E’ as the most common character and assigning it a compact representation (e.g., ‘0’ or ’00’), followed by ‘T’, ‘A’, ‘O’, ‘I’, ‘N’, etc., significant reductions in file size can be achieved. This principle is fundamental to the efficiency of modern computing infrastructure. From cloud storage solutions that manage petabytes of data to internet protocols that ensure rapid data transmission, these compression techniques, rooted in the statistical understanding of character frequency, are indispensable. They enable faster downloads, more efficient use of bandwidth, and reduced storage costs, underpinning much of our digital world.
Cryptography and Cybersecurity Implications
Historically, understanding letter frequencies was paramount in cryptanalysis, particularly for breaking substitution ciphers. Simple ciphers that merely replace each letter with another could often be deciphered by analyzing the frequency of characters in the ciphertext and mapping them back to the known frequencies of letters in the English language (e.g., the most frequent ciphertext letter would likely correspond to ‘E’). This method was famously used to decrypt secret messages for centuries.
While modern encryption techniques, such as AES or RSA, are far more sophisticated and robust against direct frequency analysis, the underlying principle of pattern detection remains relevant in cybersecurity. Anomaly detection systems, for example, might still analyze statistical properties of data streams or code to identify unusual patterns that deviate from expected norms. Detecting malicious code, identifying phishing attempts through linguistic quirks, or even pinpointing insider threats often involves analyzing the statistical distribution of characters, commands, or data segments. Although not a direct attack on encryption, an unexpected deviation in character frequency or data entropy within encrypted communications could signal a compromised system or a covert channel, prompting further investigation. Thus, the foundational concept of character frequency continues to inform strategies for detecting irregularities and upholding digital security.
Beyond English: Multilingual Tech and Unicode’s Role
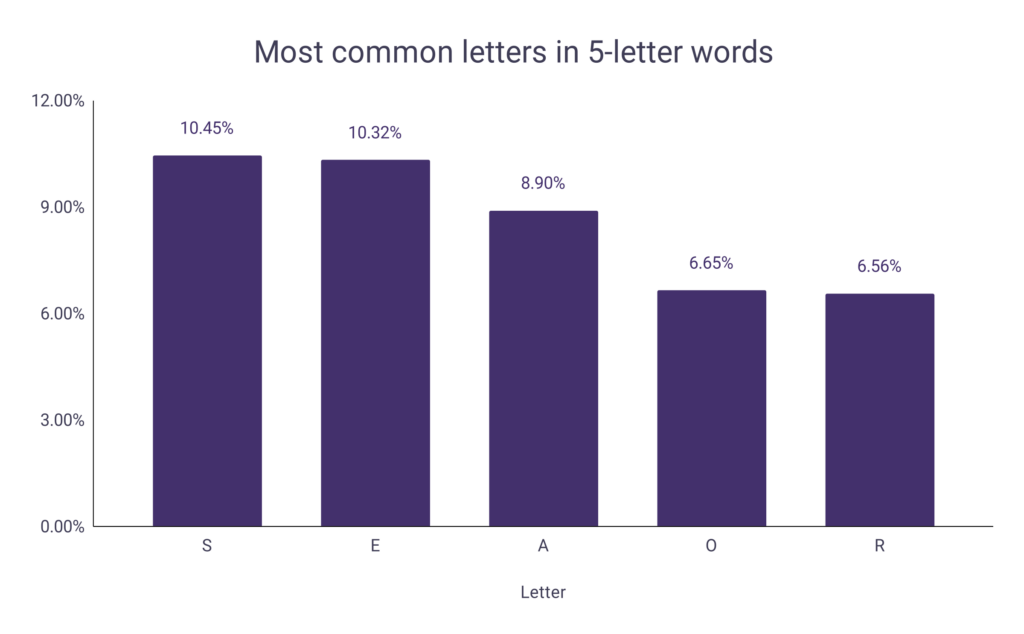
While ‘E’ reigns supreme in English, its dominance is not universal. Every language possesses its own unique character frequency distribution, posing a significant challenge and opportunity for global tech innovation. Recognizing this diversity is crucial for developing truly inclusive and effective technologies.
Adapting to Global Linguistic Diversity
The digital world is not solely English-speaking. Technologies must adapt to countless languages, each with its own alphabet, character set, and frequency patterns. For instance, in Spanish, ‘A’ is often more frequent than ‘E’; in French, ‘E’ is also very common but ‘A’ and ‘I’ follow closely; and in German, ‘E’ is again dominant, but ‘N’ and ‘I’ are also highly prevalent. Non-Latin script languages like Arabic, Mandarin, or Japanese present entirely different statistical landscapes, often dealing with logograms, syllabaries, or characters with complex internal structures rather than simple letters.
NLP models designed for global use must be trained on diverse linguistic corpora, allowing them to learn the specific character and word frequencies pertinent to each language. This training enables accurate machine translation, cross-lingual information retrieval, and language-specific predictive text. The advent of Unicode, a universal character encoding standard, has been instrumental in this adaptation. Unicode assigns a unique number to every character, across all languages and scripts, ensuring that text can be consistently represented and processed across different platforms and applications. This standardization allows algorithms to handle the complexities of thousands of different characters, each contributing to its own language’s unique frequency profile, making global communication and data processing seamless.
The Future of Textual Analysis in AI and Human-Computer Interaction
The ongoing evolution of AI and the increasing sophistication of human-computer interaction continue to elevate the importance of detailed textual analysis, including the subtle insights gleaned from character frequencies. As technology becomes more integrated into our daily lives, understanding these fundamental building blocks of language will drive advancements in ethical AI and intuitive user experiences.
Ethical Considerations and Bias Detection
As AI systems become more powerful, especially in content generation and decision-making, the ethical implications of the data they are trained on become paramount. Character and word frequency analysis, when applied to large textual datasets, can inadvertently expose and even perpetuate biases present in human language. For example, if a training dataset predominantly uses masculine pronouns in association with certain professions, the AI might learn to generate text reflecting that bias.
Advanced textual analysis, informed by an understanding of character and word distributions, can be employed to detect these biases. By identifying over-representation or under-representation of certain terms, phrases, or even character patterns linked to demographic groups, developers can work to mitigate bias in AI models. This proactive approach ensures that AI systems are fair, equitable, and do not inadvertently amplify societal prejudices embedded within the linguistic data they consume. The ability to statistically analyze and flag such patterns is a critical step towards building responsible AI.
Enhancing Human-Computer Interaction
The deeper AI understands language at its most granular level, the more natural and effective human-computer interaction becomes. This extends beyond simple predictive text to creating highly personalized and adaptive user interfaces. Systems can learn individual typing patterns, preferred linguistic styles, and even anticipate user intent with greater accuracy by implicitly understanding the statistical likelihood of character and word sequences.
For users with disabilities, particularly those relying on assistive technologies, the accuracy of text prediction, driven by sophisticated frequency analysis, is transformative. It allows for faster, more efficient input, reducing the cognitive load and physical effort required to communicate. Voice assistants become more adept at interpreting natural speech, even with variations in accent or cadence, by leveraging an underlying statistical model of language. From intelligent grammar correction tools that subtly suggest improvements, to sophisticated search engines that understand semantic meaning, the continuous refinement of how technology processes and predicts textual information, starting from the basic frequency of characters like ‘E’, is key to building more intuitive, accessible, and powerful digital experiences.
The ‘E’ Factor: Efficiency and Evolution in Tech
Ultimately, the prominence of ‘E’ in the English language serves as a potent analogy for a broader principle in Tech & Innovation: the critical importance of identifying and understanding the most common, foundational elements within any system. Just as ‘E’ is a workhorse of communication, highly frequent data patterns, common algorithms, or recurring user behaviors are the building blocks upon which efficient and innovative technologies are constructed. From optimizing data storage by compressing frequent characters to training AI models that predict common linguistic sequences, the principle of leveraging prevalence drives progress.
This deep statistical understanding of language, rooted in simple observations like character frequency, has evolved from a tool for code-breaking to a fundamental component of artificial intelligence and digital infrastructure. It underscores a crucial truth: even in the era of complex algorithms and machine learning, a meticulous appreciation for the smallest, most common units of information remains an indispensable catalyst for technological advancement and an ongoing source of innovation. The ‘E’ factor, therefore, represents not just a linguistic curiosity but a perpetual quest for efficiency and a cornerstone of evolutionary development in the tech landscape.