
In the dynamic and rapidly evolving landscape of technology and innovation, terms often transcend their original contexts, taking on new, analogous meanings to describe complex phenomena. While conventionally associated with biological systems, the concept of “hypertension” offers a powerful metaphor for understanding early, often subtle, signs of systemic stress or elevated operational pressure within advanced technological frameworks. Specifically, “Stage One Hypertension” within this tech paradigm refers to the initial, detectable phase where a system—be it an autonomous drone, an AI-driven network, or a sophisticated data processing unit—begins to experience elevated internal strain or pressure, deviating from optimal baseline performance without yet reaching a critical failure state.
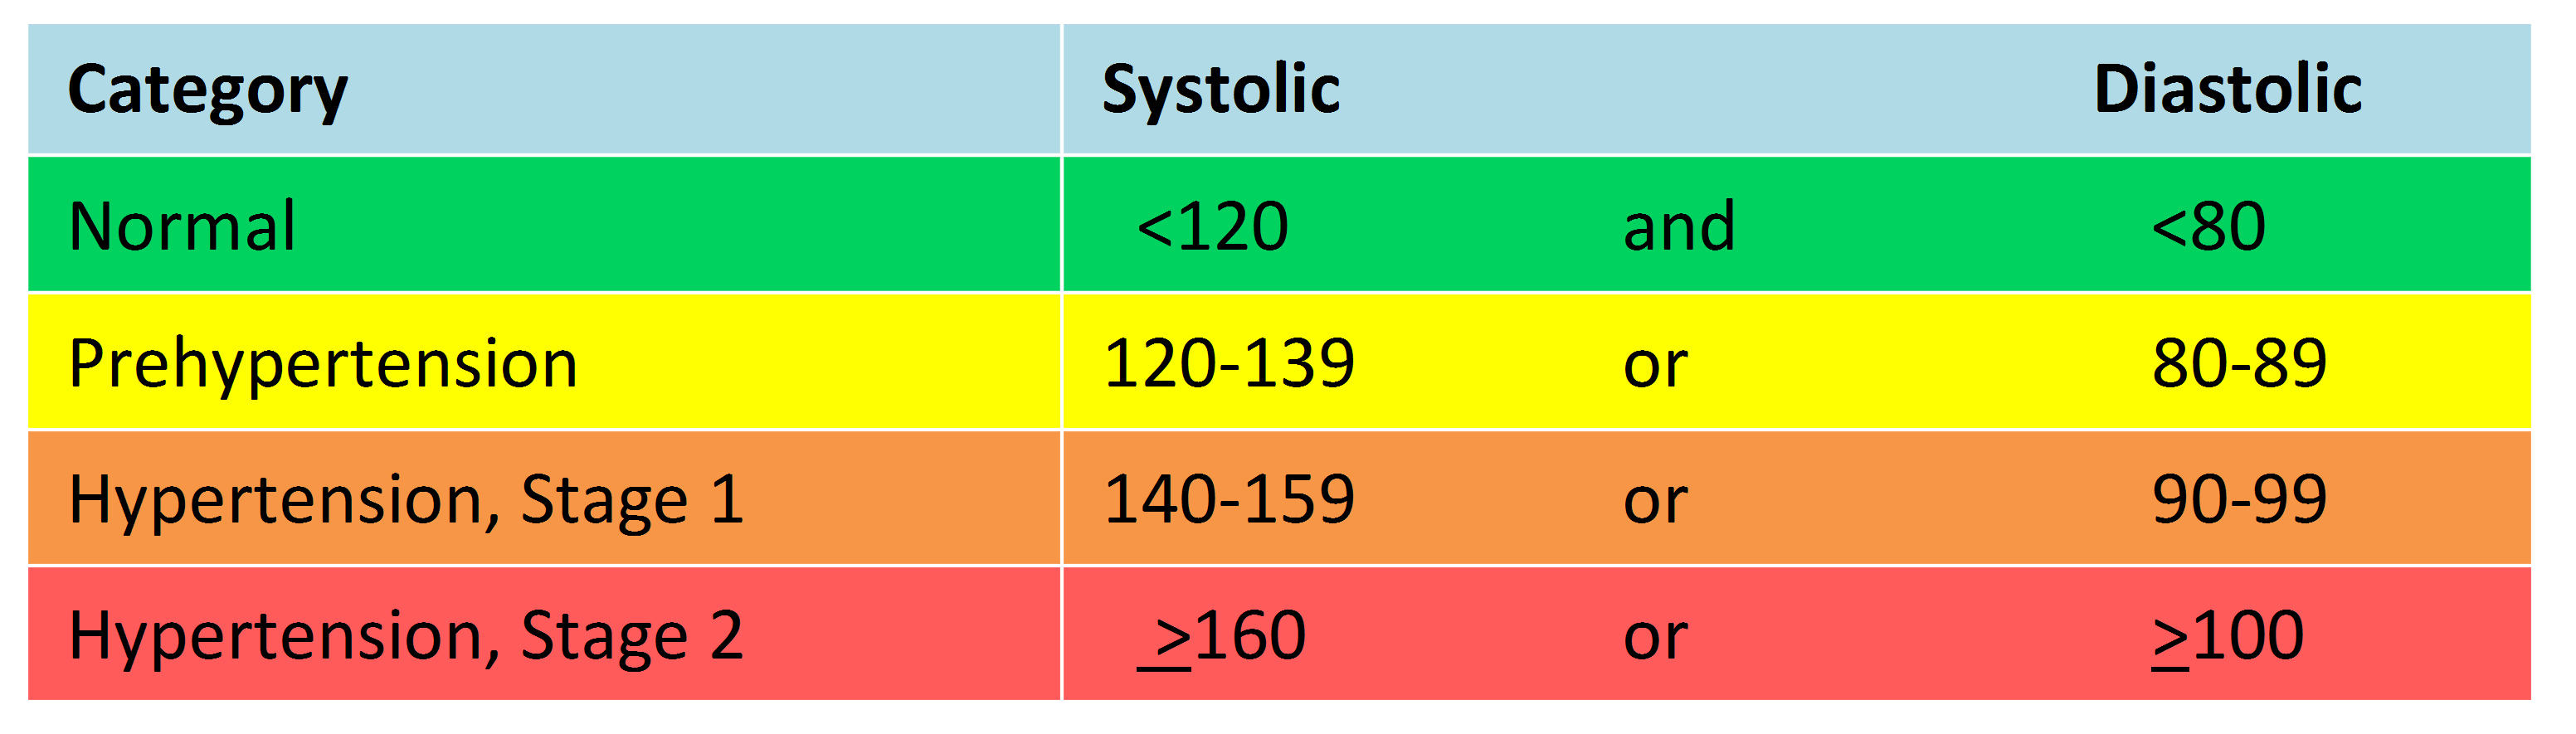
This reinterpretation is crucial for engineers, developers, and operators engaged with intricate systems where proactive monitoring and intervention are paramount. Unlike sudden catastrophic failures, Stage One Hypertension presents itself as a series of early warning indicators, often below immediate alarm thresholds, but signifying a nascent condition that, if unaddressed, could escalate to more severe performance degradation or system instability. Understanding and addressing these early signs are fundamental to maintaining the resilience, reliability, and longevity of cutting-edge technological innovations.
Decoding “Systemic Hypertension” in Advanced Technology
To grasp Stage One Hypertension in tech, it’s essential to first establish what “systemic hypertension” means outside of a biological framework. It’s not about blood pressure, but rather about the internal equilibrium and operational health of a complex system.
Beyond Biological Context: A Metaphor for Systemic Stress
In a technological context, “hypertension” describes a state where an integrated system operates under sustained or intermittent elevated stress. This stress can manifest in various forms: excessive computational load, network congestion, data flow bottlenecks, thermal increases beyond optimal ranges, or even subtle deviations in sensor outputs or control loop performance. Just as prolonged biological hypertension can lead to organ damage, unchecked systemic stress in technology can result in reduced efficiency, accelerated component wear, data corruption, decreased accuracy in AI models, or ultimately, system failure.
The metaphor is particularly potent because it highlights the insidious nature of these pressures. Often, a system continues to function under “hypertension,” perhaps with minor observable symptoms, making early detection a challenge. Yet, during this period, internal mechanisms are strained, and the system’s resilience is gradually eroded. This makes identifying Stage One Hypertension—the earliest phase of this stress—critically important for preventive action.
The Silent Signals: Early Indicators in Integrated Systems
Identifying Stage One Hypertension requires sophisticated monitoring and analytical capabilities. These early indicators are rarely glaring errors but rather subtle shifts in performance metrics. For instance, in an autonomous drone, Stage One Hypertension might manifest as a slight increase in CPU temperature during routine operations, marginally longer response times for control inputs, a higher-than-average packet loss rate in telemetry data, or inconsistent power draw from battery management systems.
In AI and machine learning systems, it could involve a gradual increase in inference latency, a minor but consistent rise in prediction error rates, or an uptick in resource utilization (e.g., GPU memory, network bandwidth) for tasks that previously required less. These “silent signals” are often within acceptable operational parameters individually but, when viewed collectively or in trending patterns, indicate a system beginning to operate under duress. The ability to distinguish these early deviations from normal operational fluctuations is the cornerstone of proactive system health management.
Identifying Stage One Pressure in Autonomous Platforms
Autonomous platforms, especially those operating in dynamic environments like UAVs or remote sensing systems, are prime candidates for experiencing and exhibiting Stage One Hypertension. Their complexity, reliance on continuous data streams, and tight integration of hardware and software make them particularly susceptible to systemic pressures.
AI & Machine Learning Workloads
Modern autonomous systems are heavily reliant on AI for tasks ranging from navigation and obstacle avoidance to data processing and decision-making. Stage One Hypertension in this domain might appear as:
- Increased Inference Latency: A slight but consistent delay in an AI model’s ability to process sensor data and output decisions, indicating an overburdened processor or inefficient model execution.
- Elevated Resource Consumption: AI algorithms might begin demanding more CPU, GPU, or memory than expected for specific tasks, signaling potential code inefficiencies, memory leaks, or an under-provisioned hardware environment for evolving AI tasks.
- Subtle Performance Drift: AI models might exhibit minor but statistically significant degradation in accuracy or precision for specific tasks, even if still within acceptable bounds. This could be due to subtle changes in input data distributions, sensor degradation, or even internal model state shifts that increase computational complexity.
Network Congestion and Data Flow Stress
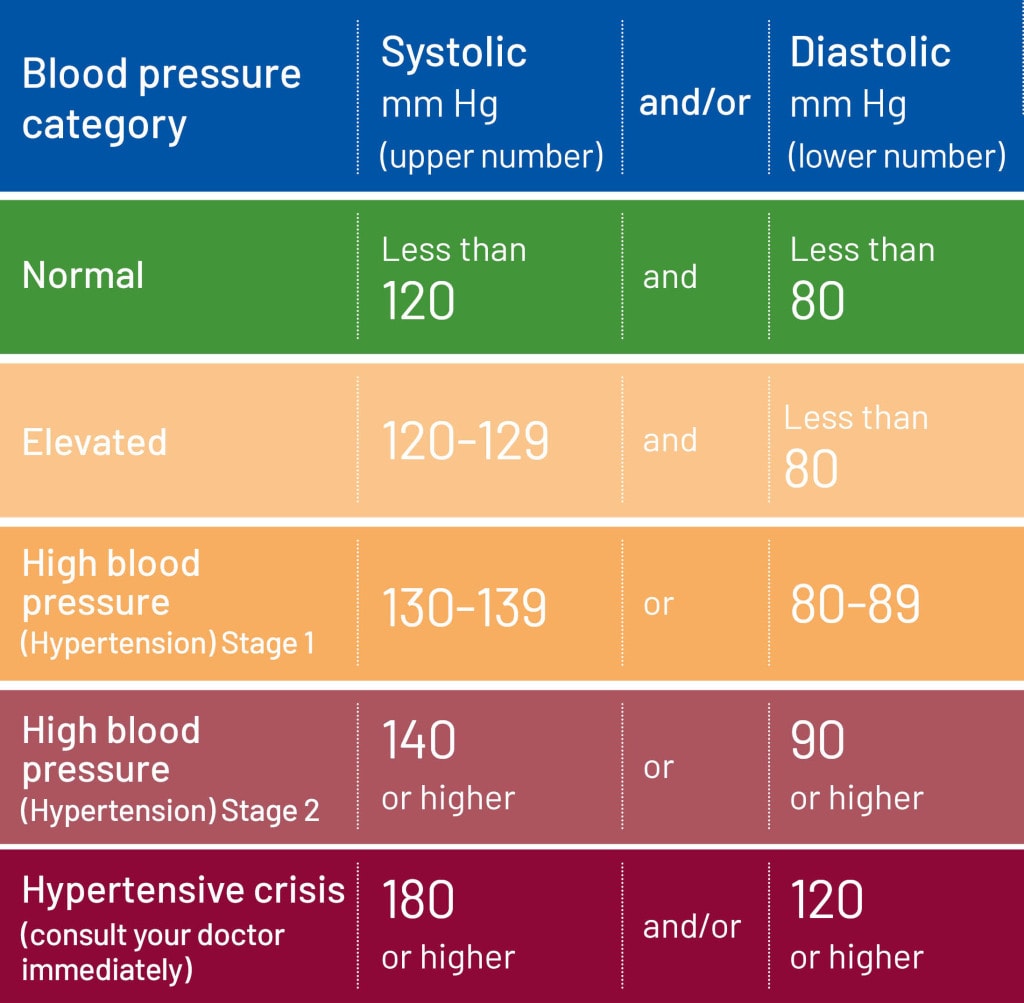
Autonomous flight and remote sensing generate massive amounts of data—from high-resolution imagery and video to LiDAR scans and environmental telemetry. The communication channels supporting these systems are vital, and even minor disruptions can lead to Stage One Hypertension:
- Elevated Packet Loss Rates: A marginal increase in lost data packets between a drone and its ground control station, or between internal sub-systems, suggests network congestion or intermittent communication instability.
- Increased Data Processing Backlogs: Data queues on onboard processors or ground stations might consistently show slightly longer processing times, indicating a bottleneck in data ingestion or analysis pipelines.
- Bandwidth Saturation Warnings: Telemetry might indicate that communication links are operating closer to their maximum bandwidth capacity more frequently than planned, signaling potential future performance issues during peak demand.
Sensor Integrity and Calibration Deviations
Sensors are the eyes and ears of autonomous platforms. Their integrity is non-negotiable, and Stage One Hypertension can manifest through their performance:
- Minor Noise Floor Elevation: A slight increase in the background noise of sensor readings (e.g., IMU, GPS, lidar), impacting the clarity and reliability of data without rendering it unusable.
- Subtle Calibration Drift: Imperceptible deviations from ideal sensor calibration parameters, leading to minor inaccuracies in positional data, environmental mapping, or object detection that are not immediately apparent but compound over time.
- Intermittent Data Gaps: Very short, infrequent gaps in sensor data streams that recover quickly, suggesting transient connectivity issues or minor hardware glitches before full sensor failure.
Proactive Management and Mitigation Strategies
Addressing Stage One Hypertension is an exercise in foresight and sophisticated system management. It requires moving beyond reactive troubleshooting to a proactive stance that leverages advanced analytics and intelligent system design.
Predictive Analytics and Anomaly Detection
The cornerstone of managing Stage One Hypertension lies in the ability to predict and detect these early signs. This involves:
- Baseline Profiling: Establishing comprehensive baseline performance metrics for all critical system components under various operational conditions. This creates a “healthy” reference point.
- Machine Learning for Anomaly Detection: Deploying AI algorithms trained to recognize deviations from these baselines, identifying patterns that signify Stage One Hypertension, even if individual metrics are within acceptable ranges. These models can flag subtle correlations between multiple seemingly minor events that, together, indicate elevated systemic pressure.
- Trend Analysis: Continuously analyzing performance data over time to identify upward trends in resource utilization, error rates, or latency, even if current values are not yet critical. This allows for intervention before thresholds are breached.
Adaptive Resource Allocation
Once Stage One Hypertension is detected, mitigation strategies often involve dynamic adjustment of system resources:
- Dynamic Load Balancing: Intelligent systems can reallocate computational tasks across available processing units to distribute stress and prevent any single component from becoming a bottleneck.
- Adaptive Throttling: Non-critical processes or data streams might be temporarily throttled or deprioritized to free up resources for essential functions, reducing overall system pressure.
- Power Management Optimization: Smart power systems can adjust power delivery to components based on demand and thermal conditions, preventing overheating and ensuring stable operation.
Redundancy and Self-Healing Architectures
Designing systems with inherent resilience is a long-term strategy against Stage One Hypertension:
- Component Redundancy: Critical components (e.g., flight controllers, communication modules) can be duplicated, allowing for seamless failover if one unit shows signs of stress or impending failure.
- Self-Healing Software: Implement software modules capable of detecting minor errors, resetting sub-systems, or reconfiguring network paths to alleviate pressure points without human intervention.
- Decentralized Processing: Distributing computational tasks across multiple, less powerful nodes can prevent a single point of failure and distribute load more effectively, making the system more resistant to localized stress.
The Imperative of System Resilience in Tech Innovation
The concept of Stage One Hypertension underscores a fundamental truth in advanced technology: complexity breeds potential vulnerabilities. As systems become more autonomous, interconnected, and reliant on AI, the margin for error shrinks, and the consequences of system failure escalate.
Ensuring Operational Longevity and Safety
For autonomous drones flying complex missions or remote sensing platforms collecting invaluable data, preventing system stress from escalating past Stage One is not just about efficiency; it’s about operational longevity and, critically, safety. Early detection and mitigation reduce the likelihood of in-flight anomalies, data loss, or even catastrophic incidents. Proactive management extends the lifespan of expensive hardware and ensures consistent data quality, maximizing return on investment. Furthermore, understanding the nuances of system stress allows developers to refine designs, improve algorithms, and build more robust future generations of technology.

Driving Continuous Improvement through Monitoring
The journey to eliminate or significantly reduce Stage One Hypertension is cyclical. The data collected from monitoring systems for early stress indicators provides invaluable feedback for the continuous improvement loop of tech innovation. Analyzing patterns of systemic pressure helps identify design flaws, software bugs, environmental sensitivities, or component weaknesses that might otherwise go unnoticed. This insights-driven approach fosters a culture of resilience engineering, where systems are not just built to perform, but built to adapt, endure, and self-optimize even under challenging conditions. In essence, recognizing Stage One Hypertension is not merely diagnosing a problem; it’s empowering innovation with the knowledge to create stronger, more reliable, and ultimately, more advanced technological futures.