
In the rapidly evolving landscape of modern software architecture, speed and efficiency are paramount. Users expect instantaneous responses, and applications must handle vast amounts of data under considerable load. This demand has driven the pervasive adoption of caching mechanisms, and among the pantheon of caching technologies, Redis stands out as a preeminent solution. More than just a simple cache, Redis (Remote Dictionary Server) is an open-source, in-memory data structure store, used as a database, cache, and message broker. Its versatility and blistering performance make it a cornerstone of countless high-performance applications and a crucial component in the broader sphere of tech innovation.
Understanding the Core Concept: What is Redis?
At its heart, Redis is an advanced key-value store renowned for its speed, flexibility, and robust feature set. Unlike traditional relational databases that store data primarily on disk, Redis keeps data primarily in RAM. This fundamental design choice is the secret behind its exceptional performance, as memory access is orders of magnitude faster than disk I/O.
Redis operates on simple yet powerful principles:
- In-Memory Operation: Data resides in the server’s main memory, allowing for microsecond-level latency for read and write operations. While data is in memory, Redis also offers optional disk persistence for disaster recovery, ensuring data is not lost during a system restart or power failure.
- Data Structures: Beyond simple key-value pairs, Redis supports a rich set of data structures. These include strings, hashes, lists, sets, sorted sets, streams, and more. This richness empowers developers to model complex data scenarios efficiently without the overhead of converting between application data types and flat key-value pairs. For instance, a list can store a series of recent events, a sorted set can manage leaderboards, and hashes can represent objects.
- Single-Threaded Architecture: Redis processes commands sequentially in a single thread, which simplifies concurrency management and ensures atomicity for operations. While seemingly limiting, this architecture, combined with its in-memory nature and highly optimized C code, allows Redis to achieve incredible throughput. The network I/O is typically handled by non-blocking mechanisms, further enhancing its efficiency.
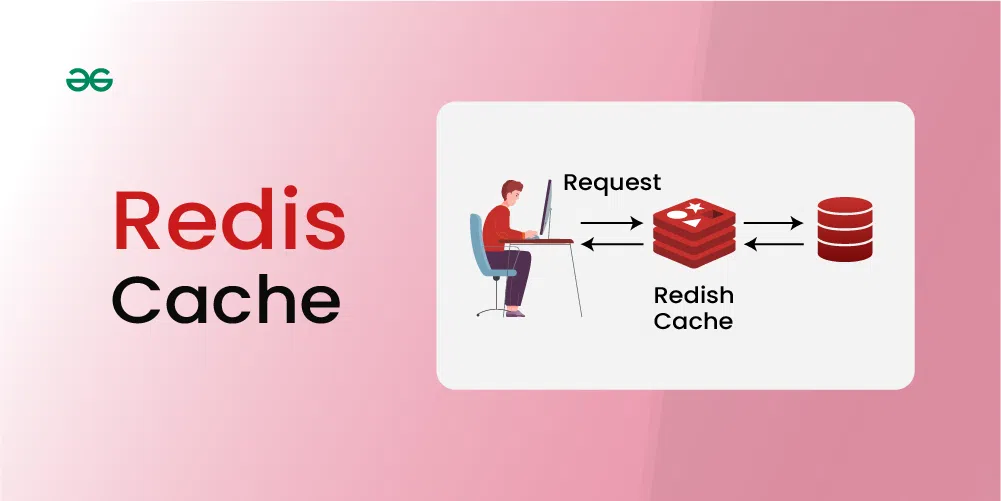
As a cache, Redis acts as a temporary, high-speed storage layer for frequently accessed data, dramatically reducing the need to hit slower, more resource-intensive primary data sources like relational databases or external APIs. This not only accelerates data retrieval but also alleviates the load on backend systems, allowing them to perform more efficiently and handle a greater volume of requests.
Why Caching is Critical in Modern Systems
The imperative for caching stems directly from the architectural challenges of modern, distributed applications. Every millisecond counts, not just for user experience but also for operational cost and system scalability. Without effective caching, applications often encounter significant bottlenecks.
The Performance Bottleneck and Its Impact
Traditional data access involves several layers of abstraction, each introducing latency:
- Database Queries: Retrieving data from disk-based databases involves complex query processing, disk I/O operations, and network round-trips. These operations, especially for complex joins or large datasets, can be slow.
- External API Calls: Integrating with third-party services or microservices often entails network latency, serialization/deserialization overhead, and potential rate limits.
- Computational Overhead: Some data might require intensive computation to generate. Recalculating this data for every request is wasteful.
These latencies accumulate, leading to slower page load times, delayed user interactions, and a generally sluggish application. From a system perspective, constant high load on primary data sources can lead to resource exhaustion, requiring expensive scaling solutions (more powerful servers, database replication) or even system crashes under peak demand.
Benefits of Strategic Caching
Implementing a robust caching strategy delivers multiple critical advantages:
- Blazing Speed: By serving frequently requested data directly from fast memory, caching drastically reduces response times, often from hundreds of milliseconds to just a few microseconds. This translates to a snappier, more responsive user experience.
- Reduced Load on Primary Systems: Offloading read requests to a cache frees up primary databases, APIs, and computational resources. This allows these systems to focus on critical write operations or serve less frequently accessed data more efficiently, extending their lifespan and reducing operational costs.
- Enhanced Scalability: With less pressure on backend services, applications can handle a much larger number of concurrent users without degrading performance. Caching is often a prerequisite for achieving high scalability in web applications and services.
- Improved User Experience: Faster loading times and more fluid interactions directly contribute to higher user satisfaction, engagement, and retention. In today’s competitive digital landscape, user experience is a key differentiator.
- Resilience and Reliability: Caching can act as a buffer during transient database outages or network issues, allowing applications to serve stale data rather than failing completely, thus improving fault tolerance.
Redis as a Caching Solution: Features and Advantages
Redis shines as a caching solution due to its specific architectural choices and feature set, which address many common caching challenges effectively.
Key Features Optimizing Caching
- Rich Data Structures: Beyond simple key-value storage, Redis’s data structures (lists for message queues, sets for unique items, sorted sets for leaderboards) allow for intelligent caching strategies. For instance, a cache could store not just a single object but a list of recent activities or a sorted leaderboard, all readily accessible with high performance.
- Configurable Eviction Policies: Caches have finite memory. Redis offers several powerful eviction policies (e.g., Least Recently Used (LRU), Least Frequently Used (LFU), random, volatile-LRU) that automatically remove less valuable data when memory limits are reached. This intelligent management ensures the cache remains filled with the most relevant and frequently accessed data.
- Time-to-Live (TTL): Every key in Redis can be assigned a TTL, after which it automatically expires and is evicted from the cache. This is fundamental for managing data freshness and preventing stale data from being served.
- Atomic Operations: Redis operations are atomic, meaning they either complete entirely or not at all. This prevents race conditions and ensures data consistency, especially critical in concurrent environments where multiple clients might try to access or modify cached data simultaneously.
- High Availability and Replication: Redis supports primary-replica (master-slave) replication, allowing for read-scaling and data redundancy. Redis Sentinel provides automatic failover capabilities, enhancing the cache’s availability and resilience against node failures. Redis Cluster further enables sharding data across multiple nodes for horizontal scalability and even greater fault tolerance.
- Pub/Sub Messaging: While primarily a cache, Redis’s publish/subscribe (Pub/Sub) messaging paradigm can be used to notify clients when cached data changes or expires, facilitating cache invalidation and real-time updates across distributed systems.
Advantages Over Generic Caching
Compared to simpler in-process caches or other key-value stores, Redis offers:
- Network-Accessible: Being a standalone server, Redis can be accessed by multiple applications and services across a network, creating a shared, centralized cache layer.
- Persistence Options: While in-memory, Redis provides options for AOF (Append Only File) and RDB (Redis Database Backup) snapshots for persistence, enabling data recovery after restarts, a crucial feature that many pure in-memory caches lack.
- Mature Ecosystem: A vast community, extensive documentation, and client libraries for virtually every programming language make integrating and managing Redis straightforward.
Implementing Redis Cache: Strategies and Considerations
Effective Redis caching involves more than just dropping it into an application. Strategic implementation is key to maximizing its benefits and avoiding common pitfalls.
Common Caching Patterns
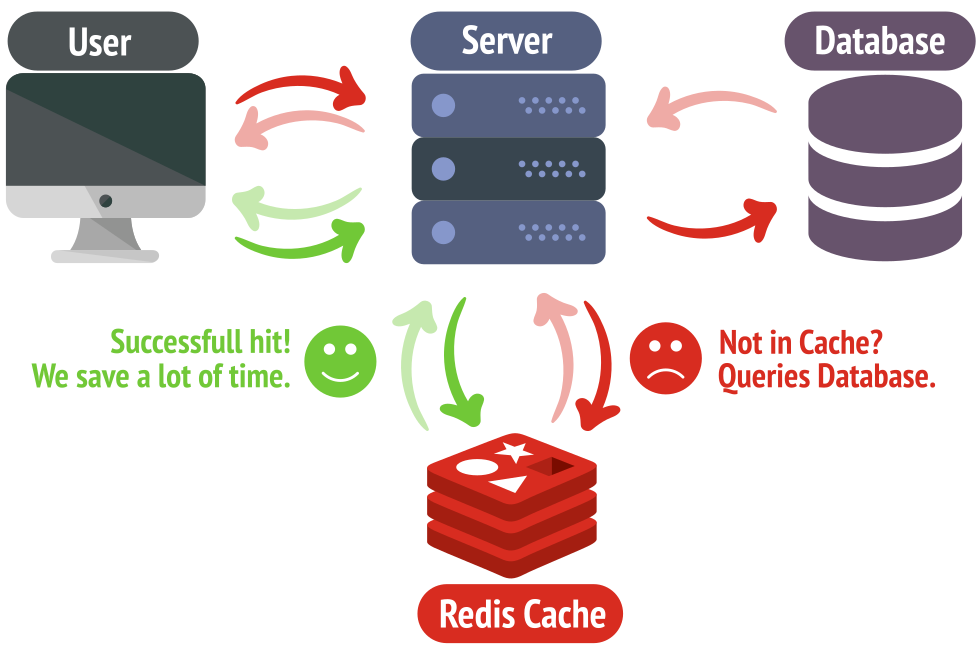
- Cache-Aside (Lazy Loading): This is the most common pattern. The application first checks if data exists in the cache. If found (a “cache hit”), it serves the data directly. If not (a “cache miss”), it retrieves the data from the primary database, stores it in the cache, and then returns it to the client. This ensures the cache only stores frequently requested data.
- Write-Through: In this pattern, data is written simultaneously to both the cache and the primary database. This ensures data consistency between the two but adds latency to write operations.
- Write-Behind (Write-Back): Data is written first to the cache, and then the write operation is acknowledged to the client. The cache asynchronously writes the data to the primary database. This offers high write performance but carries a risk of data loss if the cache fails before the data is persisted.
- Read-Through: Similar to cache-aside, but the cache itself is responsible for fetching data from the primary database on a miss, abstracting the data source from the application.
Critical Implementation Considerations
- Cache Invalidation: One of the hardest problems in computer science. How do you ensure cached data remains fresh and consistent with the primary data source? Strategies include using TTLs, active invalidation (e.g., through Pub/Sub or direct API calls to clear cache entries), and versioning.
- Data Serialization: Data stored in Redis is typically serialized into a string or binary format. Choosing an efficient serialization format (e.g., JSON, Protocol Buffers, MessagePack) is important for performance and storage efficiency.
- Memory Management: Monitoring Redis memory usage is crucial. Proper configuration of
maxmemoryandmaxmemory-policyensures the cache behaves predictably under memory pressure. - Network Latency: While Redis is fast, network latency between the application and the Redis server can impact performance. Locating Redis instances geographically close to applications or using connection pooling can mitigate this.
- High Availability and Scalability: For production systems, implementing Redis with replication, Sentinel for automatic failover, or Redis Cluster for sharding is essential to ensure continuous operation and horizontal scalability.

Redis Beyond Basic Caching: Expanding its Innovative Role
While caching is a primary use case, Redis’s rich feature set and performance enable it to serve many other critical roles in innovative tech stacks, underpinning real-time and high-performance applications.
- Session Store: Its speed and persistence options make Redis an ideal choice for storing user session data in stateless web applications, enabling seamless user experiences across multiple servers.
- Message Broker/Queue: With its Pub/Sub capabilities and list data structures, Redis can act as a lightweight message broker, facilitating communication between different services in a microservices architecture. Redis Streams, a more advanced data structure, provides a persistent, append-only log that supports consumer groups for robust message queuing.
- Real-time Analytics: The ability to rapidly increment counters, perform set operations, and manage sorted sets makes Redis excellent for real-time dashboards, leaderboards, and analytics, processing event streams with low latency.
- Rate Limiting: Using atomic increment operations and TTLs, Redis can effectively implement distributed rate limiting for APIs, protecting backend services from abuse.
- Geospatial Indexing: Redis’s
GEOcommands allow for storing and querying geospatial data, enabling features like “find nearby locations” with remarkable efficiency, critical for mapping and location-aware applications. - Distributed Locks: Redis can be used to implement simple, yet effective, distributed locks, coordinating access to shared resources across multiple application instances.
Redis is not merely a utility; it’s a foundational technology that empowers developers to build applications that are not only fast and scalable but also capable of handling complex, real-time data challenges that drive continuous tech innovation. Its enduring popularity stems from its powerful combination of simplicity, performance, and versatility, making it an indispensable tool for architecting the next generation of high-performance digital services.