
In the rapidly evolving landscape of autonomous systems and intelligent robotics, particularly within drone technology, the concept of a machine learning from its own experiences is not merely futuristic speculation but a present-day reality. At the heart of many such advancements lies Reinforcement Learning (RL), a powerful paradigm enabling systems to make decisions in complex environments. Among the foundational algorithms in this field, Q-learning stands out as a simple yet remarkably effective method for an agent to learn optimal policies through trial and error, without requiring a pre-existing model of its environment. This ability to adapt and learn from interactions is transforming how drones navigate, perform tasks, and interact with the world, pushing the boundaries of what autonomous flight can achieve in the realm of Tech & Innovation.
The Core Concept of Reinforcement Learning
Reinforcement Learning (RL) is a branch of machine learning where an “agent” learns to make sequential decisions by interacting with an “environment.” The agent’s goal is to maximize a cumulative reward signal it receives from the environment over time. Unlike supervised learning, which relies on labeled datasets, or unsupervised learning, which finds hidden patterns, RL thrives on feedback, learning from the consequences of its actions. This trial-and-error approach is particularly suited for dynamic and unpredictable scenarios, precisely the challenges faced by advanced drone operations.
Agents, Environments, States, and Actions
To understand Q-learning, it’s essential to grasp the fundamental components of an RL system. The agent is the decision-maker, in our context, the intelligent control system of a drone. The environment is the world the agent interacts with—for a drone, this could be the airspace, terrain, weather conditions, or even other objects and vehicles. The agent perceives the environment’s current state, which encapsulates all relevant information needed to make a decision, such as the drone’s GPS coordinates, altitude, velocity, battery level, camera feed, or obstacle proximity data. Based on this state, the agent chooses an action from a set of available options, like “move forward,” “ascend,” “turn left,” “increase speed,” or “activate gimbal.” Each action transitions the environment into a new state.
Rewards and Policies
After taking an action, the agent receives a reward signal from the environment. This reward can be positive for desirable outcomes (e.g., reaching a waypoint, avoiding a collision, capturing a high-quality image) or negative for undesirable ones (e.g., consuming too much fuel, crashing, entering restricted airspace). The agent’s ultimate objective is to learn a policy, which is a mapping from states to actions, guiding it to choose actions that maximize the total cumulative reward over the long run. For drones, a well-learned policy could translate into optimal mission completion, energy efficiency, or superior navigation capabilities, directly contributing to advancements in autonomous flight and intelligent surveillance.
Unpacking Q-Learning: The Value of Actions
Q-learning is a model-free reinforcement learning algorithm, meaning it doesn’t require a pre-built model of how the environment works. Instead, it learns the value of taking specific actions in specific states directly from experience. This makes it particularly robust for real-world applications where creating an accurate environmental model might be impossible or prohibitively complex, a common scenario in dynamic drone operations.
The Q-Table: Mapping State-Action Pairs
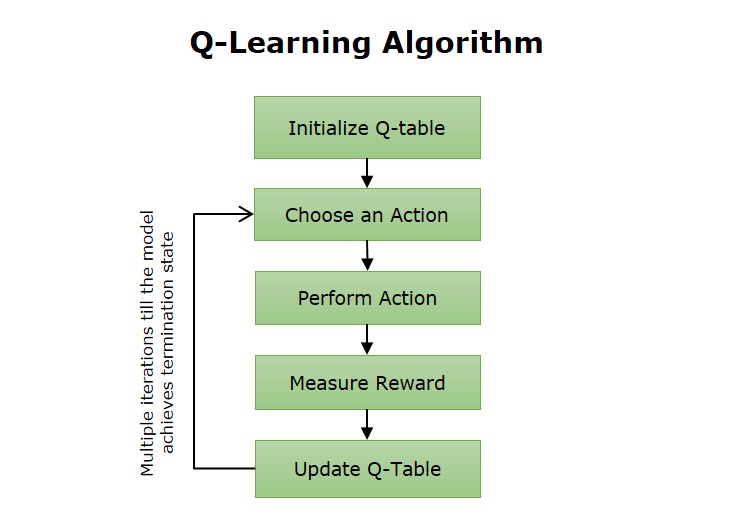
The core of Q-learning is the “Q-table” (or Q-function). This table stores the “quality” or expected maximum future reward for taking a particular action from a particular state. Each entry in the Q-table, denoted as Q(state, action), represents the value of performing a specific action when the agent is in a given state. Imagine a drone learning to navigate a cluttered warehouse: the Q-table might store values for actions like “move forward,” “turn left,” “hover” when in states such as “near obstacle ahead,” “clear path left,” or “target visible.” The drone consults this table to decide the most rewarding action to take next. The challenge for drones operating in vast and complex environments is that the number of possible states and actions can be enormous, leading to massive Q-tables.
The Bellman Equation and Iterative Updates
The learning process in Q-learning is driven by an iterative update rule derived from the Bellman equation. When the agent takes an action, observes the immediate reward, and transitions to a new state, it updates the Q-value for the previous state-action pair. The update rule incorporates the immediate reward, the Q-value of the current state-action pair, and the maximum Q-value of the new state. This process essentially tells the agent: “The value of taking this action in this state should be adjusted based on the reward I just got and the best possible future rewards I can expect from the next state.” Over many interactions, these updates allow the Q-values to converge towards optimal values, reflecting the true long-term expected reward for each state-action pair. This continuous learning from interaction makes Q-learning highly adaptive, enabling drones to refine their operational strategies over countless simulated or real-world flights.
Exploration vs. Exploitation: Balancing Discovery and Performance
A crucial aspect of Q-learning, and indeed all reinforcement learning, is finding the right balance between exploration and exploitation. Exploration involves trying new actions to discover potentially better strategies or uncover unknown aspects of the environment. For a drone, this might mean trying a novel flight path to see if it’s more efficient or safer. Exploitation involves choosing the action that is currently known to yield the highest reward, based on the current Q-table values. This means sticking to proven good strategies.
An agent that only explores might never fully leverage its learned knowledge, while an agent that only exploits might get stuck in suboptimal local maxima, never discovering better paths. The common strategy to balance this is the ε-greedy approach: with a small probability ε (epsilon), the agent chooses a random action (exploration), and with probability (1-ε), it chooses the action with the highest Q-value (exploitation). This ensures the drone continues to learn and improve while generally striving for optimal performance, leading to more robust and intelligent autonomous flight systems.

Q-Learning in the Realm of Drone Technology
The principles of Q-learning, with its ability to learn optimal policies through trial and error, are incredibly potent when applied to the complexities of drone operations. Its model-free nature allows drones to adapt to highly dynamic and uncertain environments, a cornerstone of advanced Tech & Innovation.
Autonomous Navigation and Pathfinding
One of the most direct applications of Q-learning in drones is in autonomous navigation and pathfinding. A drone can learn to navigate complex environments, such as urban landscapes, dense forests, or disaster zones, by treating its location and surrounding sensor data as states. Actions would involve movements in various directions. Through Q-learning, the drone can learn optimal paths that minimize flight time, avoid restricted airspace, conserve battery power, or reach a target destination most efficiently. This is especially valuable in dynamic environments where pre-programmed routes might quickly become obsolete due to changing conditions or newly identified obstacles. The drone continuously refines its Q-table, learning from successful traversals and penalizing inefficient or risky maneuvers.
Obstacle Avoidance Strategies
Obstacle avoidance is critical for drone safety and mission success. Q-learning provides a robust framework for drones to learn effective collision avoidance strategies. By sensing its proximity to objects (using LiDAR, sonar, or computer vision), the drone can treat different proximity states as inputs. If an action leads to a collision (negative reward), the corresponding Q-value is lowered. Conversely, successfully maneuvering around an obstacle (positive reward) reinforces the Q-value for that action-state pair. Over time, the drone develops a sophisticated “instinct” for avoiding collisions, adapting to novel obstacles and unpredictable movements in its environment, far beyond what rule-based programming could achieve. This capability is vital for autonomous drones operating in crowded airspace or confined spaces.
Adaptive Flight Control Systems
Drones often operate in environments with varying conditions, such as changing wind patterns, rain, or shifts in payload weight. Traditional PID controllers can struggle to adapt quickly to these changes. Q-learning offers a pathway to more adaptive flight control. A drone’s flight control system can learn to adjust motor thrusts, rotor speeds, and gimbal stabilization based on real-time feedback about stability and desired trajectory. For instance, if unexpected turbulence causes deviation from a planned path, the Q-learning agent can learn which corrective actions (e.g., adjusting pitch, roll, or yaw) efficiently bring the drone back to its desired state, optimizing its stability and performance under diverse and challenging environmental conditions. This ability to continuously adapt enhances reliability and expands the operational envelope for drones.
Intelligent Payload Management and Task Execution
Beyond flight, Q-learning can optimize how drones manage their payloads and execute specific tasks. Consider a surveillance drone equipped with multiple sensors (e.g., thermal, optical zoom, LiDAR). A Q-learning agent could learn the optimal times and locations to activate specific sensors to maximize data collection efficiency or identify targets more effectively. For a delivery drone, Q-learning could optimize the dropping mechanism’s timing and trajectory based on wind conditions and target characteristics, maximizing successful deliveries while minimizing energy expenditure. In search and rescue operations, a drone could learn the most effective search patterns based on terrain, weather, and known victim behaviors, vastly improving the efficiency and success rates of missions. This extends drone intelligence from just flying to intelligent task completion, unlocking new possibilities in various industries.
Challenges and Future Prospects for Q-Learning in Drones
While Q-learning presents immense potential for advancing drone intelligence, its application also comes with significant challenges. Addressing these hurdles is key to unlocking the next generation of autonomous drone capabilities.
Computational Demands and Real-time Processing
One of the primary challenges for traditional Q-learning in complex drone applications is the sheer size of the Q-table. As the number of possible states and actions grows exponentially with environmental complexity (e.g., continuous sensor readings like precise GPS coordinates or high-resolution camera feeds), the Q-table can become prohibitively large, requiring immense memory and computational power. Drones, particularly smaller ones, often have limited on-board processing capabilities and power budgets. This makes direct Q-table implementation impractical for many real-world scenarios requiring real-time decision-making. Researchers are actively working on more efficient representations and approximation methods to overcome these constraints, enabling Q-learning to function effectively on edge devices.
The Reality Gap: Simulation to Real-World Transfer
Training Q-learning agents often occurs in simulated environments, which offer a safe, cost-effective, and accelerated way to gather vast amounts of experience. However, a significant hurdle is the “reality gap”—the discrepancy between simulated and real-world physics, sensor noise, and environmental dynamics. A policy learned in a pristine simulation might perform poorly when deployed on a physical drone in the messy, unpredictable real world. Bridging this gap requires sophisticated simulation fidelity, robust transfer learning techniques, and potentially continuous fine-tuning in the real environment, albeit carefully and safely. Overcoming the reality gap is paramount for bringing advanced Q-learning drone applications from the lab to widespread practical deployment.

Integration with Deep Learning: Deep Q-Networks (DQNs)
The scalability issues of Q-tables for high-dimensional state spaces have led to a revolutionary advancement: the integration of Q-learning with deep neural networks, giving rise to Deep Q-Networks (DQNs). Instead of explicitly storing a Q-table, a DQN uses a neural network to approximate the Q-function. This allows the agent to handle continuous and high-dimensional state inputs, such as raw image data from a drone’s camera, without the need for manual feature engineering. The neural network learns to predict the Q-values for different actions in a given state. DQNs have demonstrated remarkable success in complex tasks, like playing video games at a superhuman level, and are now being actively explored for drone applications. This deep reinforcement learning approach offers a powerful solution for developing highly intelligent, adaptive, and perception-driven autonomous drone systems, paving the way for advanced AI Follow Mode, sophisticated object recognition, and truly autonomous mission execution in complex, real-world environments. The synergy between Q-learning and deep learning is set to unlock unprecedented levels of intelligence and autonomy in the future of drone technology.