
The Evolution of Application Deployment
The landscape of software development and deployment has undergone a profound transformation over the past two decades. What began with monolithic applications—single, large codebases encompassing all functionalities—has evolved into highly distributed, modular systems. This paradigm shift was driven by the increasing demand for scalability, resilience, and rapid iteration, necessitating more agile and efficient deployment strategies.
From Monoliths to Microservices
Traditionally, applications were built as monolithic units, where all components—user interface, business logic, and data access layers—were tightly coupled within a single executable. While simpler to develop initially for small projects, monoliths presented significant challenges as applications grew. Updating a small feature required redeploying the entire application, leading to slower release cycles and increased risk of downtime. Scaling became difficult, as the entire monolith had to be scaled even if only a single component faced high demand.

The rise of the microservices architecture addressed these issues by advocating for the decomposition of applications into a collection of small, independent services. Each microservice is responsible for a specific business capability, runs in its own process, and communicates with other services through well-defined APIs. This modularity enables independent development, deployment, and scaling of individual services, fostering greater agility and robustness. However, managing a multitude of these interdependent services introduced a new layer of complexity: orchestration.
The Rise of Containerization
Concurrent with the shift to microservices was the innovation of containerization. Technologies like Docker revolutionized how applications and their dependencies are packaged. Containers encapsulate an application, its runtime, libraries, and configuration files into a standardized, portable unit. Unlike virtual machines, containers share the host operating system’s kernel, making them lightweight and fast to start.
Containerization solved the notorious “it works on my machine” problem by ensuring consistency across different environments—from development to testing to production. This portability became crucial for microservices, as it allowed developers to package each service into its own container, guaranteeing predictable behavior regardless of where it ran. However, while containers simplified packaging and deployment of individual services, managing hundreds or thousands of these containers across a distributed infrastructure quickly became an arduous task, paving the way for advanced orchestration solutions.
Understanding Kubernetes: An Orchestration Powerhouse
Kubernetes, often abbreviated as K8s, emerged as the leading open-source platform for automating the deployment, scaling, and management of containerized applications. Conceived by Google and now maintained by the Cloud Native Computing Foundation (CNCF), Kubernetes provides a robust framework to orchestrate containers across a cluster of machines, abstracts away the underlying infrastructure, and offers powerful features to ensure applications are always running, resilient, and scalable.
Core Concepts: Pods, Nodes, and Clusters
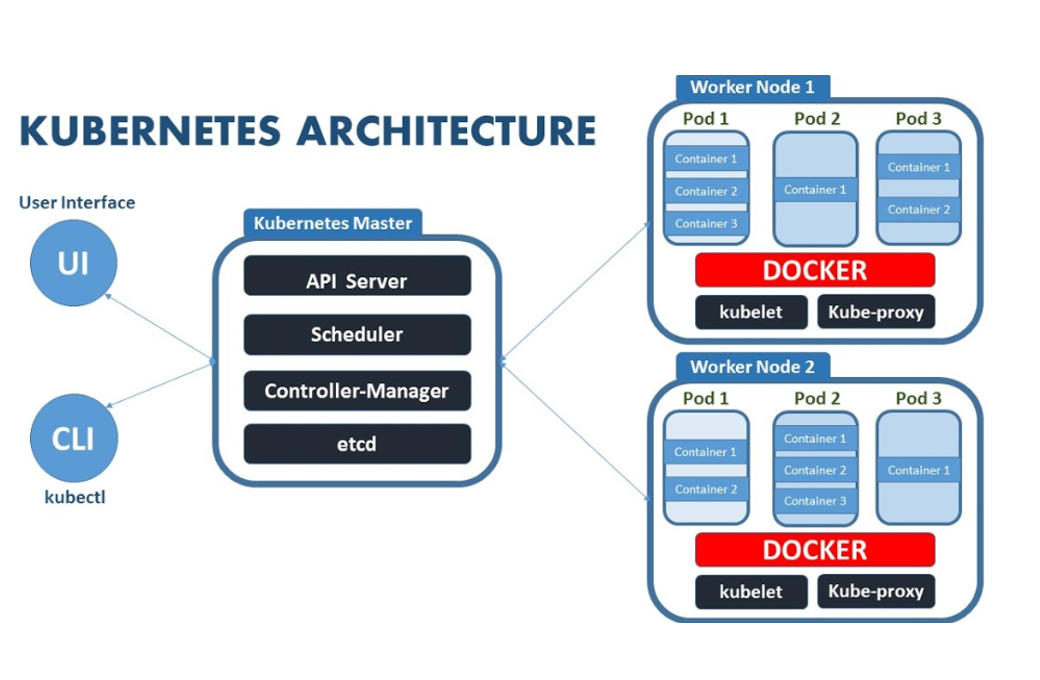
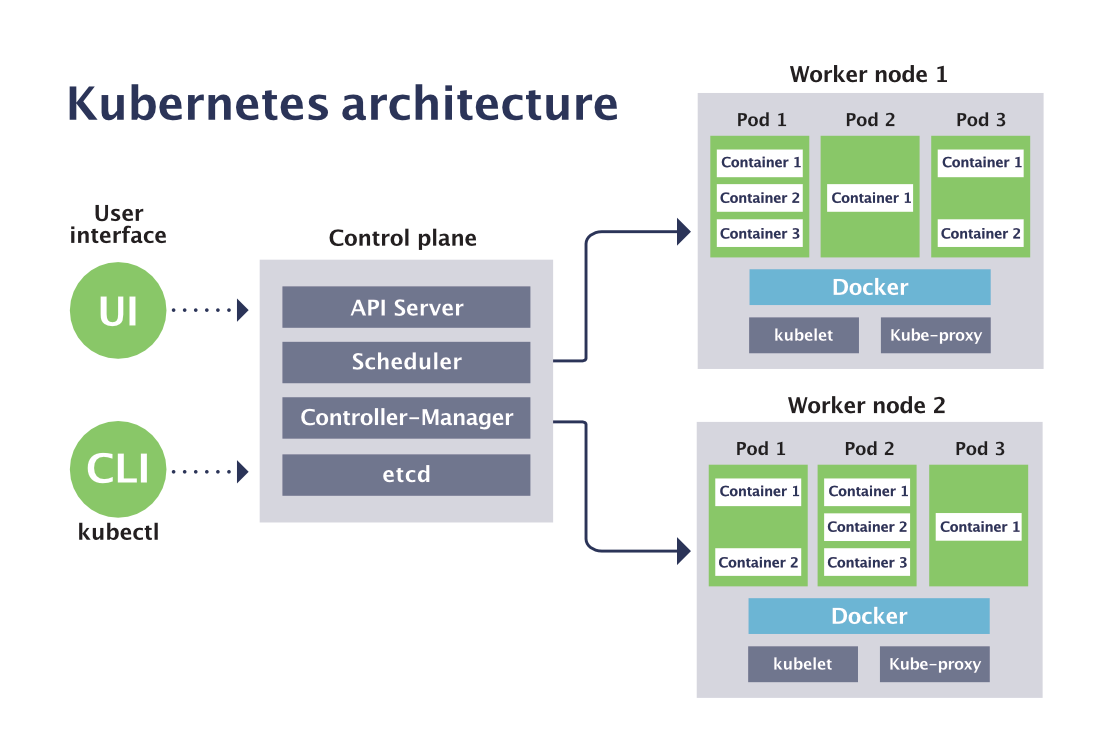
At its heart, Kubernetes operates on a few fundamental concepts. A Pod is the smallest deployable unit in Kubernetes. It’s an abstraction over a container, typically encapsulating one or more containers that share network and storage resources, acting as a single logical application. If an application needs more than one container (e.g., an application container and a sidecar logging agent), they are grouped into a single Pod.
Nodes are the worker machines (physical or virtual servers) that run your applications. Each node hosts one or more Pods. A Kubernetes Cluster is a set of nodes managed by a control plane. The control plane orchestrates the entire cluster, making decisions about where to schedule Pods, detecting and responding to cluster events, and ensuring the desired state of the system is maintained. This architecture allows developers to focus on application logic, abstracting the complexities of underlying infrastructure management.
Managing State and Persistence
Modern applications often require persistent storage for data that needs to survive beyond the life of a Pod, such as databases or user-uploaded files. Kubernetes addresses this through various storage mechanisms, including Persistent Volumes (PVs) and Persistent Volume Claims (PVCs). A PV is a piece of storage in the cluster that has been provisioned by an administrator or dynamically provisioned using Storage Classes. A PVC is a request for storage by a user. Kubernetes automatically matches PVCs with available PVs, ensuring that applications requiring persistent data can access it reliably, even if the Pod itself is restarted or moved to a different node. This capability is critical for stateful applications, providing durability and data integrity.
Self-Healing and Scalability
One of Kubernetes’ most compelling features is its inherent ability to self-heal and scale applications automatically. The control plane continuously monitors the health of Pods and nodes. If a Pod fails, Kubernetes automatically restarts it. If a node goes down, Kubernetes reschedules the Pods running on that node to healthy ones. This self-healing mechanism significantly enhances application reliability and availability, reducing the need for manual intervention.
For scalability, Kubernetes supports both horizontal and vertical scaling. Horizontal Pod Autoscaling (HPA) automatically adjusts the number of Pod replicas in a Deployment or ReplicaSet based on observed CPU utilization or other custom metrics. This ensures that applications can handle varying loads dynamically without over-provisioning resources. Vertical Pod Autoscaling (VPA), though more complex, helps adjust CPU and memory requests and limits for containers based on their historical usage, optimizing resource allocation within existing Pods. This combination of self-healing and autoscaling makes Kubernetes an ideal platform for building resilient, high-performance distributed systems.
Key Features Driving Modern Innovation
Kubernetes’ comprehensive feature set is designed to streamline operations, enhance developer productivity, and ensure robust application performance in dynamic environments. Its capabilities extend far beyond basic container management, offering a powerful platform for continuous delivery and operation of sophisticated applications.
Automated Rollouts and Rollbacks
Deploying new versions of an application is a critical and often risky process. Kubernetes simplifies this with automated rollouts and rollbacks. When a new version of an application (a new container image) is specified in a Deployment, Kubernetes performs a controlled rollout, gradually replacing old Pods with new ones while monitoring their health. This “rolling update” strategy ensures that the application remains available during the update process and minimizes downtime.
Should a new deployment introduce issues, Kubernetes provides the ability to automatically or manually roll back to a previous stable version with minimal disruption. This confidence in safe deployment and quick recovery empowers teams to iterate faster, knowing that they can revert changes swiftly if problems arise. This capability is crucial for maintaining high availability and rapid feature delivery.
Service Discovery and Load Balancing
In a microservices architecture, services need to find and communicate with each other efficiently. Kubernetes solves this with built-in service discovery. When a set of Pods is deployed, Kubernetes assigns them a stable network name (a “Service”) and an IP address. Other Pods within the cluster can then communicate with these services using their names, without needing to know the specific IP addresses of individual Pods, which can change frequently.
Furthermore, Kubernetes Services provide integrated load balancing. When multiple Pods are behind a Service, incoming requests are automatically distributed across them, ensuring even traffic distribution and maximizing resource utilization. This abstraction simplifies application networking, making it easy to expose services internally within the cluster or externally to the internet, all while ensuring high availability and efficient resource use.
Configuration and Secret Management
Applications often require configuration data (e.g., database connection strings, API keys) that varies between environments (development, staging, production) or should be kept secure. Kubernetes offers robust mechanisms for managing this sensitive information. ConfigMaps are used to store non-confidential configuration data as key-value pairs, which can then be mounted into Pods as files or injected as environment variables. This decouples configuration from application code, making applications more portable and easier to manage.
For sensitive information, Kubernetes provides Secrets. Secrets are designed to hold confidential data such as passwords, OAuth tokens, and SSH keys. They are stored encrypted (or base64 encoded by default, with additional encryption at rest possible depending on the cluster setup) and can be mounted into Pods as files or environment variables, similar to ConfigMaps. This secure handling of sensitive data is paramount for maintaining the integrity and security of applications deployed on the platform.
Kubernetes as an Enabler for Advanced Tech & Innovation
While Kubernetes is an infrastructure technology, its robust capabilities make it a foundational enabler for many cutting-edge innovations in diverse technological domains. By providing a scalable, resilient, and automated platform for running complex applications, Kubernetes empowers the development and deployment of sophisticated systems that drive advancements across various sectors.
Powering AI and Machine Learning Workloads
The rapid advancements in Artificial Intelligence and Machine Learning (AI/ML) necessitate powerful and flexible computing infrastructure. Training complex machine learning models often requires significant computational resources, including GPUs, and the ability to scale these resources on demand. Kubernetes is exceptionally well-suited for orchestrating these AI/ML workloads. It can schedule GPU-enabled Pods, manage distributed training jobs, and provide the elasticity needed to handle fluctuating computational demands. Furthermore, deploying and managing trained models for inference (e.g., for AI Follow Mode or object recognition) can be easily handled by Kubernetes, ensuring high availability and low latency for real-time predictions. This makes Kubernetes a key component in the operationalization of AI initiatives.
Backend for Autonomous Systems and Real-time Processing
Autonomous systems, whether in robotics, logistics, or transportation, rely heavily on real-time data processing, complex decision-making algorithms, and constant communication with various sensors and actuators. The backend infrastructure supporting such systems must be incredibly resilient, scalable, and capable of handling high-throughput, low-latency operations. Kubernetes provides the ideal platform for building these critical backends. It can orchestrate microservices that process sensor data, run control algorithms, and manage communication protocols. Its self-healing capabilities ensure that even if components fail, the overall autonomous system remains operational, making it invaluable for maintaining continuous functionality in mission-critical applications like Autonomous Flight systems.
Edge Computing for Distributed Intelligence
As computing moves closer to the data source—a concept known as edge computing—Kubernetes is playing an increasingly important role. In scenarios where data needs to be processed locally for immediate action or to reduce network latency, deploying lightweight Kubernetes clusters at the edge allows for consistent management of applications across distributed locations. This is particularly relevant for systems engaged in Remote Sensing and Mapping, where vast amounts of data are collected. Processing this data at the edge, before transmitting summarized information to central clouds, can significantly enhance efficiency and responsiveness, driving real-time insights for critical operations.
Streamlining Data Processing for Mapping and Remote Sensing
Remote sensing and mapping applications often involve collecting, processing, and analyzing massive datasets, including high-resolution imagery and geospatial information. These workflows typically require powerful, scalable data pipelines and analytics platforms. Kubernetes excels at orchestrating these complex data processing tasks. It can manage distributed storage systems, run parallel processing jobs, and deploy analytics applications that transform raw sensor data into actionable insights. By providing a flexible and scalable infrastructure, Kubernetes enables faster data ingestion, more efficient processing, and quicker generation of valuable maps and environmental intelligence from remote sensing missions.
The Future Landscape with Kubernetes
Kubernetes has cemented its position as a cornerstone of modern cloud-native computing. Its robust capabilities for automating containerized workloads have made it indispensable for organizations seeking to build resilient, scalable, and agile applications. The platform continues to evolve, driven by a vibrant open-source community and increasing enterprise adoption.
Cloud-Native Dominance
Kubernetes is synonymous with the cloud-native movement, providing the essential orchestration layer that enables applications to thrive in dynamic, multi-cloud, and hybrid-cloud environments. Its declarative API allows developers to define the desired state of their applications, letting Kubernetes continuously work to achieve and maintain that state, abstracting away underlying infrastructure complexities. This paradigm shift will continue to drive innovation in how software is developed, deployed, and managed.
Community and Ecosystem Growth
The strength of Kubernetes lies not only in its core features but also in its massive, active community and extensive ecosystem of tools and integrations. This vibrant community constantly contributes new features, bug fixes, and best practices, ensuring the platform remains at the forefront of technological advancement. The proliferation of complementary tools for monitoring, security, networking, and CI/CD further extends Kubernetes’ capabilities, solidifying its role as a pervasive and enduring technology in the world of modern software infrastructure.