
Imagen, a groundbreaking innovation from Google AI, represents a pivotal leap in the realm of digital imaging. Far from a physical camera or a traditional image editing suite, Imagen is a sophisticated text-to-image diffusion model engineered to generate high-fidelity, photorealistic images solely from natural language descriptions. It fundamentally redefines how images can be conceived and created, pushing the boundaries beyond capture and manipulation into the domain of synthetic generation. In the broader landscape of imaging technology, Imagen stands as a testament to the profound convergence of artificial intelligence and visual artistry, offering a powerful new tool for visual content creation that complements and expands upon established photographic and design practices.
A New Frontier in Digital Imaging
At its core, Imagen is an advanced AI system capable of translating complex textual prompts into detailed and visually coherent images. This capability places it at the forefront of a new era of imaging, where the artist’s or creator’s imagination, articulated through language, can be instantly materialized into a visual form. Unlike traditional imaging processes that rely on light capture through lenses, or even digital art created pixel by pixel, Imagen operates on a deep understanding of semantics and visual patterns learned from an immense dataset of images and their corresponding textual descriptions.
The significance of Imagen within the “Cameras & Imaging” domain cannot be overstated. While cameras historically have been the primary means of creating images of the real world, and digital software has allowed for their manipulation, Imagen introduces a third pillar: the direct synthesis of imagery from abstract concepts. This technology is not merely about stitching together existing images; it’s about generating novel compositions, textures, lighting, and perspectives that may have never existed before in a photographic sense. It represents an evolution in what “imaging” entails, broadening its scope to include intelligent generation as a powerful complement to traditional capture and processing techniques. The model’s ability to render intricate details, accurate shadows, and consistent styles makes the generated output remarkably convincing, blurring the lines between photographed reality and AI-synthesized visuals.
The Core Mechanics: From Text to Visuals
Imagen’s impressive ability to transform text into vivid imagery is rooted in a sophisticated architecture that combines advanced deep learning techniques. This process isn’t a simple lookup; it involves a nuanced understanding of language and an iterative, creative process to construct images from scratch.
Understanding Diffusion Models
The cornerstone of Imagen’s image generation capability is its reliance on a class of generative models known as diffusion models. These models operate on an ingenious principle: they learn to progressively “denoise” an image from pure static, iteratively transforming random pixels into a coherent visual representation guided by a specific condition – in Imagen’s case, a text prompt. The process can be conceptualized as starting with a canvas of random noise and then, through a series of precise steps, gradually removing that noise while simultaneously shaping the pixels to match the desired textual description.
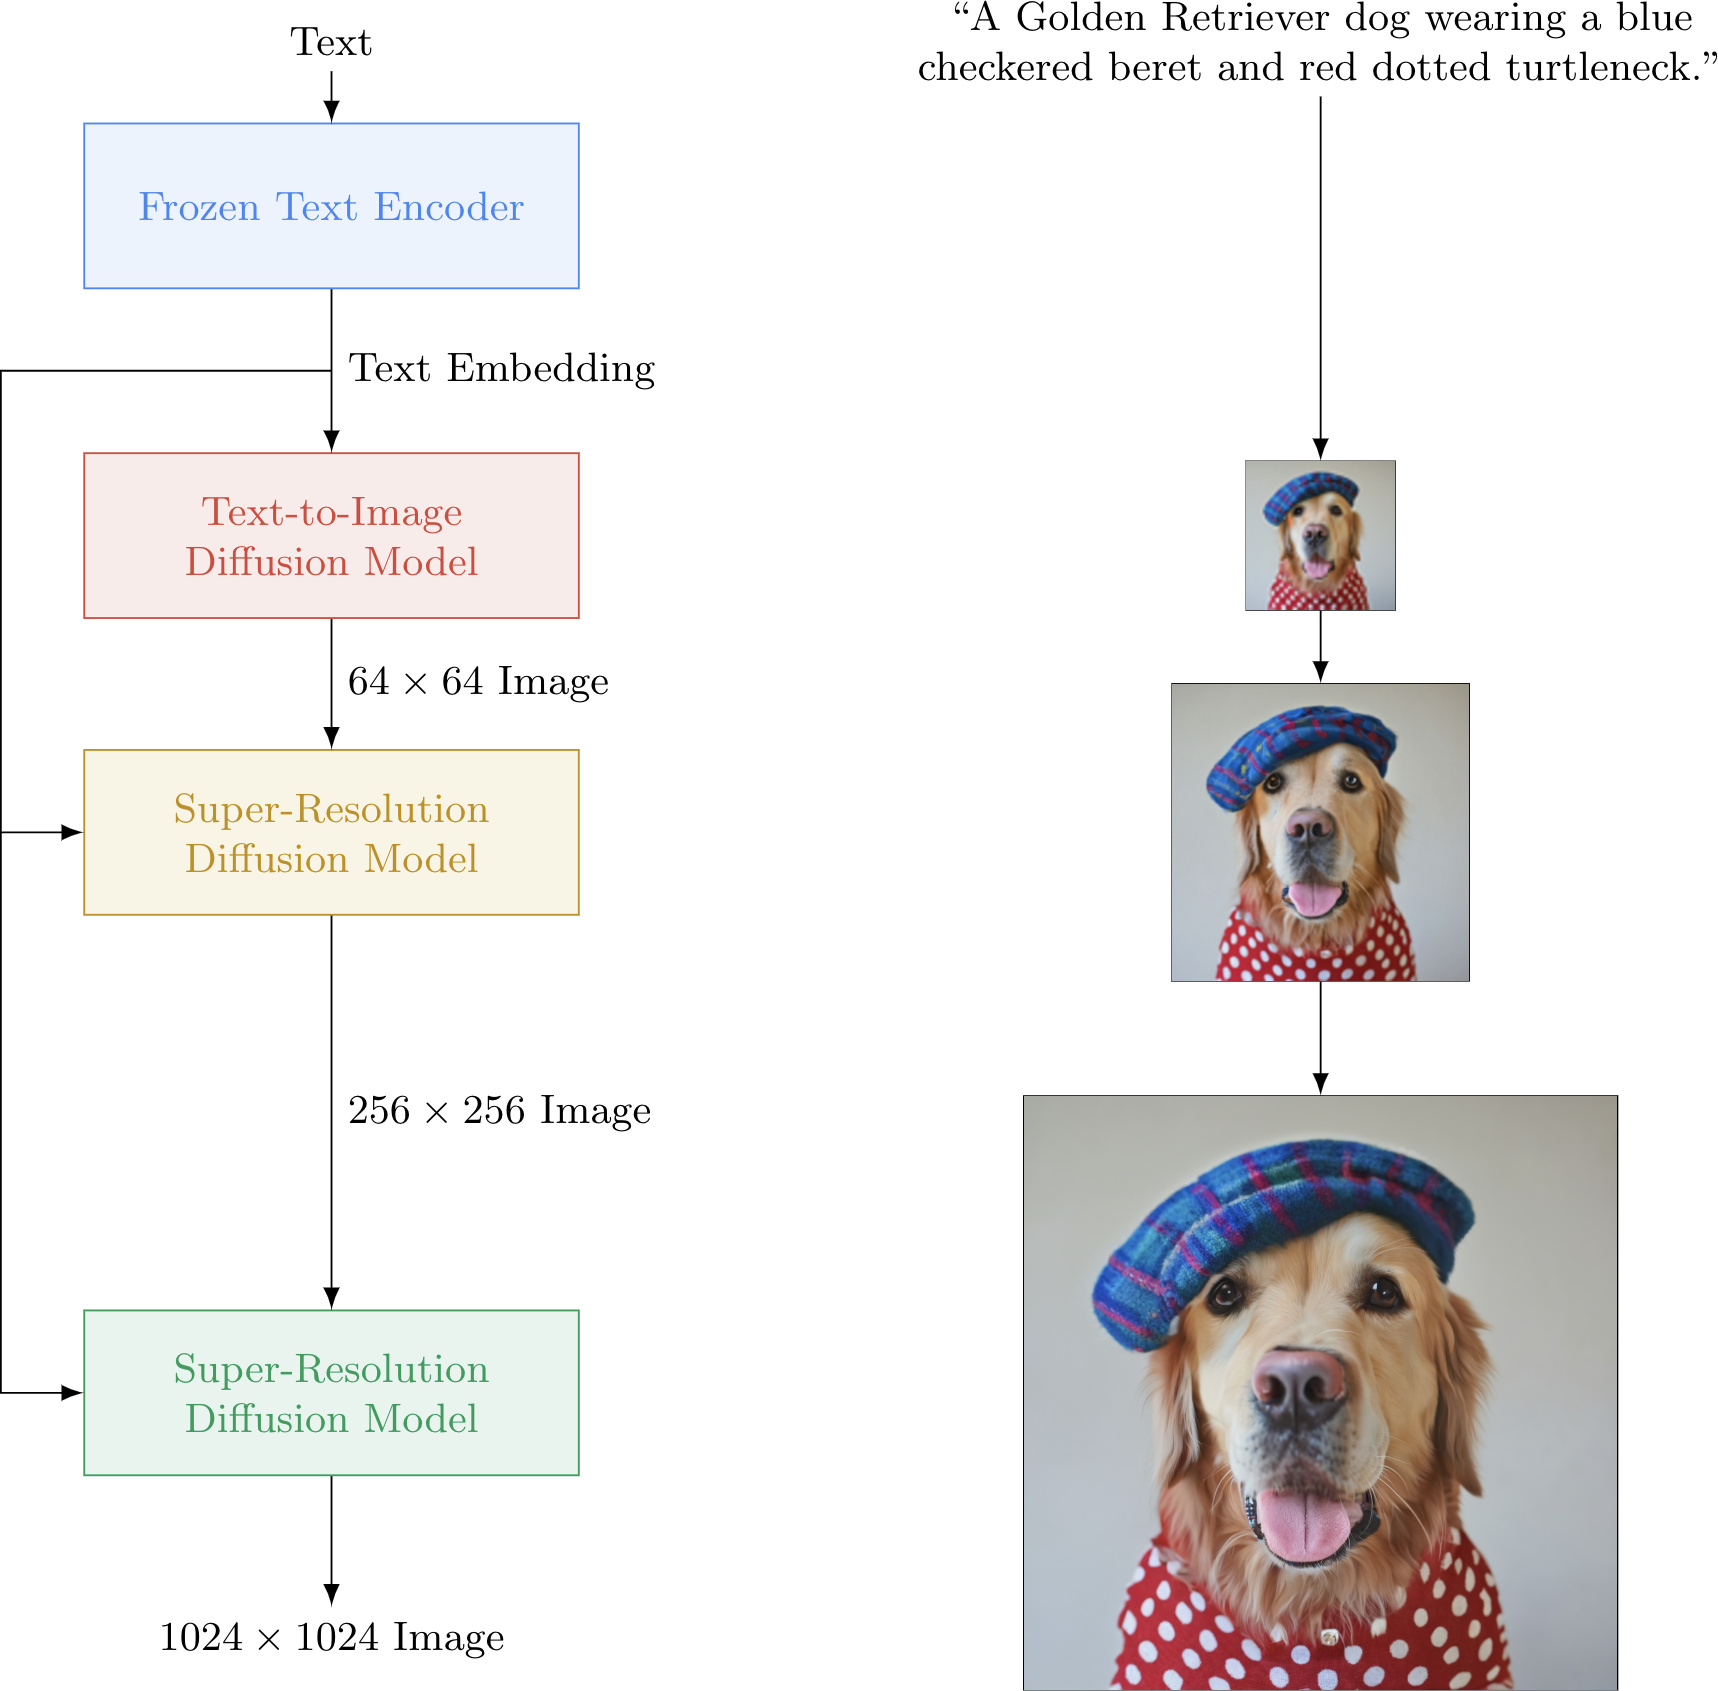
During its training phase, a diffusion model learns to reverse a process of gradually adding noise to images until they become pure static. By learning this reverse process, the model can then be prompted to start with pure noise and predict how to remove the noise in a way that generates a specific image. Imagen employs a cascade of diffusion models, meaning it uses multiple models in sequence. A base diffusion model generates a low-resolution image from the text prompt. Subsequent “super-resolution” diffusion models then take this low-resolution image and upsample it, adding finer and finer details, until a high-resolution, photorealistic image is produced. This cascaded approach is critical for achieving both semantic fidelity to the prompt and high visual quality at larger resolutions, effectively addressing the challenge of generating images with intricate textures and sharp edges.
The Role of Language Understanding
What truly sets Imagen apart is not just its robust image generation, but its unparalleled understanding of natural language. To achieve its impressive results, Imagen leverages very large transformer-based language models, such as those derived from Google’s expertise in large language models (like T5). These language models are responsible for interpreting the user’s text prompt, no matter how complex or nuanced, and translating it into an embedding – a numerical representation that the diffusion models can understand and act upon.
The quality of the generated image is profoundly tied to the model’s ability to grasp the subtleties of the input text. This includes understanding not just individual words, but also their relationships, context, stylistic requests, and even abstract concepts. For example, a prompt like “a serene minimalist landscape with soft morning light, digital art style” requires the language model to understand “serene,” “minimalist,” “soft morning light,” and “digital art style” as distinct visual characteristics and then guide the diffusion process to incorporate all these elements cohesively. This deep semantic understanding allows Imagen to create images that are not just syntactically correct but also aesthetically pleasing and conceptually aligned with the user’s intent, offering a level of creative control previously unimaginable through automated systems.
Image Fidelity and Realism

Imagen’s outputs are celebrated for their exceptional image fidelity and striking realism. This stems from several factors, including the quality of its training data, the effectiveness of its cascaded diffusion architecture, and the sophisticated alignment between its language understanding and image generation components. The model has been trained on massive datasets of text-image pairs, allowing it to learn an incredible diversity of visual concepts, styles, and details.
The super-resolution steps in the cascaded diffusion process are particularly crucial for achieving this realism. They ensure that even the smallest details, such as reflections in water, textures on surfaces, or subtle variations in light and shadow, are rendered with convincing accuracy. This goes beyond merely producing a recognizable shape; it involves capturing the intricate visual information that makes an image feel authentic and lifelike. The result is a capability to generate images with a clarity, sharpness, and textural richness that can rival professional photography or CGI, without the need for a physical camera, lenses, or complex rendering software. This high level of fidelity positions Imagen as a powerful tool for creators seeking to visualize concepts with unprecedented realism and detail, pushing the boundaries of what is possible in digital imaging.
Impact on Visual Content Creation and Beyond
Imagen represents a paradigm shift with profound implications across various aspects of visual content creation, offering new avenues and efficiencies for professionals and enthusiasts alike within the imaging ecosystem.
Augmenting Traditional Imaging Workflows
For professionals in fields such as graphic design, advertising, concept art, and even aerial filmmaking pre-visualization, Imagen offers a powerful new augmentation to existing workflows. Artists and designers can leverage Imagen to rapidly prototype ideas, generate multiple variations of a concept, or create mood boards in mere seconds. Instead of spending hours sketching or scouring stock photo libraries for specific visuals, a precise text prompt can yield a diverse array of potential images, accelerating the initial creative phases. For instance, an aerial filmmaker planning a complex shot can use Imagen to visualize a specific landscape with particular weather conditions, lighting, and architectural elements, helping them storyboard and plan their flight paths and camera angles before deploying a physical drone. This ability to instantly manifest complex visual ideas significantly reduces the time and resources traditionally required for visual ideation and asset creation. It doesn’t replace the need for skilled photography or design, but rather empowers creators with an unparalleled rapid visualization tool.
Expanding Creative Possibilities
Perhaps the most exciting aspect of Imagen is its capacity to expand the boundaries of creative expression. It enables the creation of images depicting impossible scenarios, fantastical beings, historical events that were never photographed, or abstract concepts with a level of realism and detail previously unimaginable. An artist can envision a “cyberpunk cityscape at sunset with flying vehicles and neon-lit ramen stalls” and have a highly detailed image generated within moments. This capability democratizes high-quality visual content creation, allowing individuals without extensive photography skills, specialized equipment, or expensive software licenses to generate professional-grade visuals. It unlocks new creative avenues for storytellers, game developers, educators, and marketers, allowing them to bring their most imaginative ideas to life visually, fostering a new era of visual storytelling unbound by the constraints of physical reality or manual artistic effort.
Challenges and Ethical Considerations in Imaging AI
While the capabilities of Imagen are revolutionary, its development and deployment also bring forth significant challenges and ethical considerations pertinent to the broader field of imaging. One primary concern is the issue of data bias. AI models like Imagen are trained on vast datasets of existing images, and if these datasets reflect societal biases (e.g., underrepresentation of certain groups, perpetuation of stereotypes), the AI-generated images may inadvertently amplify these biases. This raises questions about fairness, representation, and the potential for these tools to perpetuate harmful visual narratives.
Another critical ethical challenge is the potential for misinformation and the creation of “deepfakes.” The ability to generate highly realistic images of people, places, or events that never occurred poses risks in terms of authenticity and trust in visual media. Differentiating between AI-generated and real imagery will become increasingly difficult, requiring robust detection methods and greater transparency from creators. Furthermore, questions surrounding copyright and ownership of AI-generated content are complex. Who owns an image generated by an AI from a text prompt? The user? The AI developer? The original artists whose works contributed to the training data? These are nascent legal and ethical territories that demand careful consideration and the development of new frameworks to ensure responsible use and intellectual property rights in the age of generative AI.

Imagen’s Place in the Future of Imaging
Imagen undeniably marks a transformative moment in the history of imaging. It represents a potent new method for image creation, operating alongside traditional photography and digital manipulation. Its future trajectory suggests deeper integration with existing creative tools, allowing seamless workflows where AI-generated elements can be combined with captured footage or human-designed graphics. The very definition of “imaging” is expanding, moving beyond solely capturing and processing light to intelligently synthesizing visual realities from human intent.
The evolution will likely see more fine-grained control for users, enabling precise adjustments to style, composition, and specific object details within generated images. Real-time generation and even animated outputs from text prompts could become commonplace, further blurring the lines between static image creation and dynamic visual media. Ultimately, Imagen and similar technologies are set to democratize high-quality visual content, making sophisticated visual expression accessible to a wider audience and empowering creators to explore previously unattainable creative visions. It’s not a replacement for the camera or the human artist, but rather a powerful, intelligent co-creator that will fundamentally reshape the landscape of how images are made, consumed, and understood in the digital age.