
Distributed tracing is a technique used to monitor and diagnose performance issues in complex, distributed systems. In essence, it allows developers and operators to follow a single request as it travels through various services and components within an application architecture. Imagine a busy airport: distributed tracing is akin to tracking a single passenger’s journey from check-in, through security, to their gate, and finally onto their flight, noting every interaction and delay along the way. This detailed, end-to-end visibility is crucial for understanding how individual pieces of a system contribute to overall performance and for pinpointing the root cause of problems.

The rise of microservices architectures, cloud-native applications, and the increasing reliance on third-party services have made traditional monitoring methods insufficient. Monolithic applications, where all functionality resides in a single unit, are easier to troubleshoot. A problem in a monolith can often be localized to a specific function or module within that single application. However, in a distributed system, a single user action might trigger requests across dozens or even hundreds of independent services. If a user experiences slow loading times or an error, identifying which of these many services is responsible can be incredibly challenging without a robust mechanism like distributed tracing.
The Core Concepts of Distributed Tracing
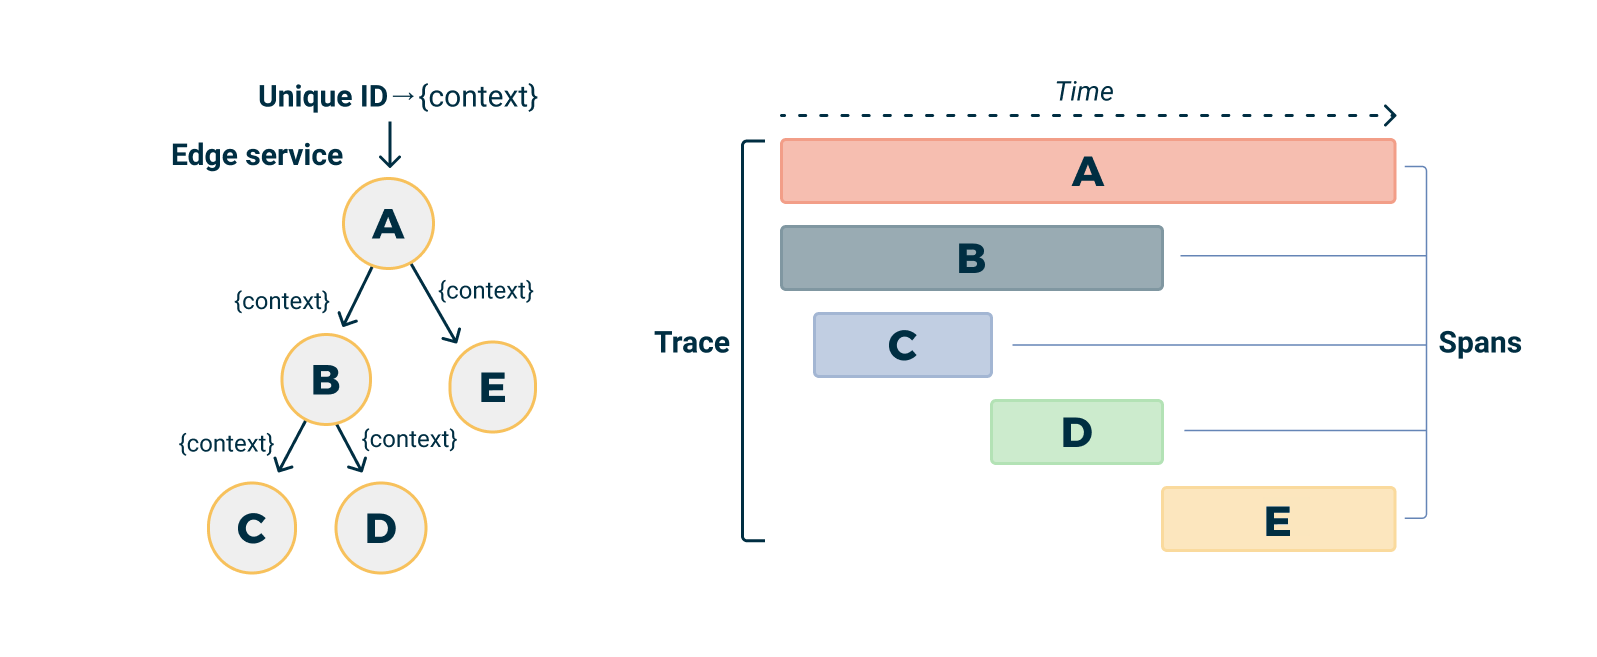
At its heart, distributed tracing involves assigning unique identifiers to requests as they enter the system and then propagating these identifiers as the request traverses different services. This allows for the reconstruction of the entire “trace” – the sequence of operations performed. Three fundamental concepts underpin this process:
Spans
A span represents a single, logical unit of work within a distributed trace. It’s a fundamental building block that captures information about a specific operation, such as an incoming HTTP request to a service, a database query, a call to another microservice, or a specific function execution. Each span has a name that describes the operation it represents, a start and end timestamp to measure its duration, and a unique identifier (Span ID). Crucially, spans are organized hierarchically. A parent span represents a larger operation, and its child spans represent the sub-operations that comprise it. This parent-child relationship is key to reconstructing the flow of a request.
Traces
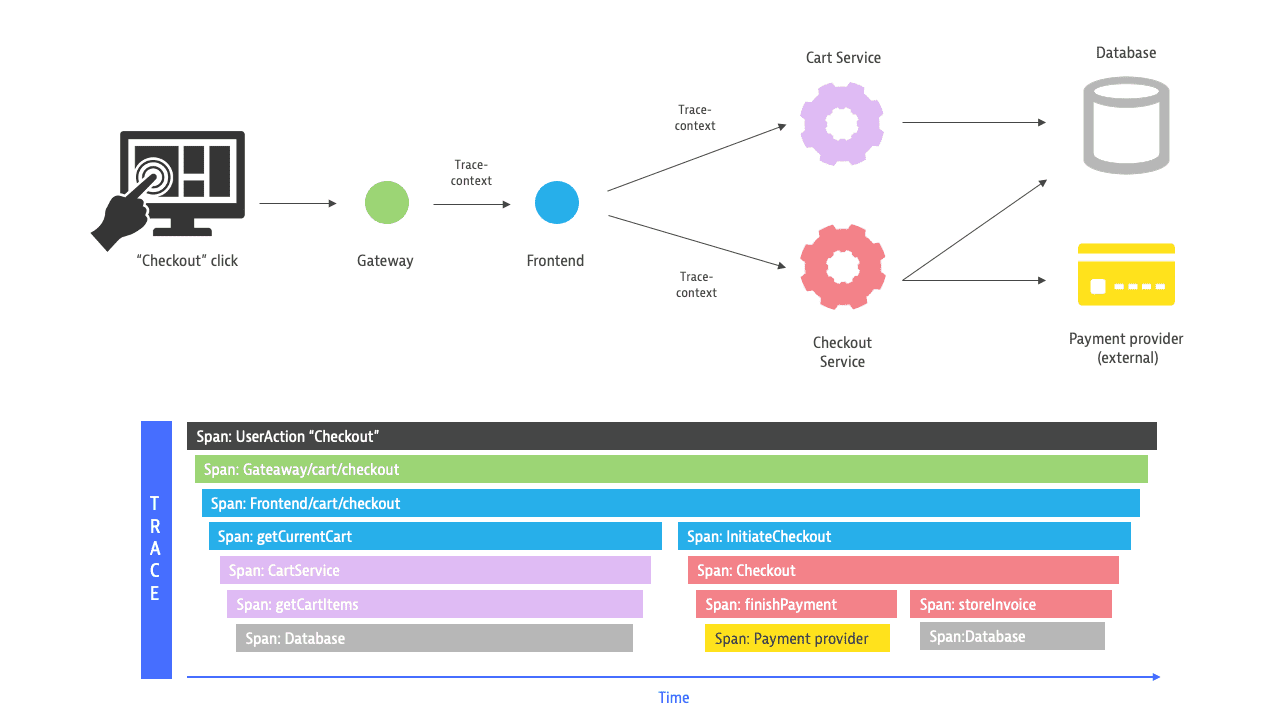
A trace is a collection of related spans that together represent the entire journey of a request through a distributed system. When a request first enters the system, a root span is created. As this request is processed by different services, new spans are generated, and these new spans become children of the previous span in the trace. All spans within a single trace share a common Trace ID, which acts as the unifying identifier. By collecting all spans with the same Trace ID, one can reconstruct the complete sequence of operations, their durations, and their interdependencies.
Context Propagation
For distributed tracing to work, context information, particularly the Trace ID and the parent Span ID, must be passed from one service to another as a request flows through the system. This is known as context propagation. This context is typically embedded in request headers (e.g., HTTP headers) or message queues. When a service receives a request, it extracts this context. If the operation within that service is significant enough, it creates a new span, setting its parent to the Span ID received in the propagated context. If no context is received, it might indicate the start of a new trace. Common standards like W3C Trace Context and B3 Propagation define how this context should be formatted and exchanged.
How Distributed Tracing Works in Practice
Implementing distributed tracing involves instrumenting the code of each service in the distributed system. This instrumentation adds the necessary logic to create spans, manage context propagation, and send span data to a tracing backend.
Instrumentation
Instrumentation is the process of modifying application code to emit tracing data. This can be done in several ways:
- Manual Instrumentation: Developers explicitly add code to create spans at the beginning and end of operations, capture relevant metadata, and propagate context. While offering fine-grained control, it can be time-consuming and error-prone, especially in large systems.
- Automatic Instrumentation: This approach uses agents or libraries that automatically detect and instrument common operations like incoming/outgoing HTTP requests, database calls, and message queue interactions without requiring explicit code changes. This is far more scalable and widely adopted for modern applications. Libraries like OpenTelemetry provide robust automatic instrumentation capabilities across many languages and frameworks.
The Tracing Backend
Once instrumentation is in place, span data needs to be collected, stored, and analyzed. This is the role of the tracing backend. When a service generates a span, it sends this data asynchronously to the tracing backend. The backend then aggregates spans based on their Trace IDs, reconstructs the complete traces, and provides tools for querying, visualizing, and analyzing this data. Popular tracing backends include Jaeger, Zipkin, and commercial solutions like Datadog, New Relic, and Honeycomb.
Visualization and Analysis
The primary benefit of distributed tracing lies in its ability to visualize and analyze the collected data. Tracing backends typically offer user interfaces that allow users to:
- View Traces: Display individual traces as a timeline, showing each span, its duration, and its relationship to other spans. This visual representation makes it easy to identify bottlenecks.
- Identify Latency: Quickly spot which services or operations are contributing most to the overall request latency. A long span in the trace immediately indicates a potential performance issue in that specific operation or service.
- Detect Errors: Correlate errors with specific spans in a trace, helping to pinpoint the service that failed and the context surrounding the failure.
- Understand Dependencies: Map out the service dependencies and how they interact during a request. This is invaluable for understanding the architecture and the impact of changes.
- Root Cause Analysis: By examining the sequence of operations and their timings, developers can efficiently diagnose and resolve performance regressions or failures.
Benefits of Distributed Tracing for Complex Systems
The adoption of distributed tracing offers profound benefits for organizations managing complex, distributed applications:
Enhanced Performance Optimization
The granular visibility provided by tracing allows for precise identification of performance bottlenecks. Developers can see exactly where time is being spent within a request lifecycle, enabling them to focus optimization efforts on the most impactful areas. This could involve optimizing database queries, improving network latency between services, or refactoring inefficient code within a specific microservice.
Accelerated Debugging and Root Cause Analysis
When a user reports an issue, tracing dramatically reduces the time it takes to diagnose the problem. Instead of sifting through logs from multiple disparate systems, developers can retrieve the trace associated with the problematic request and immediately see the sequence of events, errors, and timings. This speeds up the identification of the faulty service or component, significantly reducing Mean Time To Resolution (MTTR).
Improved System Observability
Distributed tracing is a cornerstone of observability, complementing metrics and logging. While metrics provide aggregated insights into system health (e.g., average response time), and logs offer detailed event records, tracing provides the critical link between them. It allows you to see the detailed flow of a request and then drill down into the logs or metrics for specific spans that exhibit unusual behavior. This holistic view enables a deeper understanding of system dynamics.
Understanding Service Dependencies and Interactions
In a microservices environment, understanding how services interact is paramount. Tracing naturally reveals these dependencies. By visualizing traces, teams can map out the communication patterns between services, identify unexpected call chains, and understand the impact of one service’s performance on others. This is crucial for architectural planning, impact assessment of changes, and capacity planning.
Faster Incident Response
During an incident, the ability to quickly understand what is happening is critical. Distributed tracing provides an immediate, high-level view of the affected requests and the services involved. This allows operations teams to triage issues more effectively, communicate accurately about the problem, and deploy fixes faster.
Challenges and Considerations
While the benefits are substantial, implementing and managing distributed tracing also presents challenges:
Instrumentation Overhead
While modern tracing tools strive to minimize overhead, the act of generating, propagating, and sending span data can consume CPU, memory, and network resources. Careful instrumentation strategies and sampling techniques are necessary to balance visibility with performance impact.
Data Volume and Storage
High-traffic applications can generate an enormous volume of tracing data. Storing and querying this data efficiently requires robust backend infrastructure and thoughtful data retention policies. Sampling, where only a subset of traces is recorded, is a common strategy to manage data volume.
Standard Adoption
While OpenTelemetry is emerging as a de facto standard, different vendors and older systems might use proprietary tracing formats. Ensuring interoperability and consistency across diverse technology stacks can be challenging.
Culture and Team Adoption
Successfully leveraging distributed tracing requires a shift in how development and operations teams approach problem-solving. It necessitates a culture of collaboration, shared understanding of the system, and a willingness to adopt new tools and practices. Training and clear guidelines are essential for widespread adoption.
The Future of Distributed Tracing
The field of distributed tracing continues to evolve. Key trends include:
- Convergence with Observability Platforms: Tracing is increasingly integrated into broader observability platforms that combine metrics, logs, and traces into a unified view.
- AI and Machine Learning: AI is being used to analyze trace data to automatically detect anomalies, predict failures, and provide more intelligent insights.
- Broader Adoption of Standards: The widespread adoption of OpenTelemetry is simplifying instrumentation and improving interoperability across different tools and vendors.
- Edge and IoT Tracing: As more devices become connected and distributed, the need for tracing extends to the edge, posing new challenges for data collection and analysis.
In conclusion, distributed tracing is an indispensable tool for understanding, debugging, and optimizing modern distributed systems. By providing end-to-end visibility into request flows, it empowers teams to build more resilient, performant, and observable applications in an increasingly complex technological landscape.