
The contemporary world is characterized by an unprecedented deluge of information, where every interaction, observation, and operation generates a unique footprint. Within this intricate digital landscape, data and statistics emerge as the fundamental pillars supporting virtually all technological advancement and innovation. Far from being mere academic concepts, they are the very language through which machines learn, systems optimize, and complex problems are solved across diverse fields, from autonomous systems to sophisticated remote sensing applications. Understanding what data is, how it’s collected, and how statistics transform raw information into actionable insights is crucial for anyone navigating or contributing to the tech frontier.

The Foundational Role of Data in Technological Advancement
At its core, data refers to raw facts, figures, and symbols that, when processed, can convey meaning. It is the uninterpreted building block of information, captured through various means and stored in myriad formats. In the realm of technological innovation, data acts as the indispensable fuel that powers discovery, development, and refinement. Without a continuous stream of relevant data, intelligent systems cannot learn, algorithms cannot be validated, and new technologies cannot achieve their full potential.
Raw Information as the Fuel for Innovation
Every sensor reading, every pixel in an image, every log entry from an operational system, and every input from a user contributes to the vast pool of data that drives modern technology. In advanced technological domains like robotics, AI, and autonomous vehicles, the sheer volume and velocity of data generated are staggering. For instance, a single autonomous drone undertaking a mapping mission might collect terabytes of lidar data, hyperspectral imagery, and telemetry within hours. This raw information, devoid of immediate interpretation, forms the empirical basis upon which models are built, hypotheses are tested, and innovations are forged. The quality, relevance, and accessibility of this data directly correlate with the efficacy and intelligence of the resulting technological solutions. It enables engineers to identify patterns, detect anomalies, and understand system behaviors that would be imperceptible through human observation alone.
Data Types in Tech: From Telemetry to Imagery
The nature of data varies significantly depending on the application. In technology and innovation, common data types include:
- Numerical Data: Quantitative measurements such as sensor readings (temperature, pressure, altitude, speed), financial figures, or performance metrics. This type is fundamental for control systems, performance monitoring, and scientific analysis.
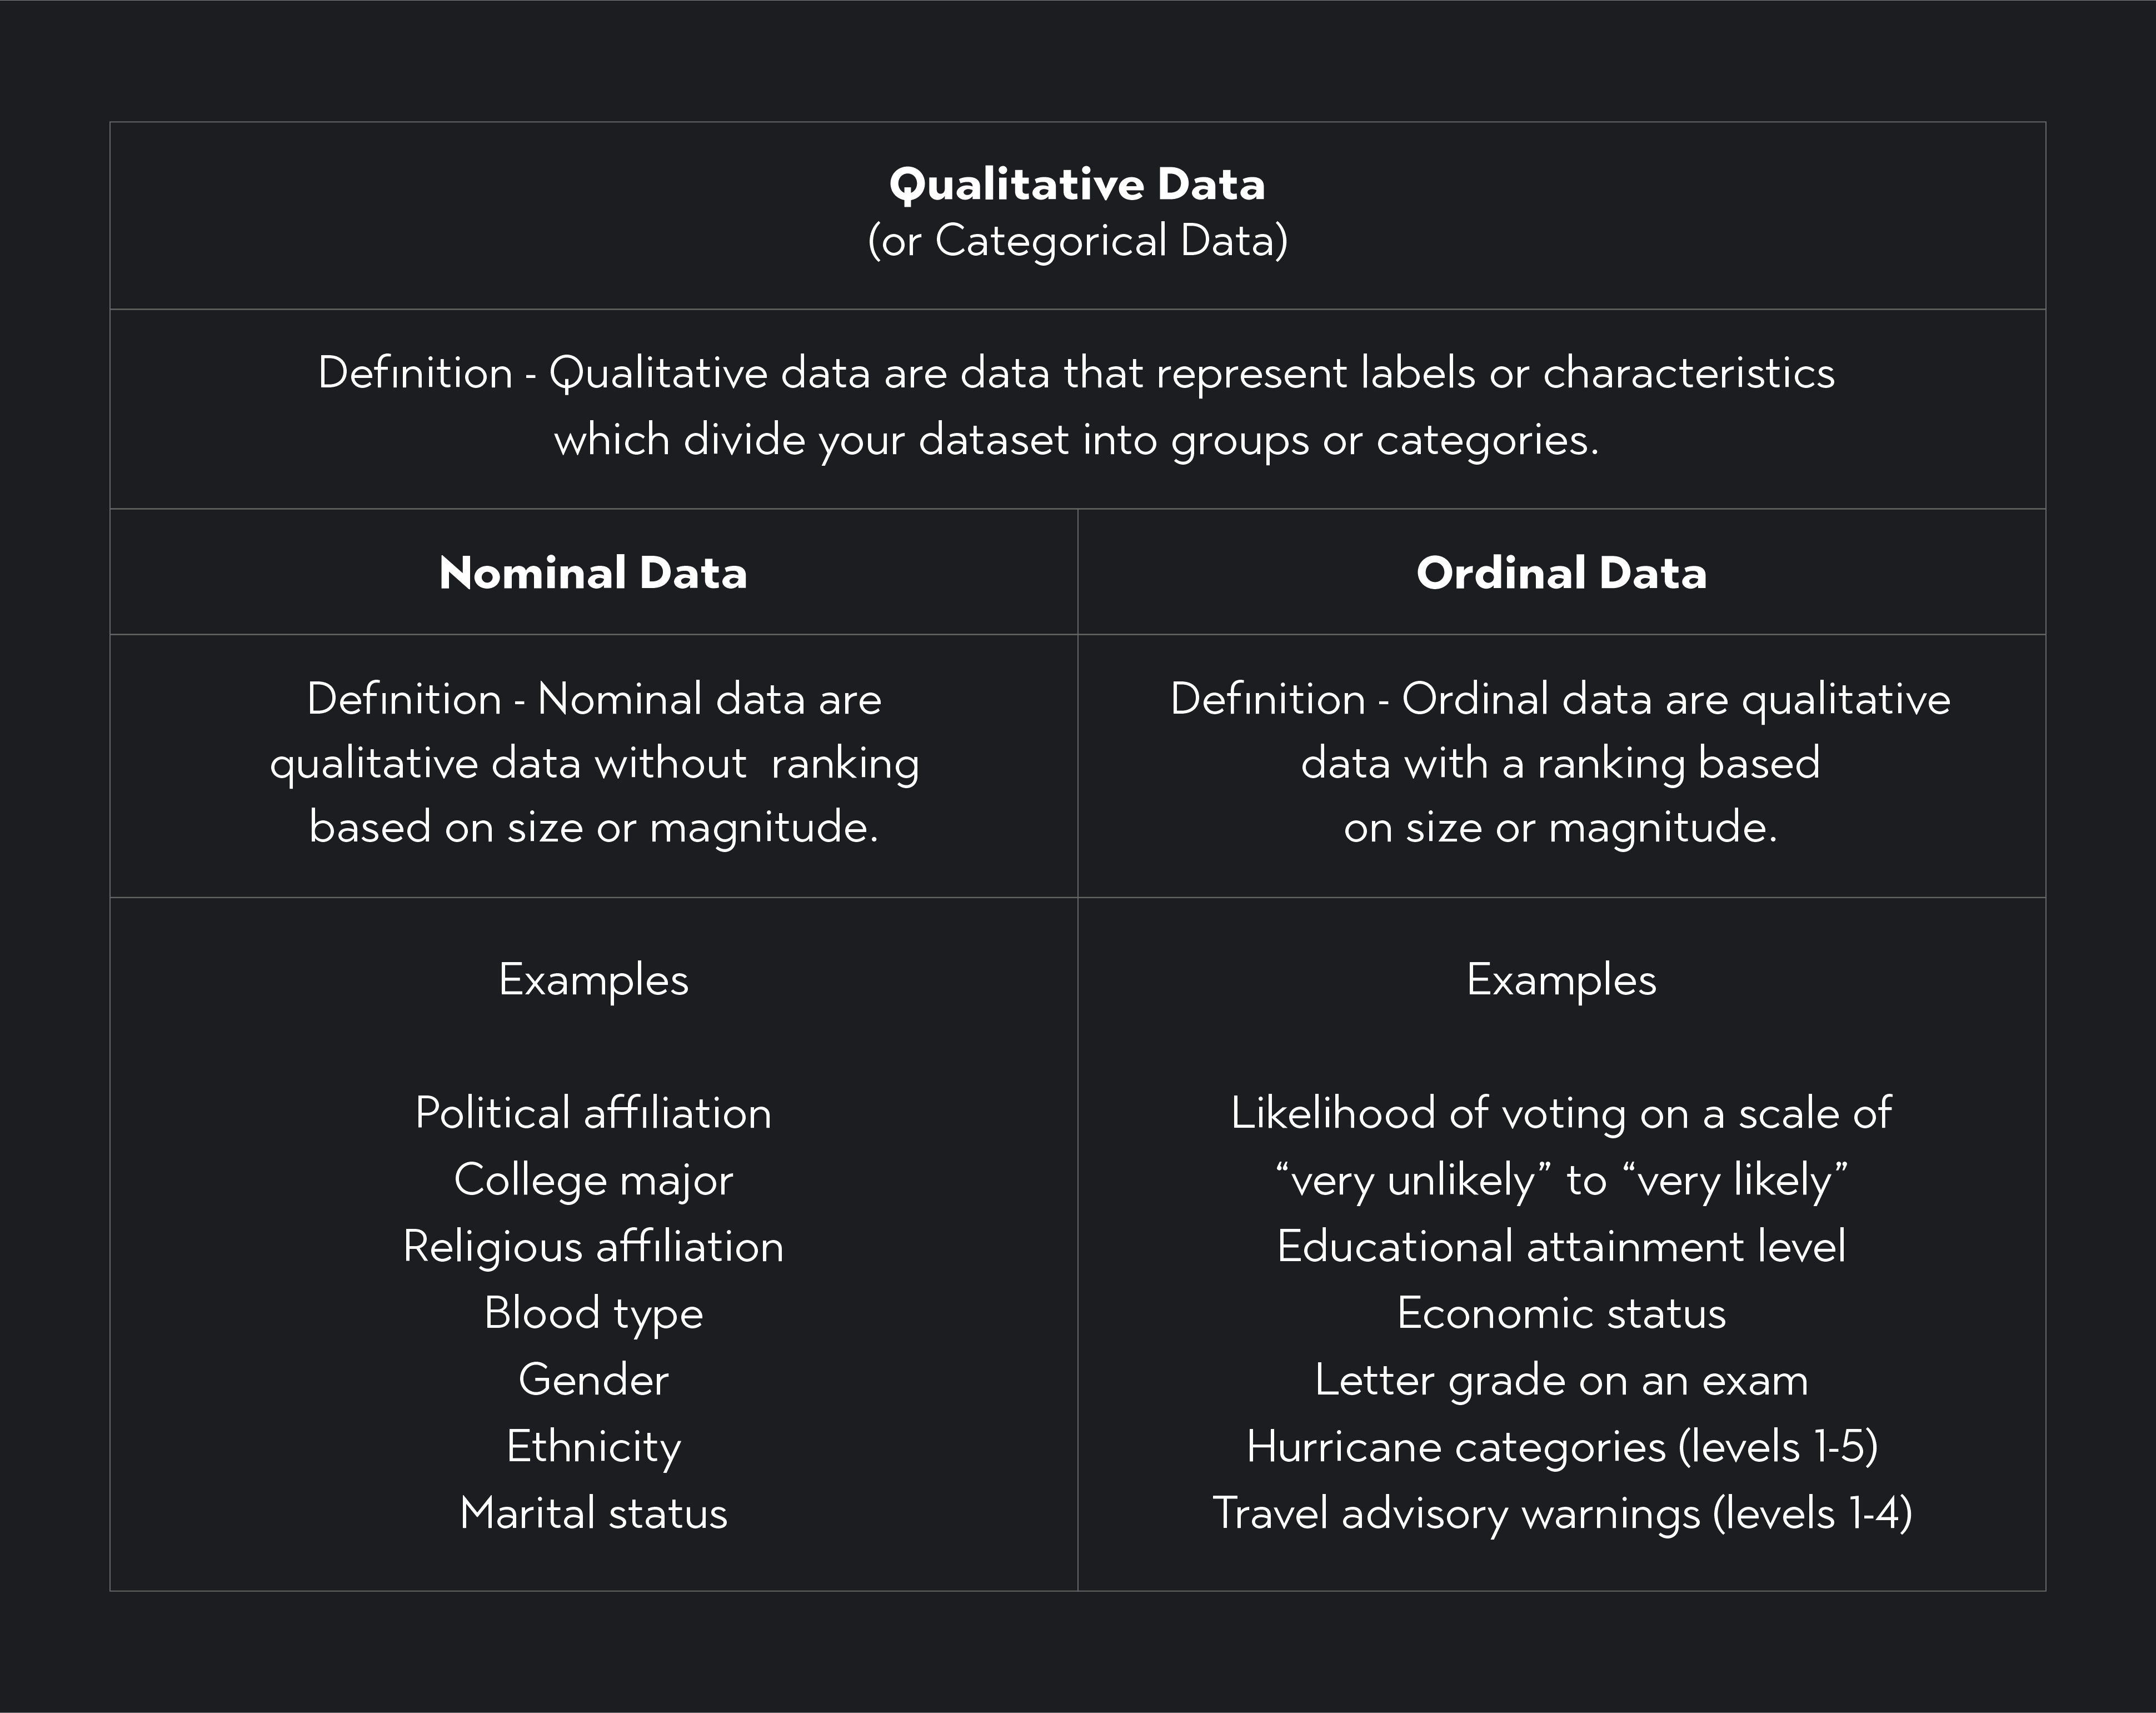
- Categorical Data: Qualitative data representing groups or labels, like types of objects detected, operational states (e.g., ‘charging’, ‘flying’, ‘idle’), or classification results.
- Time-Series Data: Sequences of data points indexed in time order, crucial for understanding trends, predicting future states, and analyzing dynamic systems. Telemetry data from drones (position, velocity, attitude over time) is a prime example.
- Spatial Data: Information that has a geographical or spatial reference, such as GPS coordinates, LiDAR point clouds, or geographical information system (GIS) layers. Essential for mapping, navigation, and environmental monitoring.
- Image and Video Data: Pixels representing visual information, ranging from high-resolution RGB photographs to multispectral and thermal imagery. This is critical for computer vision, object recognition, visual inspection, and aerial survey.
- Text Data: Unstructured data from reports, logs, documentation, or human-computer interactions, often processed using natural language processing (NLP) for insights.
The ability to collect, store, and process these diverse data types efficiently is a cornerstone of modern technological progress, enabling systems to perceive, interpret, and interact with the physical and digital worlds in increasingly sophisticated ways.
Data Collection Methods in Modern Systems
Advanced technological systems employ a myriad of sophisticated methods to collect data, often in real-time and at scale. Internet of Things (IoT) devices, for example, embed sensors into physical objects, creating vast networks that constantly monitor environmental conditions, operational parameters, and user interactions. In the context of autonomous aerial vehicles (UAVs), data collection is highly integrated:
- Onboard Sensors: Drones are equipped with GPS/GNSS modules for precise positioning, IMUs (Inertial Measurement Units) for attitude and velocity, altimeters, magnetometers, and vision cameras for navigation and obstacle avoidance.
- Payload Sensors: Specialized payloads carry high-resolution RGB cameras, thermal cameras, LiDAR scanners, multispectral or hyperspectral imagers to collect specific data for mapping, inspection, agriculture, and surveillance.
- Telemetry Systems: Continuous streaming of operational data (battery status, motor RPM, flight path, system health) to ground control stations, enabling real-time monitoring and diagnostics.
- Edge Computing: Processing data directly on the device (e.g., a drone performing real-time object detection) before transmitting aggregated or critical information, reducing latency and bandwidth requirements.
These methods collectively ensure that the intricate ecosystems of modern technology are constantly fed with the raw materials needed for intelligent operation and continuous improvement.
Statistics: Unlocking Insights from Data
While data provides the raw ingredients, statistics provides the tools and methodologies to transform this raw material into meaningful insights, knowledge, and actionable intelligence. Statistics is the science of collecting, analyzing, interpreting, presenting, and organizing data. It helps us make sense of uncertainty, identify patterns in complex datasets, and draw reliable conclusions that inform decision-making and drive technological innovation. Without statistical analysis, vast oceans of data would remain opaque and unintelligible.
Descriptive Statistics: Summarizing Complex Datasets
Descriptive statistics are the first step in understanding any dataset. They involve methods for organizing, summarizing, and presenting data in a meaningful way, allowing researchers and engineers to grasp the essential features of a phenomenon without having to examine every single data point. Key descriptive statistics include:
- Measures of Central Tendency: These describe the center of a data set, such as the mean (average), median (middle value), and mode (most frequent value). For instance, the mean flight time of a drone battery or the median altitude achieved during a mission.
- Measures of Dispersion (or Variability): These quantify the spread or variability of data points, including the range, variance, and standard deviation. A low standard deviation in sensor readings might indicate high precision, while a high standard deviation could signal instability or noise.
- Frequency Distributions: Tables or graphs (like histograms) that show how often each value or range of values occurs within a dataset, crucial for identifying common occurrences or rare events in system behavior.
By applying descriptive statistics, engineers can quickly assess the typical performance of a new component, identify common failure modes, or characterize the distribution of environmental conditions encountered by autonomous systems.
Inferential Statistics: Predicting and Generalizing
Beyond summarizing observed data, inferential statistics allows us to draw conclusions, make predictions, and generalize findings from a sample of data to a larger population. This is particularly vital in technological innovation where it’s often impractical or impossible to test every scenario or examine every instance. Inferential statistics provides the probabilistic framework for:
- Hypothesis Testing: Determining whether observed differences or relationships in data are statistically significant or likely due to random chance. For example, testing if a new navigation algorithm significantly reduces position error compared to an old one.
- Estimation: Using sample data to estimate population parameters. This could involve estimating the mean time between failures for a new drone motor based on a test batch, or predicting the expected battery degradation rate over a fleet.
- Regression Analysis: Modeling relationships between variables to predict outcomes. For example, predicting an autonomous system’s energy consumption based on flight speed, payload weight, and environmental factors.
- Classification: Building models to categorize new observations into predefined classes, a cornerstone of machine learning in tasks like object detection (e.g., identifying different types of crops from aerial imagery) or anomaly detection in sensor data.
Inferential statistics empowers innovators to make informed decisions under uncertainty, validate the effectiveness of new technologies, and generalize experimental results to real-world operational environments.
Statistical Modeling for Autonomous Systems
Statistical modeling is at the heart of designing and optimizing autonomous systems. These models use statistical relationships between variables to predict system behavior, make decisions, and adapt to changing conditions. In autonomous navigation, for instance, Kalman filters and particle filters are statistical models that estimate the current state (position, velocity, attitude) of a vehicle by combining noisy sensor measurements with a prediction model of its motion. This allows drones to navigate accurately even in environments where GPS signals are weak or unavailable.
Furthermore, statistical learning algorithms, a subset of machine learning, are extensively used for:
- Path Planning and Optimization: Statistical models can analyze environmental data (terrain, obstacles, wind patterns) and historical flight data to generate optimal flight paths that minimize energy consumption, avoid hazards, or maximize coverage.
- Object Recognition and Tracking: Algorithms like Support Vector Machines (SVMs) or neural networks (which are statistically grounded) are trained on vast datasets of imagery to identify and track objects of interest in real-time, crucial for surveillance, inspection, and delivery drones.
- Decision Making under Uncertainty: Probabilistic graphical models help autonomous systems evaluate various possible outcomes and their likelihoods, enabling them to make robust decisions in complex, dynamic environments. For example, deciding whether to land, hover, or reroute based on weather changes and remaining battery life.
These sophisticated statistical applications allow autonomous systems to move beyond programmed responses, enabling them to learn, adapt, and operate intelligently in unpredictable real-world scenarios.
Data-Driven Innovation in Specific Tech Domains
The interplay of data and statistics isn’t just a theoretical construct; it forms the backbone of tangible innovation across numerous technological domains, particularly those related to intelligent and autonomous systems.
AI and Machine Learning: Learning from Data
Artificial Intelligence (AI) and Machine Learning (ML) represent perhaps the most prominent consumers and producers of data and statistical insights. ML algorithms, at their core, are statistical models designed to learn patterns and make predictions from data without being explicitly programmed for every scenario.
- Training Data: Vast datasets are used to train neural networks and other ML models, allowing them to identify objects in images, understand human speech, or predict system failures. The quality and representativeness of this data directly impact the model’s performance.
- Statistical Validation: Statistical methods are indispensable for evaluating the performance of AI models, measuring accuracy, precision, recall, and F1-scores, and ensuring generalization to unseen data.
- Reinforcement Learning: Agents learn optimal behaviors through trial and error, collecting data on rewards and penalties in various states, and using statistical methods to update their policy. This is critical for developing autonomous agents that can learn complex control strategies in dynamic environments.
For instance, an AI-powered drone performing automated inspection uses ML models trained on millions of images of defects to identify anomalies on infrastructure with high accuracy. This learning process is entirely data-driven and statistically validated.
Remote Sensing and Mapping: Quantifying the Environment
Remote sensing, often performed using UAVs, is fundamentally a data collection and statistical analysis discipline. Drones equipped with specialized sensors (LiDAR, multispectral, thermal) gather vast amounts of data about the Earth’s surface and atmosphere without direct contact.
- Data Acquisition: High-resolution imagery and point clouds are collected, providing detailed information about terrain, vegetation health, building structures, and even underground features.
- Statistical Analysis of Spatial Data: Geographic Information Systems (GIS) and advanced statistical software are used to process this data. Techniques like spatial autocorrelation identify patterns and clusters (e.g., disease outbreaks in crops), while regression models can estimate biomass or water content from spectral data.
- Change Detection: Statistical comparisons of imagery taken at different times allow for the detection and quantification of environmental changes, such as deforestation, urban expansion, or glacier melt.
This data-driven approach transforms raw sensor readings into quantifiable insights, enabling precision agriculture, urban planning, disaster response, and environmental monitoring with unprecedented detail and efficiency.
Predictive Maintenance and System Optimization
Data and statistics are revolutionizing maintenance strategies from reactive to proactive and predictive. By continuously monitoring the operational data of technological systems (e.g., flight hours, motor temperatures, vibration levels, battery cycles of a drone fleet), statistical models can predict when a component is likely to fail.
- Anomaly Detection: Statistical methods identify deviations from normal operating parameters that could indicate an impending failure.
- Survival Analysis: Statistical models estimate the remaining useful life of components, allowing for timely maintenance scheduling, reducing downtime, and extending asset lifespan.
- Optimization: Analyzing performance data allows engineers to statistically identify bottlenecks, inefficient processes, or suboptimal configurations, leading to improvements in system design, operational procedures, and resource allocation.
This shift from calendar-based maintenance to condition-based and predictive maintenance, driven by data and statistics, significantly enhances the reliability, safety, and cost-efficiency of complex technological systems.
Enhancing Autonomous Flight and Navigation through Statistical Analysis
Autonomous flight relies heavily on the continuous collection and statistical interpretation of sensor data to ensure safe and efficient operation.
- Sensor Fusion: Algorithms like the Kalman filter statistically merge data from multiple noisy sensors (GPS, IMU, altimeter, vision sensors) to produce a more accurate and reliable estimate of the drone’s position, velocity, and orientation than any single sensor could provide.
- Obstacle Avoidance: Statistical models analyze real-time sensor data (e.g., from ultrasonic sensors, LiDAR, or stereo cameras) to detect obstacles and predict their trajectories, allowing the autonomous system to calculate collision-free paths.
- Flight Performance Tuning: Through statistical analysis of flight logs, engineers can identify optimal control parameters, refine aerodynamic models, and improve the drone’s stability and responsiveness under various environmental conditions.
These statistical underpinnings are critical for the reliability and safety of autonomous aerial vehicles, enabling them to perform complex missions with minimal human intervention.
Challenges and Ethical Considerations in Data & Statistics for Tech
While the benefits of data and statistics in tech are immense, their effective and ethical application comes with significant challenges. Addressing these issues is paramount for fostering trust and ensuring responsible innovation.
Data Quality and Integrity
The adage “garbage in, garbage out” perfectly encapsulates the importance of data quality. Poor quality data—incomplete, inaccurate, inconsistent, or biased—can lead to flawed statistical analyses and unreliable technological solutions. For autonomous systems, erroneous sensor data or unrepresentative training datasets can result in critical operational failures or biased decision-making. Ensuring data integrity through rigorous collection protocols, validation checks, and data cleaning processes is a constant challenge for tech innovators.
Privacy and Security Concerns
The collection of vast quantities of data, particularly personal or sensitive operational data, raises significant privacy and security concerns. In fields like surveillance or critical infrastructure monitoring using drones, the misuse or unauthorized access to data can have serious consequences. Robust data anonymization techniques, stringent access controls, and compliance with data protection regulations (like GDPR) are crucial for mitigating these risks and maintaining public trust.
Bias in Data and Algorithmic Fairness
One of the most profound challenges is the potential for bias embedded within data to be amplified by statistical models and AI algorithms. If training data reflects historical biases or underrepresents certain groups or conditions, the resulting algorithms can perpetuate and even exacerbate discrimination or lead to unfair outcomes. For example, an autonomous detection system trained predominantly on data from one geographic region might perform poorly or be biased when deployed in another. Addressing algorithmic fairness requires careful statistical analysis of datasets for existing biases, developing methods to mitigate these biases during model training, and ensuring transparent and accountable decision-making processes in AI. This ethical imperative calls for a multidisciplinary approach, combining statistical rigor with social and ethical considerations, to ensure that technological innovation serves all segments of society equitably.