
In the rapidly evolving landscape of Tech & Innovation, data is the new frontier. Its sheer volume, velocity, and variety present both immense opportunities and significant challenges. To harness this torrent of information and transform it into actionable insights, robust data management strategies are essential. At the heart of many such strategies lies the ETL pipeline – a fundamental concept that orchestrates the flow of data from disparate sources into a consolidated, usable format. ETL, an acronym for Extract, Transform, Load, describes a three-stage process critical for data warehousing, analytics, machine learning, and nearly every data-driven application that defines modern innovation.

An ETL pipeline is a set of processes designed to move data from one or more source systems into a target system, typically a data warehouse or data lake. Its primary purpose is to clean, standardize, and consolidate data, making it readily available for analysis, reporting, and strategic decision-making. Without a well-designed ETL process, organizations would drown in raw, unstructured data, unable to leverage its potential for competitive advantage or groundbreaking discovery. This foundational technology is the silent workhorse behind the AI models that learn, the mapping applications that guide, and the remote sensing initiatives that monitor our planet.
Understanding the Core Concept: Extract, Transform, Load
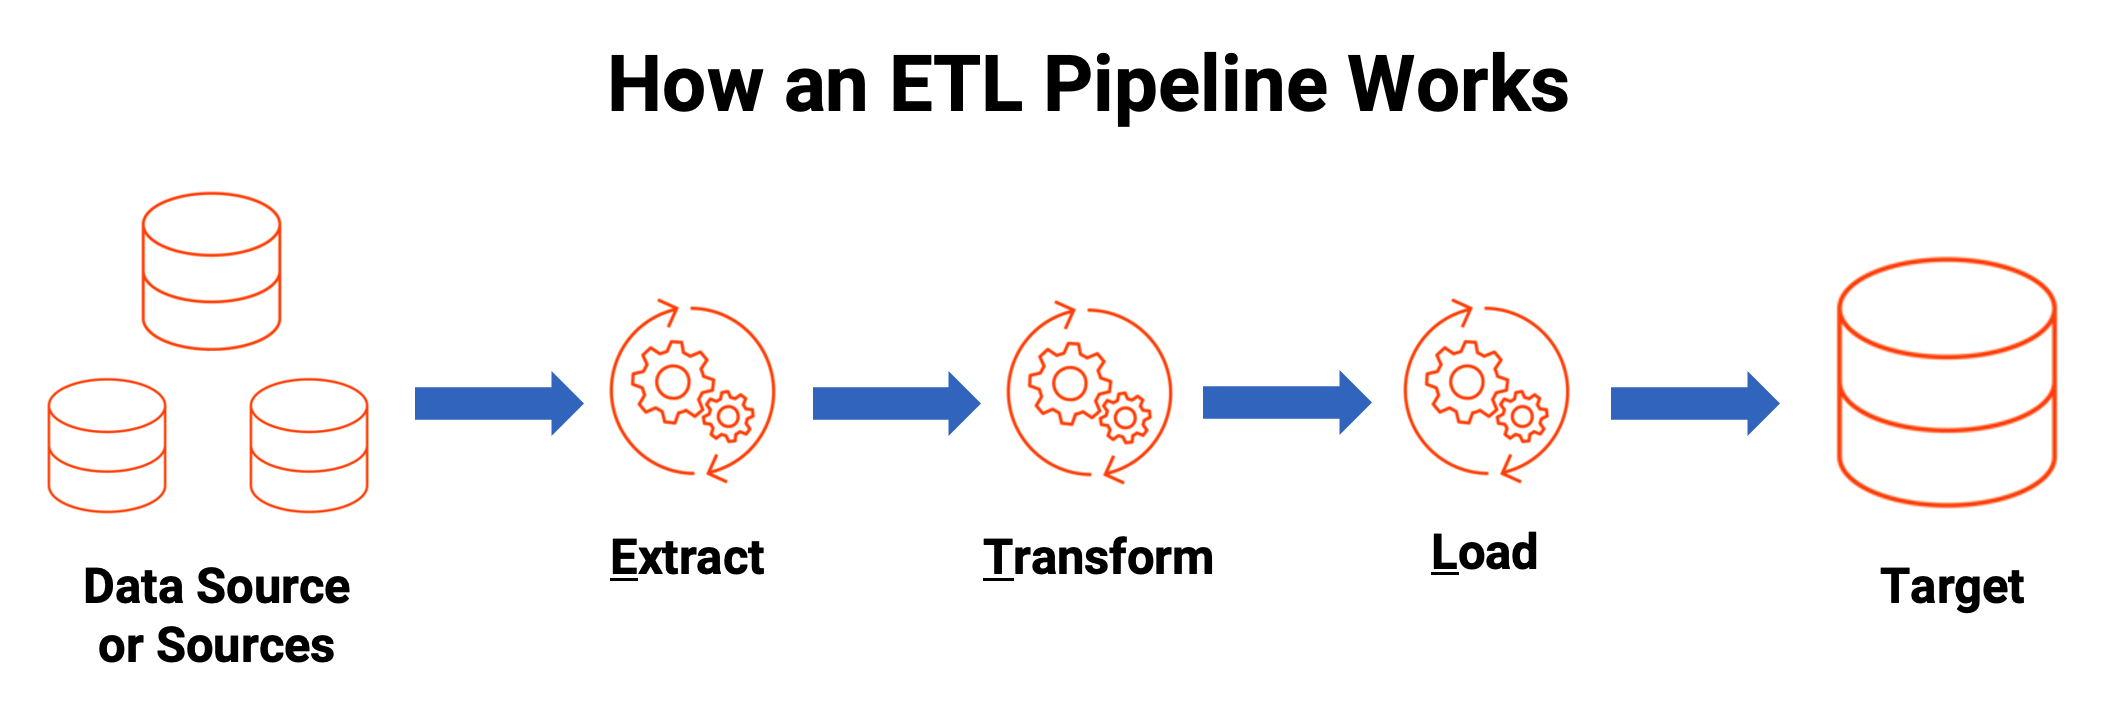
The three stages of an ETL pipeline are sequential and interdependent, each playing a vital role in preparing data for its ultimate destination and purpose. Understanding these individual components is key to appreciating the power and complexity of an ETL system within the broader tech ecosystem.
The ‘Extract’ Stage: Sourcing Diverse Data
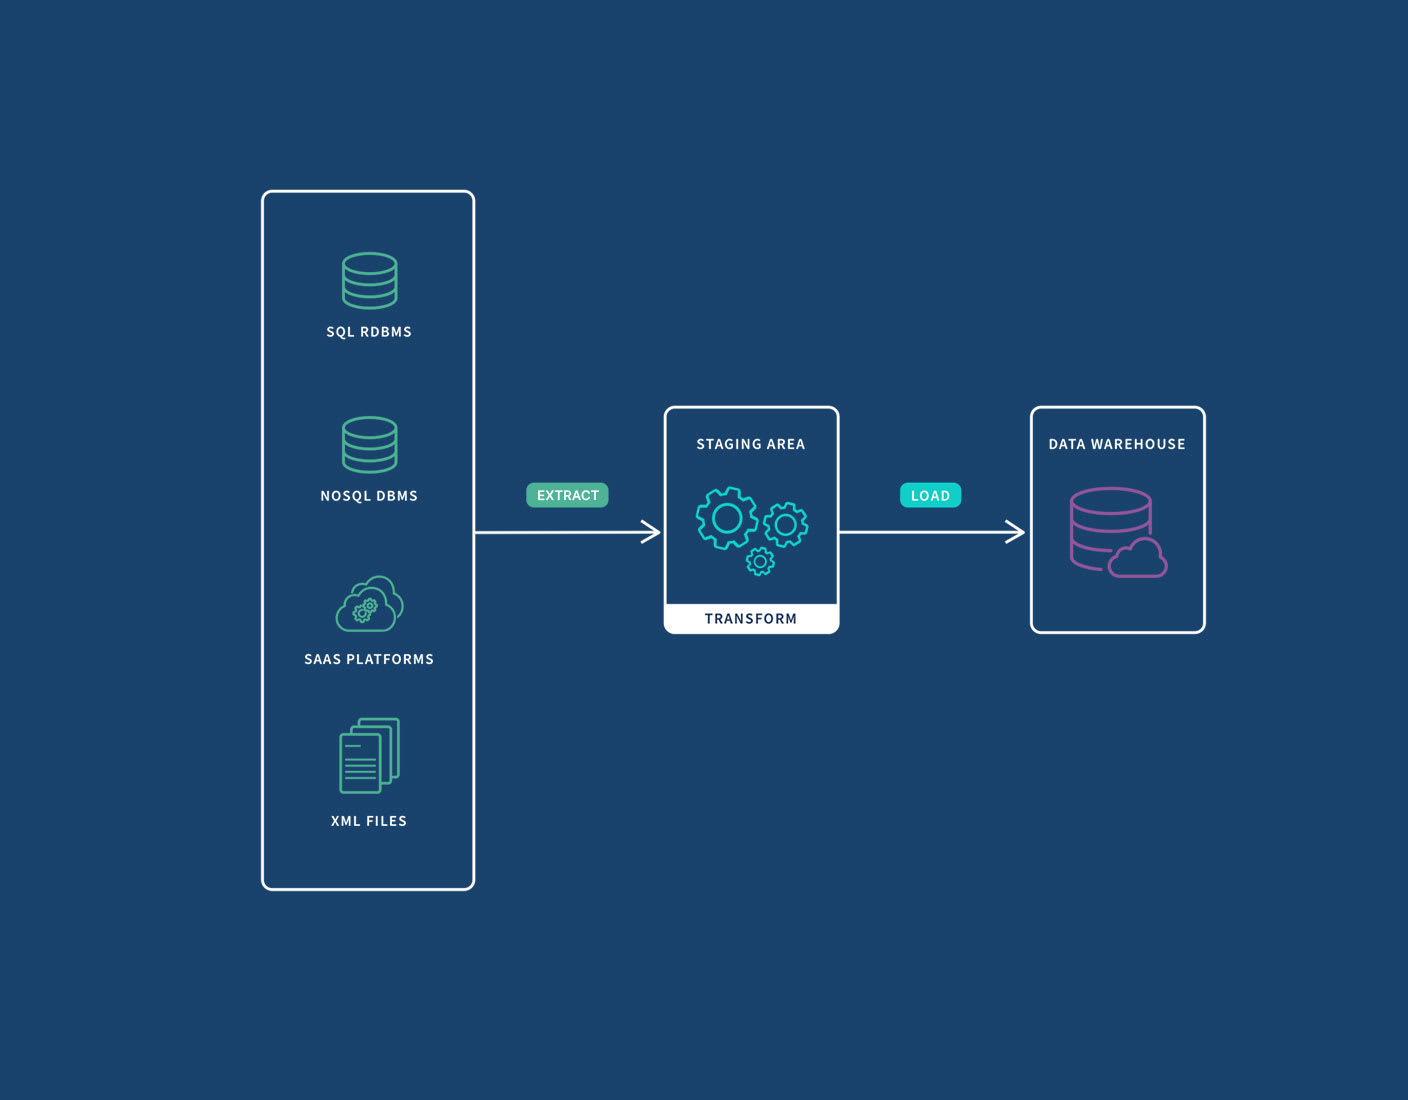
The initial phase of an ETL pipeline is extraction. This involves retrieving data from various source systems, which can be incredibly diverse in their nature and format. These sources might include relational databases (like SQL Server, Oracle, PostgreSQL), non-relational databases (NoSQL, MongoDB), flat files (CSV, XML, JSON), cloud applications (CRM, ERP systems), APIs from third-party services, streaming data platforms (Kafka), or even legacy systems. The challenge in this stage often lies in connecting to these disparate sources and handling their unique data structures, schema, and access protocols.
During extraction, the goal is to collect all relevant data, often without applying any significant changes, ensuring that the raw information is captured completely and accurately. This raw data is then staged, typically in a temporary area, before moving to the next phase. The efficiency and reliability of the extraction process are paramount, as any errors or omissions here will propagate through the entire pipeline, compromising the integrity of the final dataset.
The ‘Transform’ Stage: Shaping Data for Insights
Once extracted, the raw data is rarely in a format immediately suitable for analysis or storage in a target system like a data warehouse. This is where the ‘Transform’ stage comes into play – arguably the most complex and critical phase of an ETL process. Transformation involves applying a series of rules and functions to the extracted data to clean, refine, and restructure it according to the requirements of the target system and the analytical needs of the business.
Common transformation operations include:
- Cleaning: Handling missing values (e.g., imputation or removal), correcting inconsistencies, and removing duplicates.
- Standardization: Ensuring data conforms to a unified format (e.g., date formats, unit conversions, consistent naming conventions).
- Deduplication: Identifying and removing redundant records.
- Validation: Checking data against predefined rules to ensure accuracy and integrity.
- Enrichment: Adding new data points from other sources or generating derived attributes (e.g., calculating age from birthdate).
- Aggregation: Summarizing data (e.g., total sales per region).
- Filtering: Selecting specific rows or columns relevant to the analysis.
- Joining: Combining data from multiple sources based on common keys.
- Normalization/Denormalization: Structuring data to optimize for storage efficiency or query performance.
The transformational rules are defined by business logic and data governance policies. This stage not only ensures data quality but also prepares data for optimal performance in reporting and analytical tools, making it genuinely valuable for innovative applications.
The ‘Load’ Stage: Readying Data for Consumption
The final stage of an ETL pipeline is loading the transformed data into the target destination. This destination is typically a data warehouse, a data mart, or a data lake, where the data is stored in a structured or semi-structured format, optimized for querying and analysis.
Loading can occur in different ways:
- Full Load: All existing data is removed from the target, and the new, transformed dataset is loaded in its entirety. This is common for smaller datasets or when complete historical refreshing is needed.
- Incremental Load: Only the new or changed data from the source systems since the last load is identified and added to the target system. This is far more efficient for large, continuously updated datasets, minimizing downtime and resource consumption.
The load process must be efficient and robust, especially for large volumes of data. It often involves considerations for error handling, recovery mechanisms, and performance optimization to ensure that data is available to end-users and applications in a timely manner. The ultimate goal of loading is to provide a reliable, consistent, and high-performance foundation for advanced analytics, machine learning, and real-time decision support systems that drive modern technological advancements.
Why ETL is Indispensable in Modern Tech & Innovation
In the era of big data and pervasive connectivity, virtually every significant technological advancement relies on the ability to process, analyze, and act upon vast quantities of information. ETL pipelines are the unsung heroes that make this possible, serving as the backbone for various innovative applications.
Powering Data Analytics and Business Intelligence
At its core, ETL is about making data usable. For organizations to derive insights, understand trends, and monitor performance, data must be clean, integrated, and structured. ETL pipelines consolidate data from CRM, ERP, web analytics, social media, and operational systems into a unified view within a data warehouse. This consolidated and processed data then feeds business intelligence (BI) dashboards, reporting tools, and analytical platforms. Without robust ETL, analysts would spend an inordinate amount of time cleaning and integrating data manually, significantly hindering their ability to generate timely and accurate insights. This directly impacts an organization’s agility and capacity for data-driven innovation.
Enabling AI and Machine Learning Models
Artificial Intelligence and Machine Learning models thrive on high-quality, well-prepared data. The performance of these models – whether for predictive analytics, natural language processing, or image recognition – is directly proportional to the quality and consistency of their training data. ETL pipelines play a crucial role here by:
- Feature Engineering: Transforming raw data into features that are more suitable for ML algorithms (e.g., creating aggregated metrics, one-hot encoding categorical variables).
- Data Cleaning: Removing noise, outliers, and inconsistencies that could bias model training or lead to inaccurate predictions.
- Data Integration: Combining datasets from various sources to provide a richer context for model training.
- Data Validation: Ensuring that input data conforms to the expected schema and value ranges, crucial for model stability in production.
From autonomous vehicles learning to navigate, to remote sensing platforms identifying agricultural patterns, the underlying data preparation relies heavily on sophisticated ETL processes. The transformation stage, in particular, becomes a vital component for feature engineering, directly impacting the efficacy and accuracy of AI innovations.
Ensuring Data Quality and Consistency
Data quality is not merely a technical concern; it’s a strategic asset. Inaccurate, incomplete, or inconsistent data can lead to flawed analyses, poor decision-making, and significant financial losses. ETL pipelines are explicitly designed to address these issues. Through rigorous data cleaning, validation, and standardization performed during the transformation stage, ETL processes ensure that data entering the target system is accurate, consistent, and reliable. This consistency is vital for maintaining trust in data assets and supporting regulatory compliance requirements, especially in sensitive domains like finance or healthcare. For any tech enterprise relying on data for critical operations, maintaining high data quality through ETL is non-negotiable.
Architectural Patterns and Evolution of ETL
The concept of ETL has been around for decades, but its implementation and architectural patterns have evolved significantly with advancements in data storage, processing power, and cloud computing. The distinction between traditional batch processing and modern real-time streaming, and the rise of ELT, highlight this evolution.
Traditional ETL vs. Modern ELT Approaches
Historically, ETL meant extracting data, transforming it on a dedicated staging server, and then loading the cleaned data into a data warehouse. This made sense when computing resources were expensive and data warehouses were less powerful. However, with the advent of powerful, scalable cloud-based data warehouses and data lakes (like Snowflake, Google BigQuery, Amazon Redshift), a new paradigm has emerged: ELT (Extract, Load, Transform).
In an ELT approach, data is first extracted from sources and immediately loaded into the target data lake or data warehouse in its raw form. The transformation then occurs within the target system using its native processing power. This approach offers several advantages:
- Flexibility: Raw data is always available for different types of transformations or new analytical use cases without needing to re-extract.
- Scalability: Leverages the immense scalability of cloud data warehouses for transformation, making it faster for large datasets.
- Agility: Analysts and data scientists can perform transformations directly on the loaded raw data, reducing dependencies on data engineering teams.
While ETL remains relevant for specific use cases, especially where data privacy or complex cleansing is required before loading, ELT is gaining prominence in cloud-native environments, aligning with agile development and big data strategies within Tech & Innovation.
Batch Processing vs. Real-time Streaming ETL
The initial ETL pipelines were predominantly batch-oriented, processing large volumes of data at scheduled intervals (e.g., daily, weekly). This approach is well-suited for reporting and analysis that do not require immediate updates. However, many modern applications demand real-time insights. For instance, fraud detection, personalized recommendations, IoT sensor data processing, or dynamic mapping services require data to be processed and analyzed as soon as it arrives.
This demand has led to the development of real-time streaming ETL. Technologies like Apache Kafka, Apache Flink, and Spark Streaming enable continuous data ingestion and transformation, allowing data to be processed “in-flight” before being loaded into a real-time analytics database or a streaming data lake. Real-time ETL is crucial for applications where latency is a critical factor, powering instantaneous decisions and dynamic system responses, which are hallmarks of cutting-edge technology.
Cloud-Native ETL and Data Lake Integration
Cloud computing has revolutionized ETL. Cloud-native ETL solutions offer unparalleled scalability, flexibility, and cost-effectiveness. Services from AWS (Glue, Data Pipeline), Google Cloud (Dataflow, Dataproc), and Azure (Data Factory) provide managed ETL services that can integrate with various cloud data sources and destinations. These platforms often incorporate serverless computing, auto-scaling, and managed services, significantly reducing the operational overhead of managing ETL infrastructure.
Furthermore, the rise of data lakes as central repositories for raw, semi-structured, and structured data has influenced ETL architectures. ETL pipelines now often feed data lakes, where data scientists can access vast amounts of raw data for exploratory analysis and machine learning model development, alongside structured data warehouses for traditional BI. This hybrid approach allows organizations to leverage the best of both worlds, fostering a truly data-driven culture.
The Impact of ETL on Data-Driven Enterprises
The effective implementation of ETL pipelines is not just a technical detail; it is a strategic imperative that underpins the success of data-driven enterprises in the competitive landscape of modern innovation.
Driving Informed Decision-Making
High-quality, integrated data delivered by ETL pipelines empowers executives, managers, and operational teams to make informed decisions. From strategic planning and market analysis to operational efficiency improvements and customer experience enhancements, reliable data provides the foundation for confident choices. This ability to translate raw data into actionable intelligence directly contributes to an organization’s agility and its capacity to adapt to changing market conditions and technological shifts. In a world where data velocity is increasing, timely and accurate decision-making is a significant differentiator.
Facilitating Scalability and Agility
Well-architected ETL processes are designed to handle increasing volumes of data and new data sources without requiring a complete overhaul. This scalability is crucial for organizations experiencing rapid growth or expanding their data footprint through new products, services, or market entries. Furthermore, the flexibility inherent in modern ELT and cloud-native approaches allows data teams to respond quickly to evolving business requirements, integrating new data points or transforming existing ones for emerging analytical needs. This agility ensures that the data infrastructure can keep pace with the speed of innovation, rather than becoming a bottleneck.
The Future of Data Orchestration
As technology continues to advance, the complexity and sophistication of ETL pipelines will only grow. The future involves greater automation, driven by AI and machine learning, to self-optimize pipelines, detect anomalies, and even suggest transformations. Data governance and data lineage will become even more integrated into ETL tools, ensuring transparency and compliance. Real-time processing will become the default for many applications, blurring the lines between operational and analytical systems. Ultimately, ETL pipelines will evolve into even more intelligent, autonomous data orchestration engines, seamlessly delivering the cleansed, transformed data that fuels the next generation of technological breakthroughs and innovative applications across all industries.