
In the rapidly evolving landscape of digital information, the ability to systematically collect and process vast amounts of data has become a cornerstone of technological advancement and innovation. Within this context, the web scraper emerges as a fundamental tool, a piece of software designed to extract information from websites in an automated fashion. Far from being a niche utility, web scraping represents a significant technological innovation that fuels a myriad of data-driven applications, from market research and competitive analysis to academic studies and, increasingly, sophisticated operational intelligence for advanced systems. Understanding what a web scraper is, how it functions, and its role in modern data ecosystems is crucial for appreciating the broader scope of digital innovation.
The Core Concept of Web Scraping
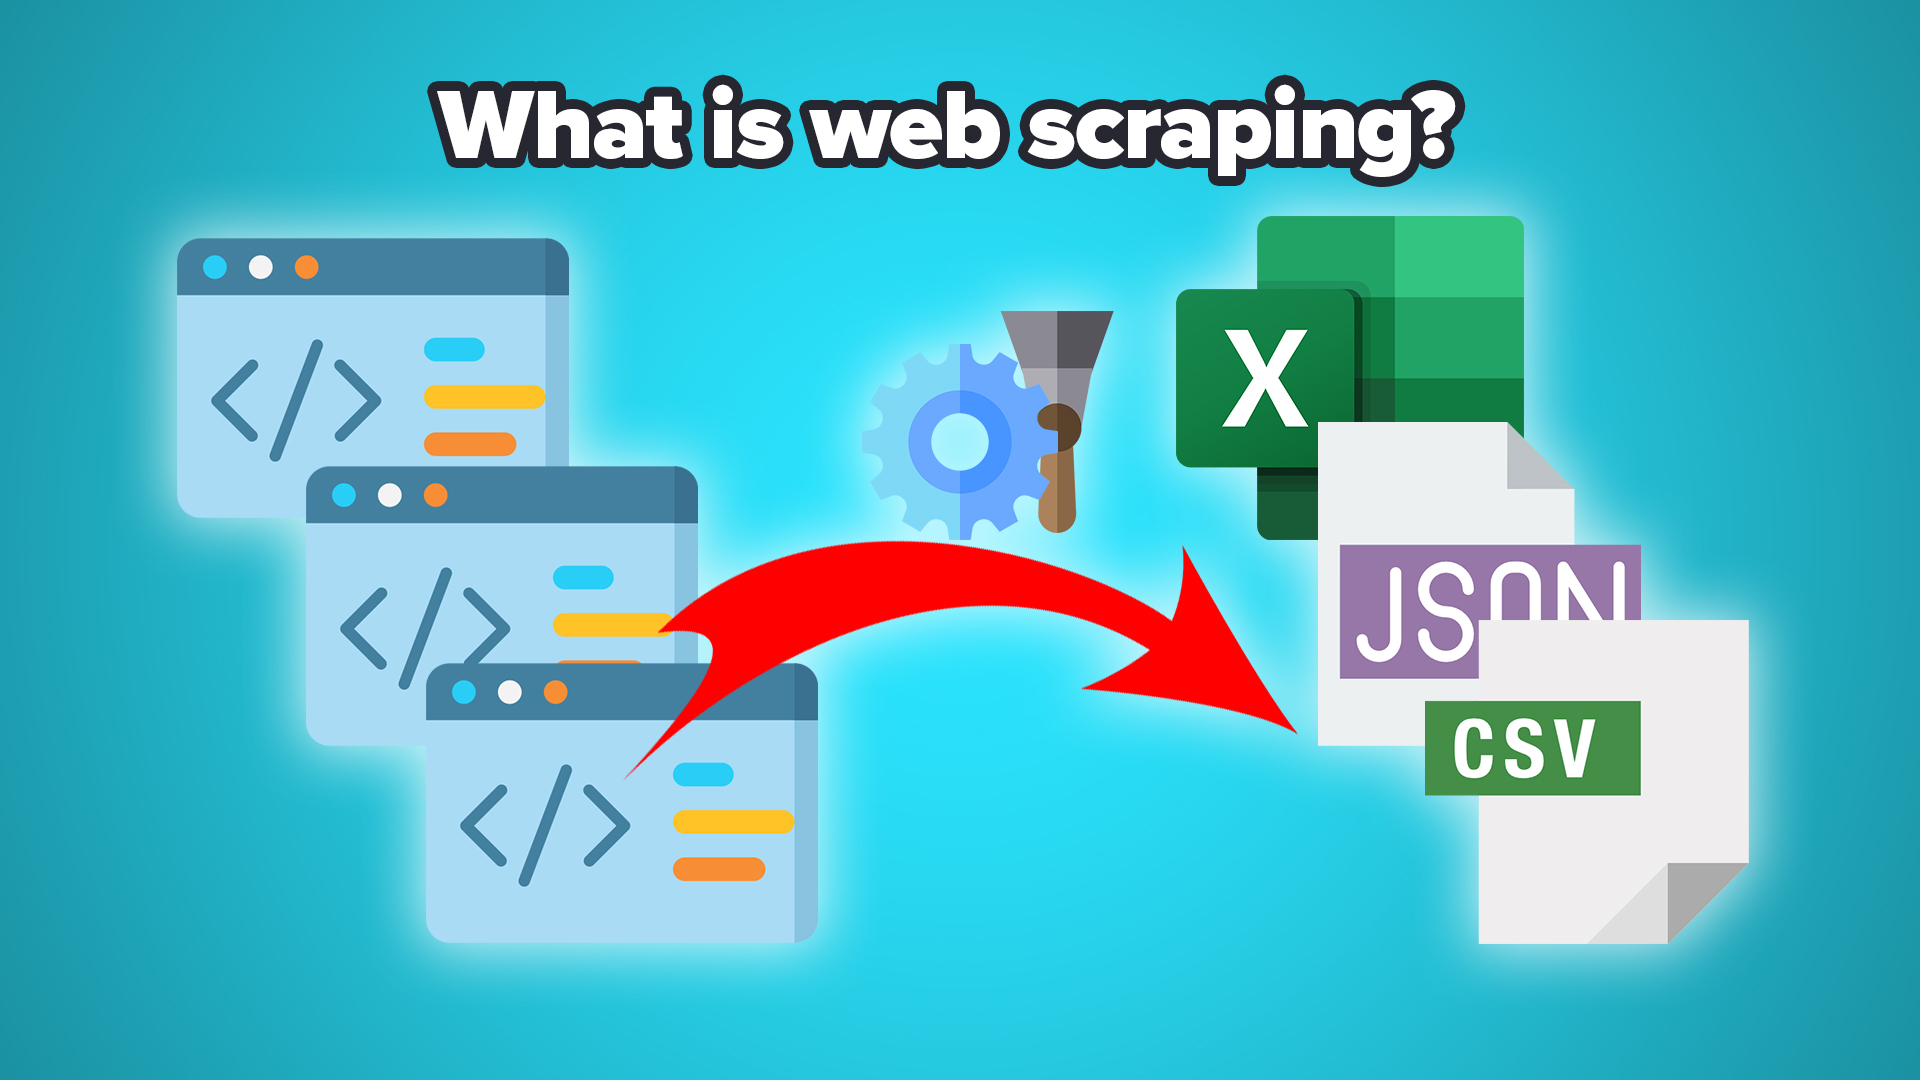
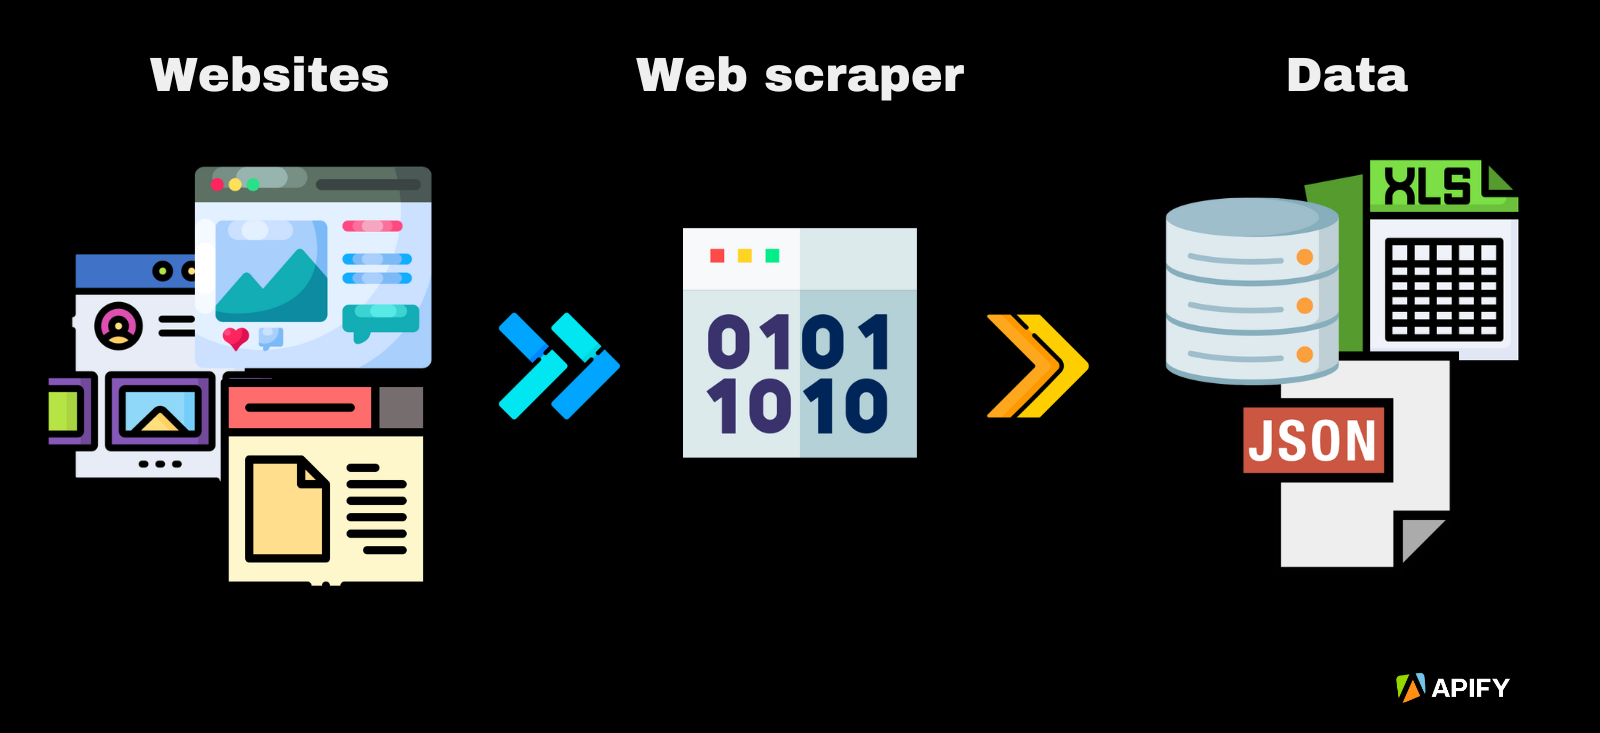
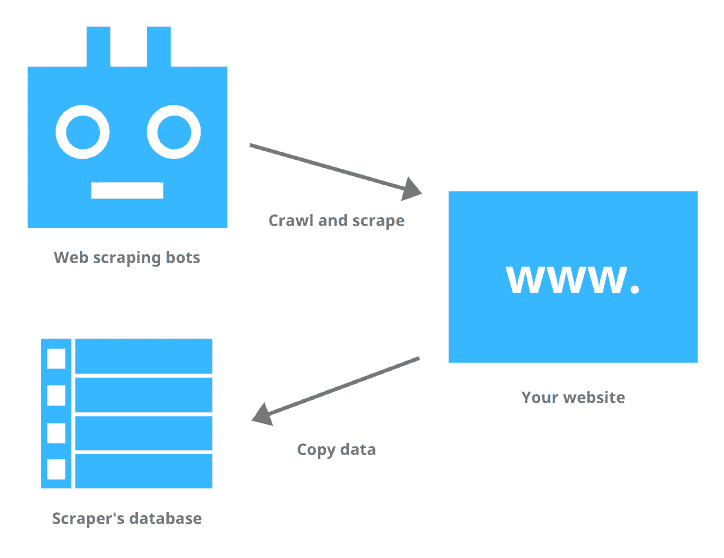
At its heart, a web scraper is an automated process that browses the internet, accesses web pages, and systematically extracts data based on predefined rules. Imagine manually copying and pasting information from hundreds or thousands of web pages; a web scraper performs this task with unparalleled speed and efficiency. It simulates human interaction with a website, navigating through links, filling out forms, and capturing specific elements such as text, images, prices, or contact details.
The operational mechanism typically involves sending HTTP requests to web servers, much like a standard web browser. Upon receiving the server’s response, which is usually in the form of HTML, XML, or JSON, the scraper then parses this data. Parsing refers to the process of analyzing the structure of the document to locate and extract the desired pieces of information. This is often achieved using techniques like XPath, CSS selectors, or regular expressions, which allow the scraper to pinpoint specific data points within the complex structure of a web page. The extracted data is then typically stored in a structured format, such as a CSV file, a database, or another data-friendly format, making it readily available for analysis or integration into other systems.
However, the practice of web scraping exists in a nuanced legal and ethical landscape. Websites often have “Terms of Service” that may prohibit scraping, and many use a robots.txt file to indicate which parts of their site should not be accessed by automated bots. Respecting these directives, along with copyright laws and data protection regulations like GDPR, is paramount for responsible and legitimate data acquisition. Ethical scraping prioritizes transparency, avoids overloading servers, and respects privacy, distinguishing legitimate data collection from malicious activities. As technology advances, the line between ethical data acquisition and potential misuse becomes increasingly scrutinized, underscoring the need for careful adherence to established guidelines and a strong understanding of legal precedents.
Web Scraping as an Enabler of Data-Driven Innovation
While often perceived as a standalone data collection method, web scraping’s true innovative impact lies in its ability to serve as a critical enabler for advanced data-driven technologies. It complements and enhances sophisticated systems that rely on comprehensive, up-to-date information, bridging the gap between publicly available web data and the specific requirements of cutting-edge applications.
Complementing Remote Sensing and Mapping
In the realm of remote sensing and mapping, web scraping offers a vital layer of contextual data that goes beyond what can be captured by physical sensors. Drones and other aerial platforms excel at gathering raw spatial data—imagery, LiDAR scans, thermal profiles—but this data often gains significant value when enriched with supplementary information. For instance, a web scraper can systematically collect publicly available geographical information system (GIS) data from government portals, land-use regulations from municipal websites, property ownership details, or historical environmental records. This scraped data can then be overlaid or integrated with drone-captured maps to provide a richer, more comprehensive understanding of an area.
Consider an autonomous mapping mission focused on urban development. While a drone meticulously records topography and building structures, a web scraper could simultaneously pull zoning laws, proposed construction plans, traffic density reports from public APIs, or demographic statistics from official census websites. This amalgamation of sensor data and scraped web data creates intelligent maps that not only visualize the physical world but also incorporate its regulatory, social, and environmental dimensions. Such integrated datasets are invaluable for urban planning, infrastructure monitoring, environmental impact assessments, and even disaster response, offering a holistic view that neither technology could achieve in isolation. The innovation here is in creating a symbiotic relationship where web scraping extends the utility and intelligence derived from traditional remote sensing techniques.
Fueling Predictive Analytics and Operational Intelligence
Beyond static mapping, the continuous data streams enabled by web scraping are instrumental in fueling predictive analytics and enhancing operational intelligence for various autonomous systems. For systems designed to operate autonomously, access to real-time or near real-time external data is crucial for dynamic decision-making and adaptive behavior.
For example, consider flight path optimization for autonomous aircraft. While on-board sensors provide immediate environmental feedback, a web scraper can continuously monitor and collect vital external data such as real-time weather forecasts, Notice to Airmen (NOTAMs) for airspace restrictions, temporary flight restrictions (TFRs), or even dynamic information on critical infrastructure status from public utility websites. This aggregated data empowers predictive models to anticipate changes in operational conditions, optimize routes for efficiency and safety, or trigger alerts for potential hazards.
Furthermore, in asset monitoring or large-scale surveillance scenarios, scraped data can provide early indicators of anomalies or required interventions. By continuously monitoring news feeds, social media (within ethical boundaries), or public incident reports related to specific geographical areas or assets, web scrapers can provide intelligence that complements visual surveillance. This foresight allows for proactive adjustments to autonomous operations, improves resource allocation, and enhances overall system resilience. The innovation lies in transforming raw web data into actionable intelligence, enabling systems to move from reactive responses to proactive management based on a more complete and dynamic understanding of their operational environment.
Technological Underpinnings and Evolution
The foundational principles of web scraping have evolved significantly, moving beyond simple script-based extraction to incorporate advanced technologies, making it a more robust and intelligent data acquisition method.
Advanced Techniques: AI and Machine Learning Integration
The integration of Artificial Intelligence (AI) and Machine Learning (ML) has revolutionized web scraping, transforming it from a rule-based system into an adaptive and intelligent data extraction engine. Traditional scrapers rely heavily on explicit rules tied to the specific structure of a webpage, meaning they break if a website’s layout changes. AI-powered scrapers, however, can intelligently navigate complex web structures, adapt to dynamic content generated by JavaScript, and even understand the context of data rather than just its location.
Machine learning models can be trained to identify data patterns across different websites, enabling them to extract similar information (e.g., product prices, property details, event dates) even when presented in vastly different web designs. Natural Language Processing (NLP) techniques allow scrapers to understand unstructured text, extracting sentiment, key entities, or thematic information that would be impossible with older methods. This leap in capability means scrapers can handle more diverse, complex, and constantly evolving web content, significantly improving their reliability and the quality of extracted data. Such intelligent scraping capabilities are crucial for supporting AI-driven systems like those found in autonomous flight, where contextual understanding of scraped data can directly inform decision-making algorithms.
Scalability and Real-time Data Streams
Modern web scraping solutions also prioritize scalability and the ability to deliver data in real-time or near real-time. For applications that require up-to-the-minute information, batch processing of data is insufficient. Cloud-based scraping platforms and distributed scraping architectures allow for the simultaneous processing of requests across a vast number of web pages, enabling the collection of massive datasets at high velocity.
The ability to schedule scraping tasks, manage proxies to avoid IP blocking, and handle CAPTCHAs are all part of building resilient, scalable scraping infrastructure. Furthermore, the integration of scraping pipelines with real-time data streaming technologies (like Kafka or message queues) means that extracted data can be immediately pushed to analytical dashboards, machine learning models, or operational control systems. This real-time capability is particularly relevant for dynamic applications such as live traffic monitoring, immediate weather updates for drone operations, or rapid response to unfolding events, ensuring that the insights derived from web data are timely and actionable.
The Future of Data Acquisition in Advanced Systems
As technology continues to advance, the role of web scraping as a crucial component of data acquisition for advanced systems will only grow. The increasing complexity of autonomous systems, the demand for more intelligent mapping solutions, and the need for richer contextual data in remote sensing applications will drive further innovation in scraping techniques. Future developments will likely focus on even more sophisticated AI integration, enabling scrapers to ‘understand’ websites semantically, extract implicit relationships between data points, and operate with even greater autonomy and ethical awareness. The synergy between sensor-based data collection and intelligent web data harvesting will unlock unprecedented capabilities, providing a holistic and dynamic understanding of our world that empowers the next generation of technological innovation.