
In the dynamic landscape of modern technology and innovation, efficient data handling and software distribution are paramount. From managing vast datasets generated by remote sensing platforms to deploying complex AI models or firmware updates for autonomous systems, the ability to package, transfer, and unpack files reliably is a fundamental requirement. Among the myriad file formats that facilitate these operations, the .tar file stands as a cornerstone, embodying a legacy of simplicity and utility that continues to be relevant in cutting-edge applications. While often associated with command-line interfaces and Unix-like operating systems, understanding the .tar format is crucial for anyone engaging with advanced tech environments where robust data management is key.
The Origins and Enduring Relevance of .tar
The .tar file format, an acronym for “tape archive,” emerged in the early days of computing as a standardized method for storing multiple files onto sequential storage media, primarily magnetic tapes. Developed in 1979 as part of Unix Version 7, its design was inherently simple yet incredibly effective for its intended purpose: to collect a hierarchy of files and directories into a single stream. This design philosophy—creating a single, contiguous stream of data—proved incredibly versatile, transcending its original tape-based application to become a ubiquitous format for file archiving, distribution, and data interchange across diverse computing platforms and modern technological stacks.
A Legacy of Archiving
The very name “tape archive” hints at its historical context. Before the advent of large, affordable hard drives and high-speed networks, magnetic tapes were the primary medium for long-term data storage and backup. The .tar utility provided a straightforward way to serialize an entire directory structure, including file permissions, timestamps, and ownership information, into a format that could be written sequentially to tape and later retrieved intact. This early functionality laid the groundwork for its enduring role in system administration, software development, and data preservation across various tech domains.
Not Just Compression
A common misconception is that .tar files inherently compress data. In reality, .tar itself is solely an archiving utility; its primary function is to consolidate multiple files and directories into a single file, preserving their metadata and hierarchical structure. It does not reduce the overall size of the data. This distinction is crucial, as it highlights .tar‘s specific utility: organizing data for easier transport or storage, rather than optimizing its footprint. The widely used compressed variants, such as .tar.gz or .tar.bz2, are the result of combining the .tar archiver with separate compression algorithms like gzip or bzip2. This modular approach allows for flexibility, enabling developers and engineers to choose the most appropriate compression method based on their specific needs for efficiency and decompression speed.
Dissecting the .tar Format
Understanding the internal structure of a .tar file reveals its elegance and robustness. Unlike more complex archive formats that might employ intricate indexing or proprietary compression schemes, .tar adheres to a straightforward, block-oriented design. This simplicity is a significant factor in its widespread adoption and continued relevance in environments demanding high reliability and broad compatibility.
Simple Concatenation
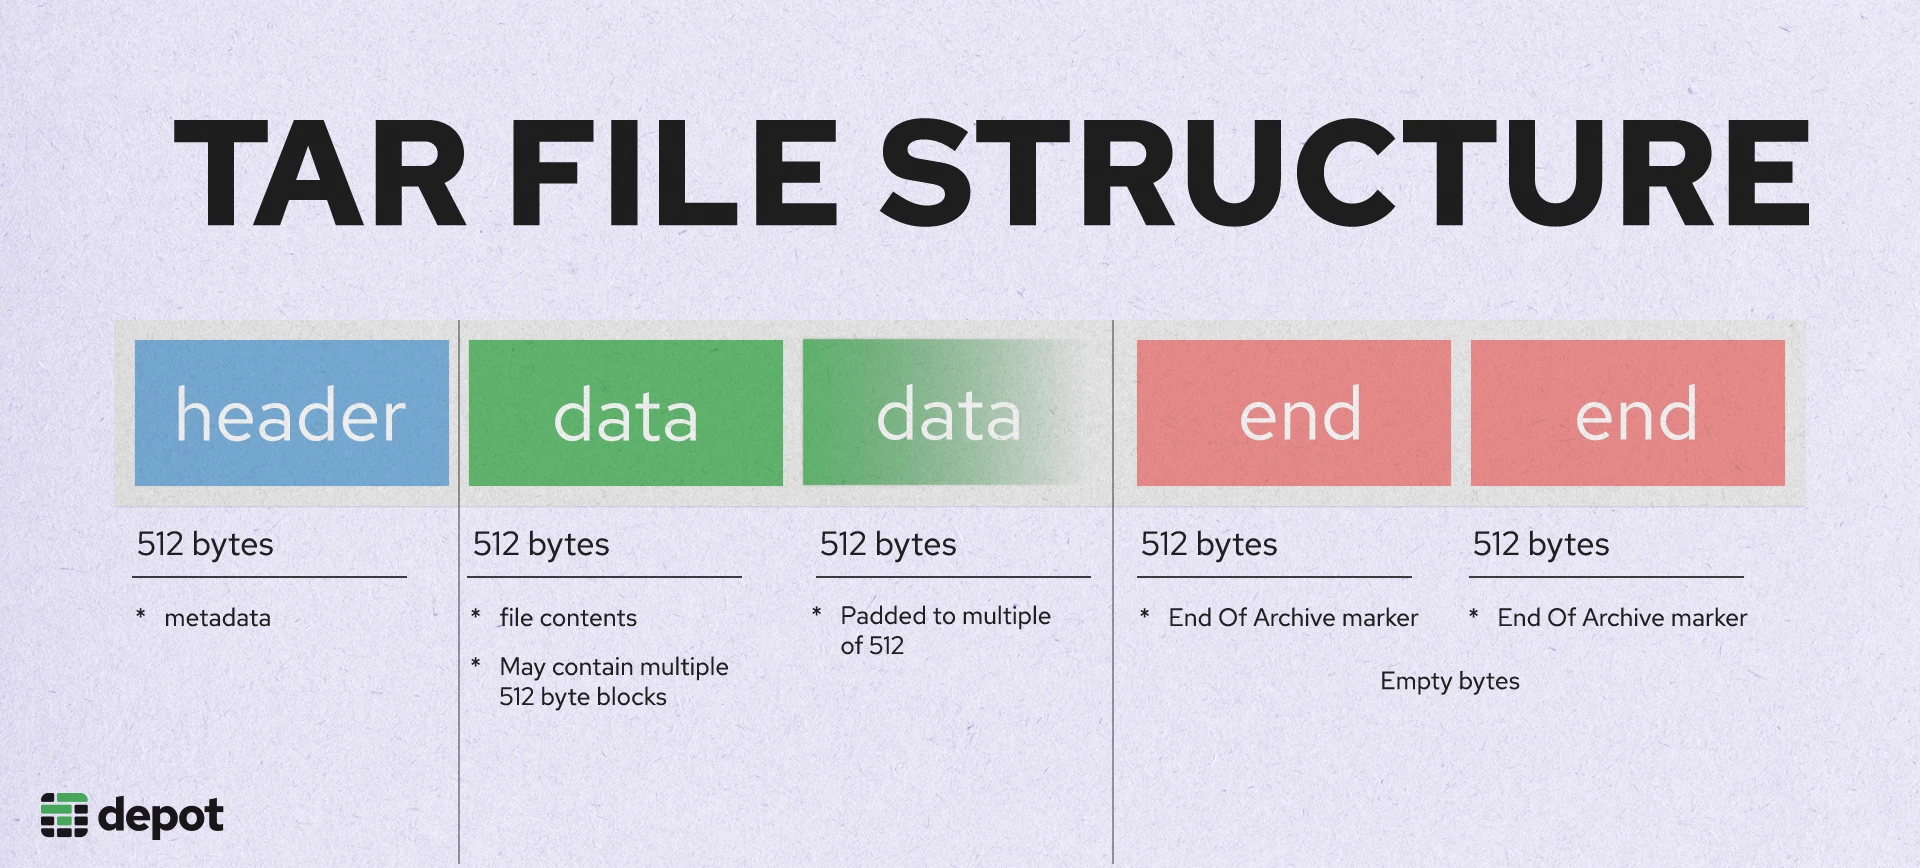
At its core, a .tar file is a concatenation of individual file archives. Each archived file within the .tar stream is preceded by a header block. Following the header, the actual content of the file is written, padded with null bytes to ensure it occupies a multiple of 512 bytes—the standard block size for .tar. This sequential layout means that to access a file located later in the archive, the system typically needs to read through the preceding data, an echo of its tape-oriented heritage. This structure, while not ideal for random access, is exceptionally robust for sequential processing and streaming.
Header Information
Each file’s header block is a 512-byte record that contains all the essential metadata about that particular file. This includes:
- File Name: The path and name of the archived file.
- File Mode: Permissions (e.g., read, write, execute) for the file.
- User ID (UID) and Group ID (GID): Identifiers for the owner and group of the file.
- Modification Time: The timestamp of when the file was last modified.
- File Size: The exact size of the file’s content in bytes.
- Checksum: A value used to verify the integrity of the header block.
- File Type: Indicates whether it’s a regular file, directory, symbolic link, etc.
- Link Name: For hard or symbolic links, the target path.
This comprehensive metadata preservation is a significant advantage of .tar, ensuring that when files are extracted, they retain their original attributes, which is critical for maintaining system integrity and reproducibility in development and deployment workflows.
.tar’s Role in Modern Tech & Innovation
While rooted in computing’s past, .tar remains exceptionally pertinent in contemporary technology and innovation, particularly where structured data management, software distribution, and system integrity are paramount. Its simplicity and universality make it an invaluable tool in diverse applications, from large-scale data science to autonomous system development.
Data Management for Large Datasets
In fields like remote sensing, geospatial intelligence, and scientific research, the generation and transfer of massive datasets are commonplace. High-resolution imagery, LiDAR scans, environmental sensor data, and simulation outputs often consist of thousands or even millions of individual files and complex directory structures. Packaging these into a single .tar archive, often subsequently compressed, simplifies storage, reduces the number of files to manage, and streamlines transfer over networks. This is particularly useful for distributing research datasets or sending collected data from field-deployed autonomous vehicles (e.g., UAVs collecting mapping data) to processing centers, ensuring that the entire dataset, complete with its original hierarchy, arrives intact.
Software and Firmware Distribution
The open-source community heavily relies on .tar archives for distributing source code, libraries, and application packages. Developers frequently release their projects as .tar.gz or .tar.xz files, providing a universal format that can be easily downloaded, extracted, compiled, and installed across various Linux and Unix-like systems—the foundational operating systems for much of modern tech infrastructure, including servers, embedded systems, and development environments for AI and machine learning. Similarly, firmware updates for sophisticated hardware, from IoT devices to high-end drone navigation systems, are often bundled in .tar derivatives to ensure all necessary components (kernel modules, binaries, configuration files) are delivered together in a reliable, atomic package.
System Backups and Portability
For maintaining the integrity and availability of complex technological systems, regular backups are indispensable. .tar provides a robust mechanism for creating point-in-time snapshots of entire directory trees, including system configurations, application data, and user files. Its ability to preserve file permissions, symbolic links, and directory structures ensures that a backed-up system can be accurately restored. Furthermore, its portability makes it suitable for migrating software environments or even entire virtual machine images between different hosts or cloud platforms, critical for scaling and managing modern IT infrastructure.
Containerization and Virtualization Support
Even in advanced virtualization and containerization technologies, the underlying principles of .tar play a role. Docker, for instance, uses a .tar like format internally for building and transferring image layers. When you commit changes to a Docker container or export an image, the filesystem differences are often represented as .tar archives, allowing for efficient layering and distribution of container images. This demonstrates how a simple, venerable format can underpin highly sophisticated and distributed computing paradigms.
Working with .tar Files: Practical Applications
Interacting with .tar files is a fundamental skill in many tech roles. While graphical user interfaces (GUIs) in some operating systems provide drag-and-drop functionality for .tar and .tar.gz files, the command-line interface (CLI) remains the most powerful and versatile method, particularly in server environments, scripting, and automated workflows.
Archiving and Extracting
The core operations for .tar files involve creating archives and extracting their contents.
To create an archive:
tar -cvf archive.tar /path/to/directory_or_files/
Here, -c stands for create, -v for verbose output (showing files being added), and -f specifies the archive filename.
To extract an archive:
tar -xvf archive.tar
Here, -x stands for extract.
These simple commands are the gateway to managing complex data structures and software packages efficiently.
Combining with Compression
As noted, .tar files are often compressed using external tools. The most common compression utilities are gzip (resulting in .tar.gz or .tgz files), bzip2 (resulting in .tar.bz2 or .tbz files), and xz (resulting in .tar.xz or .txz files). Modern tar utilities can handle the compression and decompression automatically through flags:
To create a gzipped tar archive:
tar -czvf archive.tar.gz /path/to/directory_or_files/ (-z for gzip)
To extract a gzipped tar archive:
tar -xzvf archive.tar.gz
Similar flags exist for bzip2 (-j) and xz (-J), making the workflow seamless. Choosing the right compression method depends on factors like desired compression ratio, speed of compression/decompression, and available system resources. For instance, xz generally offers better compression than gzip at the cost of slower processing, which might be preferred for long-term storage or slow network transfers of large datasets.
Cross-Platform Compatibility
While primarily associated with Unix-like systems, the .tar format’s simplicity and open specification have led to widespread support across various operating systems. Tools and libraries exist for creating and extracting .tar archives on Windows, macOS, and other platforms, ensuring broad compatibility for data exchange and software distribution in multi-platform tech environments. This universality solidifies its position as a go-to format for robust data packaging in complex, interconnected systems.
Advantages and Considerations
The continued prevalence of .tar in advanced tech underscores several key advantages, alongside a few considerations for its optimal use.
Simplicity and Universality
The .tar format’s most significant strength lies in its inherent simplicity. It is an open, well-understood standard that has remained stable for decades. This ensures maximum compatibility and longevity, reducing the risk of obsolescence that can plague more complex or proprietary formats. Its universal support across operating systems and programming languages makes it a reliable choice for interoperability in diverse technological ecosystems.
Stream-Based Operations
The sequential nature of .tar files is highly advantageous for stream-based operations. Data can be archived and unarchived directly through pipelines, facilitating efficient processing without requiring intermediate disk storage for the entire archive. This is particularly valuable in cloud computing environments, distributed systems, and real-time data processing workflows where efficiency and minimal latency are critical. For example, data from a sensor array can be continuously tarred and piped directly to a remote storage or analysis cluster.

Potential Downsides
Despite its strengths, .tar does have some limitations. Its sequential design means that randomly accessing a specific file within a very large archive can be inefficient, as the system may need to read through a substantial portion of the preceding data. For scenarios requiring frequent random access to individual files within an archive, other formats or database solutions might be more appropriate. Additionally, while it preserves most common file metadata, some highly specific filesystem attributes might not be universally supported across all .tar implementations or operating systems. However, for its primary role in bulk archiving and distribution, these limitations are generally minor in the face of its overwhelming benefits.
In summary, the .tar file format, with its humble origins in tape archiving, has evolved into an indispensable tool in the arsenal of modern tech and innovation. Its straightforward design, robust metadata preservation, and universal compatibility make it an ideal choice for managing large datasets, distributing complex software, and ensuring system integrity across the rapidly expanding frontiers of technology. Understanding and leveraging .tar is not just about historical context; it’s about harnessing a powerful, enduring utility for present and future technological challenges.