
In the vast and ever-expanding digital landscape, the ability to efficiently locate precise information is paramount. Traditional search engines like Google, Bing, and DuckDuckGo have become indispensable gateways to the internet’s immense repository of knowledge. However, each operates independently, employing distinct algorithms and indexing methodologies. This is where the concept of a meta search tool emerges as a significant innovation, offering a unique approach to information retrieval within the broader domain of Tech & Innovation.
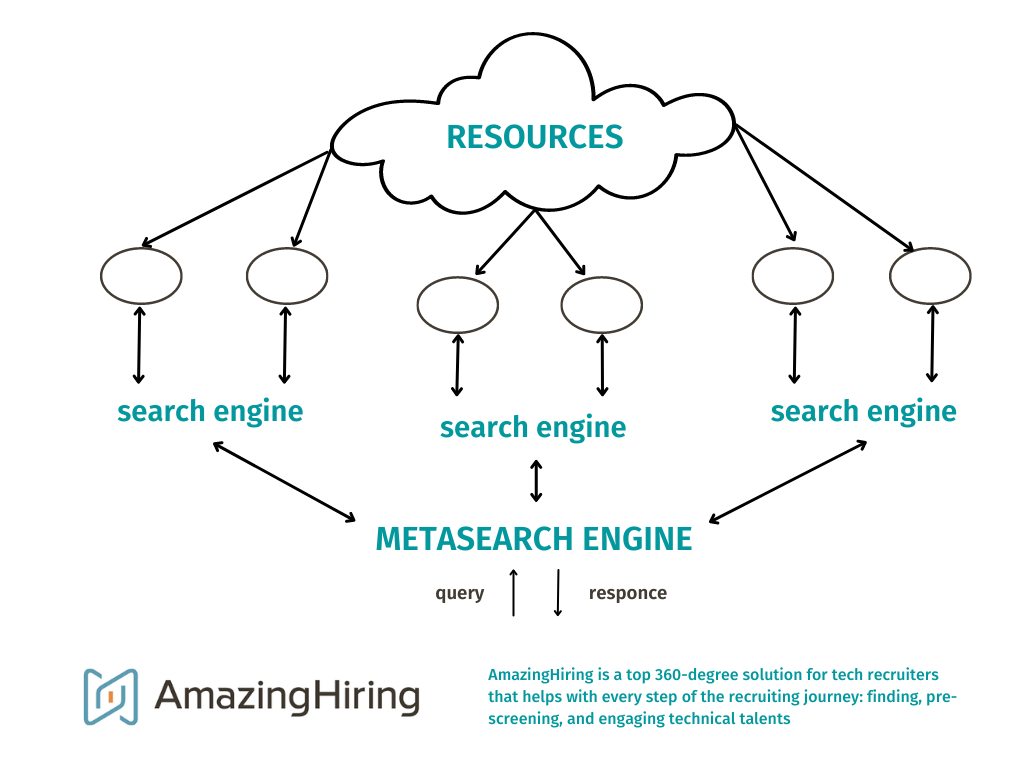
A meta search tool is essentially a search engine that doesn’t maintain its own index of web pages. Instead, when a user submits a query, it simultaneously dispatches that query to multiple other independent search engines. It then aggregates the results received from these various sources, processes them—often by removing duplicates and re-ranking—and presents a consolidated list to the user. The primary objective is to cast a wider net, providing a more comprehensive and potentially less biased set of results than any single search engine could offer on its own. It acts as an intelligent intermediary, streamlining the process of exploring diverse information landscapes.

Understanding the Core Concept
To fully grasp the utility and operational mechanics of a meta search tool, it’s crucial to first understand how its foundational components—traditional search engines—function and then delve into the aggregation principle that defines meta search.
How Traditional Search Engines Operate
Traditional search engines operate on a complex, multi-stage process. First, “crawlers” or “spiders” systematically traverse the internet, following links from page to page, discovering new content. This content is then indexed, meaning it’s categorized and stored in massive databases according to keywords, topics, and other metadata. When a user enters a search query, the engine’s proprietary algorithms spring into action. These algorithms analyze the query, compare it against their vast index, and rank relevant pages based on hundreds of factors, including keyword density, link popularity, page authority, and user engagement signals. Each major search engine has its unique algorithm, leading to varying results even for identical queries. This inherent divergence in indexing and ranking is precisely what meta search tools aim to leverage.
The Aggregation Principle
The aggregation principle is the cornerstone of meta search technology. When a user inputs a search term into a meta search tool, that query is not processed against a proprietary index. Instead, it is simultaneously sent to a predetermined set of underlying traditional search engines. These underlying engines then return their respective results to the meta search tool. Upon receiving these disparate lists, the meta search tool employs its own set of algorithms to combine, sort, and filter the data. This often involves:
- Deduplication: Identifying and removing identical results returned by multiple engines.
- Re-ranking: Applying its own logic to sort the combined results, sometimes prioritizing diversity or relevance across different sources.
- Formatting: Presenting the consolidated results in a uniform, user-friendly interface.
This process ensures that the user receives a broad spectrum of information, potentially including links that might have been buried deep in one engine’s results or entirely missed by another. It’s an exercise in synergy, drawing power from multiple independent systems to create a more comprehensive output.
The Advantages of Using Meta Search Tools
The innovative approach of meta search tools offers several compelling advantages, particularly relevant in an era where information access and critical evaluation are key components of technological literacy.
Comprehensive Results
By querying multiple search engines concurrently, meta search tools inherently cast a wider net across the internet’s indexed content. This often leads to a more comprehensive set of results. While major search engines are vast, no single engine indexes the entirety of the web or assigns the same relevance to every piece of content. A meta search tool can uncover valuable information that might be ranked lower or completely overlooked by one engine but prioritized by another. This breadth is particularly useful for niche topics, obscure data, or when users require an exhaustive overview of a subject.
Time Efficiency
Without a meta search tool, a user seeking comprehensive results would have to manually input the same query into several different search engines, sift through each set of results, and then mentally (or physically) combine them. This is a tedious and time-consuming process. Meta search tools automate this entire workflow, allowing users to perform a single query and receive a consolidated list of results from multiple sources, significantly enhancing efficiency and productivity.
Mitigating Bias and Filter Bubbles

Traditional search engines, especially those with personalized experiences, can inadvertently create “filter bubbles” or reinforce algorithmic biases. Their ranking systems are designed to predict what content users are most likely to engage with, often based on past search history, location, and other demographic data. This can lead to a narrow view of information, showing users only what aligns with their presumed interests or established perspectives. Meta search tools, by aggregating results from diverse engines with different ranking criteria and often without personalized tracking, can help to mitigate these biases. They offer a more varied perspective, potentially exposing users to alternative viewpoints or less-mainstream content they might not otherwise encounter.
Enhanced Privacy Considerations
A significant advantage of many meta search tools, especially newer iterations focused on user rights, is their commitment to privacy. Unlike some major search engines that track user activity, IP addresses, and search history to build detailed user profiles for advertising or other purposes, many meta search tools operate with a “no-logging” policy. They often strip identifying information from queries before sending them to underlying engines and do not store user search data. For individuals and organizations concerned about digital privacy and data surveillance, this makes meta search tools a compelling alternative.
Disadvantages and Limitations
While offering distinct benefits, meta search tools are not without their drawbacks. Understanding these limitations is crucial for discerning when and where they are most effective.
Redundancy and Relevance Challenges
One common issue with meta search results is redundancy. Since multiple engines might return the same top-ranking pages, the aggregated list can sometimes be cluttered with duplicate links, even after deduplication attempts. More significantly, the challenge of maintaining relevance can arise. Each underlying search engine uses its unique algorithms for ranking, and when these diverse results are combined, the meta search tool must apply its own, often simpler, re-ranking logic. This can sometimes lead to less relevant results appearing higher in the aggregated list than they would in a single, highly optimized engine. The nuanced contextual understanding that a powerful, single search engine applies might be diluted in the aggregation process.
Slower Performance
The very mechanism that gives meta search tools their power—querying multiple external sources—can also be a source of delay. The meta search tool must wait for responses from all queried engines, and then process these results before presenting them to the user. This multi-step communication and processing can sometimes make meta searches perceptibly slower than direct searches performed on a single, highly optimized engine with a direct connection to its own index. For users prioritizing speed above all else, this can be a minor inconvenience.
Lack of Advanced Features
Major traditional search engines have evolved to offer a wealth of advanced features beyond simple keyword searching. These include highly refined filters (by date, file type, region), specialized search functionalities (image search, video search, news search, academic search), knowledge panels providing direct answers, and integrated tools (currency converters, weather forecasts). Meta search tools, by their nature, generally struggle to replicate this level of sophistication across all their aggregated sources. They typically focus on core web page search, meaning users might miss out on these valuable supplementary tools and features when opting for a meta search.
Applications and Future Trends in Tech & Innovation
The concept of meta search extends far beyond general web queries, finding specialized applications and poised for significant evolution within the broader landscape of Tech & Innovation.
Beyond Web Search: Specialized Meta Tools
The meta search paradigm is incredibly versatile and has been successfully applied to numerous specialized domains. Travel aggregators, for instance, are quintessential meta search tools, querying multiple airlines, hotels, and car rental agencies to present a consolidated list of options and prices. Similarly, job search platforms often function as meta search engines, pulling listings from various corporate career pages, job boards, and recruitment sites. Academic search engines aggregate scholarly articles from diverse databases, and product comparison websites gather specifications and prices from various e-commerce vendors. This specialization highlights the adaptability of the meta search concept as a powerful information synthesis tool for specific industries and user needs.
Integration with AI and Machine Learning
The future of meta search tools is intrinsically linked with advancements in Artificial Intelligence (AI) and Machine Learning (ML). Current meta search tools primarily focus on syntactic aggregation and basic deduplication. However, AI/ML can elevate them to new levels of intelligence. Imagine a meta search tool that not only aggregates results but uses natural language processing (NLP) to understand the semantic context of a query and the content of the results. AI could dramatically improve deduplication by identifying conceptually similar but textually different pages, perform advanced re-ranking based on latent relevance rather than just keyword matching, and even synthesize information from disparate sources into concise, coherent answers rather than just presenting a list of links. Machine learning could personalize the aggregation process without compromising privacy, by learning user preferences locally on their device, thereby offering a more tailored yet unbiased experience.
The Role in Big Data and Analytics
In the era of big data, where organizations grapple with vast, heterogeneous datasets, the meta search concept holds immense potential for analytics and strategic insights. Researchers, data scientists, and business intelligence analysts often need to pull information from numerous internal and external data sources that are not indexed by a single, monolithic system. A meta search framework, perhaps adapted to query internal databases, cloud storage, external APIs, and public web resources, could provide a unified interface for data discovery. This capability would be invaluable for competitive intelligence, market trend analysis, scientific discovery, and threat intelligence, allowing for a more holistic view of information by breaking down data silos and enabling comprehensive data harvesting from a diverse digital ecosystem. The ability to quickly and thoroughly survey multiple information landscapes makes meta search a vital component in the toolkit for navigating the complexities of modern data environments.