
The Engine of Modern Computing Power
In the rapidly evolving landscape of technology, certain components stand out as foundational to advancements across diverse fields. Among these, the Graphics Processing Unit (GPU) has emerged as a cornerstone of modern computing, particularly in its profound impact on artificial intelligence (AI). While initially conceived to render complex visual graphics for video games and professional design applications, the GPU’s parallel processing architecture has proven to be exceptionally well-suited for the computationally intensive tasks that define AI development and deployment. Understanding the GPU’s capabilities is crucial to grasping the trajectory of AI’s integration into our daily lives and specialized industries.
The fundamental distinction between a Central Processing Unit (CPU) and a GPU lies in their design philosophy and intended purpose. A CPU, the “brain” of a computer, is designed for general-purpose computing. It excels at handling a wide variety of tasks sequentially, executing complex instructions one after another with high precision. This makes it ideal for tasks like running operating systems, managing applications, and performing logical operations. In contrast, a GPU is a specialized processor engineered for massively parallel computation. It contains thousands of smaller, more efficient cores designed to perform the same operation simultaneously on large datasets. This architecture is inherently optimized for tasks that can be broken down into numerous independent, repetitive calculations.
From Pixels to Parallelism: The Evolution of the GPU
The genesis of the GPU can be traced back to the demands of the burgeoning computer graphics industry. Early computer displays relied on software rendering, a process that was slow and limited in its ability to produce realistic imagery. The advent of dedicated graphics cards, and later integrated GPUs, revolutionized this by offloading the complex calculations involved in rendering polygons, textures, and lighting directly to specialized hardware. This not only enabled smoother gameplay and more sophisticated visual effects but also freed up the CPU to focus on other system operations.
This shift was driven by the need for speed and efficiency in graphics processing. Rendering a single frame of a modern video game can involve billions of calculations related to the position, color, and lighting of millions of individual pixels. A CPU, with its limited number of powerful cores, would be overwhelmed by such a task. A GPU, with its multitude of simpler cores, can divide the rendering workload among these cores, with each core handling a portion of the frame or a specific type of calculation. This parallel processing approach dramatically accelerated the rendering pipeline.
The architectural innovation that underpins GPU performance is its use of Single Instruction, Multiple Data (SIMD) or Single Instruction, Multiple Threads (SIMT) processing. In essence, this means that a single instruction can be applied to multiple data elements concurrently. For graphics, this translates to applying the same transformation or shading operation to thousands of pixels at once. This fundamental capability, while initially designed for visual data, proved to be a perfect fit for the computational needs of AI.
AI’s Computational Demands: A Perfect Match for GPU Architecture
Artificial intelligence, particularly in its modern forms like deep learning, is characterized by enormous datasets and complex mathematical operations. Training an AI model, especially a neural network, involves iteratively adjusting millions or even billions of parameters based on vast amounts of input data. This iterative process requires performing a multitude of matrix multiplications, vector additions, and other linear algebra operations. These are precisely the types of computations that a GPU is built to handle with exceptional speed.
Deep Learning and Neural Networks: The GPU’s Sweet Spot
Deep learning, a subfield of machine learning that uses multi-layered neural networks, has been the primary driver behind many of AI’s recent breakthroughs. Neural networks are inspired by the structure and function of the human brain, with interconnected nodes (neurons) organized in layers. During training, the network receives input data, processes it through its layers, and produces an output. The difference between this output and the desired outcome is used to adjust the “weights” of the connections between neurons. This adjustment process, known as backpropagation, involves calculating gradients across the entire network, which requires a significant amount of parallel computation.
Consider the process of training a convolutional neural network (CNN) for image recognition. A CNN consists of multiple layers, including convolutional layers, pooling layers, and fully connected layers. Each convolutional layer performs operations on small regions of the input image, extracting features. These operations involve sliding filters across the image and performing element-wise multiplications and summations. A GPU can efficiently execute these filter operations in parallel across different regions of the image and across multiple filters simultaneously.
Similarly, in natural language processing (NLP) tasks such as language translation or sentiment analysis, recurrent neural networks (RNNs) and transformer models are often employed. These models also rely heavily on matrix operations for processing sequential data. The ability of GPUs to perform these operations on massive matrices in parallel makes them indispensable for training large and complex language models.
The Role of Parallelism in AI Training
The parallelism inherent in GPUs allows them to outperform CPUs by orders of magnitude when it comes to AI training. While a CPU might process a single matrix multiplication sequentially, a GPU can distribute the computation across its thousands of cores, completing the task in a fraction of the time. This drastically reduces the time required to train AI models, moving from weeks or months to days or even hours for certain tasks. This acceleration has been pivotal in democratizing AI research and development, allowing researchers and developers to experiment with more complex models and larger datasets.
The specific types of calculations that are heavily optimized on GPUs for AI include:
- Matrix Multiplication: The bedrock of many AI algorithms, especially in neural networks. Large matrices representing weights and inputs are multiplied to produce outputs and gradients.
- Convolutions: Fundamental to CNNs for feature extraction from images and other grid-like data.
- Element-wise Operations: Operations like addition, subtraction, and activation functions applied to individual elements of tensors (multi-dimensional arrays).
- Reductions: Operations that aggregate data along specific dimensions, such as summing or averaging.
The efficiency gained from parallelizing these operations on a GPU directly translates to faster model development, quicker iteration cycles, and the ability to tackle more ambitious AI projects.
Beyond Training: GPUs in AI Inference and Deployment
The impact of GPUs on AI extends beyond the training phase. Once an AI model is trained, it needs to be deployed to make predictions or classifications on new, unseen data. This process is known as inference. While inference typically requires less computational power than training, it can still be a bottleneck for real-time applications or when processing massive volumes of data.
Accelerating Real-Time AI Applications
For applications that require immediate responses, such as autonomous driving, real-time video analysis, or interactive AI assistants, fast inference is critical. GPUs can accelerate the inference process by executing the forward pass of a trained neural network much faster than a CPU. This means that an AI system can analyze sensor data, process natural language commands, or identify objects in video streams with minimal latency, enabling responsive and effective operation.
In the realm of computer vision, for instance, GPUs are used to accelerate object detection, image segmentation, and facial recognition in real-time video feeds. This is essential for applications ranging from security surveillance and industrial automation to augmented reality experiences.
Edge AI and the Need for Efficient Hardware
The growing trend of “edge AI,” where AI models are deployed directly on devices rather than relying on cloud servers, further highlights the importance of GPUs. Edge devices, such as smartphones, smart cameras, and IoT sensors, often have limited power and processing capabilities. Specialized GPUs, including those found in mobile chipsets and dedicated AI accelerators, are designed to provide efficient AI inference capabilities at the edge, enabling on-device intelligence without constant connectivity.
These edge-focused GPUs are optimized for lower power consumption and smaller form factors, allowing for AI-powered features to be embedded directly into a wide range of devices. This not only enhances privacy and security by keeping data local but also enables AI functionality in environments with limited or no network access.
The Future of AI and GPU Symbiosis
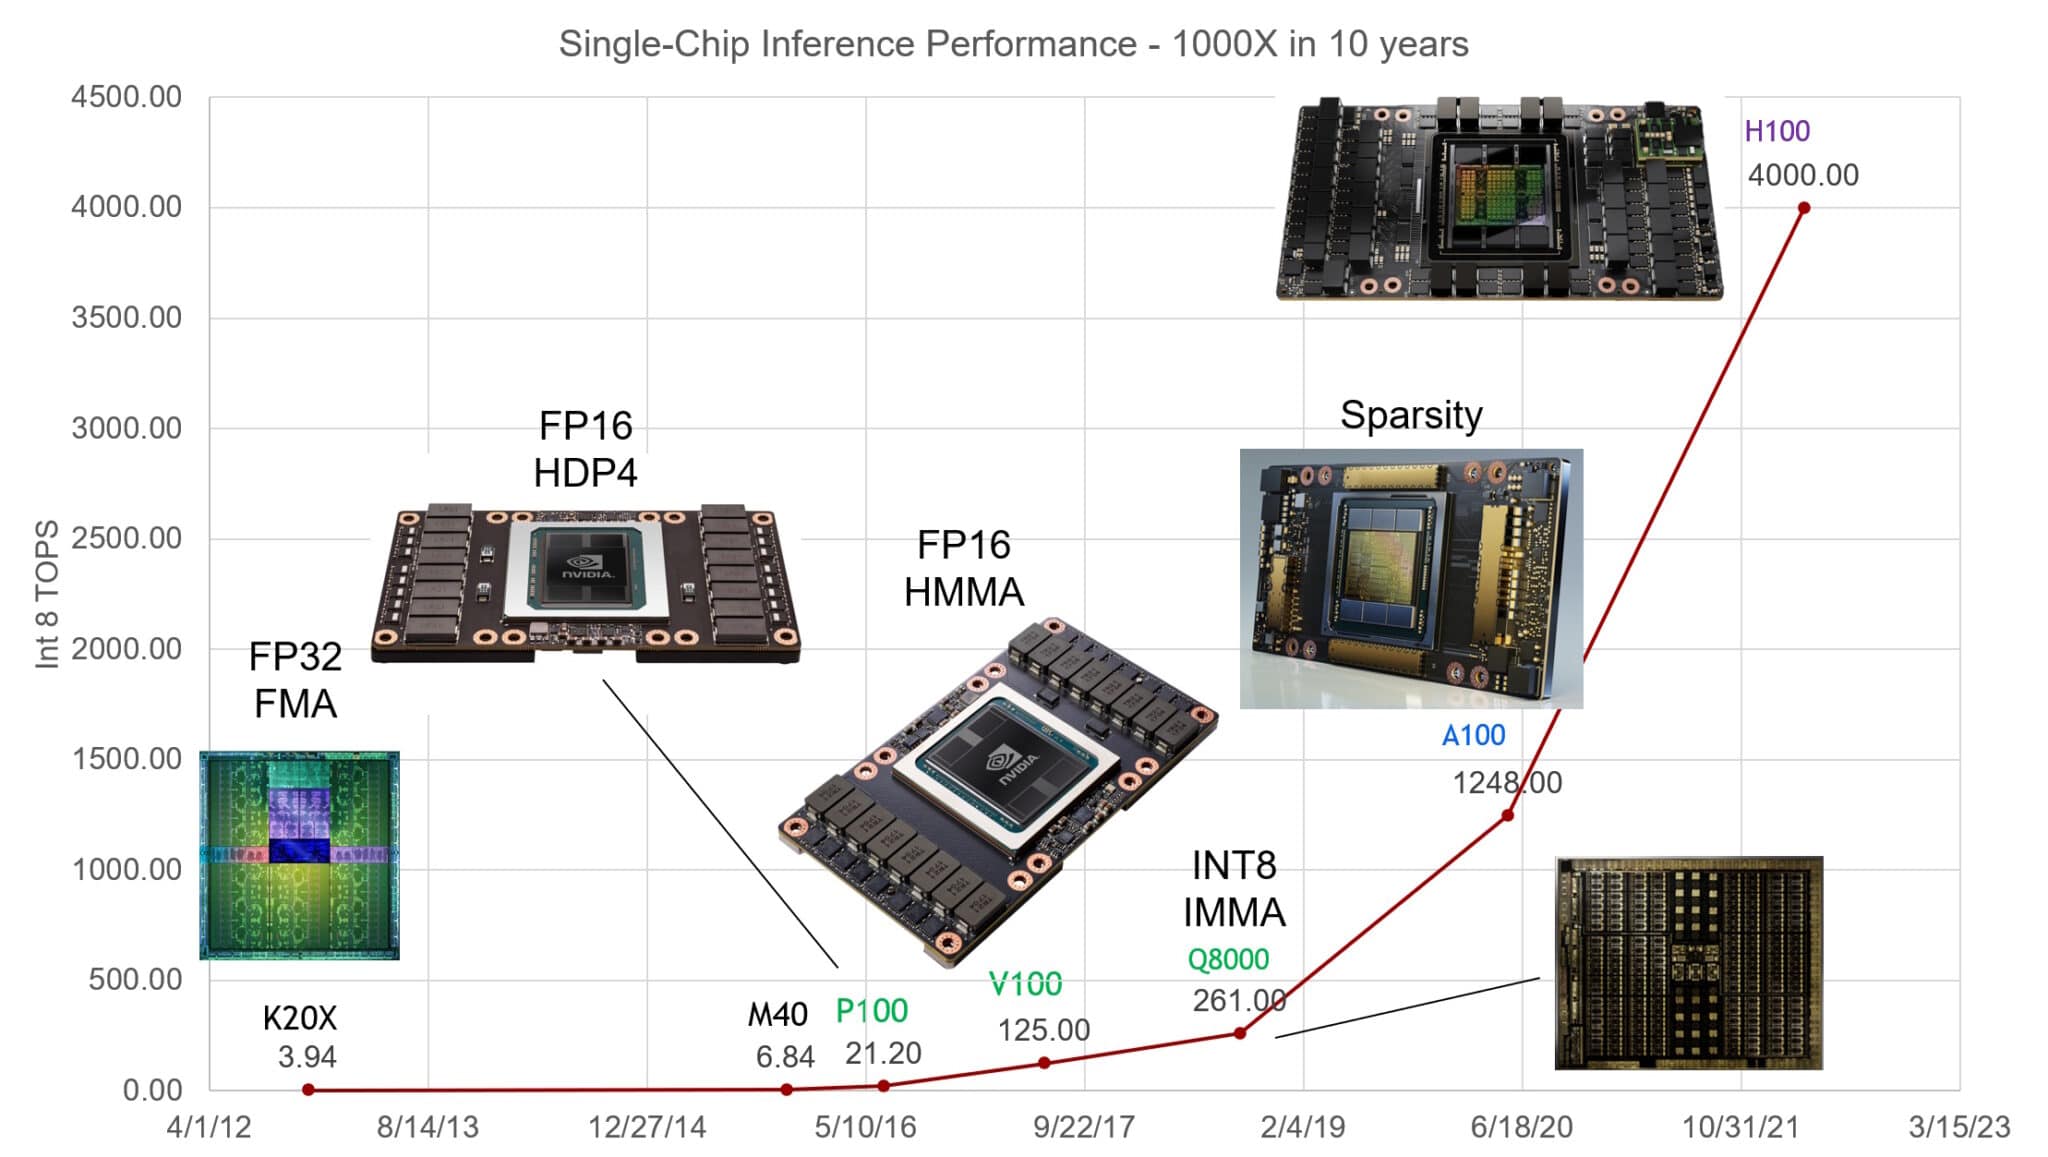
The relationship between GPUs and AI is symbiotic and mutually beneficial. The increasing complexity and scale of AI models continue to push the boundaries of GPU hardware, driving innovation in areas like specialized AI cores (e.g., Tensor Cores) and improved memory bandwidth. In turn, advancements in GPU technology enable the development of more sophisticated and capable AI systems, creating a virtuous cycle of progress.
Specialized AI Hardware on GPUs
Modern GPUs are increasingly incorporating specialized hardware designed specifically for AI workloads. NVIDIA’s Tensor Cores, for example, are dedicated processing units that accelerate mixed-precision matrix multiply-accumulate operations, which are fundamental to deep learning. These specialized cores can significantly boost the performance of AI training and inference, making GPUs even more efficient for AI tasks.
Emerging Trends and Future Possibilities
As AI continues to evolve, the demands on computational hardware will only grow. Future GPUs will likely feature even greater parallelism, more advanced memory architectures, and tighter integration with AI-specific software frameworks. Research into novel computing paradigms, such as neuromorphic computing, may also be influenced by the lessons learned from GPU architecture.
The ongoing development of AI, from more complex generative models to more robust reasoning systems, will continue to rely on the raw computational power and parallel processing capabilities that GPUs provide. The ability to quickly train and deploy these advanced AI models will be directly tied to the advancements in GPU technology, solidifying the GPU’s position as an indispensable component in the AI revolution. The synergy between AI’s computational needs and the GPU’s architectural strengths ensures that this powerful partnership will continue to shape the future of technology and innovation for years to come.