
In the realm of data warehousing and business intelligence, understanding the fundamental building blocks is crucial for effective analysis and insightful decision-making. Among these, the fact table stands out as a central component, housing the quantitative measurements and metrics that drive business performance. Unlike dimension tables, which provide descriptive context, fact tables are the engines of analysis, holding the “what,” “when,” and “how much” of business events.
The Core of the Data Warehouse: Dimensions and Facts
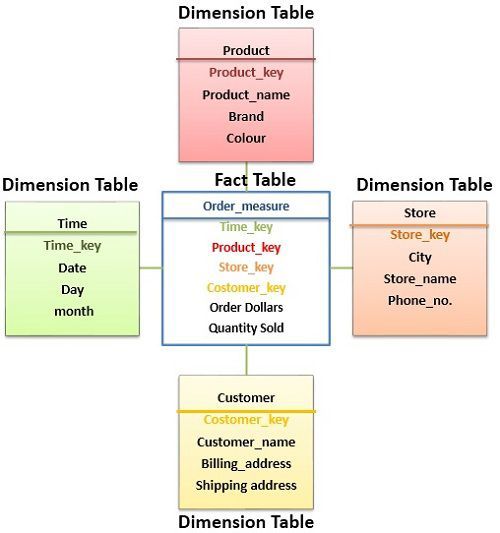
To fully grasp the role of a fact table, it’s essential to understand its relationship with dimension tables. A typical data warehouse utilizes a dimensional model, often employing a star or snowflake schema. In this structure, the fact table resides at the center, surrounded by multiple dimension tables.

Dimension Tables: Providing Context
Dimension tables offer descriptive attributes that qualify and categorize the facts. For instance, a “Product” dimension table might contain columns like ProductID, ProductName, Category, and Brand. A “Time” dimension could include DateKey, DayOfWeek, Month, Quarter, and Year. A “Customer” dimension might have CustomerID, CustomerName, City, and State. These dimensions allow users to slice, dice, and drill down into the data, gaining deeper insights by filtering and grouping the facts based on these attributes.
Fact Tables: The Quantitative Heartbeat
Fact tables, on the other hand, store the actual business events or transactions as numerical measures. These measures are typically additive, meaning they can be summed up across various dimensions. Examples of facts include sales revenue, quantity sold, number of website visits, flight hours, or transaction counts.
A fact table’s structure typically includes:
- Foreign Keys: These columns link the fact table to the primary keys of the associated dimension tables. For example, a fact table for sales might have
ProductID,TimeID, andStoreIDas foreign keys, connecting each sale record to its corresponding product, time, and store dimensions. - Measures: These are the numerical values that represent the business events. They are the raw data that analysts will aggregate, calculate, and visualize.
Types of Fact Tables
The design and content of a fact table can vary significantly depending on the business process it represents and the analytical needs. Understanding these different types is key to building an effective data warehouse.
Transaction Fact Tables
These are the most common type of fact table. Each row in a transaction fact table represents a single business transaction or event.
- Granularity: The lowest level of detail. For example, a sales transaction fact table would have one row per individual item sold within an order.
- Measures: Typically include quantities, prices, and calculated values like revenue.
- Use Cases: Analyzing sales performance, order details, website clicks, or individual service calls.
Example Structure (Sales Transaction Fact Table):
SalesFactKey (Primary Key) |
OrderID |
ProductID (FK) |
TimeID (FK) |
StoreID (FK) |
CustomerID (FK) |
QuantitySold |
UnitPrice |
SalesAmount |
|---|---|---|---|---|---|---|---|---|
| 1001 | 5001 | 201 | 3001 | 4001 | 6001 | 2 | 25.00 | 50.00 |
| 1002 | 5001 | 205 | 3001 | 4001 | 6001 | 1 | 150.00 | 150.00 |
Periodic Snapshot Fact Tables
These fact tables capture the state of a business process at regular intervals. Instead of tracking individual transactions, they record summary information at specific points in time.
- Granularity: Represents a snapshot at a defined period (e.g., daily, weekly, monthly).
- Measures: Reflect the state at that point in time, such as account balances, inventory levels, or customer churn status.
- Use Cases: Tracking financial balances, inventory levels over time, or customer account status.
Example Structure (Monthly Account Balance Fact Table):
SnapshotFactKey (Primary Key) |
AccountID (FK) |
TimeID (FK – representing month-end) |
BalanceAmount |
NumberOfTransactions |
|---|---|---|---|---|
| 2001 | 7001 | 3012 (December 2023) | 15000.50 | 45 |
| 2002 | 7002 | 3012 (December 2023) | 7500.25 | 22 |
Accumulating Snapshot Fact Tables

These tables track the progress of a process that has a defined beginning and end, with a variable number of intermediate steps. Each row represents an instance of a process, and the measures capture the state at different stages.
- Granularity: Represents a single process instance.
- Measures: Include start dates, end dates, and intermediate stage indicators or timestamps.
- Use Cases: Tracking order fulfillment, project lifecycles, or insurance claims processing.
Example Structure (Order Fulfillment Fact Table):
OrderSnapshotKey (Primary Key) |
OrderID (FK) |
OrderDateID (FK) |
ShipDateID (FK) |
DeliveryDateID (FK) |
ReturnDateID (FK) |
OrderStatus |
TotalAmount |
|---|---|---|---|---|---|---|---|
| 3001 | 8001 | 3001 | 3015 | 3020 | NULL | ‘Shipped’ | 250.00 |
| 3002 | 8002 | 3005 | NULL | NULL | 3030 | ‘Returned’ | 75.00 |
Design Considerations for Fact Tables
The effectiveness of a fact table hinges on careful design and adherence to best practices. Several key considerations influence its structure and performance.
Granularity
Choosing the right granularity is paramount. It defines the lowest level of detail represented by a single row in the fact table.
- Sufficient Detail: The granularity must be detailed enough to support all anticipated analytical queries. If a query requires individual transaction-level analysis, the fact table must capture that level of detail.
- Avoid Over-Detailing: Conversely, an overly granular fact table can lead to excessive size, slower query performance, and increased storage costs. Summarizing data prematurely can also limit analytical flexibility.
- Degenerate Dimensions: Sometimes, identifiers from transaction systems (like order numbers or invoice numbers) might not have corresponding dimension tables. These are called degenerate dimensions and are often included directly in the fact table.
Measures
The selection and type of measures are critical for the analytical power of the fact table.
- Additive Measures: These are the most flexible. They can be summed across any dimension. For example,
SalesAmountcan be summed by product, by store, or by time period. - Semi-Additive Measures: These can be summed across some dimensions but not others. Account balances are a prime example – you can sum balances across accounts for a specific month, but summing balances across months for a single account doesn’t usually make business sense.
- Non-Additive Measures: These cannot be summed or averaged meaningfully. Ratios or percentages (e.g., profit margin) often fall into this category. They are best calculated in the presentation layer or through derived measures.
- Factless Fact Tables: These tables don’t contain measures but rather record the occurrence of an event or the absence of an event. They are useful for tracking events like “student attended class” or “product was viewed.”
Foreign Keys
Each fact table row must be associated with at least one, and typically multiple, dimension tables. The foreign keys are the connectors.
- Surrogate Keys: Using surrogate keys (system-generated, meaningless integer keys) for foreign keys in the fact table is a best practice. This decouples the data warehouse from the operational systems and handles changes in dimension keys over time.
- Referential Integrity: Maintaining referential integrity between fact and dimension tables is crucial to ensure data accuracy and consistency.
Fact Table Size and Performance
Fact tables are often the largest tables in a data warehouse. Their size directly impacts query performance and storage requirements.
- Indexing: Proper indexing of foreign keys in the fact table is essential for efficient joins with dimension tables.
- Partitioning: Large fact tables can be partitioned (e.g., by date) to improve query performance and manageability.
- Compression: Employing data compression techniques can significantly reduce storage needs and improve read performance.
- Data Archiving and Purging: Implementing policies for archiving or purging old data that is no longer actively analyzed can help manage table size.
The Role of Fact Tables in Business Intelligence
Fact tables are the bedrock of business intelligence and analytics. They provide the raw material for answering critical business questions, such as:
- What are our top-selling products by region and time period?
- How have our customer acquisition costs changed over the last quarter?
- What is the average flight duration for our drone fleet over the past year?
- Which marketing campaigns have generated the highest return on investment?
By enabling aggregations, calculations, and trend analysis, fact tables empower organizations to:
- Monitor Performance: Track key performance indicators (KPIs) and identify areas of success or concern.
- Identify Trends and Patterns: Uncover underlying patterns in business data to inform strategic decisions.
- Forecast Future Outcomes: Use historical data to predict future performance and plan accordingly.
- Optimize Operations: Identify inefficiencies and opportunities for improvement in business processes.
- Gain Competitive Advantage: Make data-driven decisions that provide a competitive edge.
In conclusion, the fact table is more than just a repository of numbers; it is the quantitative heart of a data warehouse, enabling deep analysis and driving informed business strategy. Its careful design, based on a clear understanding of business processes and analytical needs, is fundamental to unlocking the true value of an organization’s data.