
The Fundamental Role of Diacritics in Digital Communication
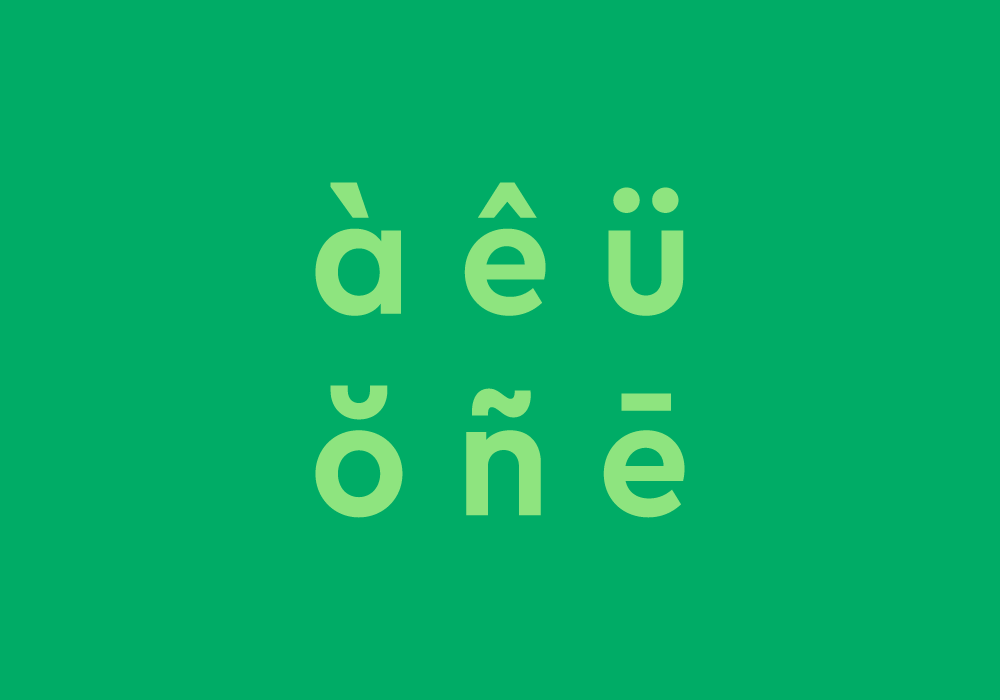
At its core, a diacritic is a mark, sign, or glyph added to a letter to modify its pronunciation, distinguish its meaning, or indicate a special phonetic value. These seemingly small additions carry immense linguistic weight, acting as essential components for accurate representation and comprehension across a vast array of written languages worldwide. Far from mere aesthetic embellishments, diacritics such as acute accents (é), grave accents (à), circumflexes (ê), tildes (ñ), umlauts (ü), cedillas (ç), and macrons (ā) fundamentally shape how words are pronounced, understood, and processed, particularly in the ever-expanding landscape of digital communication.
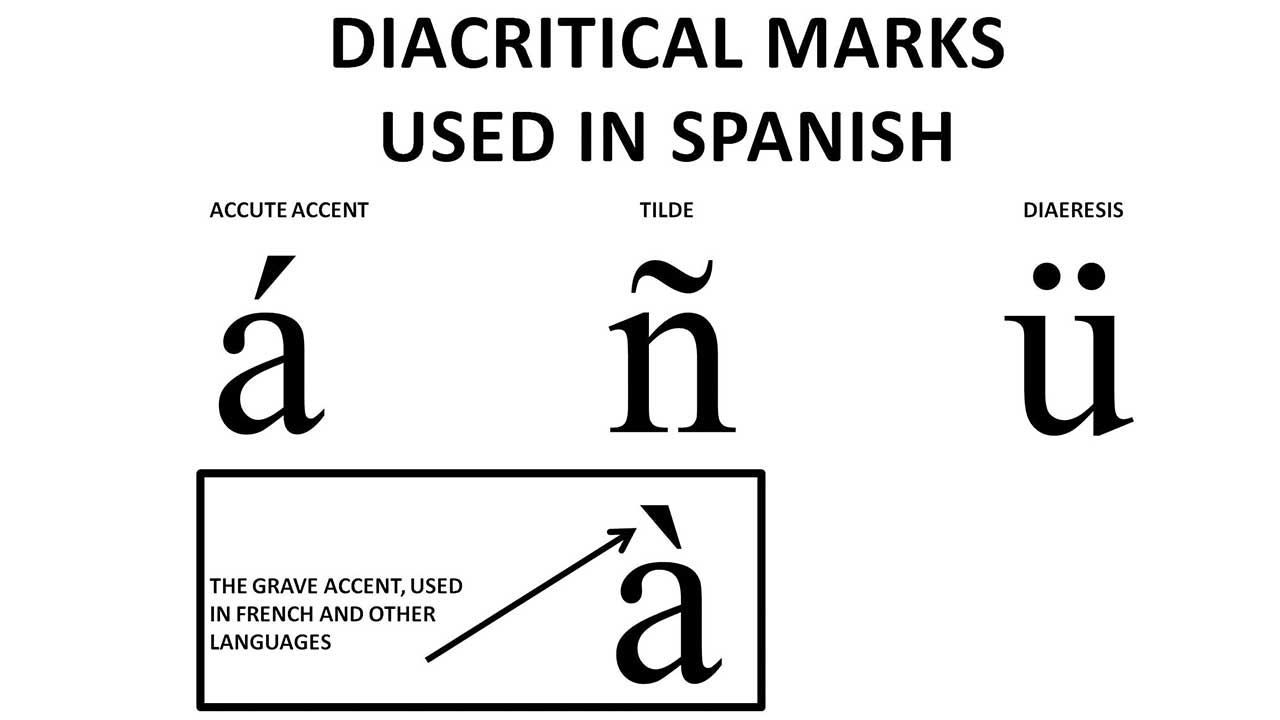
Consider the profound linguistic necessity they fulfill. In French, “cote” (rating), “côte” (coast or rib), and “coté” (quoted) are distinct words with different meanings and often pronunciations, differentiated solely by the diacritic. Similarly, in Spanish, “pena” (sorrow) is starkly different from “peña” (rocky hill or surname). Without the tilde, the nuance is lost, potentially leading to miscommunication or outright confusion. German’s “schon” (already) and “schön” (beautiful) are another prime example, where the umlaut completely alters the word’s sense. These examples underscore that diacritics are not optional extras; they are integral to the identity and intelligibility of countless words.
The impact of diacritics extends far beyond individual word meanings; they are crucial for maintaining phonetic accuracy and grammatical correctness. In Vietnamese, a complex system of six tones is indicated by diacritics, making them indispensable for distinguishing between words that would otherwise be homographs. Portuguese uses diacritics to denote stress, open/closed vowels, and nasalization, all vital for proper pronunciation. Their presence ensures that the written form faithfully reflects the spoken language, facilitating accurate speech synthesis, language learning, and inter-linguistic understanding in a globalized digital environment.
Moreover, diacritics are pivotal in promoting global accessibility and inclusivity in the digital realm. As information traverses borders and languages, the ability to accurately render and process text with diacritics is paramount. It ensures that content is accessible and understandable to native speakers of diverse languages, fostering broader participation and communication. From user interfaces to search engines, and from educational platforms to social media, the correct handling of diacritics is a testament to technological sophistication that respects linguistic diversity and empowers global users. Their absence or incorrect rendering can alienate users, create barriers to information, and erode trust in digital platforms. Thus, understanding “what is a diacritic” is not just a linguistic exercise but a recognition of a critical element in the architecture of modern, global digital communication.
Technical Implementation: Encoding and Character Sets
The journey of diacritics from ink on paper to pixels on a screen is a story deeply intertwined with the evolution of digital encoding and character sets. Early computing faced significant challenges in representing the vast diversity of global scripts and their attendant diacritics, primarily due to the limitations of initial character encoding standards.
The venerable ASCII (American Standard Code for Information Interchange), designed primarily for English, accommodated only 128 characters, leaving no room for the accented letters, tildes, and other marks crucial to most European and non-English languages. This led to a fragmented landscape where different regions developed their own “extended ASCII” variants, such as ISO 8859-x series (e.g., ISO 8859-1 for Western European languages, ISO 8859-2 for Central European). While these addressed specific regional needs by adding characters in the 128-255 range, they were inherently incompatible with each other. A document created with ISO 8859-1 might appear as “mojibake” (garbled text) when viewed with ISO 8859-7 (Greek), making global digital communication a complex and error-prone endeavor. Developers often had to manually manage character sets, leading to encoding declaration issues and display errors that plagued early multilingual software.
The monumental breakthrough came with Unicode. Conceived as a universal character encoding standard, Unicode’s primary goal was to provide a unique number (a “code point”) for every character, no matter the platform, program, or language. This ambition directly addressed the chaotic state of diacritic representation. Unicode offers two primary methods for handling characters with diacritics:
- Precomposed Characters: For many common diacritic-laden letters (e.g., é, ñ, ü), Unicode assigns a single, distinct code point. This is the simplest approach for characters frequently used together.
- Combining Diacritics: For less common combinations or for maximum flexibility, Unicode allows for “combining diacritics.” Here, a base character (e.g., ‘e’) is followed by a non-spacing combining mark (e.g., the acute accent U+0301). The rendering engine then stacks or positions this mark graphically over the preceding base character. This approach is powerful as it can generate virtually any diacritic-modified character without needing an individual code point for every single combination.
The existence of both precomposed and combining forms necessitates the concept of Unicode normalization forms (NFC, NFD, NFKC, NFKD). For instance, ‘é’ can be represented as a single precomposed character (NFC) or as ‘e’ followed by a combining acute accent (NFD). Normalization ensures that these different byte sequences are treated as equivalent when comparing or searching text, which is vital for data consistency and reliable information retrieval.
Unicode’s adoption led to the development of various encoding schemes to represent these code points in bytes:
- UTF-8: The most prevalent encoding on the internet, UTF-8 is a variable-width encoding that uses 1 to 4 bytes per character. It’s backward-compatible with ASCII for English text, making it highly efficient and flexible. Its widespread use has been instrumental in the consistent display of diacritics across websites and applications globally.
- UTF-16: Uses 2 or 4 bytes per character and is commonly employed in Windows operating systems and Java.
- UTF-32: A fixed-width encoding that uses 4 bytes per character, offering simpler processing but consuming more space.
The advantages of Unicode for diacritic handling are profound: it ensures global consistency, cross-platform compatibility, and supports nearly all known written languages, making it the bedrock upon which modern multilingual digital communication is built. Without Unicode, the seamless digital flow of information across diverse linguistic boundaries, heavily reliant on accurate diacritic representation, would be virtually impossible.
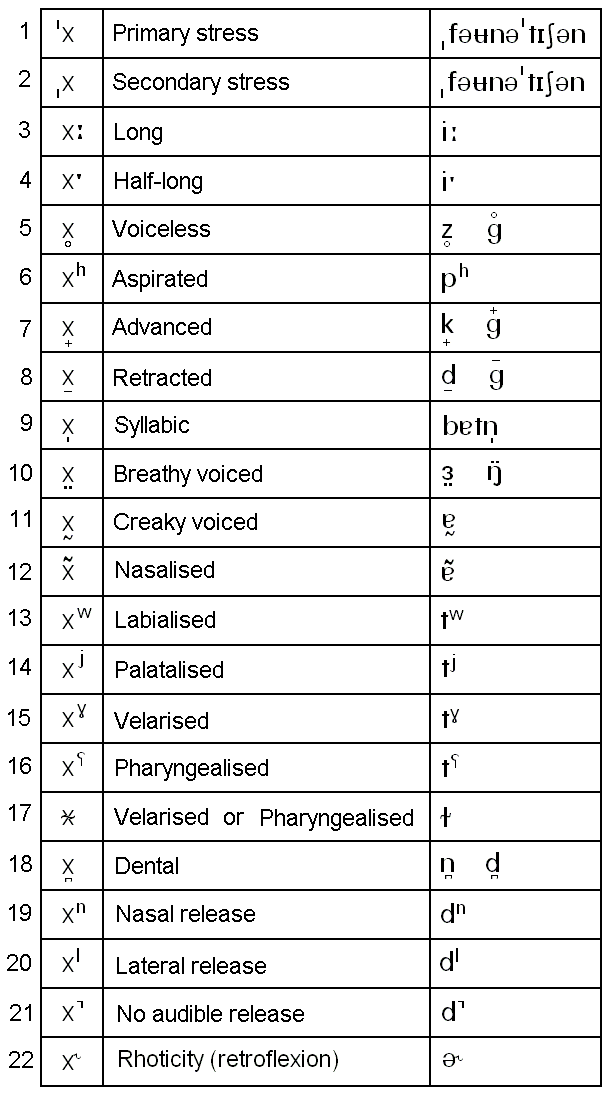
Rendering and Display Challenges in Modern Software
The accurate and aesthetically pleasing rendering of diacritics on digital screens is a complex technical feat, demanding sophisticated collaboration between operating systems, fonts, and application software. Even with the universal foundation of Unicode, the journey from a character’s code point to its visual representation is fraught with potential challenges.
Font support stands as the primary determinant for successful diacritic display. A font must contain the necessary glyphs for both base characters and their corresponding diacritics, or, critically, it must include instructions for correctly positioning combining diacritics. Modern font formats like OpenType and TrueType incorporate advanced features (such. as GSUB/GPOS tables) that define how characters should be positioned relative to each other (kerning) and how combining marks should attach to their base characters, ensuring they are neither too far nor too close, nor overlapping other characters. When a font lacks a specific glyph, a system may resort to a “fallback font,” which can lead to inconsistencies in style, size, or even incorrect rendering if the fallback font also lacks proper diacritic support. This can manifest as boxes, question marks, or generic “tofu” characters, indicating a glyph is missing.
Layout engines within web browsers, word processors, and operating systems play a crucial role in interpreting font data and drawing text on screen. These engines are responsible for tasks beyond simple character display, including:
- Text Shaping: Adjusting character forms and positions based on script-specific rules. For languages with complex scripts or many diacritics, this can involve subtle adjustments to avoid collisions or to ensure diacritics are centered correctly over their base letters.
- Ligatures: Combining certain character sequences (like “fi” or “fl”) into a single glyph for aesthetic appeal, which can sometimes interact with diacritics.
- Kerning and Tracking: Fine-tuning the spacing between individual characters and across entire blocks of text, a process made more intricate when non-spacing diacritics are involved.
- Line Breaking and Justification: Ensuring that lines break correctly without separating a diacritic from its base character, and that text justification doesn’t distort the appearance of accented letters.
Achieving cross-platform consistency is another significant hurdle. A document or webpage perfectly rendered on one operating system (e.g., macOS) might display subtly different or even incorrect diacritics on another (e.g., Windows or Linux), due to variations in their font rendering engines, default fonts, and handling of Unicode normalization. Common rendering glitches include diacritics appearing too high or too low, overlapping with adjacent characters, or even rendering as separate characters instead of combining with their base. Developers must rigorously test their applications across various environments to ensure a consistent and accurate user experience for multilingual content.
Finally, user input methods are the gateway for creating text with diacritics. Keyboard layouts are often localized to include common diacritics for a given language. “Dead keys” allow users to press a diacritic key (e.g., the accent mark) and then a base letter (e.g., ‘e’) to combine them into a single character (e.g., ‘é’). Software keyboards, character maps, and input method editors (IMEs) for complex scripts provide alternative means for users to enter diacritic-rich text. The design of these input systems is critical for user experience, making the creation of linguistically accurate digital content both efficient and accessible. The sophisticated interplay of these technical components ensures that the rich tapestry of global languages, with their intricate diacritical marks, can be faithfully presented in the digital world.
Diacritics in Data Processing and Information Retrieval
Beyond their visual representation, diacritics pose unique and significant challenges in the backend processes of data management, search, and analysis. The way diacritics are handled at this level can dramatically impact the efficiency and accuracy of information retrieval, natural language processing, and even data security.
One of the foremost challenges lies in normalization within databases. When users search for information, they may or may not include diacritics. For instance, a search for “résumé” should ideally yield results for “resume,” and vice versa. This requires databases and search engines to implement some form of “accent folding” or “diacritic stripping,” where diacritics are removed or converted to their base characters for the purpose of comparison or sorting. However, this process must be carefully managed to avoid unintended loss of linguistic distinction. For example, if “rose” and “rosé” are considered identical in a wine database search, it could lead to inaccurate results. The choice between case-sensitive/insensitive and accent-sensitive/insensitive comparisons is a fundamental design decision for any multilingual data system, often requiring configurable settings to balance strict accuracy with user-friendly search behavior.
Search Engine Optimization (SEO) is profoundly affected by diacritic handling. Websites targeting multilingual audiences must consider how search engines index and match queries containing diacritics. If a search engine treats “piñata” and “pinata” as distinct terms, a website optimized only for one might miss traffic from users searching for the other. Modern search engines are increasingly sophisticated in handling these linguistic nuances, often performing internal normalization to match variations. However, content creators still need to strategize on whether to primarily use diacritics in their content, provide both forms, or rely on search engine intelligence, particularly for terms where the diacritic significantly alters spelling or meaning.
In the realm of Natural Language Processing (NLP), diacritics are not just superficial marks but crucial data points. For tasks like tokenization (breaking text into words), stemming (reducing words to their root form), and lemmatization (grouping together different inflected forms of a word), the presence or absence of diacritics can fundamentally alter the outcome. For instance, a stemmer might treat “côte” and “cote” as having different stems if diacritics are not handled, leading to inaccuracies in sentiment analysis or topic modeling. In machine translation, the precise representation of diacritics is paramount for generating grammatically correct and semantically accurate translations. An incorrectly transcribed diacritic can lead to a completely different word or grammatical structure in the target language.
Finally, diacritics introduce fascinating and sometimes concerning aspects in security implications. The concept of homoglyph attacks leverages characters that look visually similar but have different Unicode code points, often involving diacritics or characters from different scripts. For example, an ‘a’ with a diacritic from one script might look identical to a standard English ‘a’ but has a different underlying digital identity. Malicious actors can use these visually deceptive characters to create spoofed domain names (e.g., “pàypal.com” looking like “paypal.com”) in phishing schemes, tricking users into believing they are on a legitimate site. Defending against such attacks requires robust text normalization, careful validation of input, and sophisticated character analysis to identify and flag suspicious patterns.
In summary, the technical handling of diacritics extends far beyond display; it is a critical consideration in how data is stored, searched, processed, and secured in a globally interconnected digital world, directly influencing the accuracy, efficiency, and safety of information systems.