
In the dynamic landscape of technology and innovation, where data serves as the lifeblood of progress, the ability to efficiently query and analyze vast datasets is paramount. From refining autonomous flight algorithms with sensor telemetry to optimizing AI models with segmented remote sensing data, the precision of data retrieval directly impacts the efficacy of groundbreaking applications. Within this crucial domain, SQL (Structured Query Language) remains an indispensable tool, and one of its most powerful features for complex data manipulation is the nested query, often referred to as a subquery.
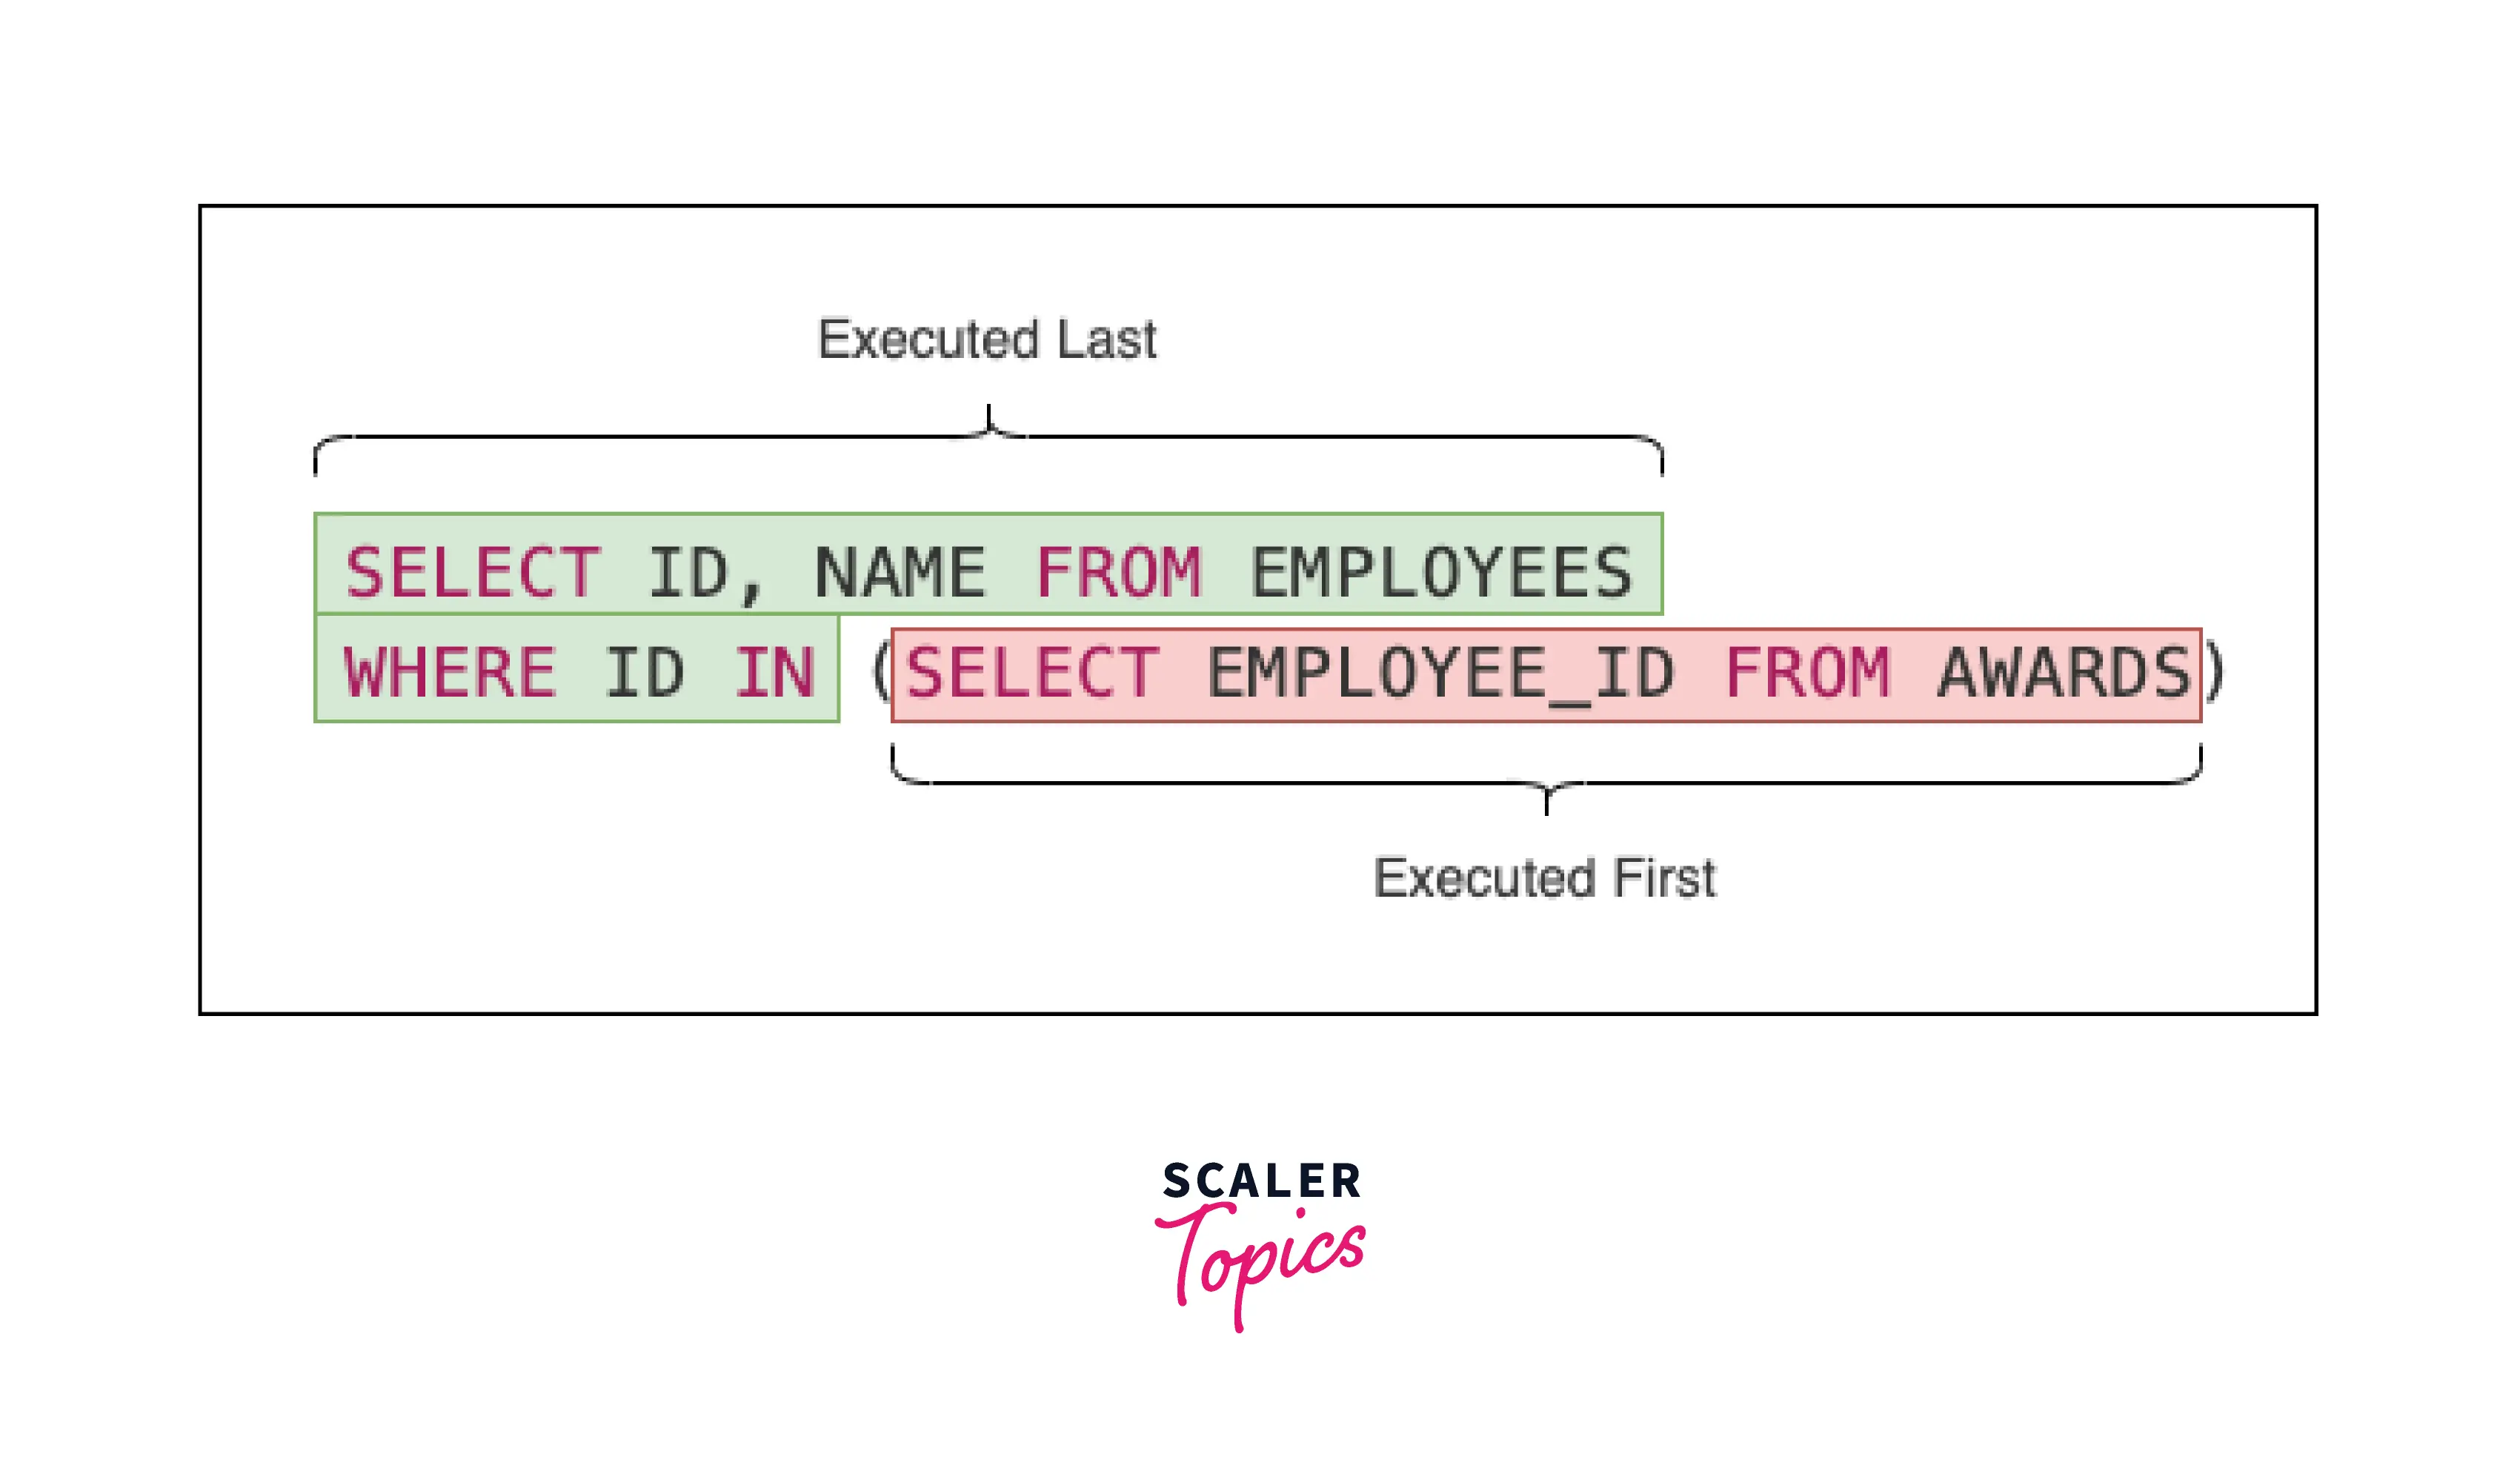
A nested query is essentially a query embedded within another SQL query. This inner query executes first, and its result set is then used by the outer query to filter or retrieve data. This hierarchical structure allows for highly granular and conditional data retrieval that would be challenging or impossible to achieve with a single, standalone query. It enables developers and data scientists to break down complex data problems into smaller, more manageable parts, making the logic clearer and the execution more robust in innovative tech environments.
Unpacking the Core Concept of Nested Queries
At its heart, a nested query provides a mechanism to use the output of one SELECT statement as an input to another SELECT, INSERT, UPDATE, or DELETE statement. The inner query, or subquery, typically runs once and returns a result that the outer query then processes. This makes nested queries incredibly versatile for scenarios where you need to perform an operation based on a condition derived from another table or a calculated value.
Basic Structure and Execution Flow
The fundamental syntax for a nested query involves placing a SELECT statement within parentheses, usually in the WHERE clause, FROM clause, or SELECT clause of the outer query.
Consider a scenario in autonomous navigation data:
Imagine you have a table SensorReadings with sensor_id, timestamp, value, and a table CriticalSensors with sensor_id, threshold. You want to find all SensorReadings that exceed their threshold for a sensor identified as Critical.
SELECT timestamp, value
FROM SensorReadings
WHERE sensor_id IN (SELECT sensor_id FROM CriticalSensors WHERE threshold > 100);
In this example:
- The inner query
(SELECT sensor_id FROM CriticalSensors WHERE threshold > 100)executes first. It identifies allsensor_ids from theCriticalSensorstable where thethresholdis greater than 100. - The outer query then uses this list of
sensor_ids to retrievetimestampandvaluefromSensorReadings, effectively filtering for readings from those specific critical sensors.
This sequential execution ensures that the outer query always has a defined input to work with, allowing for sophisticated data filtering and transformation.
Diverse Types and Advanced Applications in Tech
Nested queries are not monolithic; they manifest in several forms, each suited for distinct analytical challenges prevalent in cutting-edge technology. Understanding these variations unlocks their full potential for data management in fields like AI, IoT, and advanced robotics.
Scalar Subqueries
A scalar subquery returns a single value (one row, one column). It can be used anywhere a single expression or value is expected, such as in the SELECT list, WHERE clause, or HAVING clause.
Application Example (AI Model Optimization): Suppose you are optimizing an AI model for object recognition from drone imagery. You want to retrieve images taken at a specific average altitude for a region.
SELECT image_id, capture_time, altitude
FROM DroneImagery
WHERE altitude > (SELECT AVG(altitude) FROM DroneImagery WHERE region = 'Urban_Dense');
Here, the inner query calculates the average altitude for images in ‘Urban_Dense’, and the outer query then filters images exceeding this specific average.
Single-Row Subqueries
Similar to scalar subqueries, single-row subqueries return exactly one row but can return multiple columns. They are typically used with single-row comparison operators (=, >, <, >=, <=, <>).
Application Example (Autonomous System Anomaly Detection): To identify a specific flight anomaly where a drone’s power consumption exceeded the average power consumption for its model on a particular mission.
SELECT flight_id, power_consumption, mission_duration
FROM FlightLogs
WHERE (model_id, mission_id) = (SELECT model_id, mission_id FROM DroneFleet WHERE drone_status = 'In_Service' AND last_mission_success = 'N')
AND power_consumption > (SELECT AVG(power_consumption) FROM FlightLogs WHERE model_id = 'XYZ_DRONE');
This multi-column, single-row subquery helps pinpoint problematic drone missions.
Multi-Row Subqueries
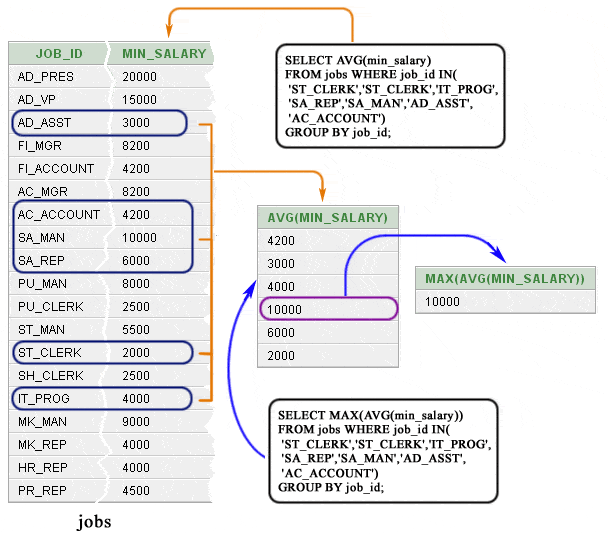
Multi-row subqueries return one or more rows, each potentially with one or more columns. These are commonly used with multi-row comparison operators like IN, NOT IN, ANY, ALL, and EXISTS.
IN and NOT IN Operators
These are used to check if a value is among a set of values returned by the subquery.
Application Example (Remote Sensing Data Analysis): Identifying all satellite images that contain specific types of environmental anomalies detected by other systems.
SELECT image_id, capture_date, anomaly_type
FROM SatelliteImagery
WHERE anomaly_type IN (SELECT distinct anomaly_code FROM EnvironmentalAlerts WHERE severity = 'High');
This efficiently filters images based on a list of high-severity anomaly codes.
ANY and ALL Operators
ANY (or SOME) means the condition is true if it is true for any of the values in the subquery’s result set. ALL means the condition is true if it is true for all values in the subquery’s result set.
Application Example (Robotics Fleet Management): Finding robots whose current battery level is lower than any of the minimum thresholds for critical missions.
SELECT robot_id, battery_level
FROM RobotStatus
WHERE battery_level < ANY (SELECT min_threshold FROM MissionRequirements WHERE mission_type = 'Critical');
Correlated Subqueries
Unlike other subqueries that execute independently and pass their results once to the outer query, a correlated subquery depends on the outer query. It executes once for each row processed by the outer query. This makes them powerful for row-by-row comparisons but can impact performance on very large datasets.
Application Example (IoT Device Monitoring): Identifying IoT sensors whose latest reading is higher than their own historical average.
SELECT s1.sensor_id, s1.reading_value, s1.timestamp
FROM SensorData s1
WHERE s1.reading_value > (SELECT AVG(s2.reading_value)
                          FROM SensorData s2
                          WHERE s2.sensor_id = s1.sensor_id);
Here, for each row in SensorData s1, the inner query calculates the average reading specifically for that sensor’s sensor_id, making the subquery ‘correlated’ to s1.
Optimizing Performance and Best Practices
While incredibly powerful, the indiscriminate use of nested queries can sometimes lead to performance bottlenecks, especially in high-throughput, innovative systems handling massive data volumes.
When to Employ Nested Queries
- Complex Filtering: When filtering criteria depend on values derived from other tables or aggregated results.
- Data Validation: To ensure data integrity, for example, by checking if an entry exists in another table before insertion.
- Reporting and Analytics: For generating intricate reports, like ranking items or calculating cumulative sums based on conditions.
- Ad-hoc Queries: Often ideal for quick, complex analyses without needing to create temporary tables.
Performance Considerations
- Correlated Subqueries: These are generally the slowest type because they execute for every row of the outer query. In many cases, a
JOINoperation can achieve the same result with better performance. - Indexing: Ensure that columns used in
WHEREclauses of both inner and outer queries, especially those involved inJOINconditions or subquery comparisons, are properly indexed. - Avoid Redundancy: Design queries to prevent recalculating the same subquery result multiple times if it’s not a correlated subquery.
EXISTSvs.IN: For checking the existence of rows,EXISTSis often more efficient thanINwhen the subquery returns a large number of rows, asEXISTSstops processing as soon as it finds a match.
Alternative Approaches: JOINs and CTEs
Often, the same logic can be achieved using JOIN operations or Common Table Expressions (CTEs).
JOINOperations: For many multi-row subqueries, especially those usingINorEXISTSto connect tables,JOINs (e.g.,INNER JOIN,LEFT JOIN) can offer superior performance by allowing the database optimizer more flexibility in execution plans.- CTEs (WITH Clause): CTEs provide a way to define a temporary, named result set that you can reference within a single
SELECT,INSERT,UPDATE, orDELETEstatement. They enhance readability and modularity, making complex queries easier to understand and debug, particularly useful in intricate data pipelines for advanced analytics.
-- Example using CTE instead of nested query for clarity
WITH AvgAltitude AS (
    SELECT AVG(altitude) as avg_alt
    FROM DroneImagery
    WHERE region = 'Urban_Dense'
)
SELECT image_id, capture_time, altitude
FROM DroneImagery, AvgAltitude
WHERE altitude > AvgAltitude.avg_alt;

The Future Role of Nested Queries in Data-Driven Innovation
As data volumes continue their exponential growth, driven by sensors, AI, and autonomous systems, the ability to extract meaningful insights quickly and accurately becomes even more critical. Nested queries, alongside other advanced SQL features, will remain a cornerstone for data manipulation, particularly in scenarios requiring nuanced, context-dependent data filtering.
In the realm of predictive maintenance for industrial IoT, nested queries can help identify machinery operating outside a specific performance envelope that is itself derived from historical aggregates. For real-time geospatial analytics, they can quickly pinpoint drones that have deviated from approved flight corridors defined by complex geographical boundaries. When training deep learning models, nested queries can segment and retrieve specific subsets of data based on intricate metadata criteria, ensuring the model is fed relevant and high-quality information.
Understanding and mastering nested queries is not merely about writing SQL; it’s about enabling a deeper, more sophisticated interaction with the data that powers the next generation of technological breakthroughs. They are a testament to SQL’s enduring relevance as a vital tool for innovators across every tech-driven industry.