
Automatic Speech Recognition (ASR), often simply referred to as speech-to-text, is a revolutionary field within artificial intelligence that enables computers to interpret human speech and convert it into a written format. Far more complex than mere voice recording, ASR systems delve into the intricate nuances of sound, language, and context to provide actionable data from spoken input. This technology forms a cornerstone of modern innovation, bridging the gap between human communication and digital systems, and profoundly impacting how we interact with technology across countless applications, from personal assistants to sophisticated control systems.
The Foundational Principles of ASR
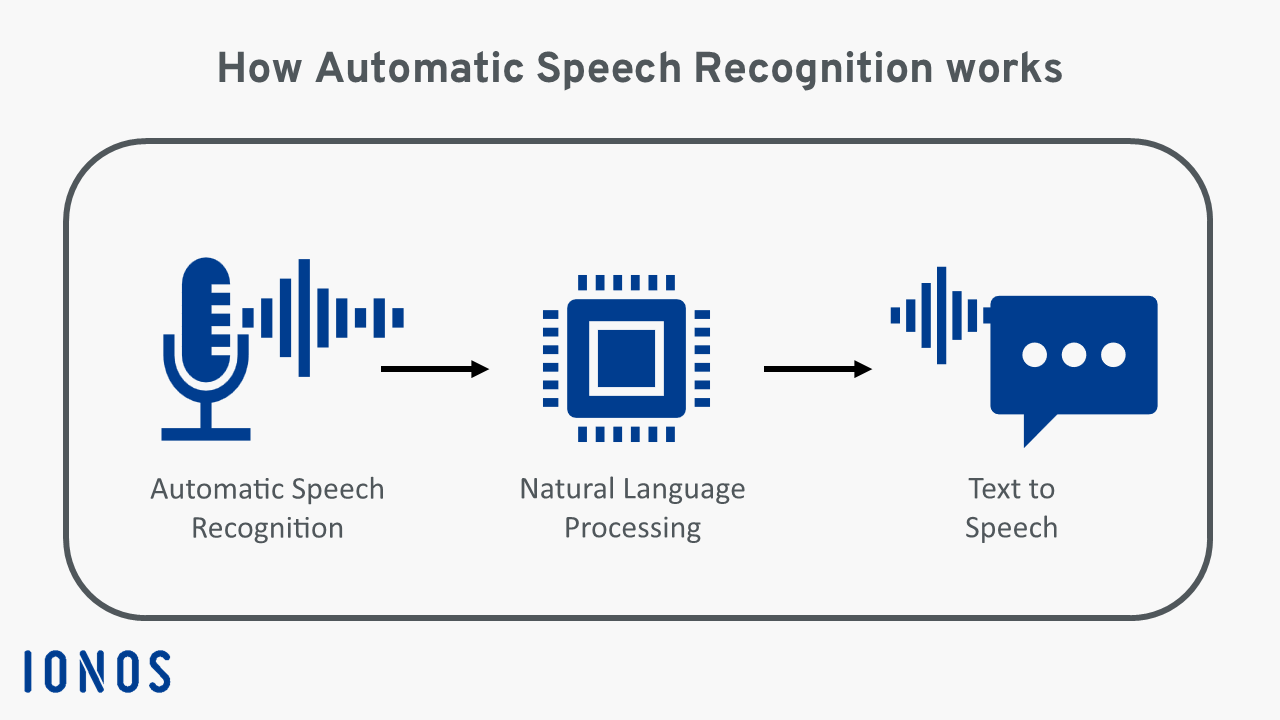
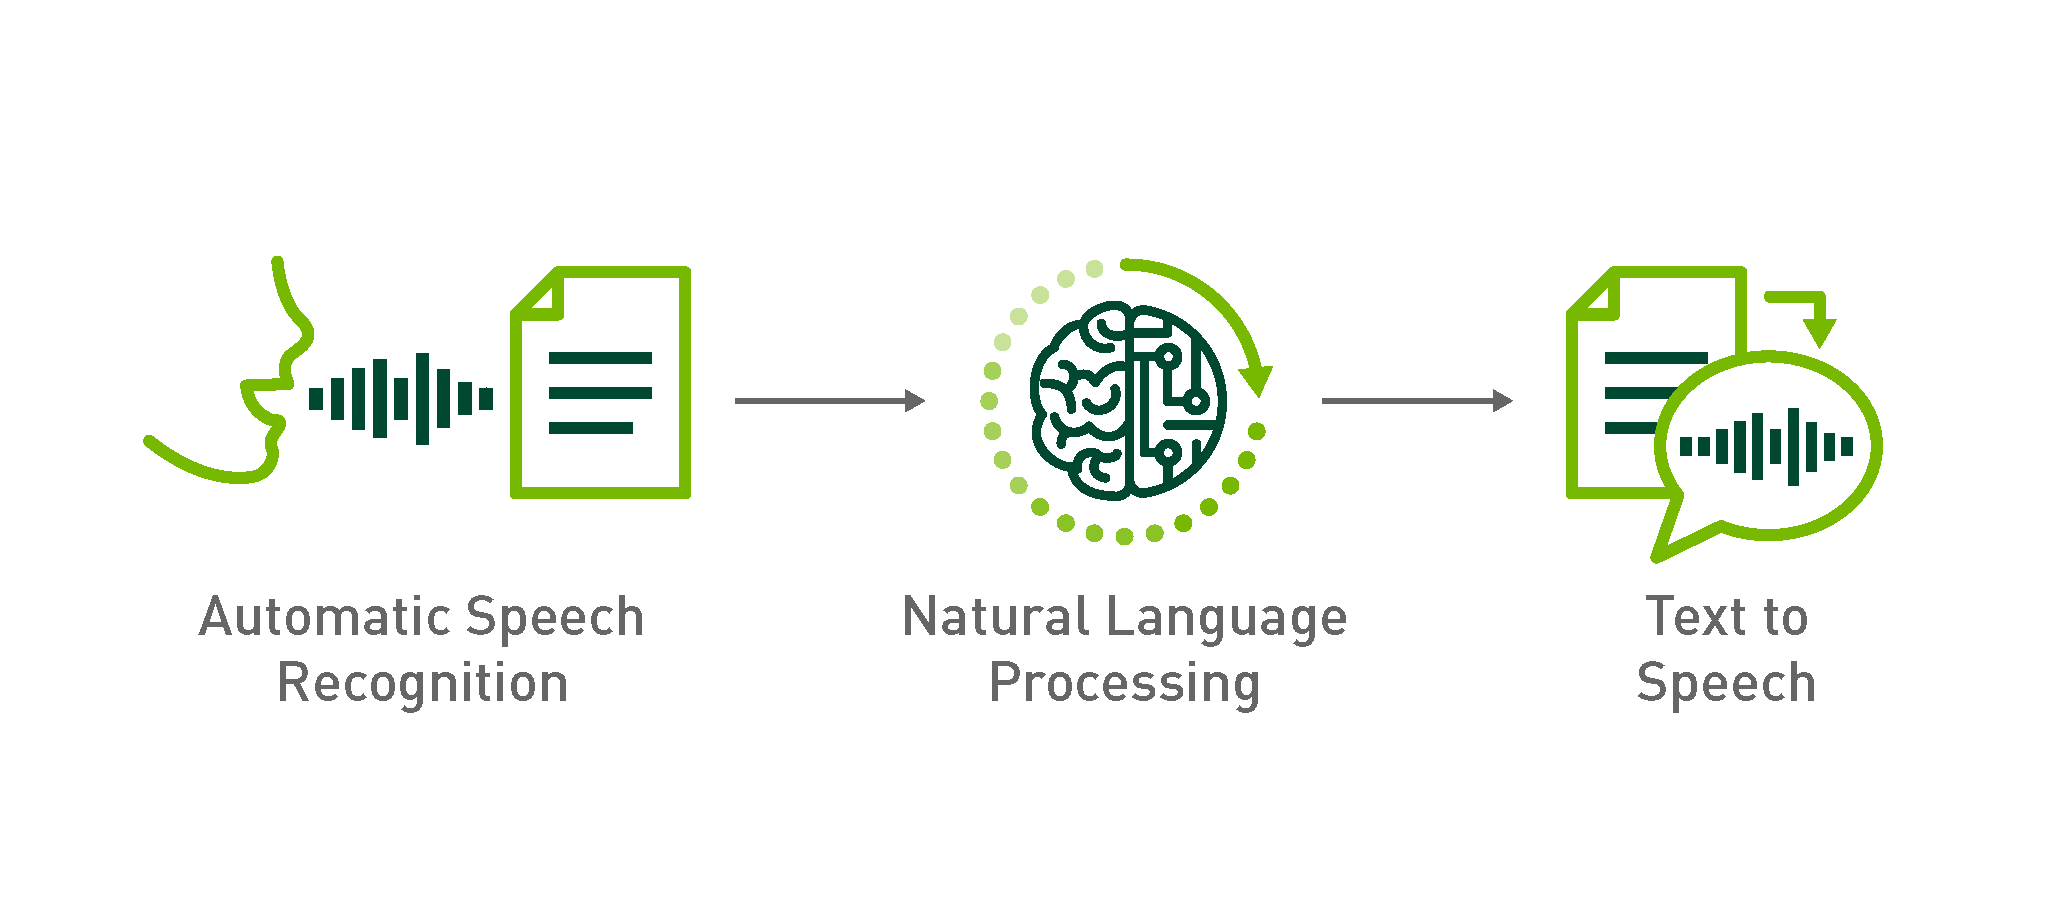
At its core, ASR is a multi-layered computational process that transforms raw audio signals into decipherable text. This transformation is not instantaneous or simple; it involves a sophisticated sequence of steps, each relying on advanced algorithms and vast datasets.
From Sound Waves to Digital Signals
The initial step in any ASR system involves capturing spoken words as analog sound waves and converting them into a digital format. Microphones record the pressure variations in the air caused by speech. These analog signals are then sampled at regular intervals and quantized, converting continuous waves into discrete numerical data points. This digital representation, often in the form of a waveform, is then pre-processed. This pre-processing typically includes noise reduction filters to isolate the human voice from background disturbances and normalization to standardize volume levels. Crucially, the audio signal is broken down into small, overlapping frames, usually lasting mere milliseconds. For each frame, a set of features is extracted, such as Mel-Frequency Cepstral Coefficients (MFCCs), which represent the spectral characteristics of the sound in a way that mimics human hearing perception. These features effectively capture the unique sonic fingerprint of different speech sounds, forming the raw input for the subsequent stages.
Acoustic Models: The Sound-to-Phoneme Link
Once the audio features are extracted, the ASR system employs acoustic models. These models are essentially statistical representations that map specific sound characteristics (the extracted features) to phonemes—the smallest units of sound that distinguish one word from another in a given language. For instance, the ‘k’ sound in ‘cat’ is a phoneme. Historically, Hidden Markov Models (HMMs) were dominant in this phase, capable of modeling the temporal variations in speech. HMMs represent phonemes as a sequence of states, allowing for the variability in how a phoneme might be pronounced over time. Modern ASR systems, however, predominantly leverage deep neural networks (DNNs), particularly recurrent neural networks (RNNs) and convolutional neural networks (CNNs), which have proven vastly more effective at discerning subtle acoustic patterns. These neural networks are trained on massive datasets of transcribed speech, learning to associate millions of audio snippets with their corresponding phonemes and words, even accounting for different pronunciations, accents, and speaking styles.
Language Models: Understanding Context
While acoustic models handle the sound-to-phoneme mapping, they alone cannot reliably convert speech into accurate text. Many phoneme sequences could correspond to multiple words or phrases. This is where language models come into play. A language model predicts the likelihood of a sequence of words occurring in a given language. It uses statistical probability to determine the most probable word sequence given the acoustic output. For example, if an acoustic model produces a sequence of phonemes that could translate to “recognize speech” or “wreck a nice beach,” a language model, trained on vast textual corpora, would overwhelmingly favor “recognize speech” because it’s a far more common and grammatically coherent phrase in the context of technology. Early language models relied on N-grams, which predict the next word based on the previous N-1 words. Contemporary ASR systems have migrated to sophisticated neural network-based language models, such as transformers, which can capture long-range dependencies and more complex syntactic and semantic relationships within sentences, leading to significantly improved accuracy and contextual understanding.
The Role of Neural Networks and Deep Learning
The dramatic advancements in ASR over the past decade are largely attributable to the rise of deep learning. Neural networks, particularly deep neural networks (DNNs), have revolutionized every stage of the ASR pipeline. They replaced or augmented traditional statistical methods like Gaussian Mixture Models (GMMs) for acoustic modeling and significantly enhanced language modeling capabilities. End-to-end deep learning models have emerged, which can directly map audio inputs to character or word sequences without explicitly defining intermediate steps like phoneme recognition. These models, often comprising many layers, learn hierarchical representations of speech, from raw audio features to high-level semantic information. Architectures like Long Short-Term Memory (LSTM) networks and Transformer networks are particularly effective at processing sequential data like speech, allowing systems to remember information over long periods and weigh the importance of different parts of an input sequence, crucial for understanding natural spoken language.
The Evolution and Modern Capabilities of ASR
The journey of ASR has been one of continuous innovation, marked by significant breakthroughs that have transformed it from a research curiosity into an indispensable technology.
Early Iterations and Limitations
The conceptual foundations of ASR date back to the 1950s with early experiments like the “Audrey” system at Bell Labs, which could recognize digits spoken by a single user. Progress was slow for decades, primarily due to limited computational power and the rudimentary nature of available algorithms. Early systems were typically speaker-dependent, requiring users to “train” the system to their voice, and had minuscule vocabularies, often restricted to a few dozen words. They were also highly sensitive to background noise and variations in pronunciation, making them impractical for widespread use outside of highly controlled environments. The focus was largely on discrete word recognition rather than continuous speech, where words flow into one another without pauses.
Breakthroughs with Statistical and Neural Approaches
The 1980s and 90s saw significant advancements with the adoption of statistical methods like Hidden Markov Models (HMMs) and the use of large speech corpora for training. This allowed for the development of speaker-independent systems and the ability to handle continuous speech with larger vocabularies. However, a true paradigm shift occurred in the 2000s and 2010s with the advent of deep learning. The application of deep neural networks to acoustic modeling, combined with increased computational power (especially GPUs) and vast amounts of training data, led to dramatic reductions in word error rates (WER). This marked the transition from ASR being a niche technology to a mainstream capability, improving accuracy by orders of magnitude and enabling robust performance in varied conditions.
Real-time Processing and Enhanced Accuracy
Modern ASR systems are characterized by their ability to process speech in real-time with remarkable accuracy, often rivaling or even surpassing human transcription in ideal conditions. These systems can handle vast vocabularies, recognize different accents, and adapt to varying speaking speeds. The integration of advanced noise cancellation techniques and sophisticated context awareness through powerful language models means they perform reliably even in moderately noisy environments. This real-time capability is critical for interactive applications such as virtual assistants, voice control systems, and live transcription services, where immediate feedback is essential. The continuous learning capabilities, often leveraging federated learning or model updates, allow these systems to improve over time as they encounter more diverse speech patterns and linguistic contexts.
Multilingual and Speaker-Independent Systems
Contemporary ASR technology has transcended linguistic barriers. Many leading ASR engines now support dozens, if not hundreds, of languages and dialects, making them globally applicable. This multilingual capability is vital for international innovation and communication. Furthermore, the concept of speaker independence, once a major challenge, is now a standard feature. Modern systems can accurately transcribe speech from virtually any speaker, regardless of their voice characteristics, without prior training. This is achieved through training on incredibly diverse datasets that encompass a wide range of voices, ages, genders, and speaking styles, allowing the models to generalize effectively.
ASR’s Impact on Tech & Innovation
ASR is not just a technology; it’s an enabler that is profoundly shaping the landscape of technological innovation by making human-computer interaction more natural, efficient, and accessible.
Enabling Hands-Free Interaction in Complex Systems
One of the most significant impacts of ASR is its ability to facilitate hands-free control, which is crucial for complex or safety-critical operations where manual input is impractical or dangerous. In environments ranging from industrial control rooms to advanced vehicle cockpits and specialized field equipment, voice commands allow operators to manage systems while keeping their hands and eyes focused on primary tasks. This enhances operational efficiency, reduces cognitive load, and improves safety by minimizing distractions and the need to switch between physical controls. For instance, in augmented reality interfaces or while operating intricate machinery, voice commands can manipulate digital overlays or control functions without requiring touch or gestures, streamlining workflows and enabling new paradigms of interaction.
Enhancing Autonomous Systems and AI
ASR is a vital component in the evolution of autonomous systems and the broader field of artificial intelligence. By allowing humans to communicate directly with AI agents using natural language, ASR makes autonomous platforms more intuitive and responsive. This capability extends to systems that leverage AI follow modes, where spoken commands can dictate parameters, change objectives, or provide real-time instructions. Similarly, in autonomous navigation and mapping, ASR can allow operators to verbally specify points of interest, delineate search areas, or update mission parameters on the fly, transforming complex interfaces into simple conversational exchanges. It empowers AI to understand human intent more directly, fostering more seamless collaboration between human and machine intelligence.
Revolutionizing Data Input and Control
Beyond direct interaction, ASR is revolutionizing how data is input into systems and how various devices are controlled. Traditional data entry methods can be slow and cumbersome, but speech-to-text allows for rapid transcription of thoughts, observations, or reports. This is particularly valuable in fields like remote sensing, where field agents can verbally log data points or provide situational updates without needing to divert attention to typing. In smart environments, ASR enables ubiquitous control, allowing users to manage lighting, environmental systems, or networked devices through simple voice commands. This ubiquitous, natural input method streamlines processes, accelerates information capture, and integrates technology more seamlessly into daily routines and specialized operations.
Personalization and Adaptive Technologies
ASR plays a key role in developing more personalized and adaptive technologies. By understanding individual speech patterns, preferences, and even emotional nuances conveyed through voice, ASR systems can contribute to more intelligent and responsive user experiences. This includes adaptive interfaces that learn a user’s vocabulary and speaking style, personalized recommendations based on spoken queries, and even systems that adjust their behavior or output based on detected emotional states. As ASR integrates with other AI capabilities, it drives the creation of highly individualized technological ecosystems that anticipate user needs and respond with tailored interactions, moving beyond generic responses to truly intelligent assistance.
Challenges and Future Directions in ASR
Despite its impressive progress, ASR continues to face challenges that researchers are actively addressing, paving the way for even more sophisticated and ubiquitous applications.
Overcoming Environmental Noise and Accent Variability
One of the persistent challenges for ASR systems is robust performance in diverse and noisy acoustic environments. While advancements in noise reduction have been made, accurately transcribing speech amidst loud background chatter, vehicle noise, or sudden disturbances remains a hurdle, especially for sensitive applications. Similarly, handling extreme variability in accents, dialects, and speaking styles globally, including non-native speakers, continues to be an area of active research. Future systems will need to employ even more advanced signal processing, adaptive learning algorithms, and deep generative models to filter noise and seamlessly adapt to virtually any spoken input, irrespective of its acoustic context or speaker characteristics.
Addressing Privacy and Security Concerns
As ASR becomes more integrated into personal and critical systems, privacy and security concerns become paramount. The processing of voice data, which can carry unique biometric identifiers and highly personal information, raises questions about data storage, transmission, and potential misuse. Future ASR development will heavily focus on robust encryption, on-device processing to minimize data transfer, and privacy-preserving AI techniques like federated learning and differential privacy. Ensuring that voice data is handled securely and transparently, with explicit user consent and control, will be crucial for maintaining public trust and widespread adoption.
Towards More Natural and Context-Aware Understanding
While current ASR systems are adept at converting speech to text, true natural language understanding (NLU) – grasping the full meaning, intent, and subtle nuances of human conversation – remains an active frontier. Future ASR will move beyond literal transcription to deeply integrate with NLU capabilities, enabling systems to understand sarcasm, implied meanings, emotional states, and complex conversational context over extended dialogues. This will lead to more genuinely intelligent virtual assistants, conversational AI, and human-robot interactions that feel intuitive and natural, mirroring human-to-human communication more closely. This involves combining ASR with advanced semantic parsing, commonsense reasoning, and multimodal understanding, where speech is interpreted alongside visual cues or other sensor data.

Integration with Augmented and Virtual Realities
The future of ASR is also inextricably linked with the burgeoning fields of Augmented Reality (AR) and Virtual Reality (VR). As AR/VR headsets become more commonplace, voice interaction will be a primary means of control and communication within these immersive environments, replacing clunky physical controllers. ASR will enable users to naturally navigate virtual worlds, manipulate digital objects, and interact with virtual characters or information overlays through spoken commands. This integration demands highly responsive, low-latency ASR that can operate seamlessly within dynamic 3D spaces, understanding context from the virtual environment itself. It will unlock new possibilities for productivity, entertainment, and training, making AR/VR experiences far more intuitive and engaging.