
In the vast landscape of data-driven innovation, understanding how to efficiently process and extract meaning from textual information is paramount. From autonomous systems sifting through operational logs to advanced mapping solutions interpreting vast amounts of descriptive metadata, the ability to identify key concepts within a sea of words dictates efficiency and accuracy. One foundational technique that has stood the test of time in this domain is TF-IDF, an acronym for Term Frequency-Inverse Document Frequency. More than just a simple algorithm, TF-IDF provides a statistical measure to evaluate the importance of a word in a document relative to a collection of documents (a corpus). It’s a sophisticated method for scoring the relevance of words, enabling intelligent systems to prioritize and interpret information much like a human expert would, but at a computational scale.
The Core Concept: Quantifying Word Importance
At its heart, TF-IDF operates on a remarkably intuitive principle: a word’s importance increases proportionally to how often it appears in a document, but is offset by how frequently it appears across all documents. This dual perspective ensures that common, less informative words (like “the” or “is”) are downplayed, while unique and contextually significant terms are highlighted.
Term Frequency (TF): Local Significance
Term Frequency (TF) is the first component of the TF-IDF calculation and is relatively straightforward. It measures how frequently a term (or word) appears in a specific document. The logic is simple: if a word appears many times in a document, it’s likely that the word is important to the subject matter of that document.
There are several ways to calculate TF:
- Raw Count: The simplest method is to just count the number of times a term appears in a document.
- Boolean Frequency: Assign a 1 if the term appears, 0 otherwise. Less common for nuanced applications.
- Log-Normalized Frequency:
log(1 + raw_count)to smooth out the impact of very high frequencies. - Augmented Frequency:
0.5 + 0.5 * (raw_count / max_frequency_in_document)to prevent bias towards longer documents.
For example, if a report on drone battery life mentions the word “lithium” 15 times, its raw term frequency for “lithium” would be 15. This raw count, however, only tells part of the story; a 10,000-word document mentioning “lithium” 15 times is different from a 100-word document doing the same. Normalized or augmented frequencies often mitigate this length bias, providing a more reliable measure of a word’s importance within that specific document.
Inverse Document Frequency (IDF): Global Rarity
While Term Frequency captures the local importance of a word within a single document, it doesn’t account for the word’s general prevalence across an entire collection of documents. This is where Inverse Document Frequency (IDF) comes into play. IDF is designed to diminish the weight of terms that appear very frequently across many documents and, conversely, to increase the weight of terms that are rare.
The formula for IDF is typically calculated as: log(Total Number of Documents / Number of Documents containing the Term).
- Total Number of Documents (N): The total count of all documents in the corpus.
- Number of Documents containing the Term (df_t): The count of documents where the specific term ‘t’ appears at least once.
The logarithm is used to dampen the effect of the ratio, preventing very rare words from having excessively high IDF values. A small constant (usually 1) is often added to the denominator (1 + df_t) to avoid division by zero if a term doesn’t appear in any document.
Consider the word “drone.” It might appear in nearly every document within a corpus focused on drone technology. Its IDF value would therefore be low, as it’s not a distinguishing term. However, a term like “LiDAR sensor calibration” might appear in only a few highly specialized reports. Its IDF value would be significantly higher, indicating its unique relevance to those specific documents. By combining TF and IDF, TF-IDF effectively filters out common noise and highlights truly significant keywords.
Why TF-IDF Matters in Tech & Innovation
TF-IDF is more than a theoretical construct; it is a workhorse in numerous practical applications within modern tech and innovation ecosystems. Its ability to quantify the relevance of words makes it indispensable for systems that need to understand, organize, and retrieve textual information efficiently.
Enhanced Information Retrieval and Search
Perhaps the most direct and historically significant application of TF-IDF is in information retrieval. Search engines, both general-purpose and specialized internal systems, heavily rely on variations of TF-IDF. When you type a query, the system calculates the TF-IDF score for each term in your query against the content of millions of documents. Documents with higher aggregate TF-IDF scores for your query terms are considered more relevant and are ranked higher in search results. For specialized databases in remote sensing, drone component inventories, or regulatory compliance documents, TF-IDF allows users to quickly find the most pertinent information amidst vast archives. This is crucial for rapid decision-making and operational efficiency in complex technical fields.
Content Summarization and Keyword Extraction
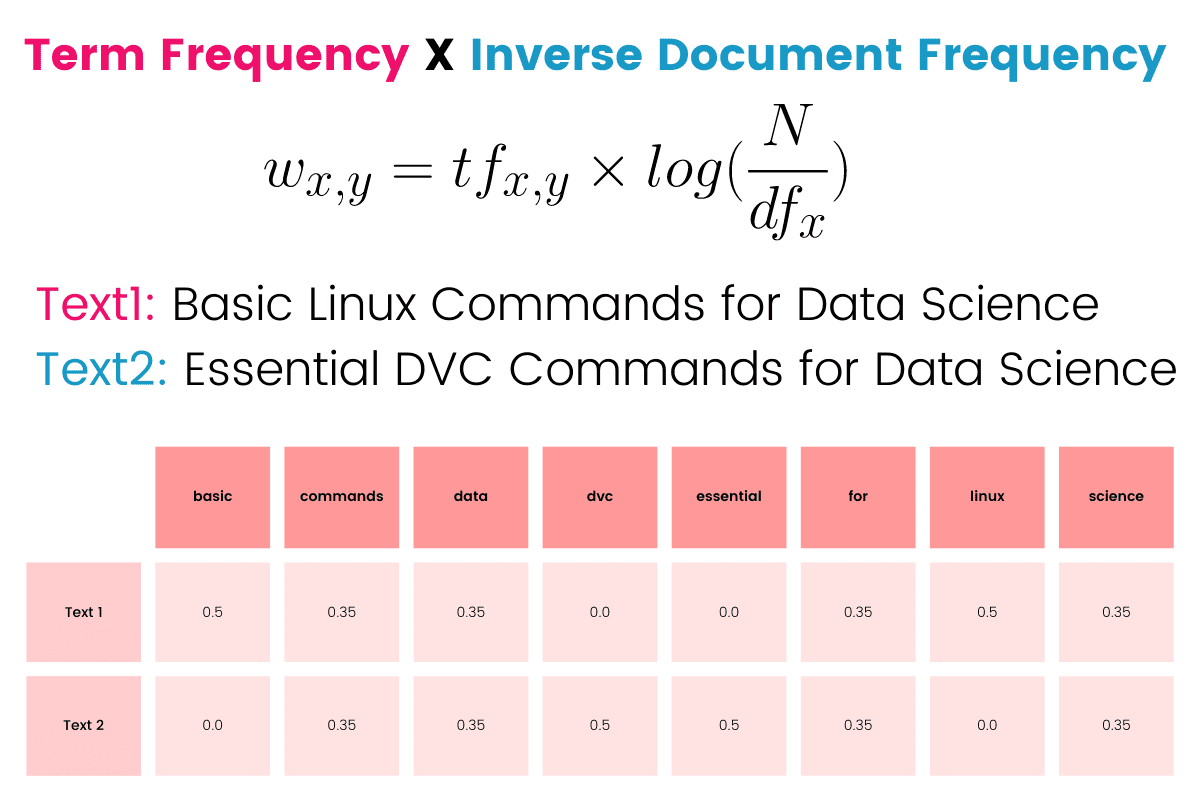
In a world overflowing with data, the ability to quickly grasp the essence of a document or a collection of documents is invaluable. TF-IDF excels at identifying keywords and key phrases that best represent the core topic of a text. By calculating TF-IDF scores for all terms and then ranking them, an algorithm can identify the top ‘n’ words that are most characteristic of the document. This capability is used in automatic content summarization, where a system can condense lengthy reports into concise overviews by extracting sentences or phrases containing high-scoring TF-IDF terms. For innovators, this means rapidly summarizing research papers, market analysis reports for new drone technologies, or performance evaluations of novel flight systems.
Powering Recommendation Systems
TF-IDF also plays a foundational role in many recommendation systems, particularly those based on content-based filtering. If a user expresses interest in documents or products characterized by certain keywords, a system can use TF-IDF to build a profile of that user’s preferences. It then recommends new documents or items that contain terms with high TF-IDF scores relative to the user’s profile. For instance, in a platform offering drone accessories, if a user frequently views content related to “long-range FPV” and “high-capacity batteries,” TF-IDF can help the system identify and recommend new products or articles featuring those specific high-relevance terms. This personalization enhances user experience and drives engagement with relevant innovative technologies.
Applications in Drone-Related Innovation
While TF-IDF’s principles are general, their application within the specific context of drone technology and innovation highlights their practical utility. From interpreting sensor data to managing vast operational data sets, TF-IDF provides a robust framework.
Analyzing Remote Sensing Data Reports
Drones equipped with various sensors (LiDAR, multispectral, thermal) generate immense amounts of data. This data is often accompanied by detailed textual reports, metadata, and analysis summaries produced by experts or automated systems. TF-IDF can be used to process these textual accompaniments. For example, if a drone performs an agricultural survey, the associated report might mention “crop health,” “nitrogen deficiency,” or “pest infestation” repeatedly. By applying TF-IDF to a collection of such reports, an agricultural tech company can quickly identify prevalent issues across different farms, track the emergence of new threats, or categorize reports based on their primary concerns, making the vast data digestible and actionable for decision-makers.
Optimizing Data Annotation for AI Models
The development of sophisticated AI models for autonomous drones often requires massive amounts of annotated data. For instance, training an object detection model to identify specific types of agricultural machinery from aerial imagery might involve numerous textual annotations describing the contents of each image. If annotators are tagging images, TF-IDF can help ensure consistency and highlight the most descriptive tags. When reviewing annotation quality or searching for specific types of annotated data, TF-IDF can quickly pinpoint images associated with rare or critical features (e.g., “damaged wind turbine blade” vs. “general power line inspection”), streamlining the data management and model training pipeline.
Intelligent Search for Drone Operations and Regulations
The regulatory landscape for drone operations is complex and constantly evolving. Pilots and operators frequently need to consult manuals, regulatory documents (e.g., FAA regulations, local bylaws), and operational guidelines. A powerful search engine built on TF-IDF principles can significantly improve the efficiency of finding relevant information. Rather than simply keyword matching, which can be imprecise, TF-IDF ranks documents based on the statistical importance of query terms within the regulatory context. This ensures that an operator searching for “Class G airspace waiver” gets results that truly emphasize that specific topic, rather than general documents that merely mention “airspace” a few times. Similarly, in fleet management, TF-IDF can help filter through maintenance logs to quickly identify drones with recurring issues related to specific components.
Beyond the Basics: TF-IDF in Modern AI Workflows
While TF-IDF has been around for decades, its utility is far from diminished. In modern AI workflows, it continues to serve as a fundamental building block, often integrated with more advanced techniques to achieve sophisticated results.
Feature Engineering for Machine Learning
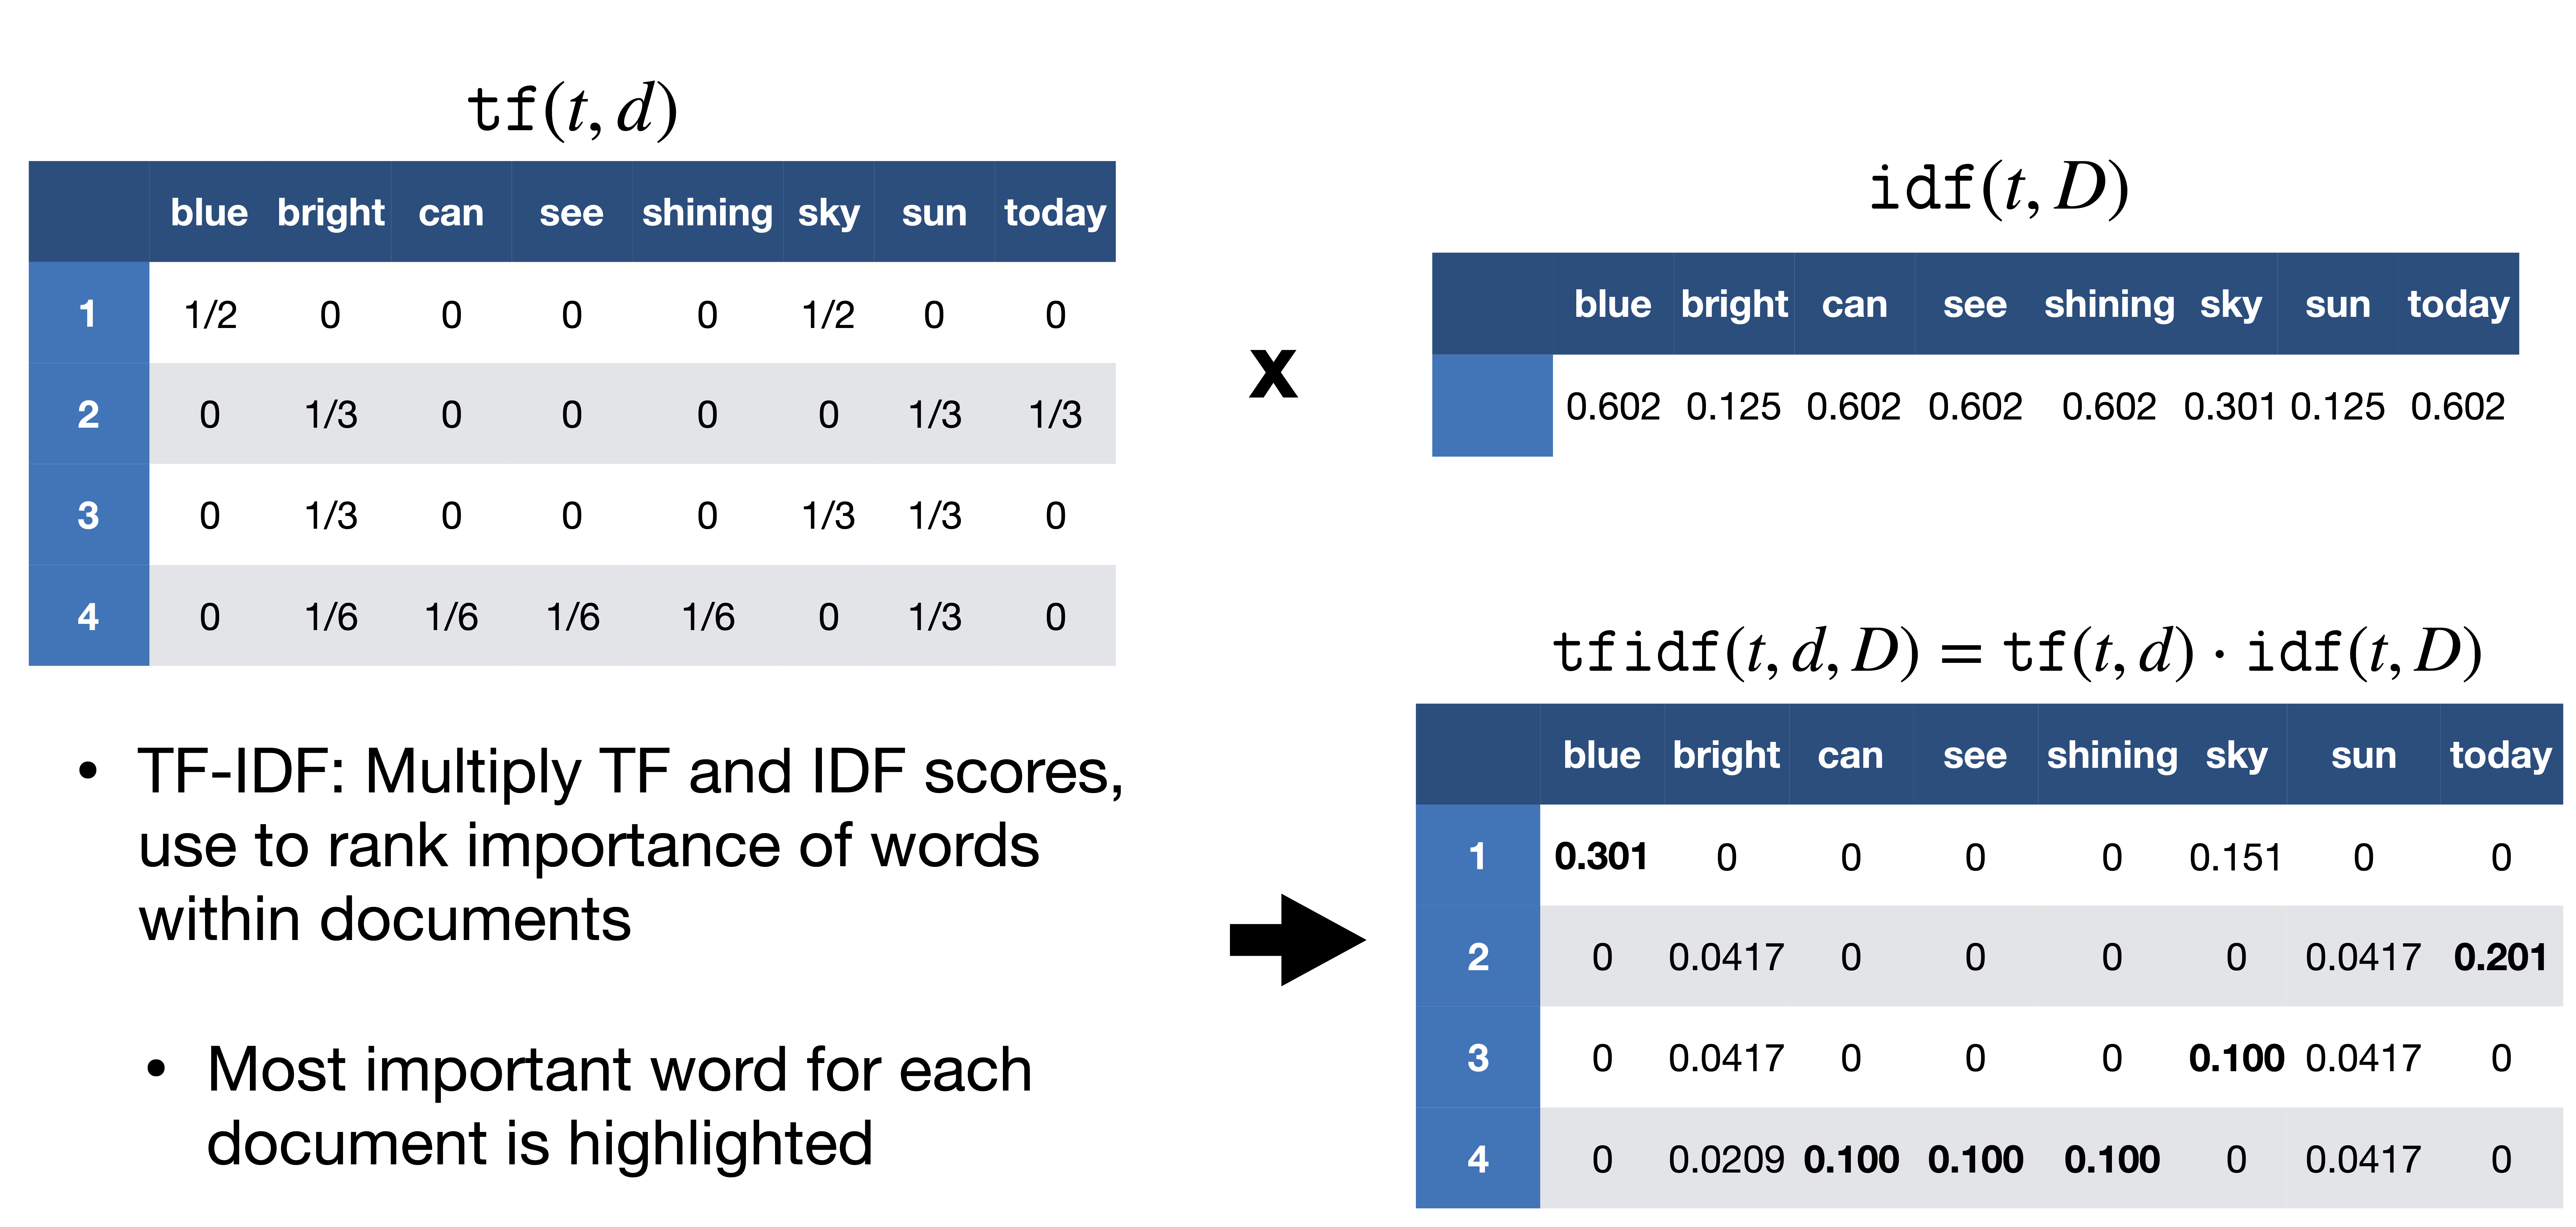
In machine learning, transforming raw text into numerical features that an algorithm can understand is called feature engineering. TF-IDF vectors are a classic and highly effective method for this. Each document can be represented as a vector where each dimension corresponds to a unique term in the corpus, and the value in that dimension is the term’s TF-IDF score for that document. These TF-IDF vectors can then be fed into various machine learning models for tasks such as document classification (e.g., classifying drone incident reports by severity), clustering (e.g., grouping similar drone sensor calibration issues), or sentiment analysis (e.g., analyzing feedback on new drone features). It provides a robust, interpretable representation of textual content that advanced algorithms can leverage.
Foundation for Semantic Understanding
While TF-IDF operates at the word level, its insights often serve as a stepping stone towards more complex semantic understanding. By identifying key terms and their relative importance, it helps prune noise and focus attention on the most meaningful parts of a text. In conjunction with techniques like latent semantic analysis (LSA) or topic modeling algorithms (like LDA), TF-IDF contributes to uncovering hidden thematic structures within large drone-related text corpora, helping innovators grasp underlying patterns in operational data, market trends, or research publications.
Limitations and Complementary Techniques
Despite its power, TF-IDF has limitations. It treats words as independent entities, ignoring their order and the semantic relationships between them (e.g., “not good” has the opposite meaning of “good”). It also struggles with synonymy and polysemy. For instance, “UAV” and “drone” might refer to the same concept but would be treated as distinct terms.
To overcome these limitations, modern AI workflows often combine TF-IDF with more advanced natural language processing (NLP) techniques. Word embeddings (like Word2Vec, GloVe, or BERT) capture the semantic meaning and contextual relationships of words, allowing systems to understand that “drone” and “UAV” are similar. Sequence models, such as recurrent neural networks (RNNs) and transformers, can process words in order, understanding grammar and syntax. However, even with these sophisticated methods, TF-IDF often provides a valuable baseline or a powerful set of initial features, demonstrating its enduring relevance as a cornerstone in the toolkit of data scientists and AI engineers pushing the boundaries of technological innovation.