
Git forking is a fundamental concept in distributed version control systems, particularly within the collaborative workflows common in software development. While the term “forking” itself is widely used across various technological domains, its specific technical implementation and significance are deeply rooted in the principles of how Git manages codebases. Understanding forking is crucial for anyone participating in open-source projects, contributing to team-based development, or seeking to experiment with existing code without directly impacting the original project.
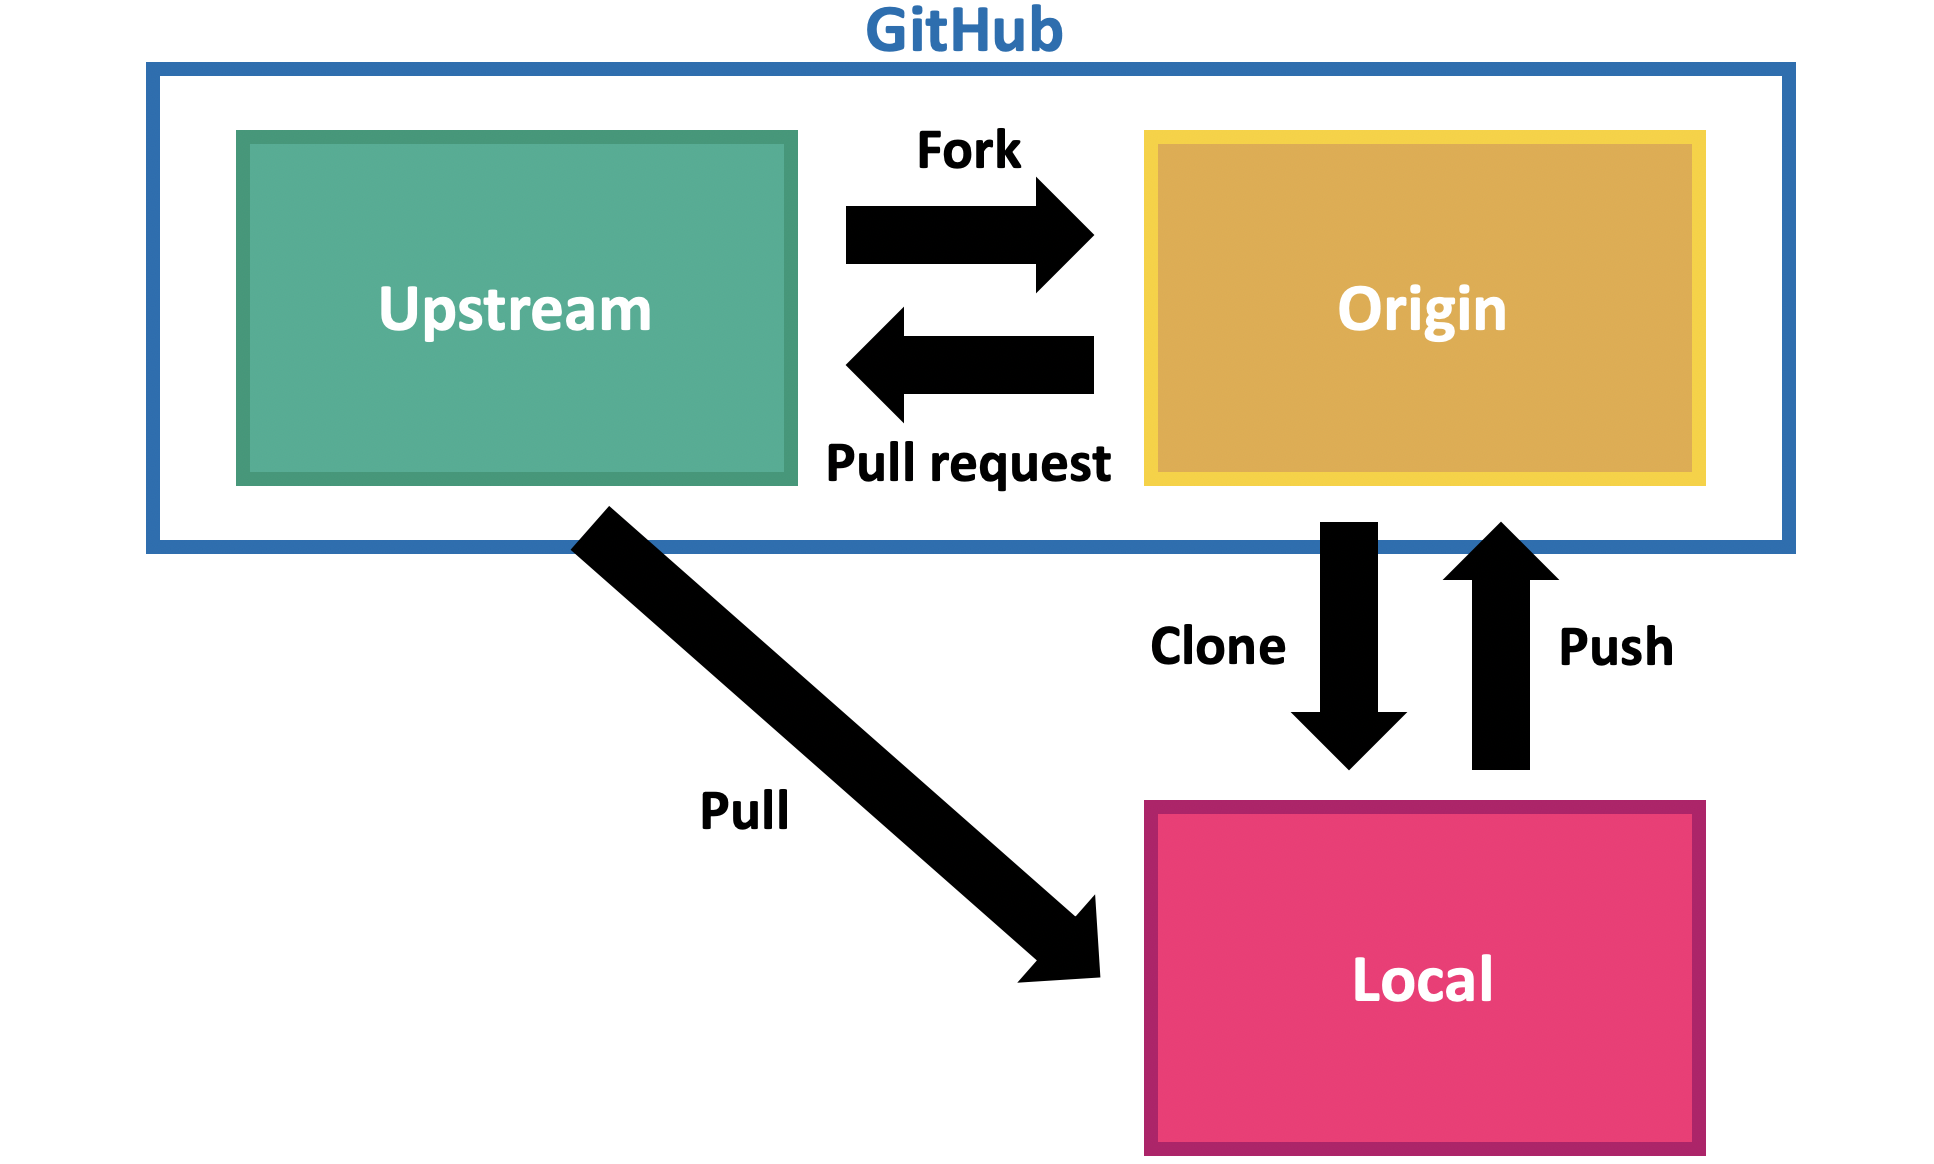
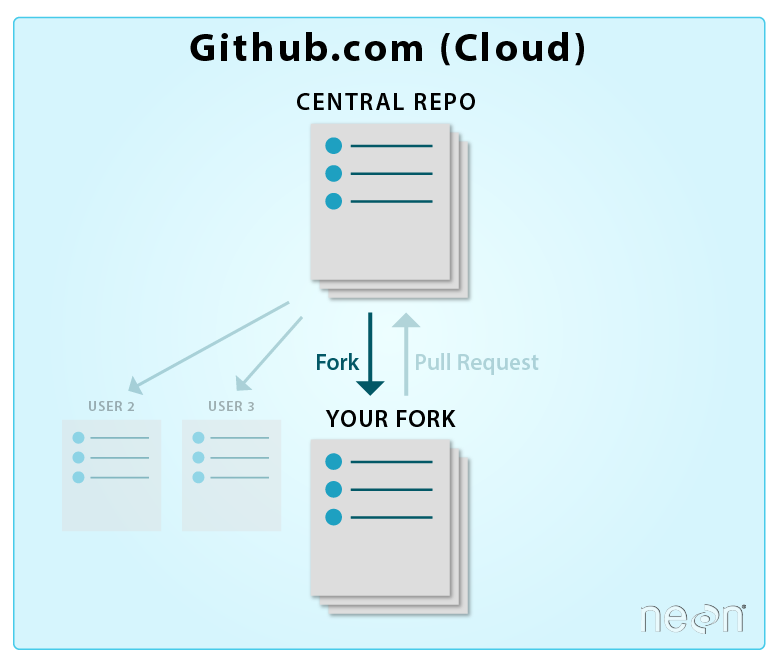
At its core, a fork is essentially a copy of a repository. However, in the context of Git and platforms like GitHub, GitLab, or Bitbucket, it signifies more than just a simple duplication. A fork creates a personal copy of another user’s repository under your own account. This independent copy allows you to make changes, experiment with new features, or fix bugs without altering the original project. The relationship between the original repository (often referred to as the “upstream” repository) and your fork is maintained, enabling a pathway for contributions back to the original project. This mechanism is the cornerstone of collaborative development, allowing a wide community of developers to engage with and improve a single codebase.
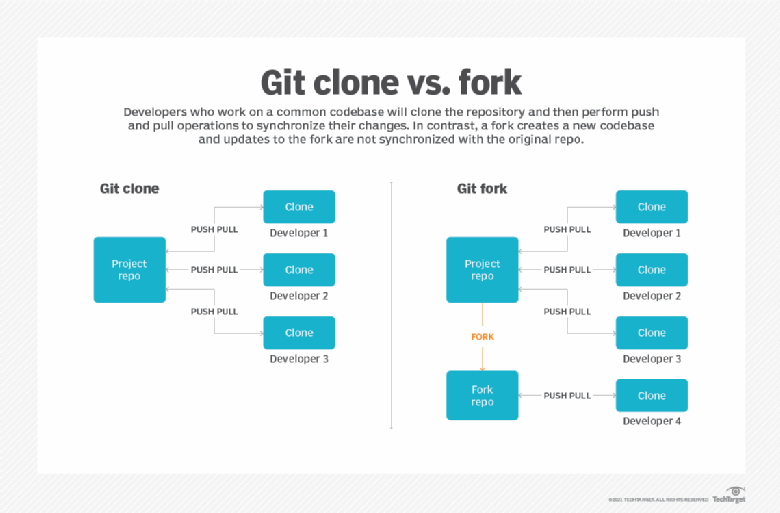
The process of forking is designed to facilitate contributions to projects where you might not have direct write access. Instead of requesting direct permissions to push changes to a central repository, you create your own copy. You then work on your fork, making your desired modifications. Once you are satisfied with your changes, you can then propose these changes to be integrated back into the original project. This proposal is typically done through a “pull request” (or “merge request” on some platforms), which is a formal request to merge the changes from your fork into the upstream repository. The maintainers of the original project can then review your code, provide feedback, and, if approved, merge your contributions.
The Mechanics of Forking in Git
When you “fork” a repository on a platform like GitHub, several things happen behind the scenes. The platform creates a complete copy of the repository’s files, including its entire commit history, branches, and metadata, under your user account. This new repository is entirely separate from the original. You have full control over this forked repository, allowing you to create new branches, commit changes, and manage it as you see fit.
However, the key differentiator of a fork is its connection to the original repository. The platform keeps track of which repository your fork was created from. This linkage is vital for subsequent actions, most notably for synchronizing your fork with the upstream repository and for creating pull requests.
Local Clones and Remote Tracking
While a fork exists on the remote platform (e.g., GitHub), you will typically want to work on it locally on your computer. This involves cloning your forked repository to your local machine using Git commands. When you clone your fork, Git automatically sets up a remote named “origin” pointing to your forked repository on the platform.
To manage contributions back to the original project and to keep your fork up-to-date, it’s standard practice to add another remote. This remote is conventionally named “upstream” and points to the original repository from which you forked. This setup allows you to fetch changes from the upstream repository into your local environment and, importantly, to push your local changes to your own remote fork.
The typical workflow involves:
- Forking: Creating a copy of the upstream repository on the platform.
- Cloning: Downloading your forked repository to your local machine.
- Adding Upstream Remote: Configuring a remote named “upstream” to point to the original repository.
- Fetching Upstream Changes: Regularly pulling the latest commits from the upstream repository into your local copy.
- Creating a New Branch: Working on new features or fixes in isolated branches.
- Making Commits: Saving your changes locally.
- Pushing to Your Fork: Uploading your local commits to your remote fork.
- Creating a Pull Request: Proposing your changes from your fork to the upstream repository for review.
This structured approach ensures that your work is organized, maintainable, and can be seamlessly integrated back into the main project.
Staying Synchronized with Upstream
One of the most common challenges when working with forks is keeping your fork synchronized with the original (“upstream”) repository. Projects, especially popular open-source ones, evolve rapidly. If you don’t regularly update your fork with the latest changes from the upstream, your fork can become significantly out of sync, making it harder to merge your contributions later.
To synchronize your fork, you typically follow these steps:
- Fetch from Upstream: Use the command
git fetch upstreamto download all the latest commits and branches from the original repository. - Checkout Your Branch: Switch to the local branch you are working on (e.g.,
git checkout mainor a feature branch). - Merge Upstream Changes: Merge the changes from the upstream’s main branch into your current branch. This is usually done with
git merge upstream/main.
If your fork has diverged significantly, you might encounter merge conflicts, which are situations where Git cannot automatically reconcile conflicting changes between your branch and the upstream branch. Resolving these conflicts requires careful attention to ensure that the correct code is preserved.
Alternatively, some developers prefer to rebase their branch onto the latest upstream changes. Rebasing rewrites commit history, making it appear as if your commits were made directly after the latest upstream commits. The command for this is git rebase upstream/main. While rebasing can lead to a cleaner, more linear history, it’s crucial to understand that rebasing should generally be avoided on branches that have already been pushed and shared with others, as it can cause confusion and complications for collaborators.
The Purpose and Benefits of Forking
Forking serves several critical purposes, particularly within the collaborative spirit of open-source software development. It democratizes contribution, enables experimentation, and provides a safety net for developers.
Facilitating Open-Source Contributions
The most prevalent use of forking is to enable contributions to open-source projects. For projects with many contributors, it’s impractical and insecure to grant everyone direct write access to the main repository. Forking provides a standardized, permission-based workflow:
- Low Barrier to Entry: Any developer can fork a project and start contributing without needing explicit permission from the project maintainers.
- Decentralized Development: It allows a distributed network of developers to work independently on the same codebase.
- Quality Control: Project maintainers review changes proposed via pull requests, ensuring that only well-tested and relevant code is integrated into the main project. This acts as a vital quality assurance mechanism.
- Bug Fixing and Feature Development: Developers can fork a project to fix bugs they encounter or to develop new features they envision.
Experimentation and Personal Projects
Beyond open-source contributions, forking is an excellent tool for personal experimentation. If you find a project that interests you but want to try out a different approach or build upon it for a personal project, forking is the ideal solution. You can freely modify your fork without any risk of damaging the original project. This allows for a sandbox environment where you can learn, innovate, and tailor code to your specific needs.
Creating Derivatives and Successor Projects
In some cases, a fork can evolve into a completely new project. If a community disagrees with the direction of an original project, or if a specific set of features is desired that deviates significantly from the upstream’s roadmap, a fork can become the foundation for a derivative project. These forks may eventually diverge so much that they become distinct entities, sometimes even surpassing the original in popularity or relevance for a particular niche. This is how many alternative software projects have emerged and thrived.
Isolating Work and Managing Personal Backups
For individual developers, forking can also be a personal workflow enhancement. You might fork a repository to create a private sandbox for trying out risky changes, or to maintain a personal backup of a project that you value, even if you have some level of access to the original. This ensures that even if the original repository is somehow compromised or deleted, you have a complete copy with its history.
Forking vs. Branching
It’s important to distinguish between forking and branching, as both are mechanisms for managing different lines of development within Git, but they operate at different scopes.
Branching is an operation performed within a single Git repository. When you create a branch, you are essentially creating a new, lightweight, movable pointer to a specific commit. All branches within a repository share the same commit history up to the point where they diverge. You can easily switch between branches, merge them, and delete them within that single repository. Branching is ideal for isolating different features, bug fixes, or experiments that are intended to be part of the same project and will eventually be merged back into the main line of development.
Forking, on the other hand, is an operation typically performed on platforms like GitHub, GitLab, or Bitbucket. It creates an entirely new repository that is a copy of an existing one. This new repository is under your control, and it exists independently of the original. While you can perform branching operations within your forked repository, the fork itself represents a conceptual separation from the upstream project. The primary purpose of forking is to facilitate contributions to a project where you don’t have direct write access, or to create a separate, personal version of a project.
In essence:
- Branching: For parallel development within a single repository.
- Forking: For creating a separate copy of a repository to enable independent development and/or contribution to an external project.
When you fork a repository, you get your own copy. You can then create branches within that copy to organize your work. The ability to fork and then create branches within that fork is what makes the collaborative workflow so powerful. You fork the project, create a branch on your fork for a specific feature, implement the feature, push that branch to your fork, and then create a pull request from that branch to the upstream repository.
Conclusion: The Indispensable Tool for Collaboration
Git forking is far more than a technical feature; it’s a philosophy of collaborative development. It embodies the principles of open access, distributed contribution, and iterative improvement. By enabling developers to create their own independent copies of repositories, forking lowers the barrier to entry for participation in projects of all sizes. It empowers individual creativity for experimentation while simultaneously providing a structured, review-based pathway for collective advancement.
From the vast landscape of open-source software, where countless projects thrive on the contributions of a global community, to the internal workflows of development teams, forking plays an indispensable role. It fosters innovation by providing a safe space for bold ideas, ensures code quality through a review process, and allows for the organic evolution of software. Understanding and leveraging the power of forking is a critical skill for any developer aiming to collaborate effectively, contribute meaningfully, or build upon the vast digital commons. It is the mechanism that underpins much of the modern software development ecosystem, fostering a culture of sharing and collective problem-solving that drives technological progress.