
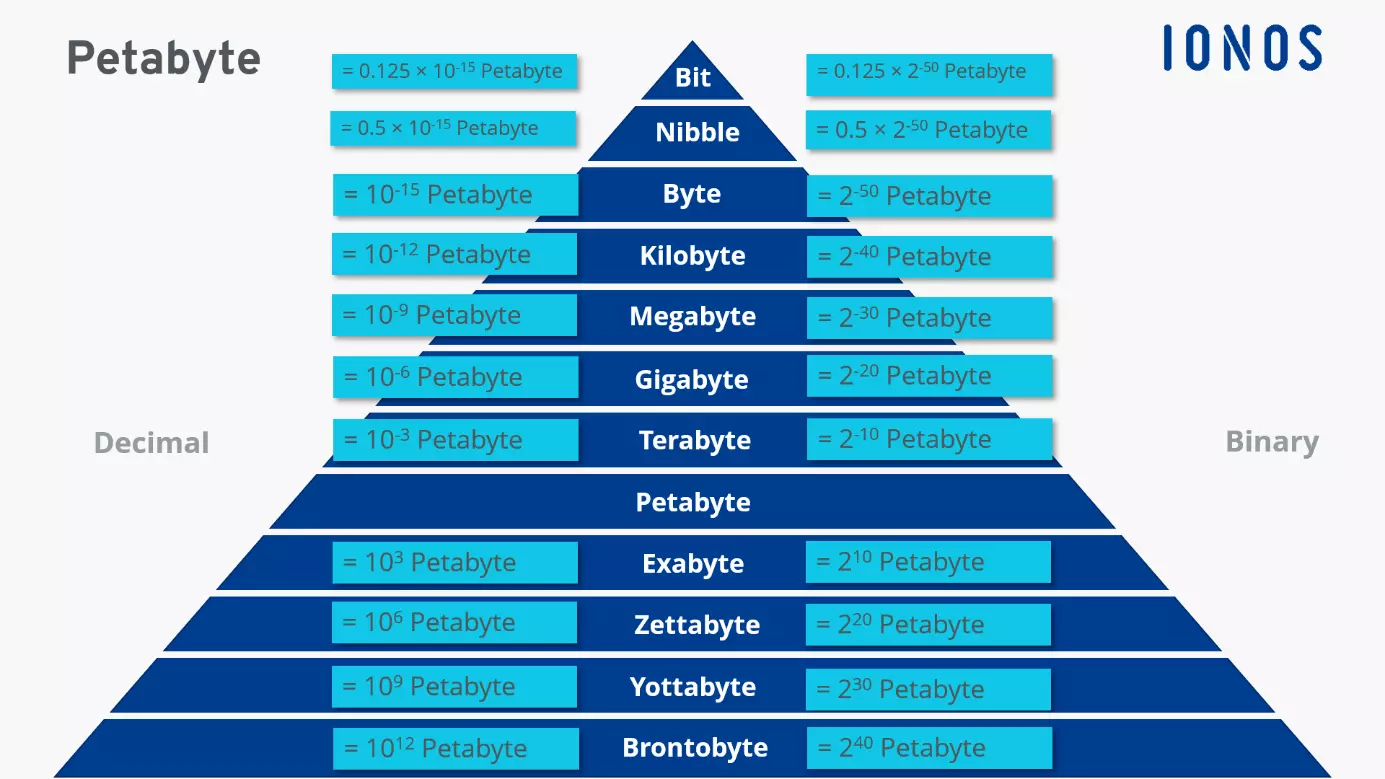
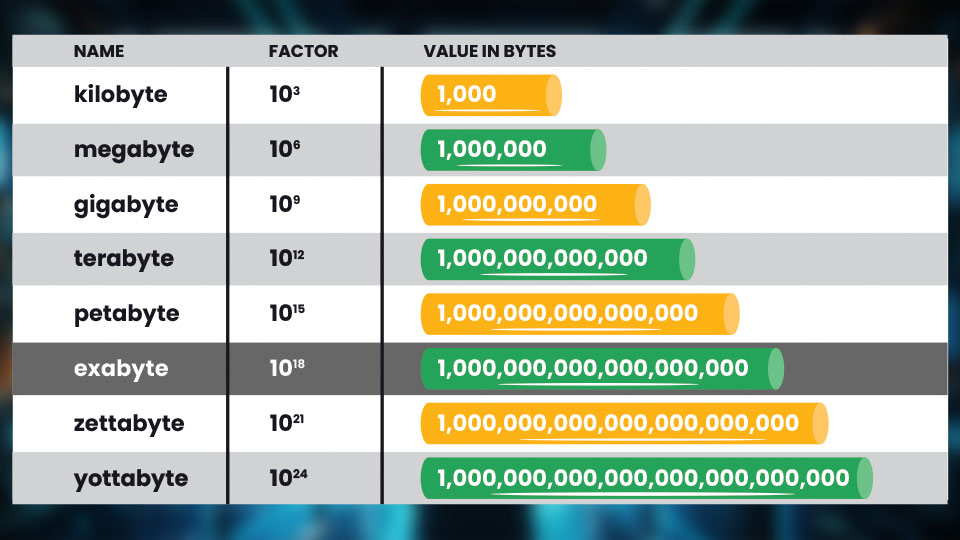
The digital universe is expanding at an exponential rate, far outpacing our ability to comprehend its sheer scale. When we talk about data, the term “petabyte” has long represented a colossal amount of information. A petabyte (PB) is equal to one thousand terabytes (TB), or one million gigabytes (GB). To put this into perspective, a single petabyte could hold about 200,000 high-definition movies. Yet, as our technological capabilities grow, so does the volume of data we generate, store, and process. This necessitates an understanding of units of measurement that extend far beyond the petabyte, pushing the boundaries of our digital comprehension. This exploration delves into the realms of exabytes, zettabytes, yottabytes, and beyond, specifically within the context of Tech & Innovation, particularly as it relates to the burgeoning fields of AI, autonomous systems, and data-intensive applications.
The Era of Exabytes and Zettabytes
As we move past the petabyte mark, the next significant unit is the exabyte (EB). One exabyte is equal to 1,000 petabytes. The global internet traffic alone generates exabytes of data annually. Consider the continuous stream of information from billions of connected devices, encompassing everything from social media interactions and video streaming to scientific research and the Internet of Things (IoT).
The Global Data Deluge
The sheer volume of data being created is staggering. Experts predict that by 2025, the world will generate over 175 zettabytes (ZB) of data. A zettabyte is a mind-boggling figure: 1,000 exabytes, or one billion petabytes. To visualize this, imagine stacking one billion petabytes of hard drives; the physical scale would be immense. This data deluge is not merely a theoretical construct; it has tangible implications for how we develop and deploy technology.
Implications for AI and Machine Learning
The advancement of Artificial Intelligence (AI) and machine learning (ML) is intrinsically linked to the availability of vast datasets. These algorithms learn and improve by being trained on enormous quantities of data, identifying patterns, and making predictions. The development of sophisticated AI models for autonomous flight, remote sensing, and complex environmental mapping relies on processing exabytes and zettabytes of sensor data, high-resolution imagery, and historical performance metrics. Without this scale of data, the current trajectory of AI innovation would be severely curtailed.
The Internet of Things (IoT) and Big Data
The Internet of Things, a network of physical devices embedded with sensors, software, and other technologies that enable them to collect and exchange data, is a significant contributor to this data explosion. Smart cities, industrial automation, and connected vehicles all generate continuous streams of data measured in petabytes and exabytes. Analyzing this data is crucial for optimizing operations, predicting failures, and creating more intelligent and responsive systems. For instance, a fully autonomous mapping drone system would collect terabytes of data per flight, and across a fleet operating globally, this quickly escalates to petabytes and beyond.
Scaling to Yottabytes and Beyond
The units of digital measurement continue to escalate, with the yottabyte (YB) being the next step after the zettabyte. One yottabyte equals 1,000 zettabytes, or one trillion petabytes. At this scale, we are talking about data volumes that are almost incomprehensible to the human mind. Current projections suggest that we will reach the yottabyte era within the next few decades, driven by further advancements in computing, sensing, and interconnectedness.
The Future of Data Storage and Processing
Storing and processing yottabytes of data presents immense technological challenges. Traditional storage methods are becoming increasingly inadequate. This has spurred innovation in areas such as cloud computing, distributed storage systems, and novel storage media. The development of petascale and exascale computing clusters is a direct response to the need to analyze these massive datasets.

Quantum Computing and Data
While still in its nascent stages, quantum computing holds the potential to revolutionize data processing. Its ability to perform complex calculations exponentially faster than classical computers could unlock new ways to analyze and extract insights from colossal datasets, potentially making the manipulation of yottabytes feasible. This synergy between quantum computing and big data could redefine the limits of what is possible in areas like scientific simulation, cryptography, and advanced AI.
The Role of Data in Autonomous Systems
The development of fully autonomous systems, from self-driving cars to advanced UAVs, is heavily reliant on processing enormous datasets. These systems need to perceive their environment, make real-time decisions, and learn from their experiences. This requires continuous ingestion and analysis of data from multiple sensors, including lidar, radar, cameras, and GPS. The data generated by a single autonomous vehicle over its lifetime could easily reach petabytes, and a global fleet would contribute to exabytes and beyond.
Autonomous Flight and Remote Sensing
In the realm of drones, autonomous flight systems are becoming increasingly sophisticated. For applications like agricultural monitoring, infrastructure inspection, and environmental surveying, drones equipped with high-resolution cameras and specialized sensors can collect vast amounts of data. Imagine a drone surveying a large agricultural area, capturing detailed imagery and spectral data. This data, when aggregated across thousands of flights and diverse geographical locations, can quickly climb into the petabyte and exabyte range. The insights derived from analyzing this data are critical for optimizing crop yields, detecting early signs of disease, and monitoring environmental changes with unprecedented accuracy.
Beyond Yottabytes: The Horizon of Data
The units of data measurement do not stop at yottabytes. Beyond them lie the brontobyte (BB), a thousand yottabytes, and the geopetabyte (GP), a thousand brontobytes. While these terms are largely theoretical and speculative at present, they highlight the relentless growth of data. The challenges and opportunities presented by such immense data volumes drive continuous innovation across the technology landscape.
The Value Proposition of Big Data
The true significance of these colossal data volumes lies not just in their size, but in the actionable insights they can yield. Advanced analytics, predictive modeling, and machine learning algorithms are tools that allow us to harness the power of big data. For businesses, governments, and research institutions, the ability to effectively manage, process, and analyze these vast datasets is becoming a critical competitive advantage.
Driving Innovation in Sensing and Data Acquisition
The quest for greater data volumes also fuels innovation in sensor technology and data acquisition methods. The development of higher resolution cameras, more sensitive environmental sensors, and more efficient data transmission protocols are all driven by the need to capture more information. This, in turn, feeds the cycle of data growth, pushing us towards ever-larger units of measurement.
Ethical and Societal Considerations
As data volumes continue to explode, so do the ethical and societal considerations surrounding data privacy, security, and equitable access. The ability to collect and analyze such vast amounts of information raises important questions about who controls this data, how it is used, and its potential impact on individuals and society. The development of robust regulatory frameworks and ethical guidelines is paramount as we navigate this increasingly data-rich world.
In conclusion, while a petabyte represents an immense quantity of data, it is merely a waypoint on a journey towards vastly larger scales. The ongoing advancements in technology, particularly in AI, autonomous systems, and sensing, are not only generating data at an unprecedented rate but are also requiring us to develop new paradigms for understanding, storing, and processing it. The era of exabytes, zettabytes, and yottabytes is not a distant future; it is the present and the immediate future, shaping the very fabric of our technological and societal evolution. The continuous innovation required to manage this data deluge will undoubtedly lead to further breakthroughs in computing, artificial intelligence, and our ability to understand the complex world around us.