
In the rapidly evolving landscape of technology and innovation, the cloud has become the foundational backbone for countless advanced applications, from AI-driven analytics to complex remote sensing operations. Within this critical infrastructure, a key metric for evaluating system resilience and operational efficiency is MTTR: Mean Time To Recovery. Understanding MTTR in the cloud isn’t merely an operational detail; it’s a strategic imperative that directly impacts innovation velocity, service reliability, and ultimately, the success of cutting-edge technological endeavors. For any organization pushing the boundaries of what’s possible, a deep grasp of MTTR in their cloud environments is paramount to maintaining continuous operation and fostering an agile development culture.
Demystifying MTTR in the Cloud Ecosystem
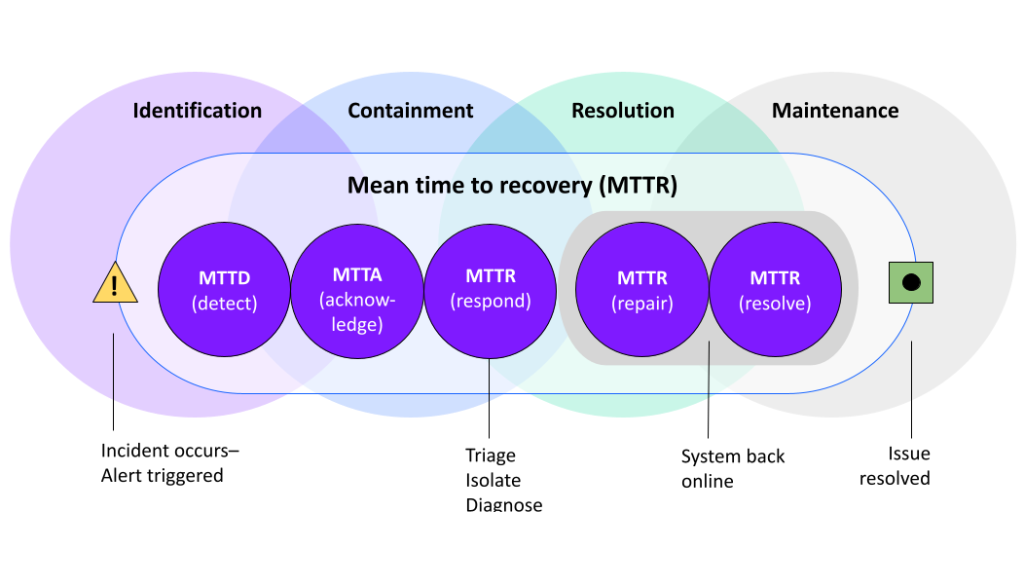
MTTR, or Mean Time To Recovery, quantifies the average time it takes to restore a system to full operation following a failure. While often conflated with Mean Time To Repair, which focuses on the time to fix a defect, MTTR emphasizes the restoration of service functionality. In a cloud context, this involves more than just fixing a server; it encompasses the entire lifecycle from incident detection to resolution and verification across potentially distributed and complex microservice architectures.
The cloud introduces unique complexities and opportunities for MTTR. Its distributed nature, reliance on virtualized resources, and often ephemeral components mean that failures can be harder to pinpoint and propagate rapidly. However, the inherent elasticity and automation capabilities of cloud platforms also offer powerful tools for rapid recovery. A low MTTR in the cloud signifies a robust system that can withstand disruptions and return to an operational state swiftly, minimizing downtime and its associated costs. Conversely, a high MTTR can lead to prolonged outages, data loss, reputational damage, and significant financial penalties, hindering innovation cycles and customer trust.
Components Influencing Cloud MTTR
Several factors contribute to the overall MTTR in a cloud environment:
- Incident Detection: The speed and accuracy with which a problem is identified are foundational. Advanced monitoring tools, anomaly detection, and comprehensive logging are crucial.
- Diagnosis & Analysis: Quickly understanding the root cause of an incident. This requires skilled personnel, effective diagnostic tools, and clear documentation.
- Resolution & Remediation: The actual process of fixing the issue, which might involve rolling back deployments, scaling up resources, reconfiguring services, or applying patches. Automation plays a significant role here.
- Verification: Ensuring that the fix has indeed resolved the problem and that the system is fully operational and stable. This step prevents recurring issues and false positives.
Each of these stages presents opportunities for optimization and innovation. For tech enterprises relying on cloud infrastructure for demanding tasks like real-time data processing for autonomous systems or complex AI model training, every minute of downtime can have cascading effects on project timelines and operational capabilities.
The Imperative of Low MTTR for Resilient Cloud Services
In an era defined by continuous delivery and always-on services, a low MTTR isn’t just a best practice; it’s a competitive differentiator and a fundamental requirement for innovation. Cloud-native applications are designed to be resilient, but true resilience is only achieved when failures can be swiftly addressed and systems returned to normalcy. For innovations such as AI follow modes for drones, or the processing of massive datasets from remote sensing missions, consistent uptime and rapid recovery from any service interruption are non-negotiable.
Impact on Business Continuity and Innovation Velocity
A low MTTR directly correlates with enhanced business continuity. Organizations can maintain uninterrupted service, protecting revenue streams and customer satisfaction. More critically, for innovation, it means development teams can iterate faster without the fear of prolonged outages derailing progress. When the underlying infrastructure is robust and quickly recoverable, innovators can push boundaries with greater confidence, knowing that system failures can be managed efficiently.
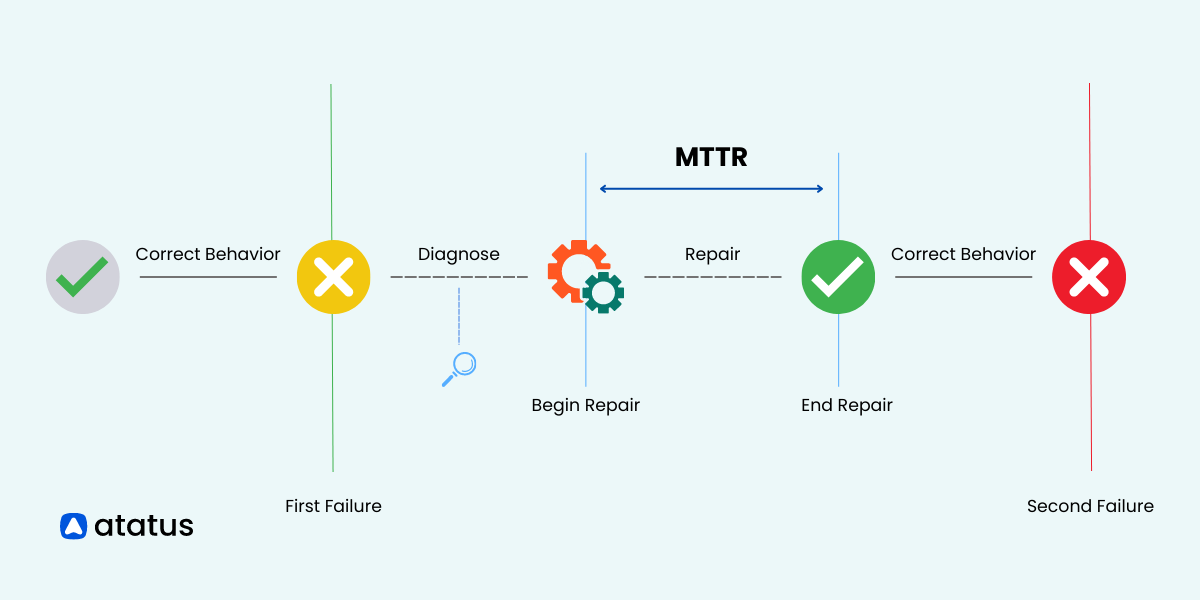
Consider the scenario of a cloud-based platform processing real-time telemetry from a fleet of UAVs. A high MTTR could mean significant data loss during an outage, leading to compromised flight safety analyses or incomplete mission data. This directly impedes the development and refinement of advanced flight technologies and autonomous capabilities. Conversely, a low MTTR ensures that even if an issue occurs, the data stream is quickly re-established, and the impact on ongoing operations and future innovations is minimized.
Building Trust and Reliability
Reliability is a cornerstone of trust, both internally among development teams and externally with end-users and partners. Consistently low MTTR demonstrates a commitment to operational excellence and a mature approach to risk management. For companies developing cutting-edge technologies, this reliability is crucial for establishing themselves as leaders in their respective fields. Whether it’s the reliability of a navigation system’s cloud backend or the stability of a drone’s mapping software, the underlying cloud infrastructure’s MTTR plays an indirect but vital role in the perceived and actual reliability of the entire tech stack.
Strategies for Optimizing MTTR in Distributed Cloud Environments
Achieving a low MTTR in the complex and dynamic environment of the cloud requires a multi-faceted approach, integrating advanced technology, robust processes, and a culture of continuous improvement. The goal is not just to fix things faster, but to build systems that are inherently more resilient and self-healing.
Embracing Automation and Orchestration
Automation is arguably the most powerful tool for reducing MTTR. From automated incident detection and alerting to automated remediation scripts and infrastructure as code (IaC) for rapid redeployment, automation reduces manual errors and speeds up every stage of the recovery process. Cloud orchestration platforms enable automated scaling, self-healing services, and rapid failovers, drastically cutting down the time required to restore service. Innovators are increasingly leveraging serverless functions and container orchestration tools like Kubernetes to encapsulate services, making them easier to isolate, diagnose, and recover.
Proactive Monitoring and Observability
Comprehensive monitoring and observability are the eyes and ears of a resilient cloud operation. Beyond basic metrics, teams need deep insights into application performance, infrastructure health, and user experience. This involves:
- Distributed Tracing: To follow requests across multiple microservices and pinpoint bottlenecks or failures.
- Centralized Logging: Aggregating logs from all services for quick searching and analysis.
- Real-time Dashboards: Providing a holistic view of system health and immediate alerts on anomalies.
- Synthetic Monitoring: Proactively testing critical user paths to detect issues before users do.
By understanding system behavior and potential failure points before they manifest as full-blown incidents, teams can act preemptively, often preventing outages entirely or dramatically shortening their duration.
Adopting a Blameless Post-Mortem Culture
Technical solutions alone are not enough; organizational culture plays a critical role. A blameless post-mortem approach encourages teams to analyze incidents openly and honestly, focusing on systemic improvements rather than assigning blame. This fosters psychological safety, allowing engineers to share insights and learn from mistakes, which is essential for continuous improvement in MTTR. Each incident becomes a learning opportunity, driving refinements in monitoring, automation, and system architecture.
Designing for Resilience (Chaos Engineering)
Innovation in resilience includes intentionally breaking things. Chaos Engineering, the practice of injecting failures into a system to test its resilience, is a proactive approach to identifying weaknesses before they cause real outages. By simulating network latency, service failures, or resource exhaustion, teams can observe how their systems react and refine their recovery mechanisms, thereby ensuring that when real incidents occur, the MTTR is as low as possible. This approach is vital for complex, distributed cloud systems that support high-stakes applications.
The Future of Cloud Reliability: Predictive Analytics and AI
The ongoing evolution of cloud reliability is increasingly integrating advanced technologies like predictive analytics and artificial intelligence. Rather than merely reacting to incidents, the focus is shifting towards predicting and preventing them. AI/ML models can analyze vast amounts of operational data – logs, metrics, traces – to identify subtle patterns that precede failures. This allows for proactive intervention, such as pre-emptively scaling resources, rerouting traffic, or even self-healing certain components before an outage occurs.
This predictive capability represents a significant leap forward in reducing MTTR, effectively pushing it towards zero by preventing incidents altogether. For cutting-edge applications in areas like autonomous flight path optimization or real-time environmental mapping, where continuous data flow and system availability are paramount, such predictive reliability will be transformative. The integration of AI into incident management and response pipelines will further automate diagnosis and remediation, reducing the need for human intervention in the initial stages of recovery and allowing technical teams to focus on deeper architectural improvements, accelerating the pace of innovation across all sectors.