
The rapid proliferation of large language models (LLMs) has marked a significant paradigm shift in artificial intelligence, unleashing unprecedented capabilities in natural language understanding and generation. However, despite their impressive fluency and breadth of knowledge, standalone LLMs often grapple with inherent limitations: they can “hallucinate” facts, their knowledge is capped at their last training cutoff, and they lack specific, real-time, or proprietary domain expertise. Addressing these challenges is paramount for deploying reliable and trustworthy AI solutions in critical applications. This is precisely where Retrieval-Augmented Generation (RAG) applications emerge as a pivotal innovation, combining the generative power of LLMs with the precision and grounding of factual retrieval.

The Evolution of AI and the LLM Knowledge Gap
The journey of AI has seen cycles of innovation, from expert systems to machine learning and now deep learning, with LLMs representing a peak in the latter. These models, trained on vast swathes of internet data, exhibit remarkable general knowledge and reasoning abilities. Yet, their very architecture—a fixed set of learned parameters—poses inherent constraints when confronted with the dynamic, nuanced, and often proprietary information requirements of real-world scenarios.
Limitations of Standalone LLMs
One of the most frequently cited challenges with LLMs is their propensity for “hallucination”—generating plausible-sounding but factually incorrect information. This arises because LLMs are trained to predict the next token based on statistical patterns, not to explicitly verify facts against an external truth source. Furthermore, their knowledge base is static, reflecting the data they were trained on, which means they cannot access or incorporate new information that has emerged since their last training update. This makes them unsuitable for tasks requiring real-time data or knowledge about recent events. Lastly, for enterprise applications, LLMs often lack access to an organization’s internal, proprietary documents, databases, or specialized domain knowledge, making them less effective for bespoke tasks that demand specific contextual understanding.
The Need for Grounded AI Responses
The commercial and ethical implications of these limitations are significant. In fields like healthcare, finance, legal services, or even customer support, misinformation can have severe consequences. Enterprises require AI systems that can provide not just fluent, but also accurate, up-to-date, and contextually relevant responses, grounded in verifiable information. This demand spurred the development of architectures that could augment LLMs with external knowledge, ensuring that the generated output is not solely a product of the model’s internal statistical patterns but also informed by reliable, external data sources.
Deconstructing Retrieval-Augmented Generation (RAG)
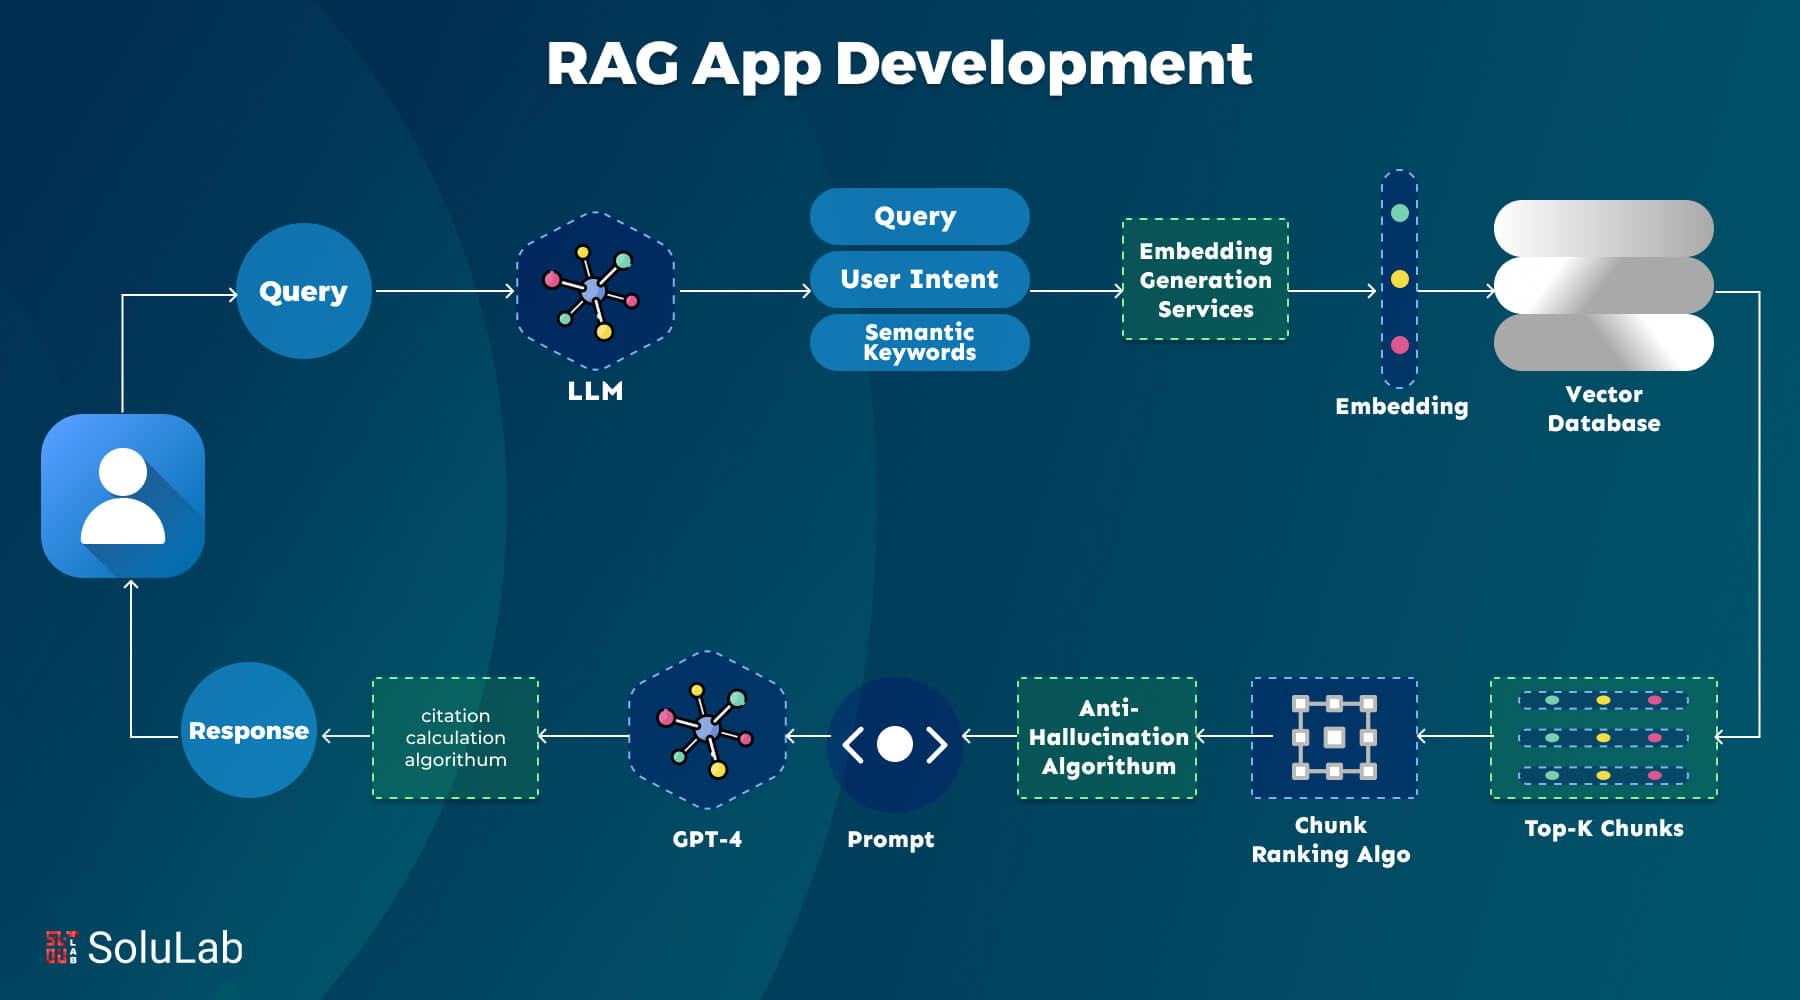
A RAG application fundamentally works by providing an LLM with relevant, external information at inference time before it generates a response. This process can be broken down into three core components: Retrieval, Augmentation, and Generation.
The Retrieval Component: Accessing External Knowledge Bases
When a user submits a query to a RAG application, the first step is to intelligently search for and retrieve pertinent information from a designated knowledge base. This knowledge base can be anything from a vast collection of documents (PDFs, articles, web pages), structured databases, APIs, or specialized data repositories.
The retrieval process typically involves:
- Indexing the Knowledge Base: The external data is first processed and indexed. This often involves segmenting documents into smaller, manageable chunks (e.g., paragraphs or sentences) and converting them into numerical representations called “embeddings” using a specialized embedding model. These embeddings capture the semantic meaning of the text.
- Semantic Search: When a user query arrives, it is also converted into an embedding. A semantic search then compares the query’s embedding against the embeddings of the indexed chunks in the knowledge base to find the most semantically similar pieces of information. This is often performed using vector databases, which are optimized for fast similarity searches across high-dimensional vectors. Unlike traditional keyword search, semantic search understands the intent and meaning behind the query, leading to more relevant results.
The Augmentation Component: Contextualizing Prompts
Once the most relevant chunks of information have been retrieved from the external knowledge base, they are not simply passed directly to the user. Instead, they are used to “augment” the user’s original query. This augmentation involves dynamically constructing an enhanced prompt for the LLM. The retrieved information is strategically inserted into the prompt, providing the LLM with immediate, relevant context that was not part of its original training data. For example, a prompt might be structured as: “Based on the following context: [retrieved relevant document snippets], answer the question: [original user query].” This step is crucial, as it transforms the LLM’s task from generating a response purely from its internal memory to synthesizing information from both its internal knowledge and the provided external context.
The Generation Component: Producing Informed Responses
With the augmented prompt, the LLM then performs its core function: generating a response. However, unlike a standalone LLM, its generation is now heavily guided and grounded by the specific, external information it received in the prompt. This forces the LLM to prioritize the provided context, significantly reducing the likelihood of hallucinations and increasing the factual accuracy and relevance of its output. The LLM acts as a sophisticated reasoning engine, synthesizing the retrieved facts with its general understanding to formulate a coherent, natural-sounding, and accurate answer. In many advanced RAG implementations, the LLM might even be prompted to cite its sources, pointing back to the specific retrieved document chunks that informed its response, further enhancing transparency and trustworthiness.
Key Benefits of RAG in Modern AI Systems
RAG applications represent a significant leap forward in making AI systems more reliable, versatile, and transparent. Their benefits extend across various dimensions, making them indispensable for sophisticated tech and innovation initiatives.
Enhanced Accuracy and Factual Grounding
The most prominent advantage of RAG is its ability to drastically mitigate the problem of LLM hallucinations. By providing the model with real-time, verifiable data, RAG applications ensure that the generated responses are factually accurate and grounded in truth. This makes AI outputs more dependable for critical decision-making processes, reducing the need for extensive human oversight and validation.
Access to Real-time and Proprietary Information
RAG directly addresses the LLM’s knowledge cutoff issue. By connecting to dynamic external databases, RAG applications can access and incorporate the latest information, ensuring that responses are always up-to-date. Furthermore, for enterprises, RAG allows LLMs to interact with proprietary internal documents, knowledge bases, and specialized data without needing to retrain or fine-tune the base LLM, which can be prohibitively expensive and time-consuming. This unlocks the potential for highly customized AI solutions that leverage an organization’s unique data assets.

Improved Transparency and Explainability
Many RAG implementations are designed to provide source attribution. By referencing the specific document snippets or data points from which information was retrieved, RAG systems offer a degree of transparency that is often lacking in black-box LLMs. Users can trace the origin of the information, verify its credibility, and audit the AI’s reasoning process. This explainability is crucial for regulatory compliance, trust-building, and debugging AI systems in complex environments.
Cost-Effectiveness and Agility
Fine-tuning or continually retraining large LLMs to incorporate new information or domain-specific knowledge is an extremely resource-intensive process. RAG offers a more agile and cost-effective alternative. Instead of altering the LLM itself, organizations can simply update their external knowledge bases. This modularity means that an LLM can be leveraged across numerous domains by simply swapping out the retrieval corpus, offering unprecedented flexibility and rapid deployment of specialized AI solutions.
Real-World Applications and Impact on Innovation
RAG applications are not merely a theoretical construct; they are rapidly being deployed across industries, transforming how organizations leverage AI for intelligence, efficiency, and customer engagement.
Enterprise Knowledge Management
One of the most impactful applications of RAG is in revolutionizing how businesses manage and access their vast repositories of internal knowledge. RAG-powered chatbots and intelligent search engines can provide instant, accurate answers to employee queries about company policies, product specifications, HR benefits, or technical documentation. This significantly reduces the time spent searching for information, improves employee productivity, and ensures consistency in information dissemination. For customer support, RAG enables sophisticated virtual agents that can answer complex customer inquiries by drawing from extensive product manuals, FAQs, and service histories, enhancing customer satisfaction and reducing agent workload.
Research and Development
In scientific and academic domains, RAG is empowering researchers to navigate and synthesize information from massive volumes of papers, reports, and data sets. By querying a RAG system, researchers can quickly summarize findings across multiple studies, identify emerging trends, and synthesize complex information, accelerating the pace of discovery and innovation. It can help analyze patent databases, summarize legal precedents, or sift through clinical trial data with unprecedented speed and accuracy.
Education and Training
RAG applications hold immense potential in education, offering personalized learning experiences and dynamic knowledge retrieval. Students can ask nuanced questions about course material, receiving answers grounded in specific textbooks or lecture notes. Trainers can deploy RAG systems to create interactive learning modules that adapt to individual progress and instantly provide contextual explanations, making learning more engaging and effective.
Content Creation and Curation
For content creators, marketers, and journalists, RAG applications provide a powerful tool for fact-checking, generating well-researched articles, or curating relevant information. By grounding content generation in verifiable external sources, RAG helps produce high-quality, trustworthy narratives, reducing the risk of spreading misinformation and enhancing editorial integrity.
The Future Landscape of RAG and AI Innovation
The current iteration of RAG is just the beginning. The field is rapidly evolving, with ongoing research pushing the boundaries of what these systems can achieve, promising even more sophisticated and intelligent AI applications.
Advanced Retrieval Mechanisms
Future RAG systems will likely feature more sophisticated retrieval mechanisms. This includes multi-modal retrieval, where the system can search across and retrieve information from text, images, audio, and video simultaneously to answer a query. Reasoning-based retrieval will involve systems that can perform more complex logical deductions to identify relevant information, rather than just semantic similarity. Techniques like “self-correction” or “self-reflection” where the LLM can critique its own retrieved results and initiate further retrieval if needed, are also emerging.
Dynamic Augmentation Strategies
The way information is augmented in the prompt will also become more dynamic and adaptive. Instead of a fixed template, future RAG systems might intelligently decide how much context to include, how to structure it, and even rephrase it to optimize for the LLM’s understanding. Personalized augmentation, tailoring retrieved information based on user profiles or past interactions, will further refine the user experience.
Integration with Autonomous Agents
Perhaps the most transformative future lies in integrating RAG with more autonomous AI agents. These agents, endowed with the ability to plan, act, and reflect, could leverage RAG to access an external “memory” or “knowledge base” to inform their decisions and actions in complex environments. This would enable highly intelligent, self-sufficient AI systems capable of performing intricate tasks by continuously learning from and interacting with their environment and vast external knowledge. RAG is thus not just a technique for LLMs but a fundamental building block for the next generation of intelligent, grounded, and trustworthy AI.