
In the vast, interconnected expanse of the internet, information resides in colossal quantities, structured and unstructured, across countless websites. Extracting and harnessing this data efficiently is a cornerstone of modern technological innovation, and at the heart of this capability lies the web scraper. A web scraper is an automated software tool or script designed to systematically browse the internet, extract specific information from web pages, and then store it in a structured format, such as a spreadsheet or database, for further analysis or use. More than just a simple download tool, scrapers are sophisticated agents capable of navigating complex website structures, interacting with dynamic content, and parsing data patterns that are often imperceptible to the human eye. They represent a fundamental innovation in how businesses, researchers, and developers interact with and derive value from public web content, powering decisions and driving progress across numerous sectors.
The Fundamentals of Automated Data Extraction
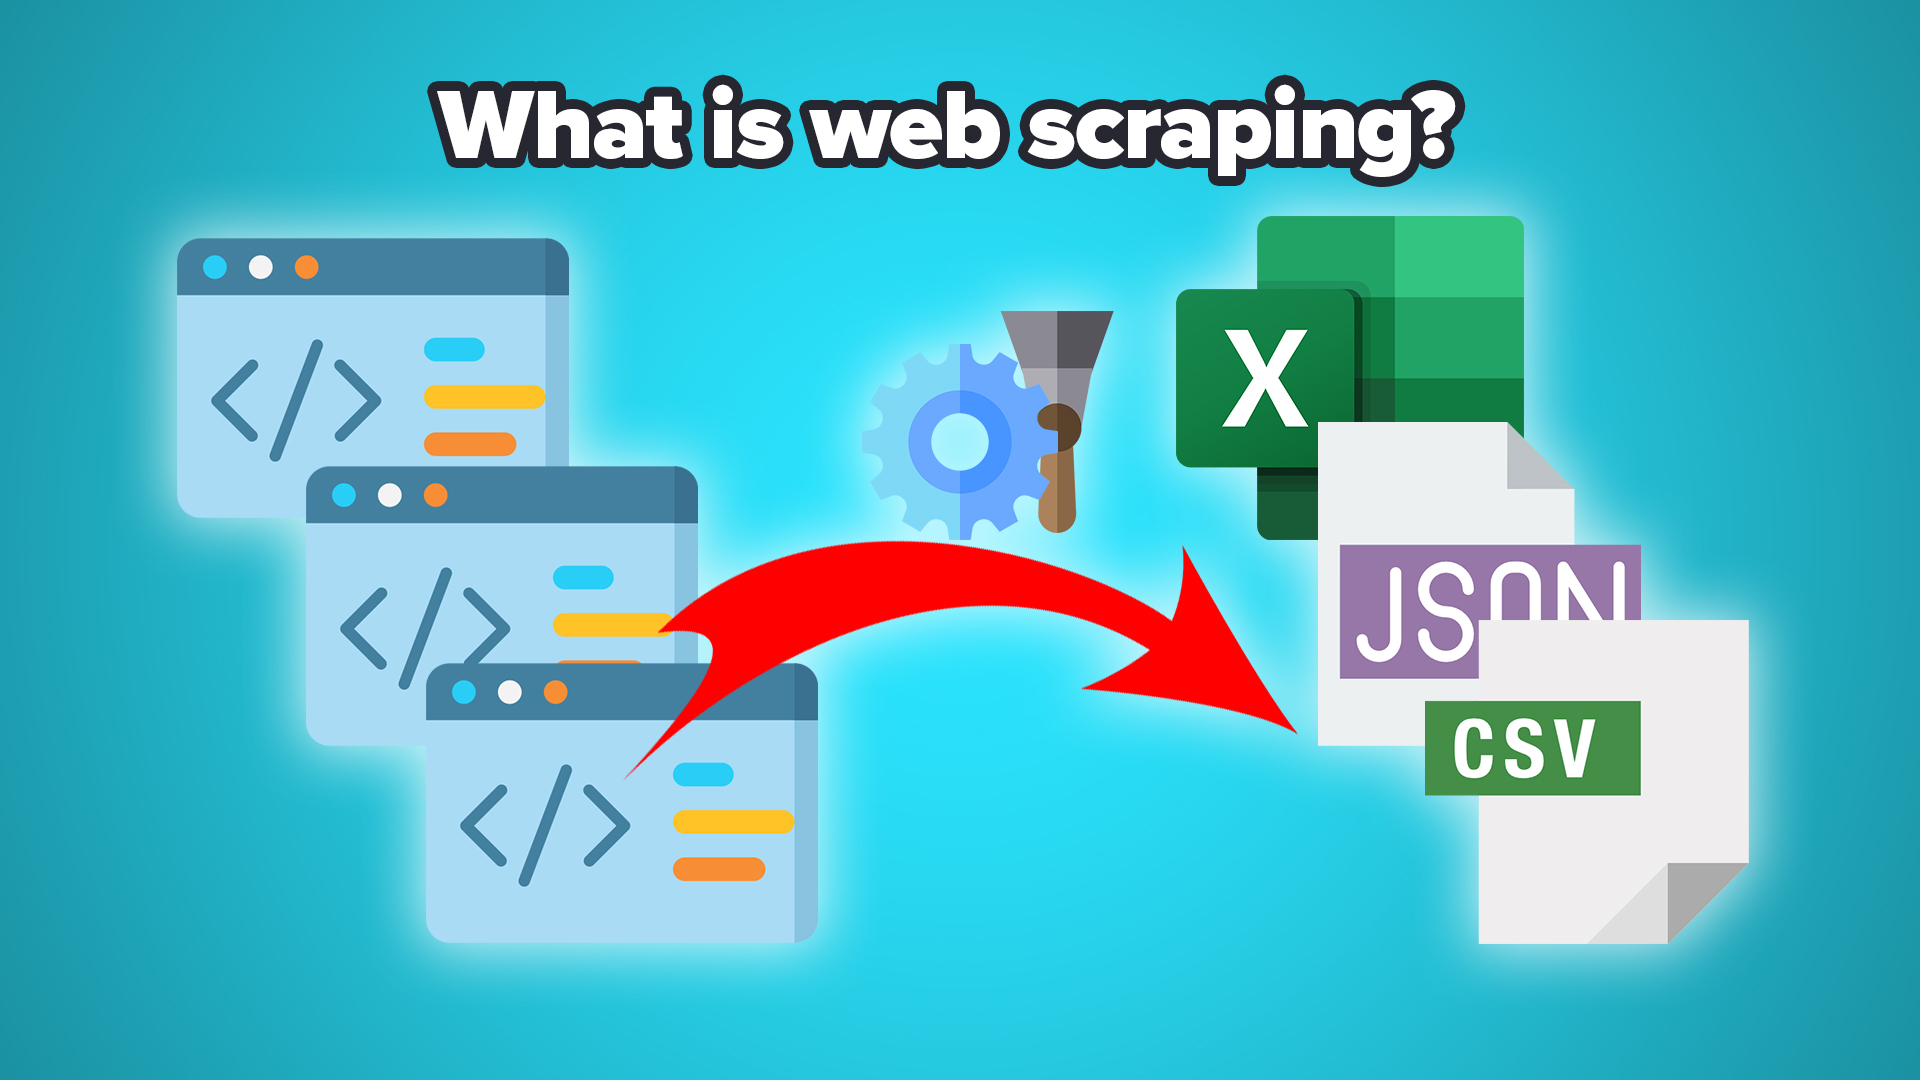
Understanding web scrapers begins with recognizing their core functionality: automation. Manual data collection from thousands or millions of web pages is impractical, costly, and prone to human error. Web scrapers address this challenge by automating the process, executing tasks at speeds and scales unattainable by human effort. This automation extends beyond mere content retrieval to include advanced features like form submission, login management, and dynamic content rendering, effectively simulating human browsing behavior to access and extract the desired data.
How Web Scrapers Operate
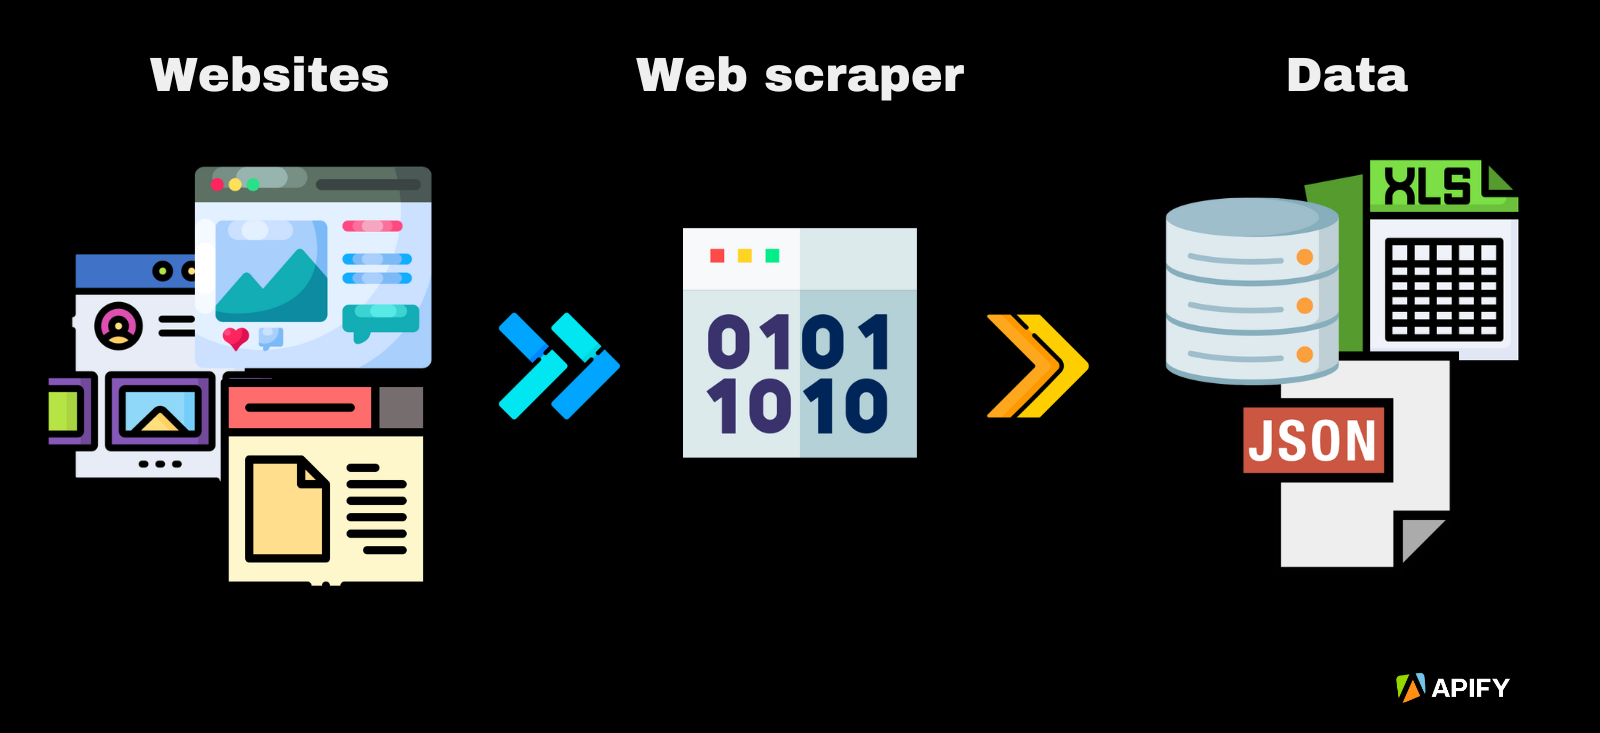
The operation of a typical web scraper involves several key stages, each requiring a blend of technical understanding and strategic design. Initially, a scraper sends HTTP requests to a target website, much like a web browser does when a user types in a URL. The server responds by sending back the HTML, CSS, and JavaScript code that comprises the web page.
Upon receiving the page content, the scraper then proceeds to parse this raw data. Parsing involves analyzing the HTML structure to locate and identify the specific data points of interest, whether it’s product prices, article headlines, customer reviews, or contact information. This is often achieved using techniques like XPath, CSS selectors, or regular expressions to define precise patterns or locations within the document object model (DOM) tree. Advanced scrapers can also execute JavaScript to render dynamic content, mimicking a full browser environment to capture data that only appears after client-side scripts have run.
Finally, once the data is extracted, it is cleaned, transformed, and stored in a usable format. This could be a CSV file, JSON, an SQL database, or even direct integration into another application via an API. The entire process is iterative, often involving navigating multiple pages, following links, and handling pagination to ensure comprehensive data collection from a large website.
Distinctions: Scraping vs. Crawling
While often used interchangeably, “web scraping” and “web crawling” refer to distinct yet related activities. A web crawler, often called a “spider,” is primarily focused on discovering and indexing web pages across the internet to build a comprehensive map of web content. Search engines like Google use sophisticated crawlers to discover new pages and updates to existing ones, feeding this information into their search indexes. Their goal is breadth and discovery, following links and exploring the web graph.
Web scraping, by contrast, is a more targeted activity. While a scraper might use crawling techniques to navigate through a website, its ultimate objective is not just discovery, but the extraction of specific data elements from those pages. A scraper knows what it is looking for and where to find it on a page, focusing on depth of data extraction rather than breadth of page discovery. For instance, a crawler might find a product page, while a scraper would then extract the product name, price, description, and reviews from that specific page. Both are integral to internet-scale data operations, but their aims and methodologies diverge significantly.
The Driving Force Behind Data Innovation
Web scrapers are not merely technical curiosities; they are powerful engines driving innovation across countless industries. Their ability to gather vast amounts of structured data from the unstructured web unlocks insights, automates processes, and fuels advanced technological applications. As an essential tool within the broader “Tech & Innovation” landscape, web scraping facilitates competitive advantage, enriches research, and provides the raw material for artificial intelligence and machine learning.
Market Intelligence and Competitive Analysis
For businesses operating in competitive landscapes, timely and accurate market intelligence is paramount. Web scrapers provide a powerful means to achieve this by continuously monitoring competitor pricing, product offerings, promotional strategies, and customer sentiment. E-commerce platforms, for example, can deploy scrapers to track millions of product prices across rival sites, allowing them to dynamically adjust their own pricing strategies to remain competitive. Similarly, by scraping customer reviews and social media mentions, companies can gain invaluable insights into public perception of their brands and products versus those of their competitors, identifying gaps in the market or areas for improvement. This proactive data acquisition empowers businesses to make data-driven decisions that impact sales, marketing, and product development.
Content Aggregation and Research
The internet is an unparalleled repository of information, making content aggregation a critical task for researchers, journalists, and specialized content platforms. Web scrapers enable the automated collection of news articles, scientific papers, job postings, real estate listings, and myriad other forms of content from diverse sources. This aggregated data can then be analyzed for trends, patterns, and anomalies that would be impossible to discern through manual review. Financial analysts might scrape news headlines to predict market movements, while academic researchers could gather data from government portals or public databases for large-scale studies. This automated content gathering accelerates research cycles and democratizes access to information, fostering deeper insights and innovation across disciplines.
Machine Learning and AI Training Data
Perhaps one of the most significant impacts of web scraping on “Tech & Innovation” lies in its role as a primary source of training data for Artificial Intelligence and Machine Learning models. Modern AI, particularly in fields like natural language processing, computer vision, and predictive analytics, relies on vast datasets to learn patterns and make accurate predictions. Web scrapers are instrumental in acquiring these datasets. For instance, to train a sentiment analysis model, a scraper can collect millions of customer reviews or social media posts. For object recognition in computer vision, scrapers can gather images tagged with specific objects from publicly available repositories. The quality and volume of data directly influence the performance of AI models, making efficient and targeted web scraping a critical component in the development and refinement of advanced AI systems. Without the ability to systematically collect and structure this data, the progress of AI would be severely hindered.
Ethical Considerations and Legal Landscapes
While the technological capabilities of web scrapers are immense, their deployment is not without ethical and legal considerations. The responsible use of this technology requires an understanding of website terms of service, the intentions of website owners, and broader data privacy regulations. Innovation in data extraction must always be balanced with respect for data ownership and user privacy.
Respecting Website Terms of Service
Most websites publish “Terms of Service” or “Terms of Use” that outline the rules for interacting with their content. These terms often include clauses prohibiting automated data collection or scraping. Ignoring these terms can lead to legal action, intellectual property disputes, or the blocking of the scraper’s IP address. Ethical scraping practices involve reviewing these terms and, where necessary, seeking permission from website owners before commencing large-scale data extraction. While the enforceability of these terms can vary by jurisdiction and specific circumstances, adhering to them demonstrates a professional and respectful approach to data acquisition.
The Role of Robots.txt
Another critical component for ethical web scraping is the robots.txt file. This is a standard protocol that website owners use to communicate with web crawlers and scrapers, indicating which parts of their site should not be accessed or indexed. While not legally binding in the same way as terms of service, a robots.txt file serves as a strong signal of a website owner’s preferences regarding automated access. Responsible scrapers are programmed to check and respect the directives in robots.txt, demonstrating good netiquette and minimizing the risk of overloading website servers or accessing sensitive information inadvertently.
Data Privacy and Regulatory Compliance
The data collected through web scraping can include personal information, which brings it under the purview of stringent data privacy regulations like the GDPR in Europe or the CCPA in California. Extracting personal data without explicit consent or a legitimate legal basis can lead to significant fines and reputational damage. Innovators utilizing web scraping must ensure their practices are compliant with all applicable data protection laws, anonymizing or pseudonymizing data where necessary, and being transparent about data collection methods when required. The innovation of web scraping must therefore be coupled with robust data governance strategies to ensure ethical and legal compliance.
Advanced Techniques and Future Trends
The field of web scraping is continuously evolving, driven by the increasing sophistication of anti-scraping measures and the demand for more robust, scalable, and intelligent data extraction solutions. Future innovations in web scraping are set to integrate more deeply with AI and cloud technologies, pushing the boundaries of what automated data collection can achieve.
Overcoming Anti-Scraping Measures
Website owners increasingly deploy advanced techniques to deter unwanted scraping, including CAPTCHAs, IP blocking, user-agent checks, dynamic content changes, and sophisticated bot detection algorithms. This has led to an arms race in web scraping technology. Advanced scrapers now incorporate distributed IP rotation, headless browser automation (using browsers like Chromium programmatically), machine learning to solve CAPTCHAs, and sophisticated session management to mimic human behavior more convincingly. The ability to dynamically adapt to website changes and bypass these defenses is a key area of innovation for web scraping tool developers.
Cloud-Based Scraping and APIs
The demand for scalable and reliable web scraping has propelled the rise of cloud-based scraping services and dedicated scraping APIs. These platforms abstract away the complexities of infrastructure management, IP rotation, and bot detection, allowing users to focus solely on data extraction logic. Cloud-based solutions offer significant advantages in terms of scalability, allowing users to process millions of pages simultaneously without managing their own server infrastructure. Furthermore, purpose-built scraping APIs provide structured access to specific data points, reducing the need for custom scraper development and offering a more reliable, often legally sanctioned, method for data acquisition. This shift towards “Scraping as a Service” marks a significant technological advancement, democratizing access to powerful data extraction capabilities.
AI-Powered Scraping and Automation
The future of web scraping is inextricably linked with advancements in Artificial Intelligence. AI-powered scrapers are emerging that can intelligently identify data points on a web page without explicit instructions, adapting to changes in website layouts autonomously. Using techniques like natural language processing and computer vision, these intelligent agents can understand the context of web content, making them far more resilient to website design changes and reducing the need for constant manual adjustments. From semantic analysis to automatically generating scraping rules based on examples, AI is set to revolutionize the efficiency, accuracy, and adaptability of web scraping. This fusion of scraping with advanced AI will enable unprecedented levels of automation in data acquisition, transforming how we gather intelligence and fuel further innovation across the digital landscape.