
In the rapidly evolving landscape of technology and innovation, from the intricate dance of autonomous drones to the complex calculations of AI algorithms, one fundamental concept underpins nearly every breakthrough: data structures. At its core, a data structure is a specialized format for organizing, processing, retrieving, and storing data. It’s not merely about storing information; it’s about doing so in a way that allows for efficient access and modification, enabling the sophisticated operations that define modern tech. Without well-chosen and expertly implemented data structures, the advanced functionalities we take for granted—like real-time object detection, precise navigation, or rapid data analysis from remote sensing—would be computationally prohibitive, if not impossible.
The Foundational Blocks of Modern Technology
Imagine a world where every piece of information, every sensor reading, every command instruction was simply thrown into a chaotic pile. Retrieving a specific piece of data, let alone processing it in a meaningful way, would be an arduous, time-consuming task. Data structures provide the blueprint for order within this potential chaos. They dictate how data elements are related to each other and how operations can be performed on them. This organization is critical for building scalable, high-performance systems.
Understanding the Core Types
Various data structures serve different purposes, each optimized for particular operations or data patterns.
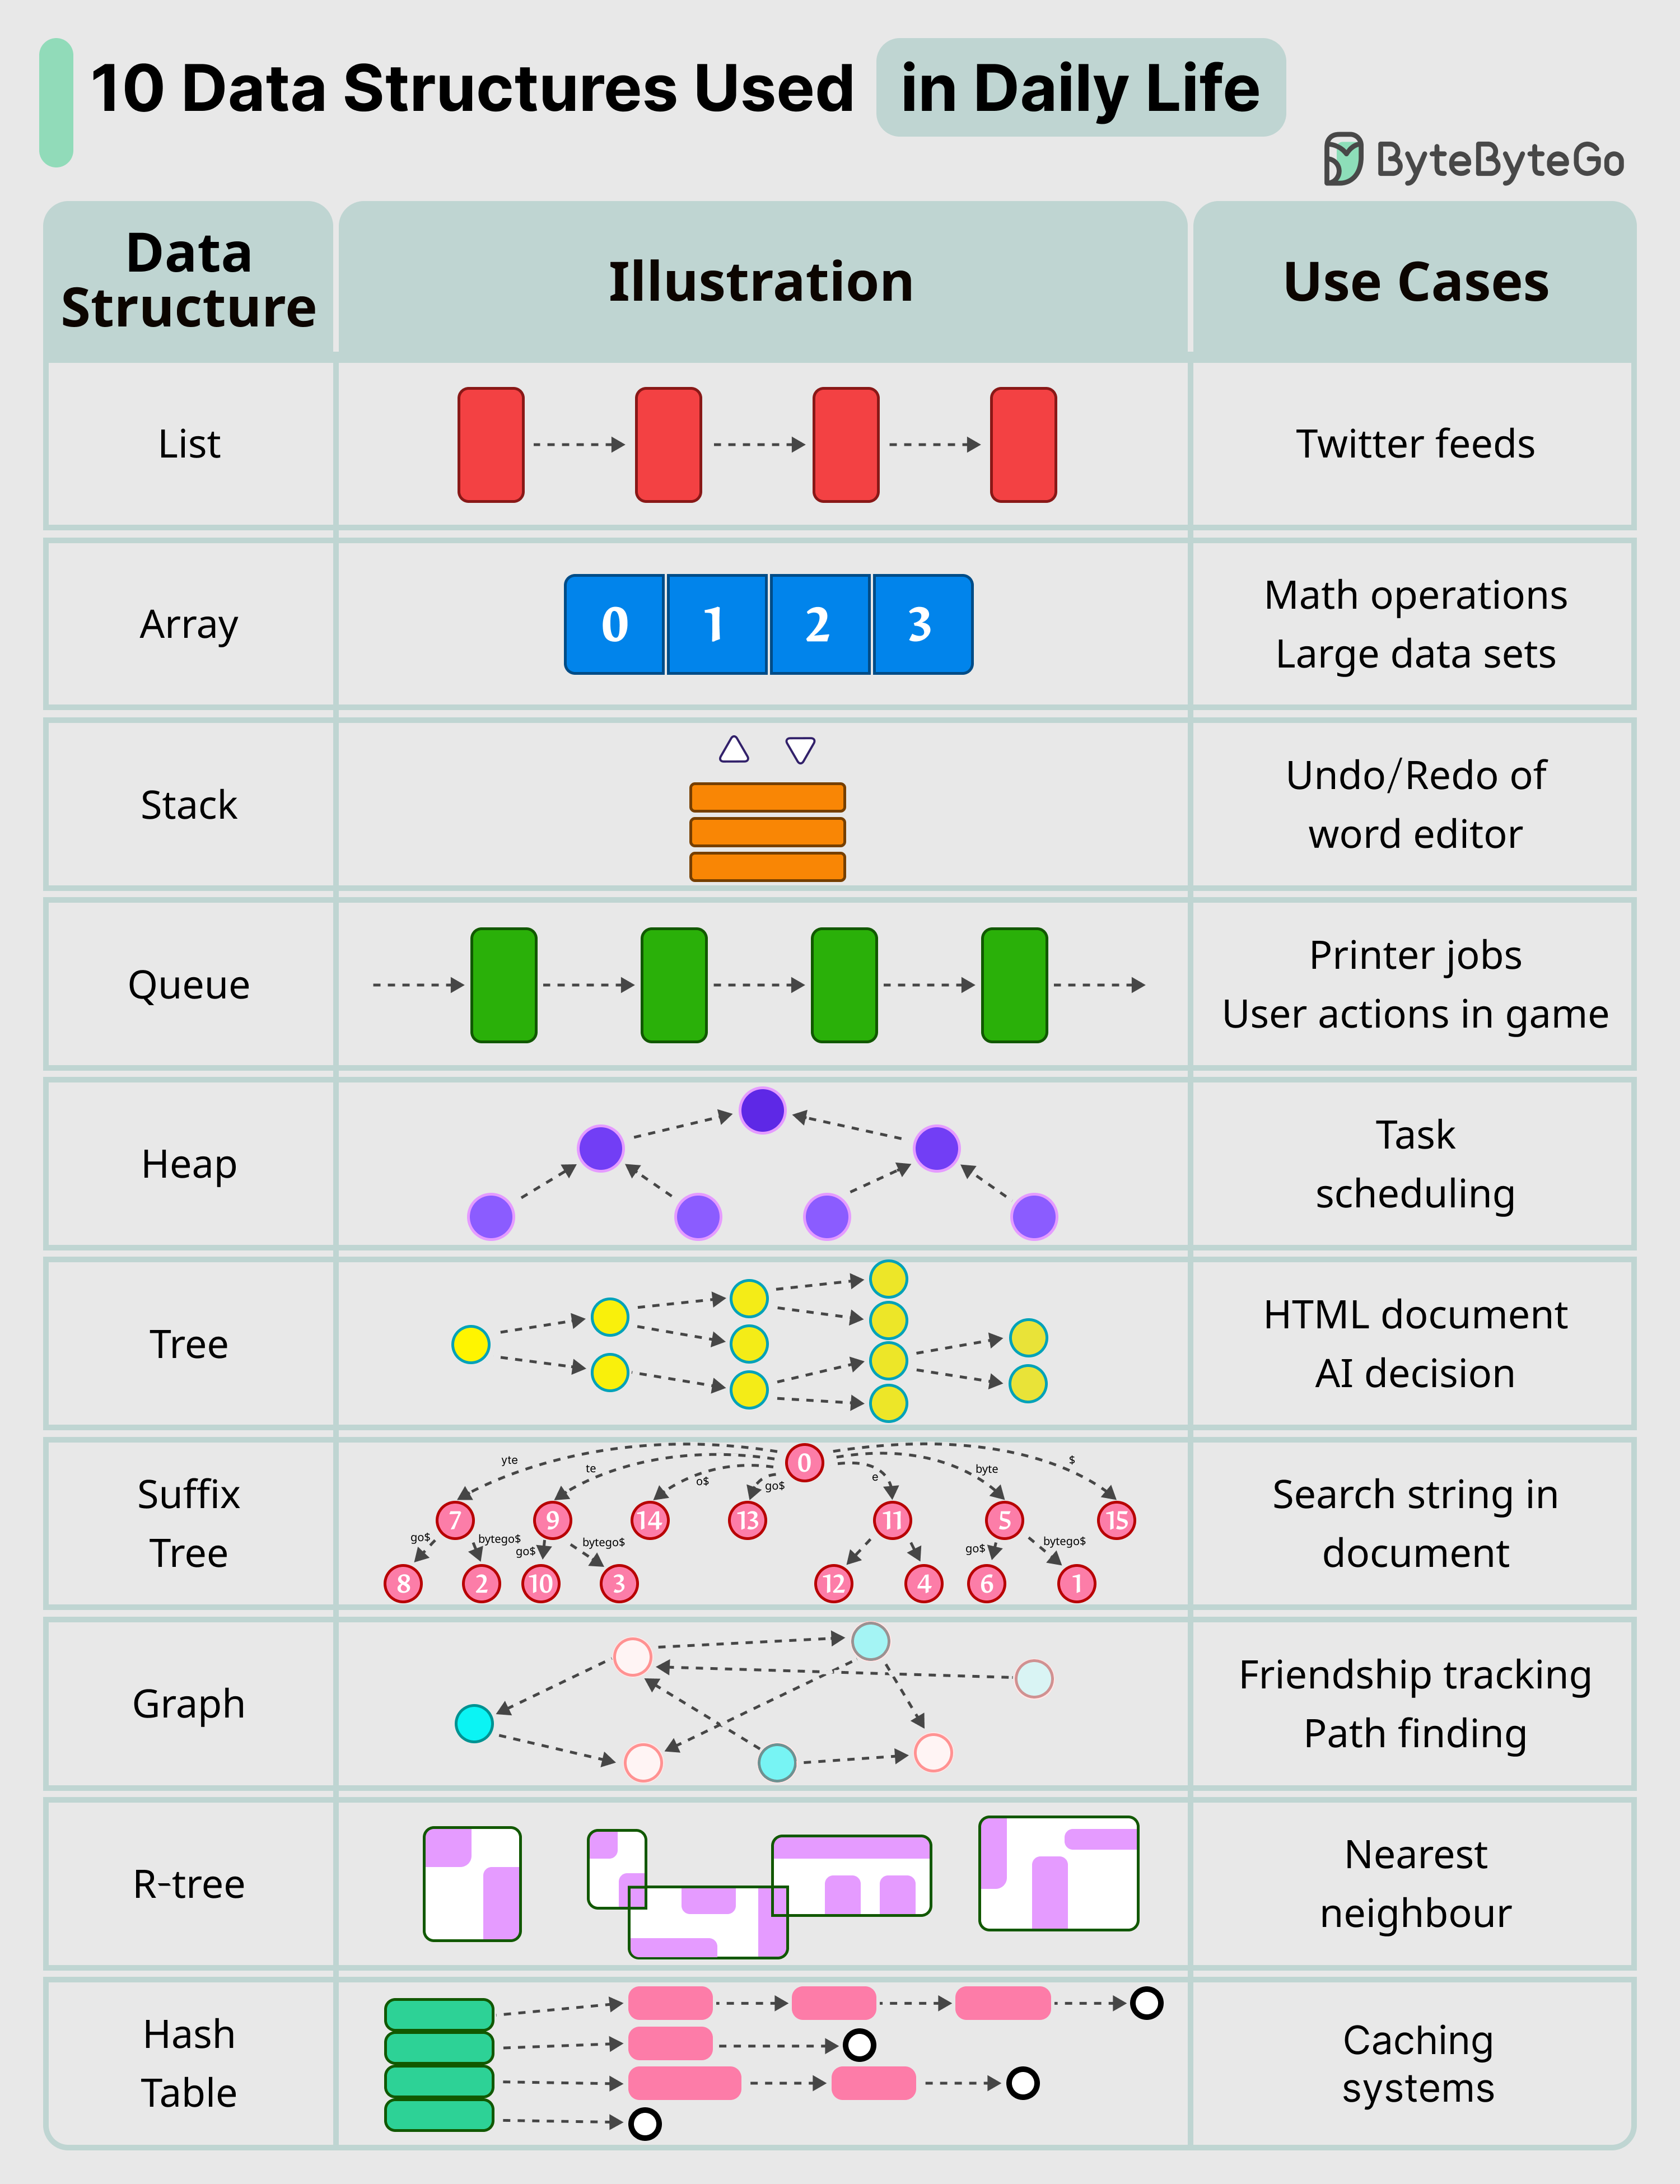
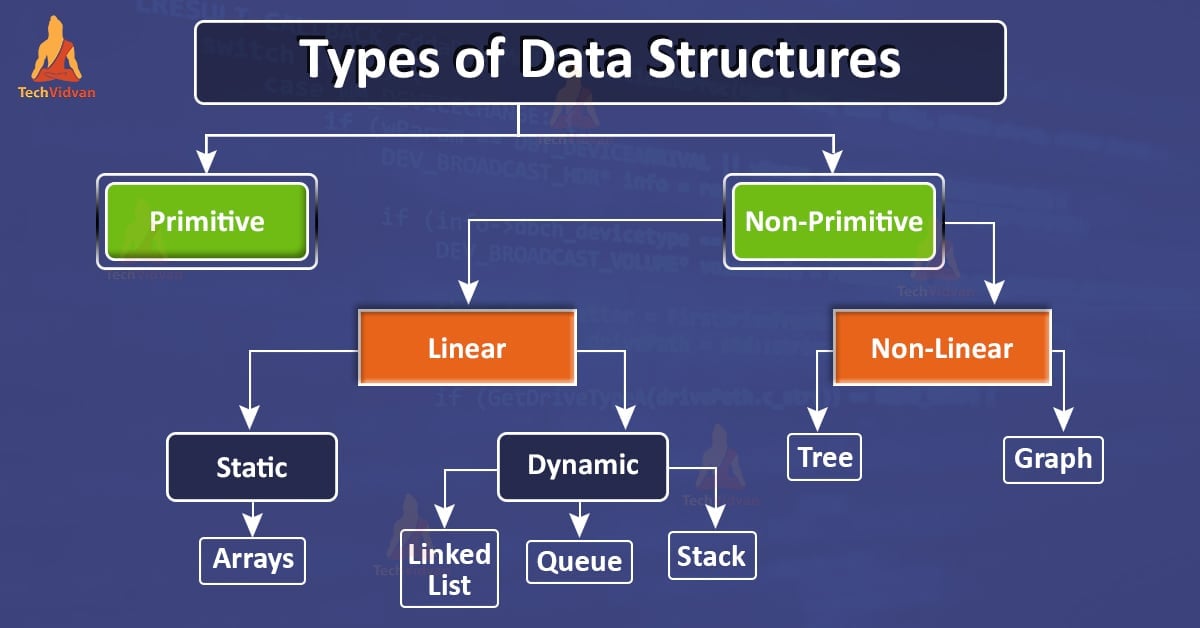
- Arrays: Perhaps the simplest and most fundamental, arrays store a collection of items at contiguous memory locations. They offer constant-time access to elements given their index, making them ideal for fixed-size collections or when rapid lookups by position are needed. In systems like those powering autonomous flight, arrays might store parameters for sensor calibration or a sequence of pre-defined waypoints.
- Linked Lists: Unlike arrays, linked lists store elements non-contiguously, with each element (node) containing the data and a reference (link) to the next node. This allows for efficient insertions and deletions anywhere in the list, as it only requires updating a few pointers, unlike arrays which might necessitate shifting many elements. This dynamic nature is valuable for managing sequences where the number of elements changes frequently, such as a log of incoming sensor data.
- Stacks: Operating on a Last-In, First-Out (LIFO) principle, stacks are analogous to a pile of plates. The last plate added is the first one removed. They are crucial for managing function calls in programs, undo/redo functionalities, or processing data in a specific order, like parsing commands in a drone’s control system.
- Queues: Adhering to a First-In, First-Out (FIFO) principle, queues are like a line of people waiting. The first one in is the first one out. They are essential for handling tasks in sequence, such as processing a stream of incoming telemetry data, managing print jobs, or scheduling tasks for multi-threaded applications in an autonomous system.
- Trees: Hierarchical structures where data is organized in nodes connected by edges, resembling an inverted tree. Each node can have child nodes, allowing for efficient searching, sorting, and storage of hierarchical data. Binary search trees, for instance, can quickly locate data by repeatedly dividing the search space in half. Trees are vital for decision-making processes in AI, representing hierarchical classifications, or organizing spatial data for mapping.
- Graphs: Composed of nodes (vertices) and connections (edges) between them, graphs are incredibly versatile for representing relationships between entities. They can model complex networks, such as road maps, social connections, or, critically, the possible flight paths and obstacles in an autonomous navigation system.
- Hash Tables (or Hash Maps): These structures store key-value pairs, allowing for incredibly fast (average constant time) retrieval of values by their corresponding keys. They use a hash function to compute an index into an array of buckets or slots, from which the desired value can be found. Hash tables are perfect for implementing caches, indexing large datasets, or quickly mapping identifiers to specific objects in a remote sensing database.
Data Structures in Action: Powering Autonomous Systems and AI
The theoretical elegance of data structures truly shines when applied to the demanding requirements of cutting-edge technology. In fields like autonomous flight, AI follow modes, and advanced robotics, the efficiency and logical organization provided by data structures are non-negotiable for real-time performance and reliability.
Representing Spatial Data and Navigation
For an autonomous drone, understanding its environment is paramount. This involves not just knowing its current position but also having a comprehensive map of its surroundings, including potential obstacles and designated waypoints.
- Graphs are extensively used to model navigation paths and environmental layouts. A drone’s path planning algorithm might represent various locations as nodes and the traversable routes between them as edges. This allows algorithms like Dijkstra’s or A* search to find the shortest or most efficient path from a starting point to a destination while avoiding obstacles.
- Trees, particularly Quadtrees or Octrees, are invaluable for spatially partitioning 2D or 3D environments. A Quadtree recursively divides a 2D space into four quadrants, while an Octree divides a 3D space into eight octants. This hierarchical decomposition allows autonomous systems to quickly identify objects or features within a specific region of interest, significantly speeding up collision detection and target tracking.
- Grid-based Maps, often implemented using 2D arrays, represent the environment as a collection of cells. Each cell can store information about occupancy (free, occupied, unknown), elevation, or other features. This provides a straightforward way for path planning algorithms to navigate and avoid obstacles.
Efficient Data Handling for AI Follow Modes and Object Recognition
AI-powered features, such as intelligent follow modes or real-time object recognition in drones, rely heavily on fast data processing and access.
- Hash Tables are critical for quickly associating detected objects with their attributes or for caching frequently accessed data. For instance, in an AI follow mode, a hash table might map unique object IDs (e.g., the target person or vehicle) to their continuously updated spatial coordinates, allowing for rapid retrieval and precise tracking.
- Arrays and Matrices form the backbone of image processing and machine learning algorithms. Raw image data, sensor readings, and feature vectors extracted for AI models are often represented as multi-dimensional arrays (matrices or tensors). Efficient array operations are fundamental to convolutional neural networks (CNNs) and other deep learning architectures used for object detection and classification.
- Queues are used to manage the influx of sensory data from cameras, LiDAR, and other sensors. Processing these streams in a structured, FIFO manner ensures that data is handled in the correct temporal sequence, crucial for real-time applications where every millisecond counts.
Optimizing Performance for Mapping and Remote Sensing
Mapping and remote sensing applications generate colossal amounts of data, from high-resolution imagery to intricate topographical details. The ability to process, store, and query this data efficiently is paramount, and here, data structures play a defining role in system performance and scalability.
Geographical Information Systems (GIS) with Trees and Grids
GIS platforms, which are essential for processing remote sensing data, leverage sophisticated data structures to manage spatial information.
- R-Trees and similar spatial indexing trees are specialized tree structures designed to store and query multi-dimensional data, such as geographical coordinates. They enable rapid spatial queries, like “find all buildings within a 1-kilometer radius” or “identify all land features intersecting this flight path.” Without such structures, querying vast geographical datasets would be agonizingly slow.
- Grids (often implemented as large arrays or specialized matrix structures) are used to store raster data, such as elevation models or satellite imagery. Each cell in the grid holds a specific value (e.g., altitude, pixel intensity), allowing for straightforward computation of terrain features, change detection, and overlay analysis.
Remote Sensing Data Indexing and Retrieval
The sheer volume of data collected through remote sensing (hyperspectral imagery, LiDAR point clouds, etc.) demands highly optimized storage and retrieval mechanisms.
- B-Trees and B+-Trees are widely used in databases and file systems to index large datasets. Their balanced tree structure ensures that data retrieval operations remain efficient even as the dataset grows to petabytes. In remote sensing, these could index metadata associated with imagery, enabling fast searches based on date, location, sensor type, or spectral band.
- Hash Tables can be employed for quick lookups of specific data products or for caching frequently accessed segments of remote sensing data, improving the responsiveness of data analysis platforms.
- Kd-Trees (k-dimensional trees) are another variant of binary search trees used for organizing points in k-dimensional space. They are particularly useful for efficiently querying point cloud data generated by LiDAR sensors, allowing for rapid nearest-neighbor searches or range queries, which are critical for 3D modeling and environmental analysis.

The Future of Tech: How Data Structures Enable Innovation
As technology continues to advance, the complexity of the systems we build only increases. AI models become more intricate, autonomous agents grow more intelligent, and the data they process expands exponentially. In this future, the role of data structures will remain as critical as ever, evolving alongside the challenges. New paradigms in data handling, such as immutable data structures for concurrent processing or specialized structures for quantum computing, are already emerging.
Efficient data structures are not merely an academic concept; they are the invisible architecture that allows our most ambitious technological visions to take flight. From optimizing battery life in drones by streamlining control algorithms to enabling instantaneous insights from vast remote sensing datasets, their mastery is fundamental to pushing the boundaries of what’s possible in tech and innovation. They are the silent enablers, transforming raw data into meaningful actions and intelligent decisions, paving the way for the next generation of autonomous, intelligent, and interconnected systems.