
In an era defined by an exponential surge in data and the relentless pursuit of technological advancement, organizations face an unprecedented challenge: how to effectively manage, access, and leverage vast, diverse datasets to fuel innovation. Traditional, centralized data architectures, once sufficient, now struggle under the weight of complexity, scale, and the demand for agility. Enter the data mesh, a revolutionary architectural paradigm gaining traction as a critical piece of modern “Tech & Innovation,” particularly for driving advancements in fields like AI, autonomous systems, mapping, and remote sensing.
The Evolution of Data Architecture in a Data-Driven World
The digital transformation has ushered in an age where data is often considered the new oil, powering everything from personalized user experiences to complex scientific simulations. However, extracting value from this deluge of information is far from straightforward. The volume, velocity, and variety of data have exploded, driven by internet-of-things (IoT) sensors, high-resolution cameras, autonomous vehicles, and remote sensing platforms. Each of these technologies generates unique and often disparate data streams that need to be ingested, processed, stored, and analyzed.

Historically, organizations attempted to centralize all their data into monolithic data warehouses or, more recently, data lakes. While these approaches offered a single source of truth and economies of scale, they often became bottlenecks. Centralized data teams struggled to understand the nuances of every domain’s data, leading to slow data delivery, poor data quality, and a lack of ownership. Data consumers – be it an AI developer building an “AI Follow Mode” algorithm, an engineer perfecting an “Autonomous Flight” system, or a data scientist working on “Remote Sensing” analytics – frequently encountered delays and frustration in accessing the specific, high-quality data they needed. This bottleneck stifled innovation, preventing agile development and deployment of new data-driven capabilities. The limitations of these monolithic systems highlighted an urgent need for a more decentralized, scalable, and domain-oriented approach to data management – a truly innovative solution that the data mesh aims to provide.
Unpacking the Core Principles of Data Mesh
Coined by Zhamak Dehghani, the data mesh proposes a paradigm shift from centralized data ownership to a decentralized, domain-oriented architecture. It is built on four foundational principles, each representing a significant innovation in how organizations approach data:
Domain-Oriented Decentralization
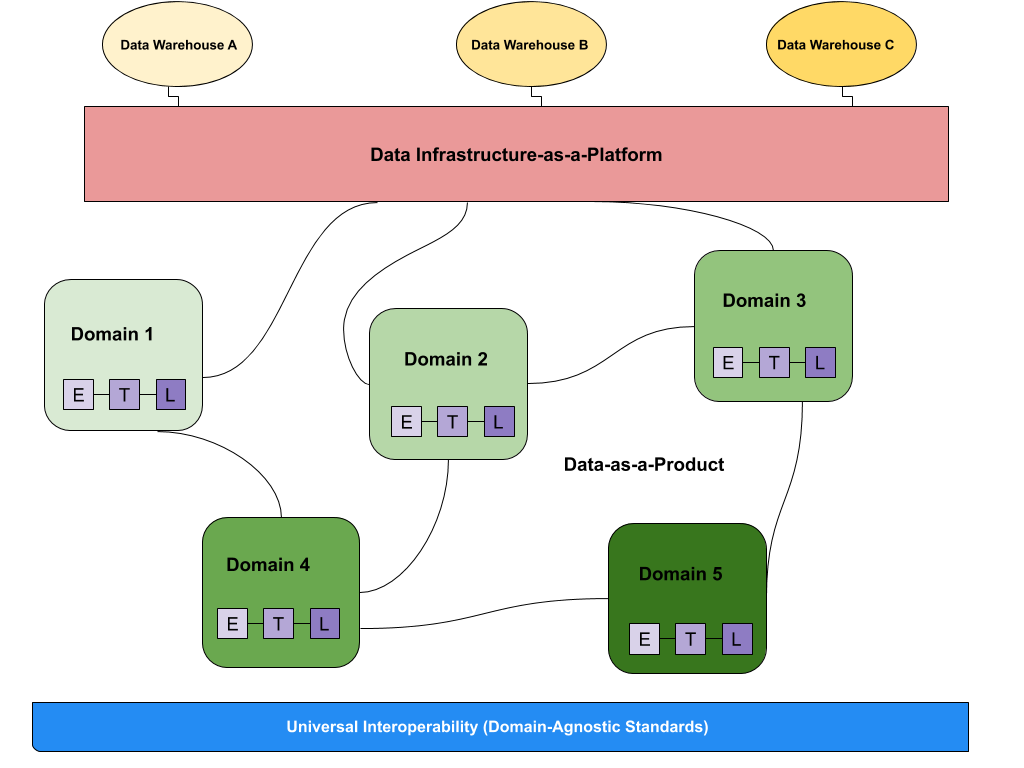
At its heart, data mesh advocates for organizing data around business domains rather than centralizing it by technical function. Instead of a single, centralized data team responsible for all data, ownership is pushed to the operational domains that generate and consume the data. For instance, in a company developing autonomous flight systems, “navigation data,” “perception sensor data,” or “flight control telemetry” would each be managed by their respective engineering or product domains. These domain teams possess the deep subject matter expertise required to understand their data’s context, quality, and usage patterns. This decentralization significantly reduces the communication overhead and bottlenecks associated with centralized data teams, empowering innovators within each domain. It ensures that the creators of data are also the experts responsible for its lifecycle and quality, a critical shift for reliable inputs into sensitive systems like “AI Follow Mode” or “Autonomous Flight.”
Data as a Product
This principle is arguably the most transformative. Within a data mesh, data is no longer merely a byproduct of operational systems; it is treated as a first-class product with dedicated owners, clear specifications, and a focus on user experience. Each domain team is responsible for offering its data as discoverable, addressable, trustworthy, interoperable, and valuable data products. This means data products have well-defined schemas, comprehensive documentation, clear quality metrics, and service-level agreements (SLAs). For an advanced mapping application, this could mean a “geospatial imagery data product” that guarantees certain resolution, update frequency, and accuracy. For AI developers, having data products that are immediately usable, well-structured, and reliable accelerates model training and deployment. This product-centric view shifts the focus from merely collecting data to actively curating and publishing data that meets the needs of its consumers, effectively catalyzing data-driven innovation.
Self-Serve Data Platform
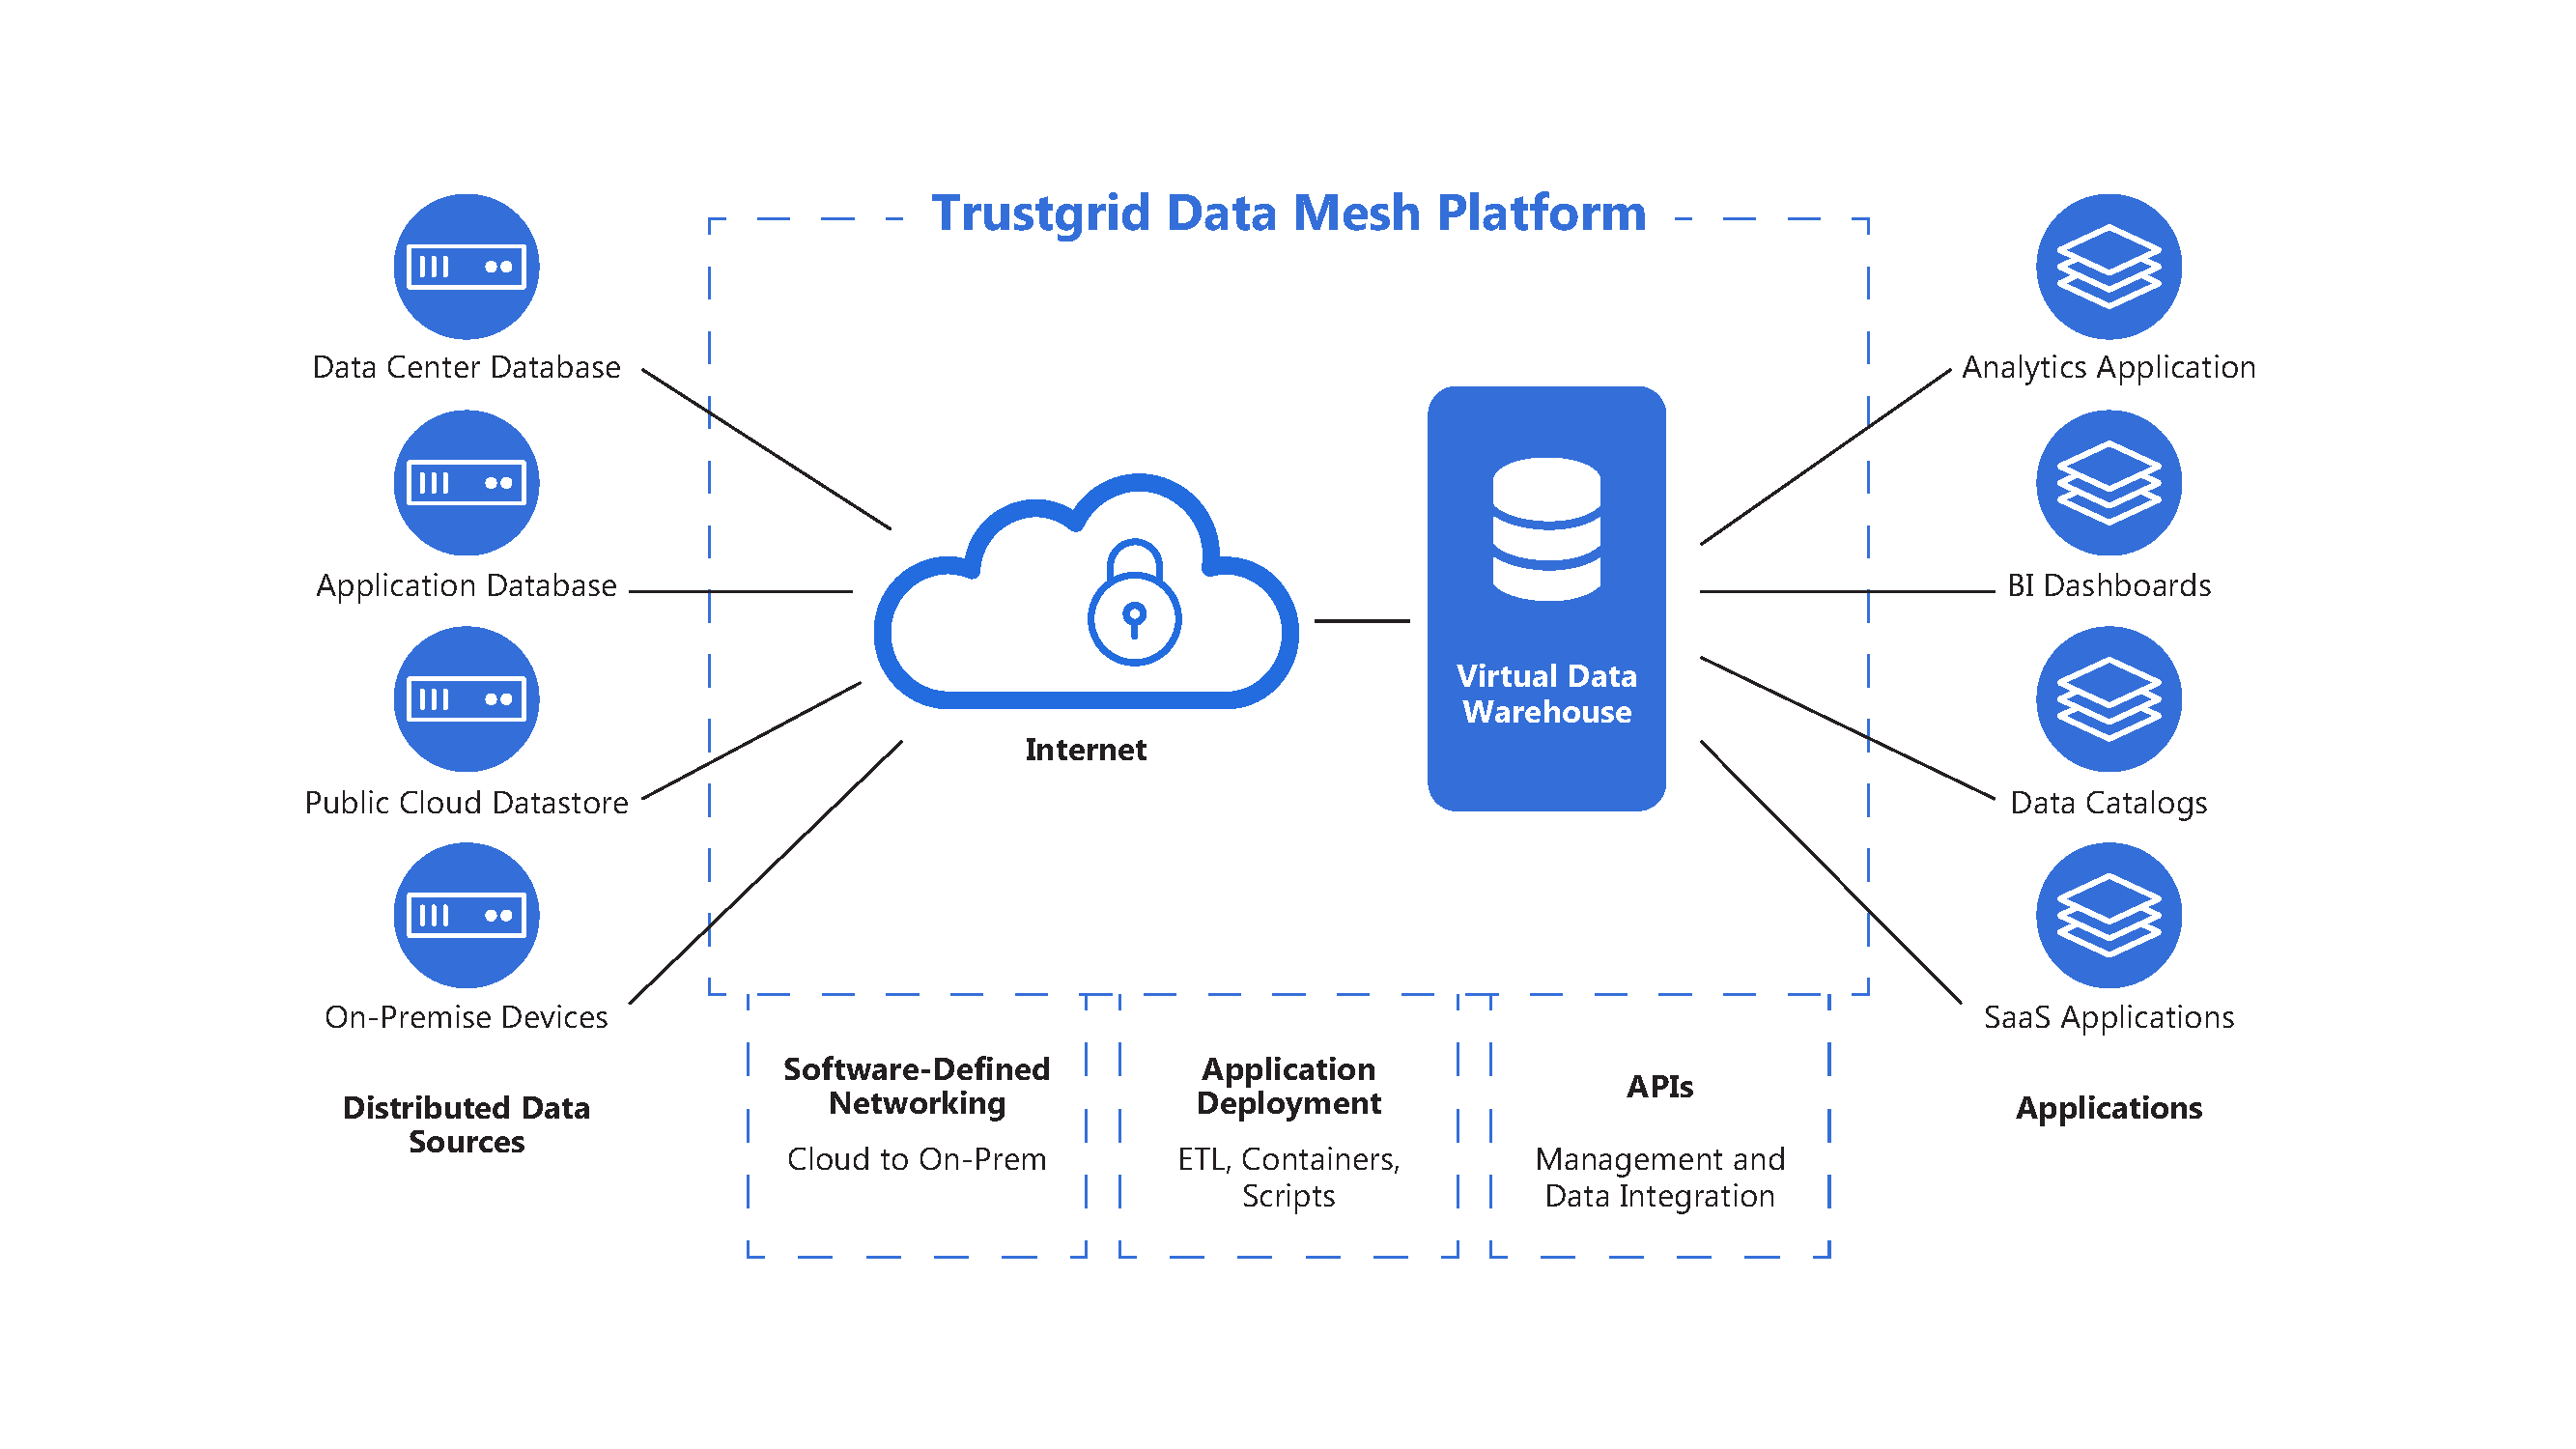
To enable domain teams to effectively create and manage their data products without becoming data infrastructure experts, a data mesh relies on a robust self-serve data platform. This platform is a layer of technological innovation that provides the underlying infrastructure, tools, and capabilities needed for data product development, storage, governance, and consumption. It abstracts away the complexity of distributed systems, data pipelines, and infrastructure management. Capabilities typically offered by such a platform include data ingestion services, storage solutions, data quality frameworks, metadata management, security and access controls, and data discovery portals. This self-serve capability empowers domain teams to autonomously build and evolve their data products, significantly reducing dependencies on central platform teams and fostering agile development, which is crucial for rapidly iterating on technologies like “AI Follow Mode” or new “Remote Sensing” algorithms.
Federated Computational Governance
While promoting decentralization, a data mesh doesn’t imply anarchy. Instead, it introduces “federated computational governance.” This principle establishes a collaborative governance model where a small, cross-functional team (the federation) defines global policies, standards, and rules – covering aspects like data privacy, security, interoperability, and compliance – that all data products must adhere to. The “computational” aspect means these governance policies are often implemented and enforced programmatically through the self-serve data platform. This ensures consistency and cohesion across the decentralized domains, preventing data silos from reappearing and ensuring that all data products are interoperable and compliant. For instance, common data classification standards or access control policies are essential when integrating diverse data from multiple sensors for “Autonomous Flight” systems, ensuring both data utility and regulatory adherence. This balanced approach to governance allows for innovation at the edge while maintaining necessary oversight and compliance across the entire data ecosystem.
Data Mesh as a Catalyst for Advanced Tech & Innovation
The data mesh architecture is not merely an academic concept; it’s a practical, impactful innovation that directly addresses the data challenges faced by cutting-edge technologies. Its principles lay a resilient and agile foundation crucial for the ongoing development and scaling of AI, autonomous systems, advanced mapping, and remote sensing.
Empowering AI, Autonomous Systems, and Advanced Mapping
AI models, especially those powering “AI Follow Mode” in drones or the sophisticated decision-making in “Autonomous Flight” systems, are voracious consumers of data. They require vast quantities of high-quality, diverse data – from high-resolution imagery and video to LiDAR point clouds, inertial measurement unit (IMU) data, and GPS telemetry. A data mesh transforms how these critical data inputs are managed and accessed:
- Reliable Data Products for AI Training: Each distinct data source (e.g., camera feeds, sensor logs, object detection annotations) can be treated as a separate, governed data product. This ensures that AI teams building predictive models or control algorithms for autonomous systems have immediate access to well-understood, validated, and trustworthy datasets. The “data as a product” principle guarantees discoverability and quality, significantly reducing the “data wrangling” time that often plagues AI development.
- Accelerated Iteration for Autonomous Systems: Developing and deploying autonomous capabilities requires rapid iteration. With data mesh, different data domains (e.g., perception, planning, control) can independently evolve their data products without impacting others. This enables faster development cycles for features like improved obstacle avoidance or more robust navigation in “Autonomous Flight” systems.
- Integrated Data for Advanced Mapping: Modern mapping initiatives, from creating detailed 3D models of urban environments to generating real-time traffic maps, rely on integrating data from various sources: satellite imagery, aerial photography, ground-based sensors, and crowd-sourced information. A data mesh facilitates this by making each of these data types available as standardized, interoperable data products, simplifying integration and enabling the creation of richer, more dynamic maps. For example, a domain owning “terrain elevation data” can serve it as a product, easily combinable with a “satellite imagery data product” to generate comprehensive geospatial insights.
Enhancing Remote Sensing Capabilities
“Remote Sensing” platforms, including drones, satellites, and airborne sensors, generate colossal amounts of highly specialized data across various spectral bands, spatial resolutions, and temporal frequencies. Analyzing this data to derive actionable insights for agriculture, environmental monitoring, disaster response, and urban planning presents significant data management challenges that data mesh is uniquely positioned to address:
- Domain-Specific Data Expertise: Remote sensing data often requires deep domain knowledge for interpretation and processing. A data mesh aligns data ownership with this expertise. For instance, a “precision agriculture data” domain would manage satellite imagery, drone multispectral data, and soil sensor readings specific to agricultural applications, ensuring high relevance and quality.
- Improved Data Discoverability and Access: Researchers and application developers often struggle to find and access specific remote sensing datasets across different providers or internal departments. By treating these datasets as discoverable data products with rich metadata, data mesh significantly lowers the barrier to entry, fostering broader utilization and enabling new discoveries.
- Facilitating Cross-Modality Analysis: Many advanced remote sensing applications require combining data from different sensor types (e.g., optical imagery with synthetic aperture radar). Data mesh’s emphasis on interoperable data products with federated governance standards simplifies this complex integration, leading to more robust analytical models and enhanced insights for environmental monitoring or change detection. This enables innovations like combining thermal imaging data products from drones with ground sensor data products for sophisticated energy management solutions.
Implementing Data Mesh: Challenges and the Path Forward
Adopting a data mesh architecture is a significant undertaking, representing not just a technological shift but also a profound cultural and organizational transformation. One of the primary challenges lies in transitioning from established centralized data teams to empowering cross-functional domain teams with data ownership and product responsibility. This requires new skills, processes, and a mindset shift across the entire organization, particularly for teams who are accustomed to relying on central data providers for their “AI Follow Mode” or “Remote Sensing” data needs.
Technically, building the self-serve data platform that abstracts away complexity for domain teams is a substantial effort, requiring expertise in distributed systems, data governance, and developer experience. Ensuring consistent application of federated governance across a decentralized landscape also demands careful planning and robust automation.
However, the benefits far outweigh these challenges. Organizations embarking on a data mesh journey often begin with incremental adoption, identifying a few critical data domains to pilot the new approach. This allows them to demonstrate value, learn, and refine their implementation strategy before scaling.
Ultimately, data mesh represents a pivotal “Tech & Innovation” that empowers organizations to unlock the full potential of their data. By fostering decentralization, product thinking, self-service capabilities, and federated governance, it provides a scalable, resilient, and agile data foundation that is indispensable for driving the next generation of advancements in artificial intelligence, autonomous systems, advanced mapping, and remote sensing, ensuring that data fuels, rather than hinders, the pace of innovation.