
In an increasingly data-driven world, the ability to collect, process, and analyze vast amounts of information is a significant competitive advantage. Websites, in particular, are colossal repositories of public data, ranging from product prices and customer reviews to news articles and scientific publications. However, accessing this information in a structured, machine-readable format often presents a challenge. This is where website scraping, also known as web scraping or web data extraction, emerges as a critical technological solution. At its core, website scraping is the automated process of collecting data from websites. It involves programmatic tools and scripts that simulate human browsing behavior to read and extract specific information from web pages, transforming unstructured web content into structured data that can be stored, analyzed, and utilized for various purposes.
The Fundamentals of Web Scraping
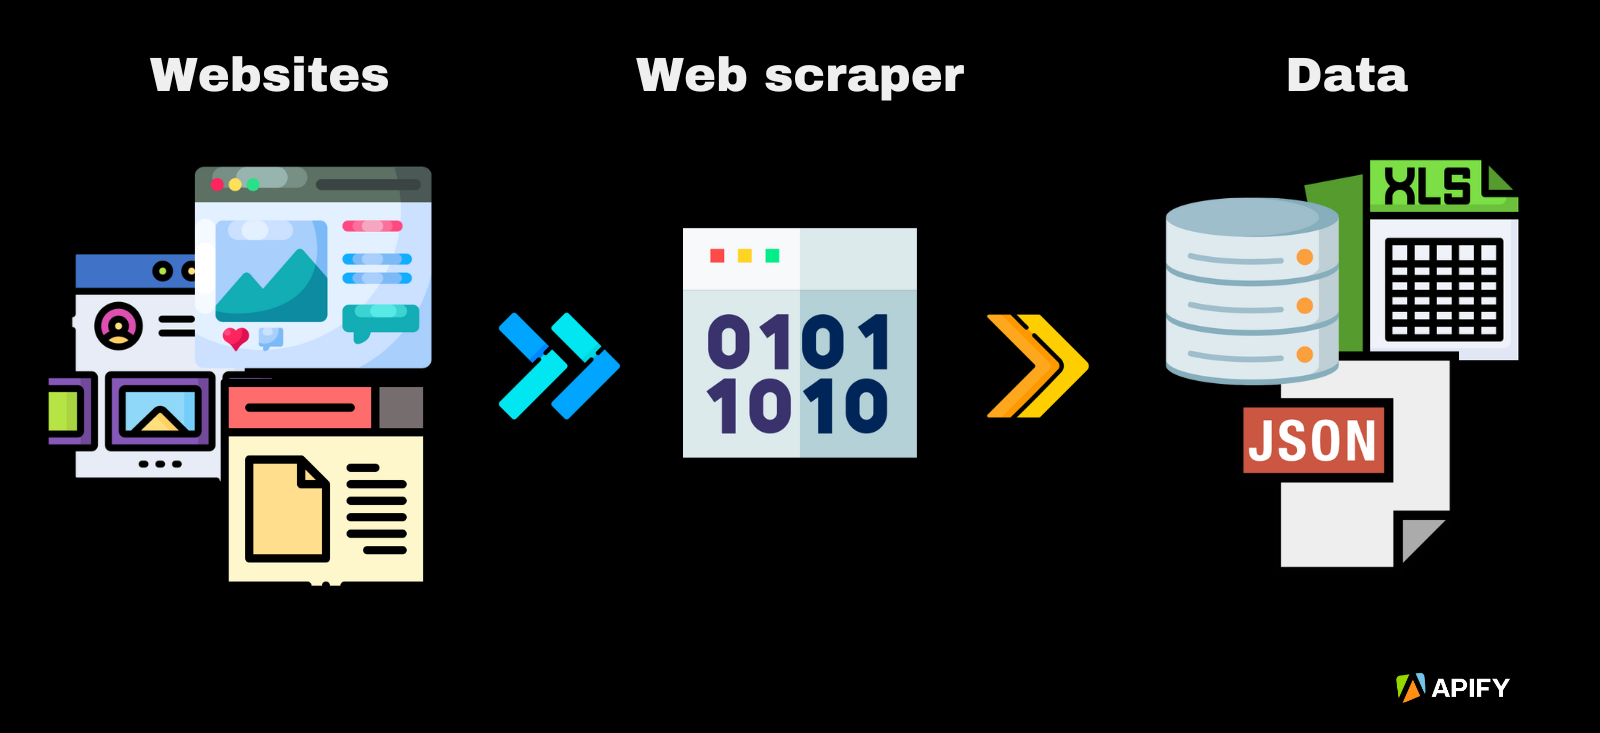
Website scraping is a sophisticated form of data collection that leverages software to interact with web servers and retrieve content. Unlike manual copy-pasting, which is time-consuming and error-prone for large datasets, scraping automates the entire process, allowing for the efficient acquisition of information at scale.
Defining Website Scraping
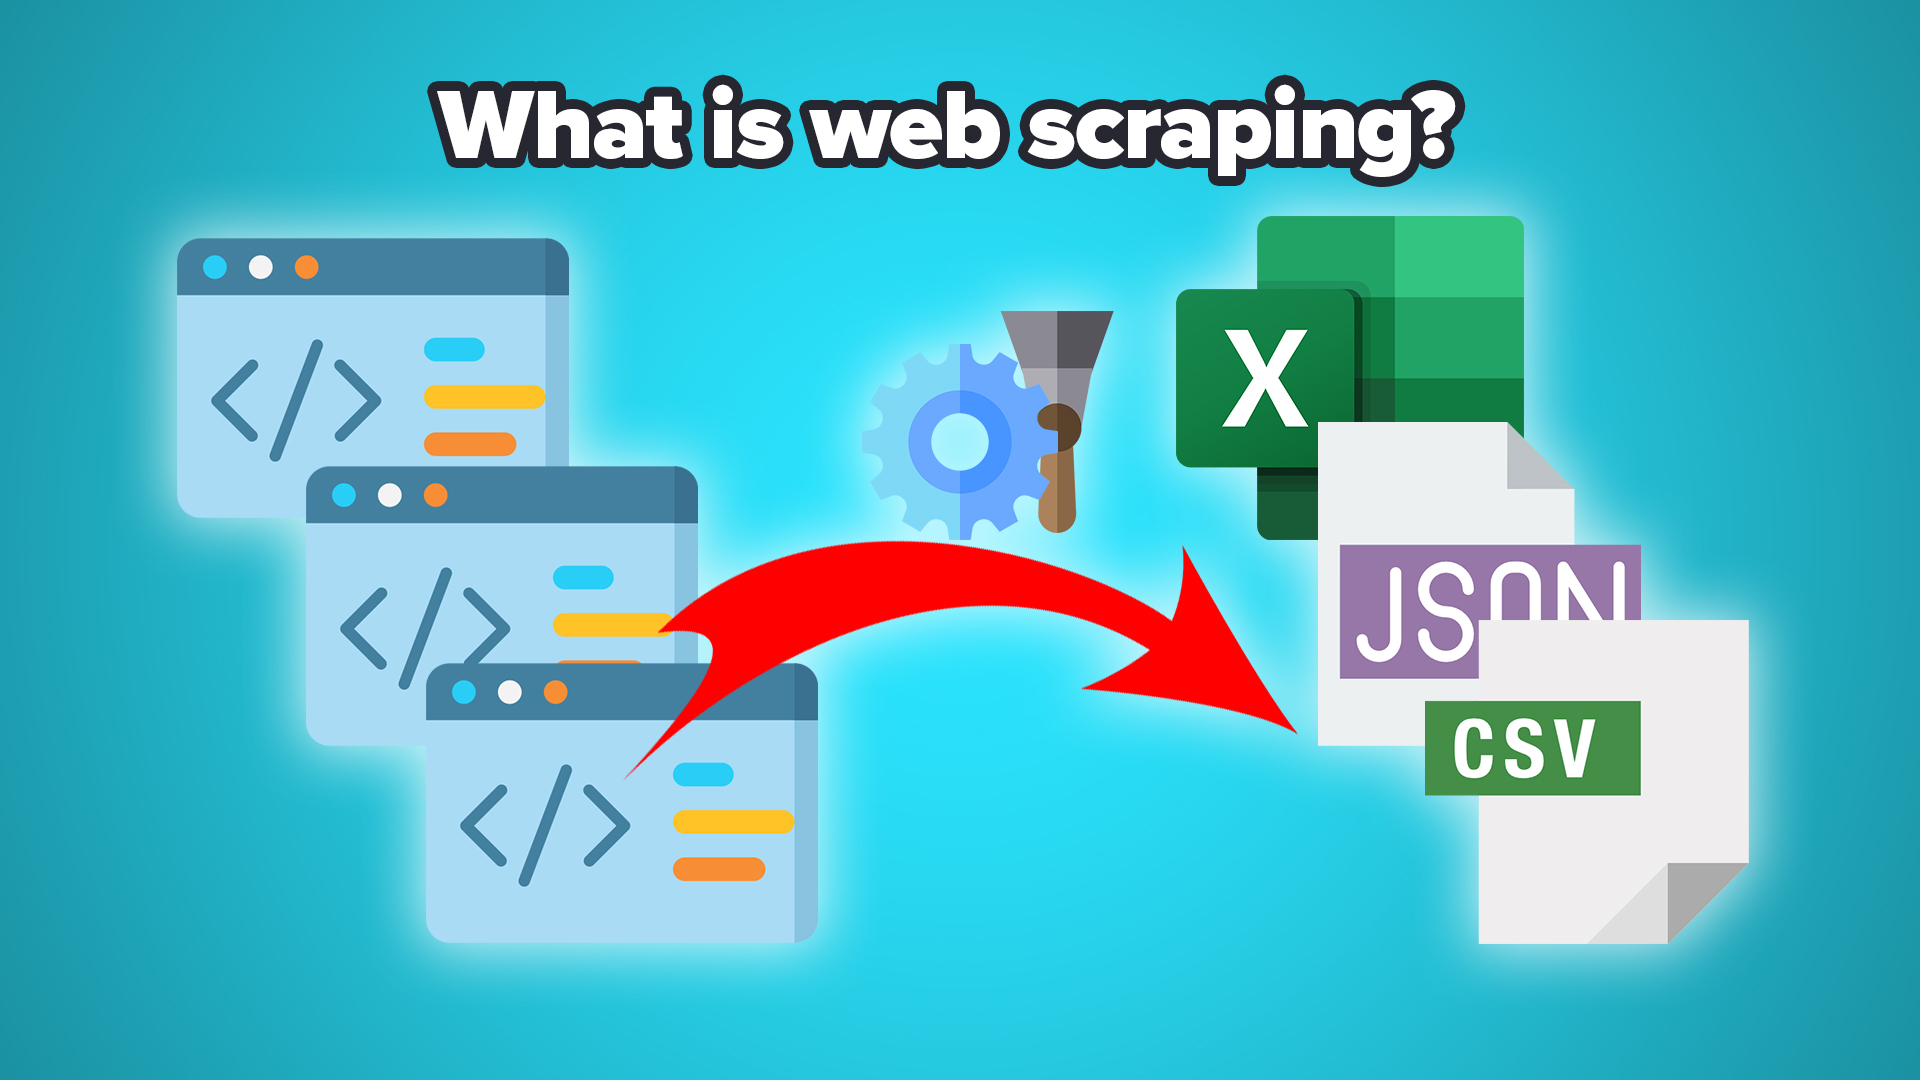
Website scraping refers to the use of bots or web crawlers to download and parse content from web pages. The goal is typically to extract specific pieces of data—be it text, images, links, or numerical figures—and organize them into a structured format, such as a CSV file, a database, or a JSON document. This process stands in contrast to using Application Programming Interfaces (APIs), which are explicitly designed by website owners to allow programmatic access to their data in a clean, pre-defined format. When an API is available, it is almost always the preferred method for data retrieval due to its reliability and adherence to terms of service. However, many websites do not offer public APIs for all their data, or the available APIs might not provide the exact data points required, making web scraping a necessary alternative.
How Website Scraping Works
The underlying mechanism of website scraping involves several steps that mimic how a web browser renders a page:
- Request: The scraper sends an HTTP GET request to a specific URL, just like a browser does when you type an address into the search bar. The web server responds by sending back the HTML content of the page.
- Download: The scraper receives and downloads the entire HTML document, along with any associated CSS, JavaScript, and image files that constitute the web page.
- Parse: This is the crucial step where the scraper analyzes the downloaded HTML. Using various parsing techniques, it navigates through the document’s structure (its Document Object Model or DOM) to locate the specific data elements of interest. This often involves identifying HTML tags, class names, IDs, or XPath/CSS selectors that uniquely point to the desired information.
- Extract: Once the data elements are identified, the scraper extracts them. This could mean extracting text content from a paragraph tag, the
srcattribute from an image tag, or thehrefattribute from a hyperlink. - Store: The extracted data is then stored in a structured format. This could be a simple spreadsheet, a relational database, or a NoSQL database, depending on the volume and nature of the data and the intended use.
- Iteration (Crawling): For more complex scraping tasks that involve multiple pages (e.g., all products in an e-commerce category or all articles on a news site), the scraper might identify links to other relevant pages and repeat the request-download-parse-extract-store cycle, effectively “crawling” through the website.
Modern web pages often use JavaScript to dynamically load content, presenting a challenge for simple HTTP request-based scrapers. In such cases, advanced scraping tools might employ headless browsers (web browsers without a graphical user interface) to execute JavaScript and render the page before parsing its content, thereby accessing data that would otherwise be unavailable.
Key Components and Technologies
The field of website scraping is supported by a rich ecosystem of programming languages, libraries, and tools, each offering unique advantages for different scraping scenarios.
Programming Languages and Libraries
Python is widely regarded as the most popular language for web scraping due to its simplicity, extensive libraries, and strong community support. Key Python libraries include:
- Requests: For making HTTP requests to download web page content.
- Beautiful Soup: A powerful library for parsing HTML and XML documents, making it easy to navigate and search the parse tree.
- Scrapy: A comprehensive, open-source web crawling framework designed for large-scale and complex scraping projects, offering built-in features for handling requests, parsing, and data storage.
- Pandas: Essential for data manipulation and analysis once data has been extracted, allowing for easy export to various formats.
Other languages like Node.js (with libraries such as Cheerio and Puppeteer) and Ruby (with libraries like Mechanize and Nokogiri) are also used, particularly in environments where these languages are already dominant.
Parsing Techniques
Effective parsing is fundamental to successful data extraction. Common techniques include:
- CSS Selectors: These are patterns used to select HTML elements based on their ID, class, type, attributes, or position in the DOM tree. They are intuitive and widely used due to their similarity to CSS styling.
- XPath (XML Path Language): A query language for selecting nodes from an XML document, which HTML is a type of. XPath offers more power and flexibility than CSS selectors for complex selections, especially when navigating non-standard or deeply nested structures.
- Regular Expressions (Regex): Powerful for pattern matching within text strings. While less suitable for navigating complex HTML structures, regex can be invaluable for extracting specific data patterns (e.g., dates, phone numbers, email addresses) from text content after an element has been isolated.
Browser Automation Tools
For websites that heavily rely on JavaScript to render content or involve complex user interactions (like logins, button clicks, or form submissions), traditional request-based scraping falls short. Browser automation tools come to the rescue by controlling a web browser programmatically.
- Selenium: A widely used tool for automating web browsers. It can control browsers like Chrome, Firefox, and Edge, allowing scrapers to simulate real user interactions, execute JavaScript, wait for elements to load, and navigate dynamic web pages.
- Puppeteer: A Node.js library that provides a high-level API to control headless Chrome or Chromium. It’s excellent for dynamic content rendering, generating screenshots, and automating form submissions.
- Playwright: Developed by Microsoft, Playwright is similar to Puppeteer but supports multiple browsers (Chromium, Firefox, and WebKit) with a single API, offering robust automation capabilities.
These tools enable scrapers to handle dynamic content, infinite scrolling, and AJAX requests, making them indispensable for extracting data from modern, interactive web applications.
Common Applications and Use Cases
The versatility of website scraping makes it a valuable tool across numerous industries and domains, driving innovation and providing actionable insights.
Market Research and Competitive Analysis
Businesses frequently use web scraping to monitor market trends, analyze competitor strategies, and inform their own pricing and product development. This includes:
- Price Monitoring: Tracking product prices across various e-commerce sites to adjust pricing strategies dynamically.
- Product Research: Gathering data on product features, specifications, and customer reviews to identify market gaps or improve existing offerings.
- Competitor Intelligence: Scraping public data about competitors’ marketing campaigns, job postings, and news mentions to gain insights into their operations.
Data Aggregation and Content Curation
Scraping is essential for services that aggregate information from multiple sources:
- News Aggregators: Collecting articles from various news outlets to provide a consolidated news feed.
- Job Boards: Compiling job listings from company career pages and other recruitment platforms.
- Real Estate Listings: Aggregating property data from multiple listing services to offer a comprehensive search experience.
- Travel and Accommodation Sites: Collecting flight prices, hotel availability, and rental car rates from different providers.
Lead Generation and Sales Intelligence
Sales and marketing teams leverage scraping to build targeted contact lists and gather intelligence:
- Contact Information: Extracting email addresses, phone numbers, and social media profiles from company websites or professional directories for outreach.
- Company Data: Collecting information about company size, industry, location, and key personnel to qualify leads.
Academic Research and Public Data Analysis
Researchers and analysts use scraping to build datasets for studies and public interest projects:
- Social Science Research: Analyzing public sentiment by scraping social media platforms or forums.
- Economic Research: Collecting economic indicators, financial reports, or stock market data.
- Environmental Monitoring: Gathering publicly available environmental data from government agencies or research institutions.
Ethical Considerations and Legal Landscape
While website scraping offers immense benefits, it operates in a legally and ethically complex landscape. Navigating these waters responsibly is crucial to avoid potential legal issues and maintain a positive reputation.
Respecting robots.txt and Terms of Service
The robots.txt file is a standard protocol that websites use to communicate with web crawlers and other bots, specifying which parts of the site they are allowed or disallowed to access. While not legally binding in all jurisdictions, ignoring robots.txt is generally considered unethical and can be a strong indicator of malicious intent.
Similarly, every website has a “Terms of Service” (ToS) or “Terms of Use” agreement. Many ToS explicitly prohibit automated data collection or scraping. Violating a website’s ToS, especially when it results in unauthorized access or data misuse, can lead to legal action, including claims for breach of contract or even computer fraud.
Data Privacy and Copyright Infringement
Scraping personal identifiable information (PII) raises significant data privacy concerns, particularly under regulations like GDPR (General Data Protection Regulation) and CCPA (California Consumer Privacy Act). Even if the data is publicly available, its automated collection and subsequent use must adhere to privacy laws. Misusing scraped PII can lead to severe penalties and reputational damage.
Furthermore, copyright law protects the original content published on websites. Scraping large volumes of copyrighted text, images, or other media and republishing it without permission can constitute copyright infringement. The “fair use” doctrine may offer some protection, but its applicability depends heavily on the context and purpose of the scraping.
Anti-Scraping Measures and Their Impact
Website owners actively deploy various anti-scraping measures to protect their data and server resources. These include:
- CAPTCHAs: Requiring human verification to access content.
- IP Blocking: Blocking IP addresses that exhibit suspicious behavior (e.g., too many requests in a short period).
- User-Agent String Checks: Detecting non-browser user-agent strings.
- Dynamic Content: Using JavaScript to render content, making it harder for simple scrapers.
- Honeypot Traps: Invisible links designed to catch bots, leading to IP bans.
Bypassing these measures can escalate the ethical and legal risks, potentially crossing the line from simple data collection to unauthorized access or cyber trespass, which carry more severe legal consequences. Responsible scraping often involves rate limiting, rotating IP addresses, and respecting site policies to avoid being blocked and to minimize strain on the target server.
The Future of Data Extraction
The landscape of data extraction is continuously evolving, driven by advancements in artificial intelligence and the increasing demand for real-time information.
AI and Machine Learning in Scraping
Artificial intelligence and machine learning are revolutionizing web scraping by making it more robust and intelligent. AI-powered scrapers can:
- Adapt to Website Changes: Traditional scrapers often break when a website’s layout changes. AI models can learn to identify data elements based on context and semantics, making them more resilient to minor structural alterations.
- Handle Unstructured Data: Machine learning algorithms can process and extract meaningful information from highly unstructured text, transcending the limitations of rule-based parsing.
- Sentiment Analysis: Beyond just extracting text, AI can perform sentiment analysis on scraped reviews or social media posts, providing deeper insights into public opinion.
- Automated Data Labeling: AI can assist in automatically labeling and categorizing extracted data, streamlining the post-scraping processing.
These advancements promise more reliable, autonomous, and insightful data extraction capabilities, reducing the manual effort required to maintain scrapers and extract complex information.
Real-time Data Streams and APIs
The trend toward real-time data is pushing the boundaries of traditional batch scraping. Businesses increasingly need immediate access to information for dynamic pricing, instant fraud detection, or real-time market analysis. While continuous scraping can approximate real-time, the ideal solution often lies in well-designed APIs.
As websites and services recognize the value of sharing data in a controlled manner, the proliferation of robust and well-documented APIs is a positive development. APIs offer a structured, reliable, and ethically sound method for data exchange, reducing the need for extensive scraping efforts. The future likely holds a hybrid approach: leveraging APIs where available for critical, structured data, and deploying advanced, AI-driven scrapers for unique, unstructured, or niche data points where no API exists. The goal remains consistent: efficient, accurate, and actionable data acquisition to fuel innovation and informed decision-making.