
The Algorithmic Pursuit of Lexical Patterns
In an era increasingly defined by computational prowess and sophisticated data analysis, seemingly simple linguistic queries like “what is a 5 letter word” transcend their basic nature, becoming a fascinating touchstone for examining the capabilities of modern technology and innovation. Far from a trivial parlor game, the automated identification and generation of words based on specific criteria represent a fundamental challenge and a significant achievement within computer science, particularly in the fields of natural language processing (NLP) and artificial intelligence (AI). The underlying mechanisms that allow systems to process such a request involve intricate algorithms designed to navigate vast lexical databases, apply specific constraints, and return relevant outputs with remarkable speed and accuracy.
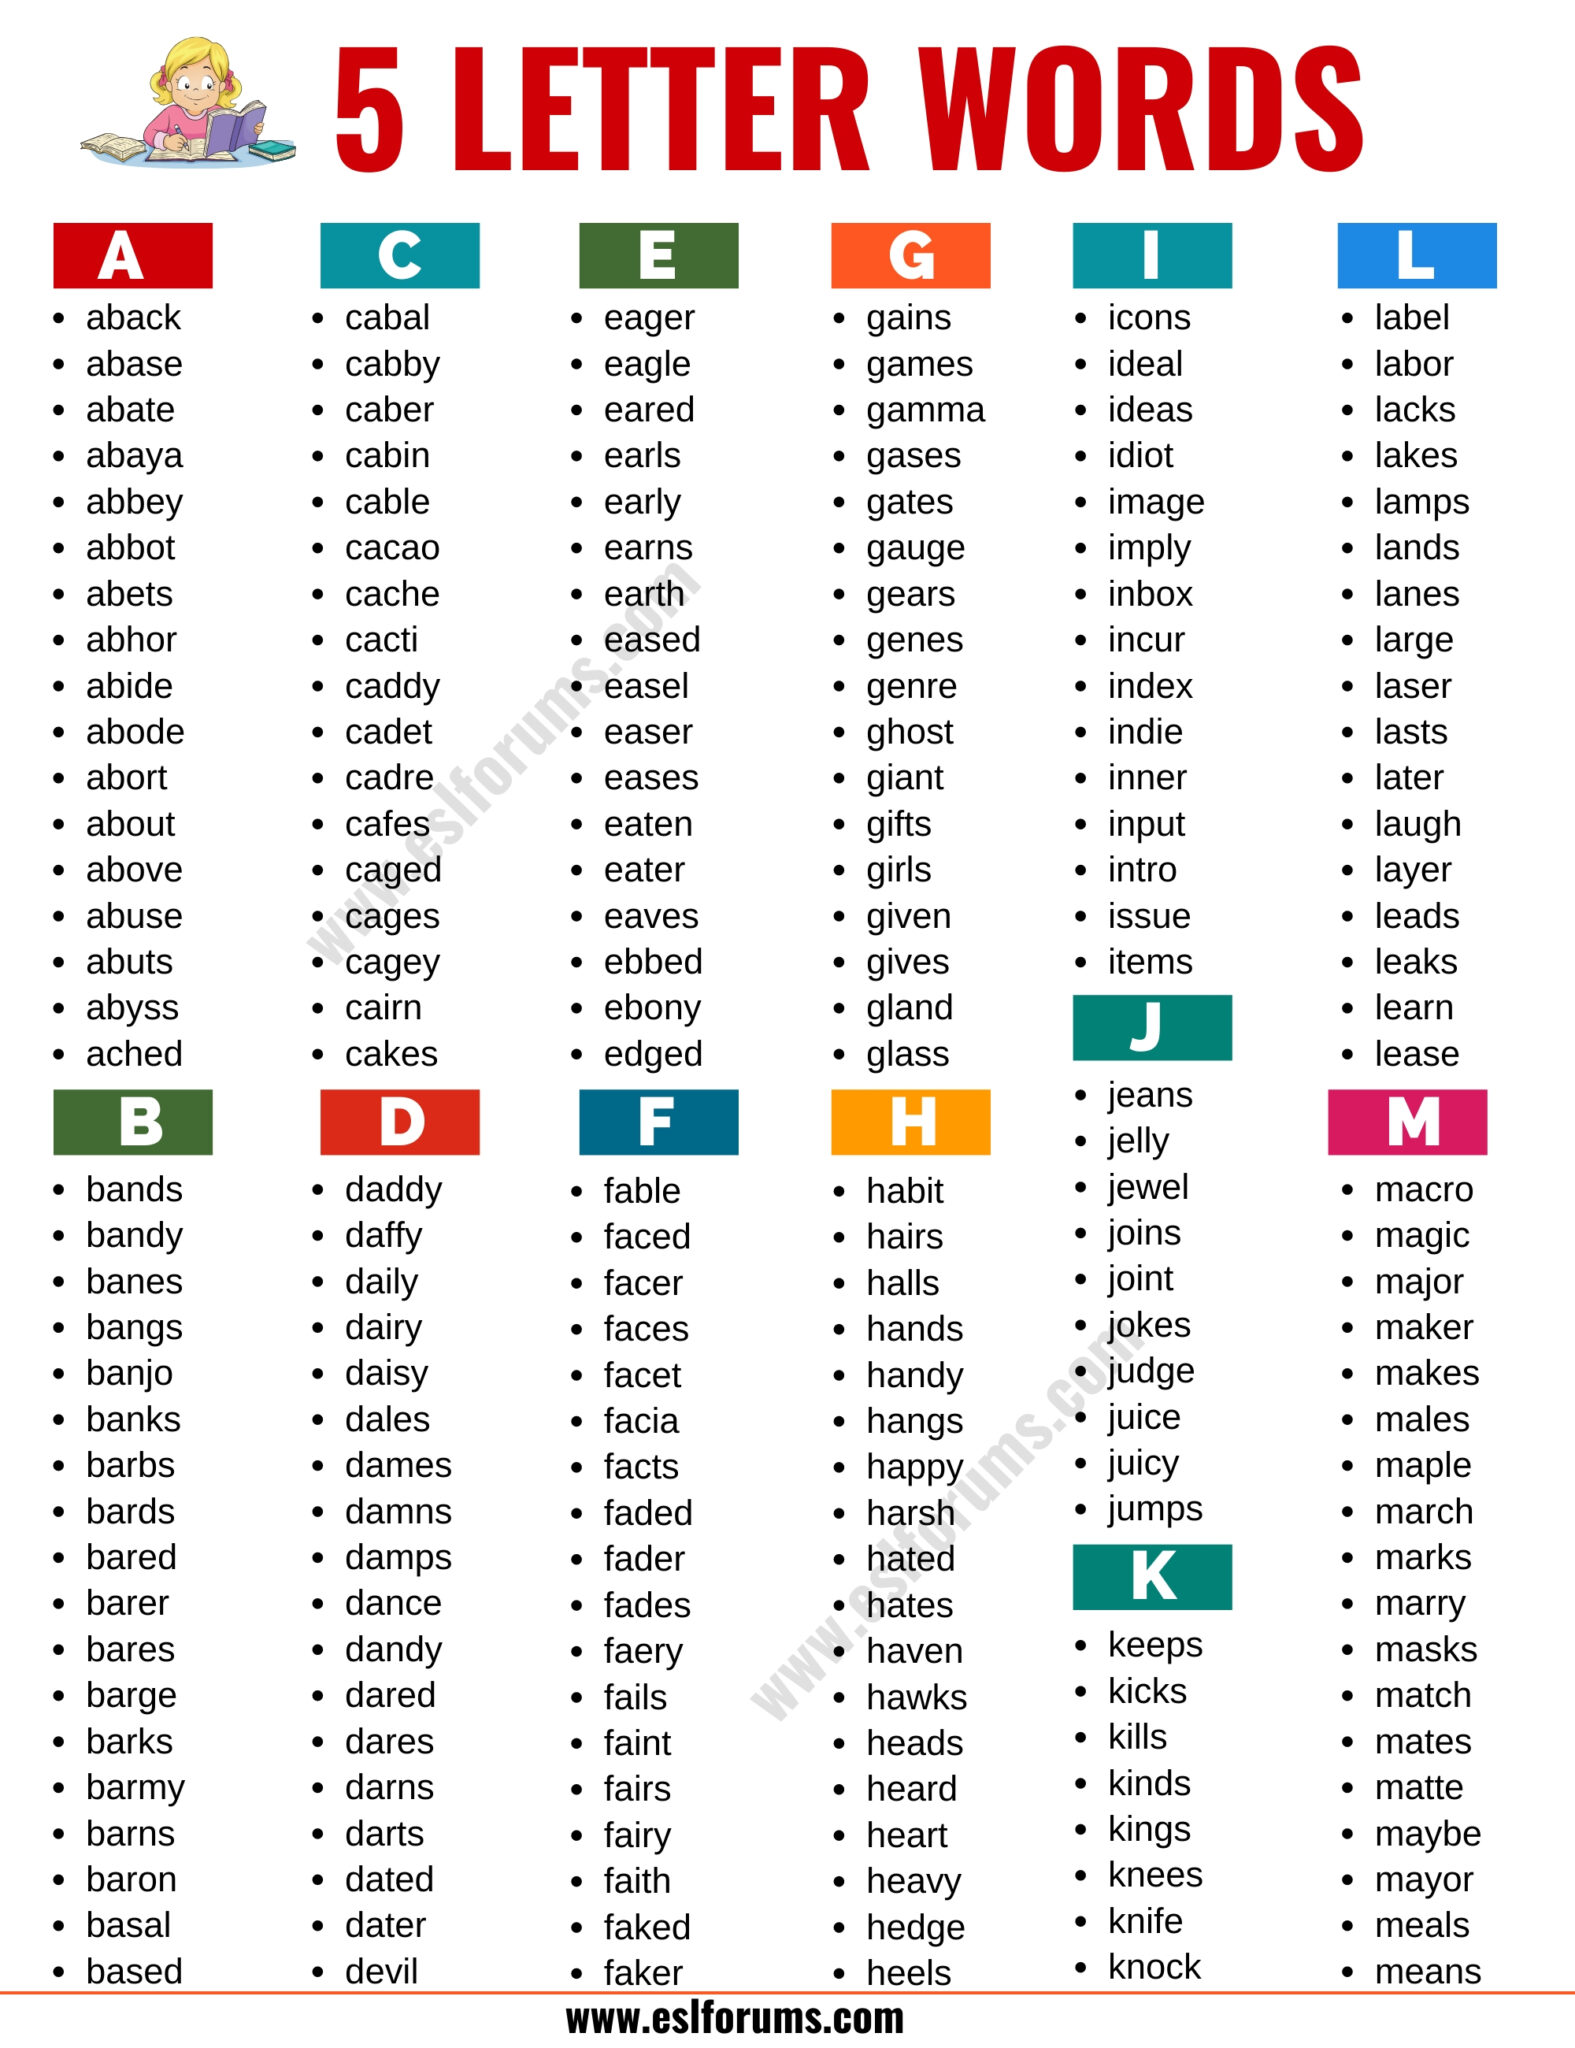
At its core, addressing “what is a 5 letter word” computationally begins with access to comprehensive dictionaries or lexical datasets. These datasets are not merely lists; they are often structured databases, allowing for efficient querying based on attributes like word length, starting letters, letter patterns, and even semantic categories. The innovation lies in how these datasets are built, maintained, and, crucially, how algorithms are engineered to extract information from them. Early approaches might have involved brute-force scanning, but contemporary methods employ advanced data structures like hash tables, tries (prefix trees), or inverted indices, which drastically reduce the search space and execution time. For instance, a trie can quickly prune branches of words that do not match the desired length or pattern, ensuring that only relevant possibilities are explored.
Moreover, the challenge extends beyond mere matching. Modern systems often incorporate linguistic rules and statistical models to enhance relevance. For example, if the query were implicitly contextualized (e.g., “what is a 5 letter word for joy?”), the system would need to apply semantic filters, drawing upon knowledge graphs or word embeddings that map words to their meanings and relationships. This transition from purely syntactic (length, pattern) to semantic understanding marks a significant leap in technological capability, driven by continuous innovation in algorithm design and data representation. The development of efficient search algorithms, combined with intelligently organized linguistic resources, underpins the ability of search engines, spell checkers, and virtual assistants to effortlessly fulfill such requests, making the complexity largely invisible to the end-user. The iterative refinement of these algorithms continues, pushing the boundaries of how efficiently and intelligently machines can interact with human language.
Artificial Intelligence and Natural Language Processing (NLP)
The evolution of technology in understanding and responding to linguistic queries finds its most advanced expression within Artificial Intelligence and Natural Language Processing (NLP). The seemingly straightforward task of identifying a “5 letter word” becomes a sophisticated demonstration of how AI systems interpret human intent, access knowledge, and formulate responses. NLP is the branch of AI that enables computers to understand, interpret, and generate human language in a valuable way. For a query like this, NLP frameworks analyze the structure of the question, identify key parameters (word length, implicit context), and then leverage vast linguistic models to derive an appropriate answer.
From Rule-Based Systems to Deep Learning
Initially, NLP systems relied heavily on rule-based approaches, where explicit grammatical rules and dictionaries guided the processing of language. For a simple query about word length, a rule-based system could parse the sentence, identify “5 letter word” as the core request, and then query a pre-indexed dictionary for entries matching that length. While effective for well-defined tasks, these systems were brittle, struggling with ambiguity, nuance, and the vast irregularities of human language.
The paradigm shifted dramatically with the advent of machine learning and, more recently, deep learning. Modern NLP is dominated by neural networks, particularly transformer architectures, which power large language models (LLMs). These models are trained on colossal datasets of text and code, enabling them to learn intricate patterns, grammatical structures, semantic relationships, and even contextual nuances without explicit programming for every rule. When faced with “what is 5 letter word,” an LLM doesn’t just perform a database lookup; it understands the intent behind the query. It recognizes the request for a lexical item of a specific length and can then generate examples based on its learned understanding of vocabulary, frequency, and typical usage. This is a profound difference, moving from mechanical lookup to an inferential generation based on probabilistic understanding. The innovation here is not just in scale, but in the qualitative leap in language comprehension and generation capabilities.
The Role of Semantic Understanding
Beyond simply identifying words by their length, advanced AI systems leverage semantic understanding to provide more intelligent and relevant responses. While the prompt “what is 5 letter word” is simple, an AI might infer, based on a user’s past interactions or current context, that the user is looking for a common word, a word related to a specific topic, or even a word for a puzzle. This involves tapping into semantic networks, ontologies, and word embeddings that represent words not just as symbols, but as vectors in a multi-dimensional space where closeness indicates semantic similarity.
For instance, if a user asks for a “5 letter word” immediately after discussing “travel,” an AI might prioritize words like “plane,” “train,” or “hotel,” even without explicit mention of relatedness. This context-aware understanding is a hallmark of sophisticated AI, built upon innovations in neural network architectures that can process sequential data (like sentences) and maintain state or memory of previous interactions. The ability to link a simple structural query to a rich tapestry of meaning transforms the interaction from a mere data retrieval exercise into a more conversational and intelligent exchange, pushing the boundaries of human-computer interaction.

Innovation in Linguistic Data Analysis
The ability to answer a query like “what is 5 letter word” with accuracy, speed, and contextual relevance relies heavily on profound innovations in linguistic data analysis. Beyond the algorithms, the very nature of how language data is collected, organized, and made accessible has undergone a revolutionary transformation. These advancements enable technologies that go far beyond simple word searches, underpinning everything from predictive text to complex semantic understanding in AI. The scale and sophistication of modern linguistic data analysis are critical enablers for contemporary tech and innovation.
Lexical Databases and Their Applications
At the heart of any system capable of processing language are lexical databases. These are not just digitized dictionaries; they are highly structured, annotated repositories of words, phrases, and their associated linguistic properties. Innovations in database design and management have allowed for the creation of vast, multilingual lexical resources that can store not only word forms and definitions but also phonetic transcriptions, etymologies, grammatical tags (part of speech, tense, gender), frequency statistics, and even sentiment scores.
For a query about a “5 letter word,” a well-indexed lexical database can instantly filter words by length. But its utility extends far beyond this. Applications include:
- Spell Checkers and Grammar Correctors: Leveraging frequency data and common misspellings to suggest corrections.
- Machine Translation: Mapping words and phrases across languages, informed by parallel corpora within the database.
- Information Retrieval: Enhancing search engine relevance by understanding synonyms, hyponyms, and hypernyms.
- Text Generation: Providing a vocabulary base and grammatical rules for AI models to construct coherent sentences.
- Digital Humanities: Enabling researchers to perform large-scale textual analysis, identifying linguistic trends and patterns over time.
The continuous development of standards for lexical encoding (e.g., WordNet, FrameNet) and the creation of open-source projects have democratized access to these rich linguistic resources, fostering further innovation across various applications. The ability to query these databases not just for exact matches but for words meeting specific criteria (like a given length) is a foundational capability built upon decades of data science and computational linguistics.
Predictive Text and Autocompletion
One of the most ubiquitous innovations stemming from linguistic data analysis is predictive text and autocompletion, familiar features in smartphones, search engines, and word processors. While seemingly simple, these functionalities are powered by sophisticated statistical models and machine learning algorithms trained on massive text corpora. When you type “wha” and your phone suggests “what,” it’s not just guessing; it’s drawing on probabilities derived from analyzing billions of sentences to determine the most likely next word or completion.
For predicting a “5 letter word” in a given context, these systems leverage N-gram models (sequences of N words) or, more recently, neural language models that capture long-range dependencies and complex semantic relationships. If a user is typing a crossword puzzle hint, for example, and has already typed “ocean ____,” an intelligent autocompletion system might suggest “beach” or “floor” if it has learned those patterns. The system doesn’t just store every possible word; it learns the likelihood of words appearing together, their typical lengths in certain contexts, and their semantic fit. This represents a dynamic, probabilistic approach to lexical prediction, a stark contrast to static dictionary lookups. The constant innovation in optimizing these models for speed, accuracy, and reduced computational footprint on various devices highlights a key area of ongoing technological advancement in linguistic data analysis.
The Broader Implications for Tech and Cognition
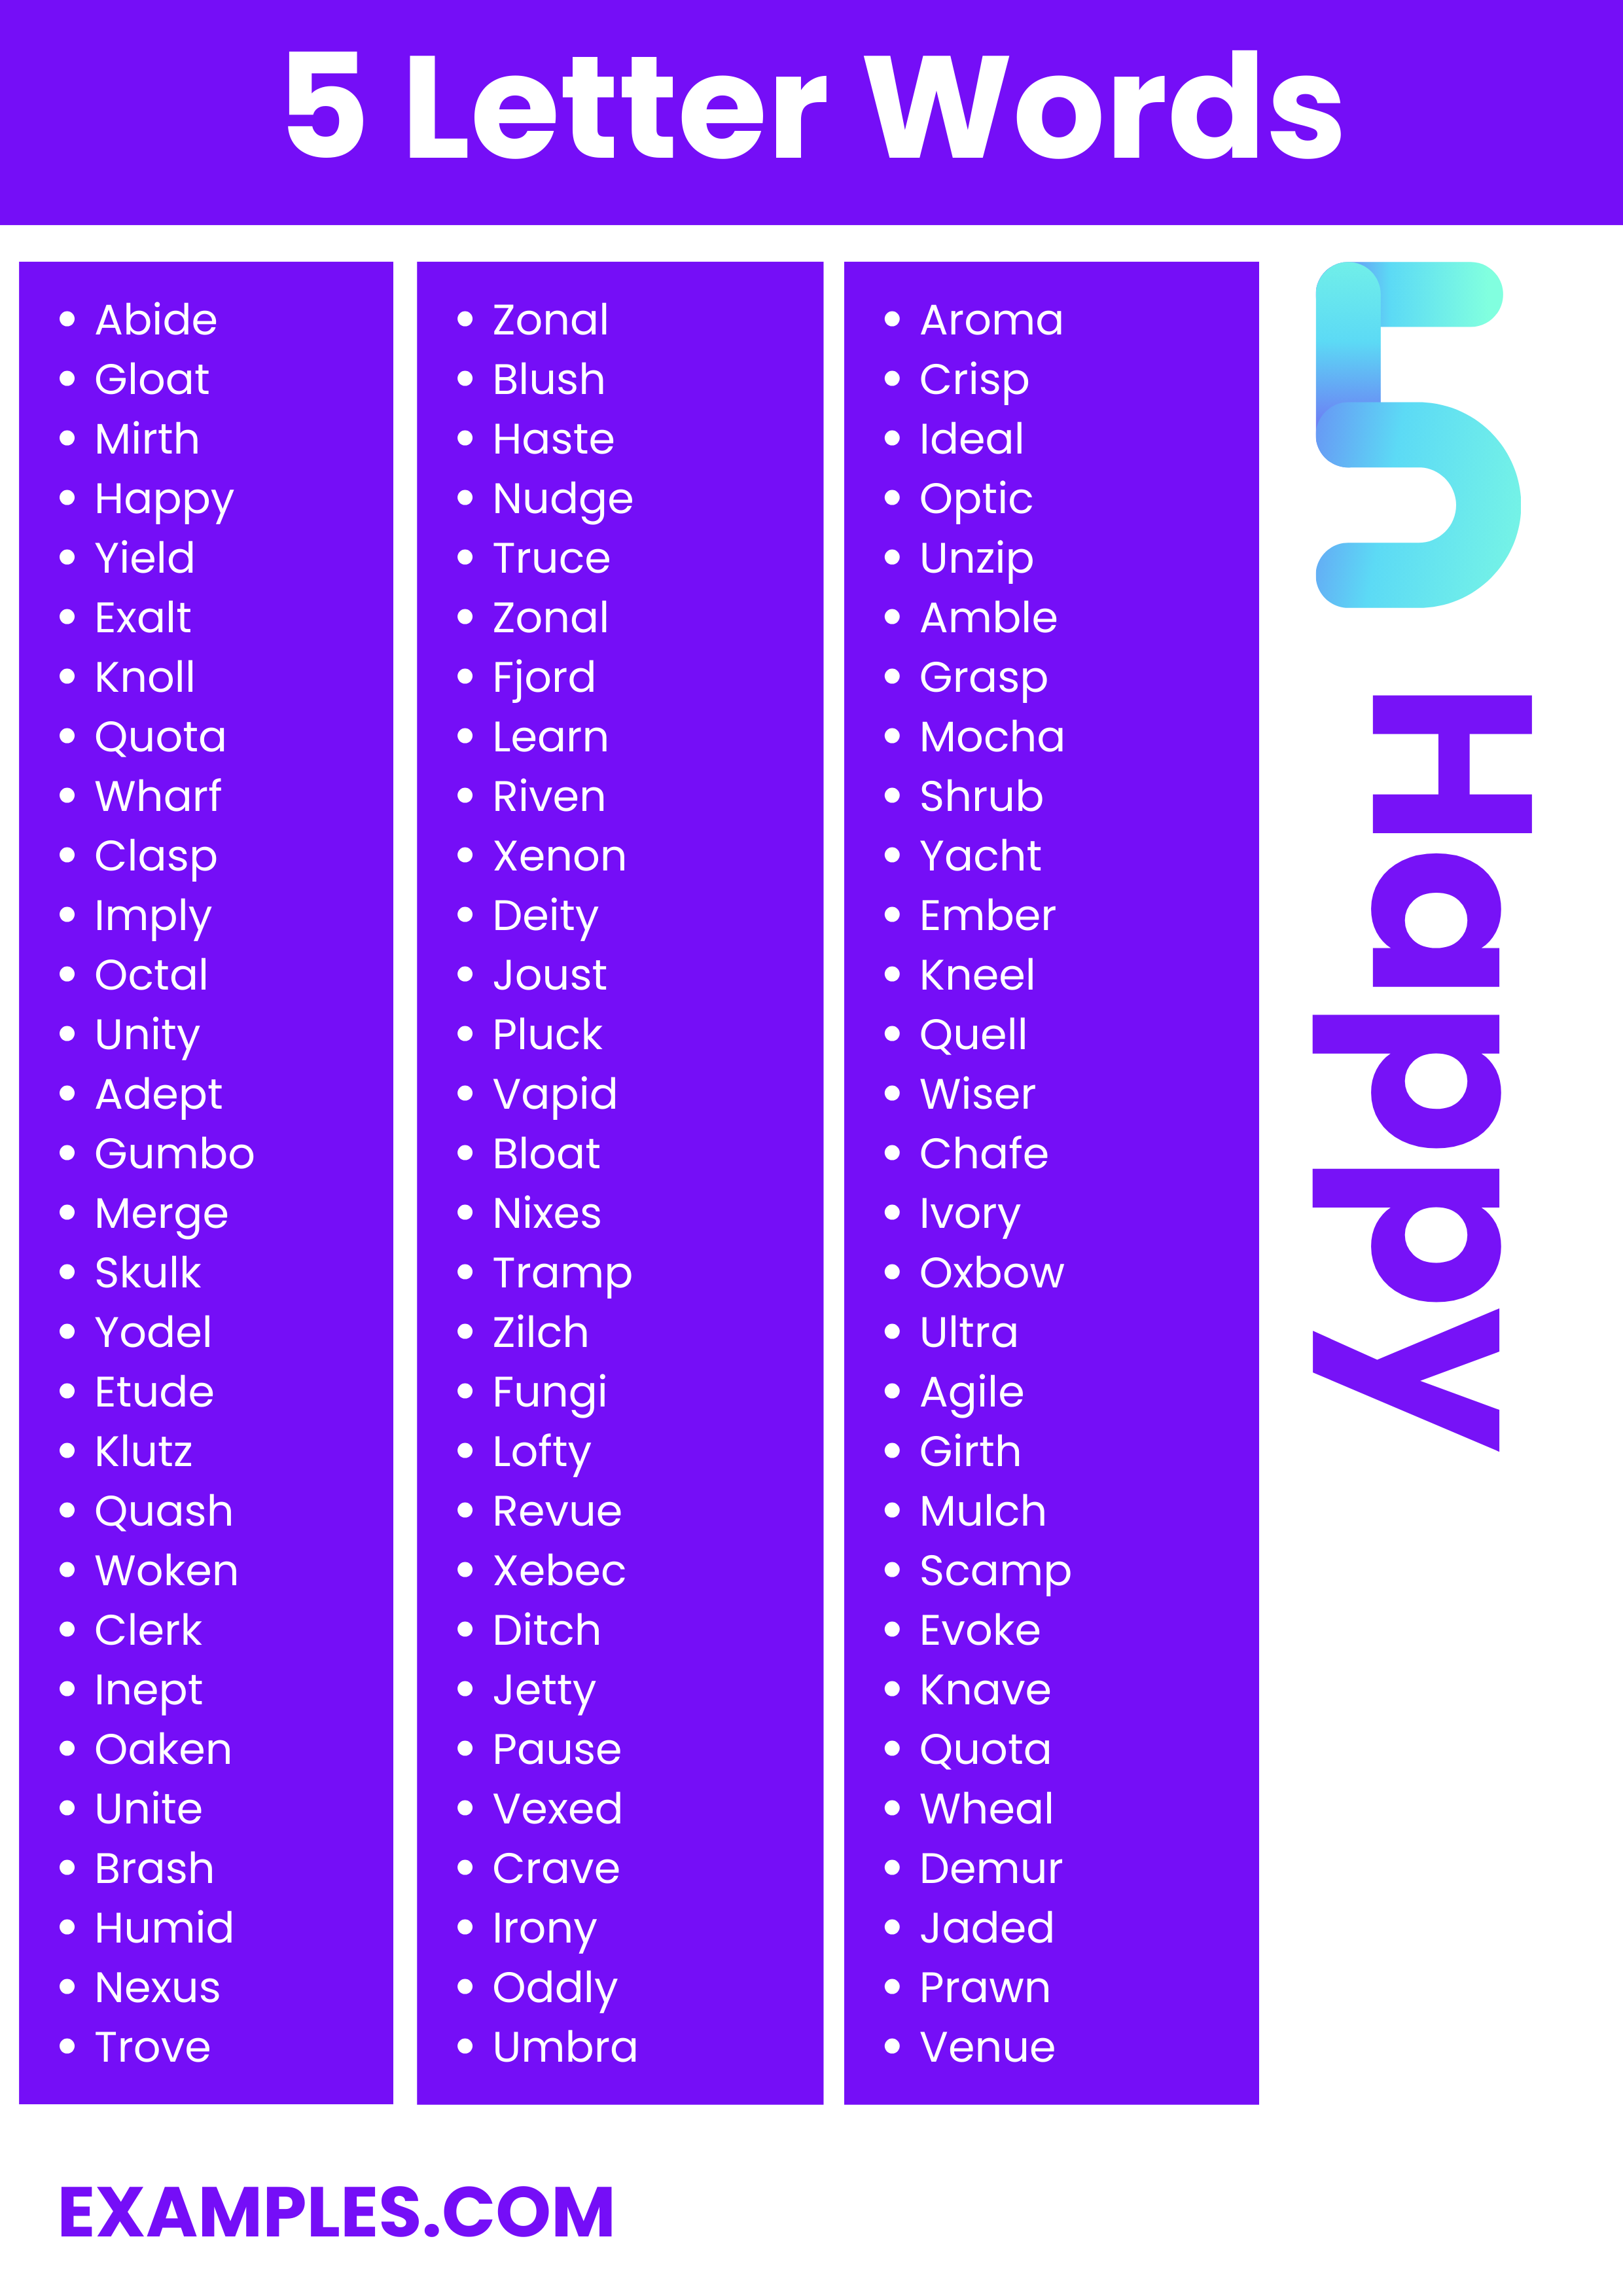
The ability of technology to process and respond to a query as deceptively simple as “what is 5 letter word” offers a microcosm into the broader implications for technological advancement and our understanding of human cognition. This fundamental capacity to manipulate and understand language is not merely a utility; it’s a cornerstone for more complex AI functionalities, influencing everything from advanced search to the development of truly conversational agents. It underscores the profound journey from rudimentary pattern matching to sophisticated semantic reasoning that characterizes modern tech innovation.
The advancements in efficiently querying lexical datasets, applying linguistic constraints, and generating contextually relevant word suggestions are foundational to AI’s push into more nuanced cognitive tasks. Consider the role of such capabilities in AI-driven content generation, where systems are tasked with creating text that adheres to specific stylistic, thematic, and even structural parameters. An AI designing a poem, for instance, might need to find a 5-letter word that rhymes with a preceding word and fits a particular emotional tone. This moves far beyond simple retrieval, requiring a synthesis of linguistic knowledge, creative rules, and contextual awareness—all built upon the same basic principles of lexical understanding.
Furthermore, the continuous improvement in AI’s ability to handle such linguistic tasks informs our understanding of human cognition itself. How do humans intuitively recognize a “5-letter word” or generate one that fits a specific criterion? By building and refining AI models that mimic these processes, researchers gain insights into the cognitive architectures that govern human language acquisition, memory, and creative problem-solving. When an AI can not only list 5-letter words but also infer the user’s implicit intent or provide words relevant to a subtle context, it sheds light on the complex interplay of explicit rules, probabilistic inference, and associative memory that characterizes human thought.
Ultimately, the journey from a simple dictionary lookup to sophisticated natural language understanding reflects a continuous innovation cycle. Each step forward in processing straightforward linguistic queries enhances AI’s capacity to tackle ambiguity, context, and nuance—qualities inherent in human communication. This ongoing evolution in language-centric technologies promises a future where human-computer interaction becomes ever more seamless, intuitive, and truly intelligent, transcending mere command-and-response mechanisms to engage in genuine dialogue and collaborative problem-solving. The seemingly minor question, “what is 5 letter word,” thus serves as a powerful indicator of the vast and exciting landscape of innovation in AI and our quest to replicate, and perhaps even augment, human cognitive abilities.