
The Foundational Protocol for Autonomous Agents
In an increasingly automated world, where intelligent systems and autonomous agents operate across various domains, the necessity for clear communication protocols is paramount. One of the earliest and most enduring examples of such a protocol, defining the operational guidelines for automated entities in a digital environment, is the robots.txt file. Far from a niche technical detail, robots.txt represents a fundamental concept in the governance of autonomous systems, illustrating how rulesets can be established to direct, restrict, or optimize the behavior of bots. This simple text file, residing at the root of a website’s directory, serves as a directive for web crawlers—a specific type of autonomous agent often referred to as web robots or spiders—telling them which parts of the site they are permitted or forbidden to access. Understanding robots.txt offers insight into the broader principles of managing automated interactions, data access, and resource allocation in the digital realm, concepts that echo across the spectrum of modern tech and innovation, from AI-driven data analysis to autonomous system navigation.
Defining Web Robots and Their Interactions
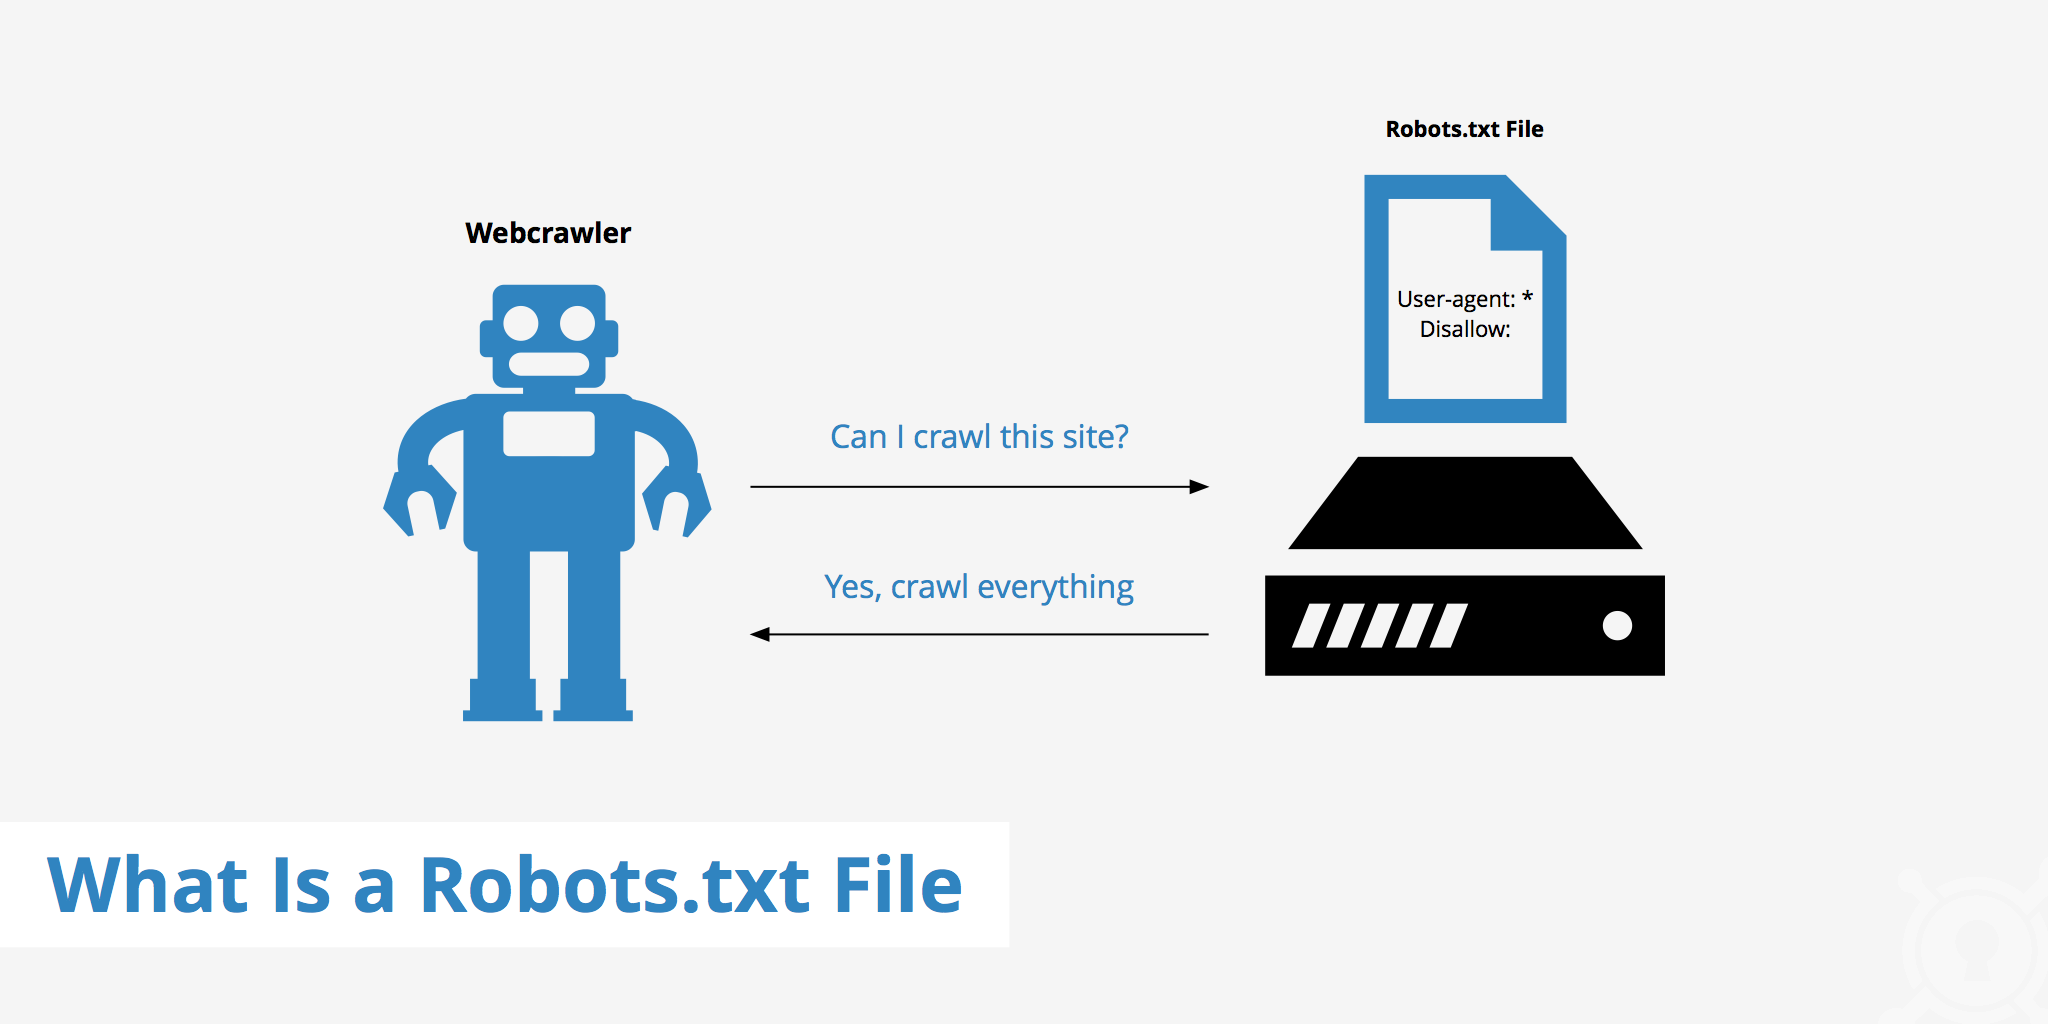
Web robots are automated software programs designed to traverse the internet, systematically indexing content, monitoring links, or gathering specific information. These autonomous agents are the backbone of search engines, competitive intelligence tools, and various data analysis platforms. Without them, the vastness of the internet would remain largely unindexed and undiscoverable. However, their unbridled operation could pose significant challenges, including server overload, unauthorized access to sensitive data, or the inefficient indexing of irrelevant or duplicate content. The robots.txt protocol emerged as a pragmatic solution to manage these interactions. It doesn’t legally enforce behavior but rather provides a set of widely accepted guidelines that well-behaved robots are programmed to respect. This voluntary compliance underscores a cooperative spirit in the digital ecosystem, where the benefits of mutual understanding outweigh the technical possibility of brute-forcing access.
The Core Function: Directing Automated Behavior
At its heart, robots.txt functions as a gatekeeper, guiding web robots on where they can and cannot go within a website. It’s not a security mechanism that prevents access entirely—a malicious bot can simply ignore it—but rather a critical instruction manual for ethical and efficient crawling. For developers and site administrators, this means granular control over how their digital content is processed by external autonomous systems. This control is vital for several reasons: protecting the privacy of certain data (e.g., user profiles, admin areas), preventing server strain from excessive requests to resource-intensive pages, and ensuring that only valuable, public-facing content is indexed by search engines. By strategically implementing robots.txt, organizations can optimize their digital footprint, enhance the discoverability of essential content, and safeguard internal operations from unintended robotic interference.
Structure, Syntax, and Strategic Implementation
The simplicity of robots.txt belies its strategic power. It’s a plain text file composed of specific directives that instruct user-agents—the identification names given to various web robots—on their permissible actions. Mastering its syntax is key to harnessing its capabilities for effective digital property management.
Disallow Directives and User-Agent Specificity
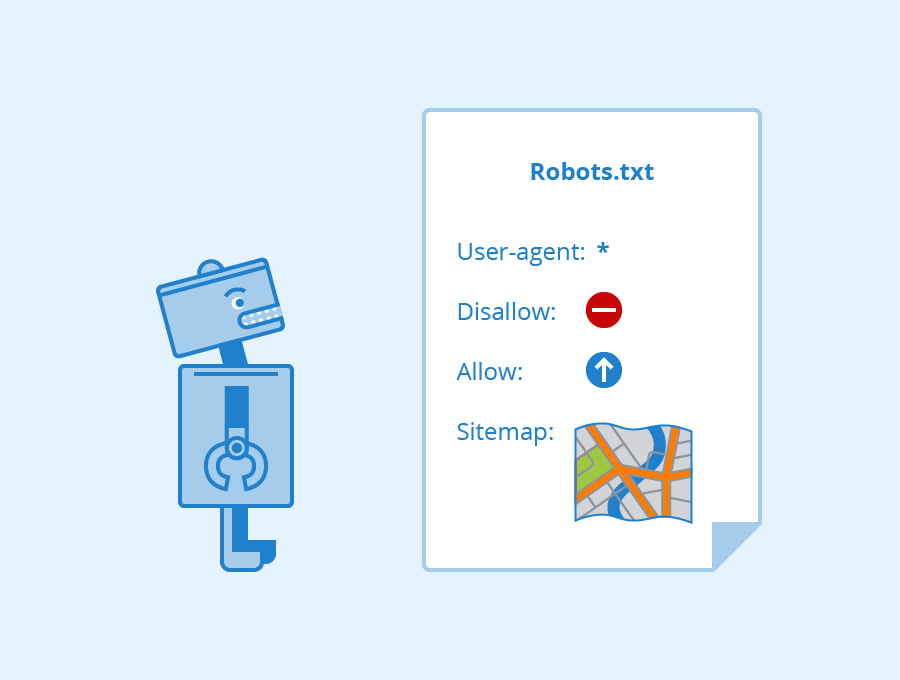
The primary directive within a robots.txt file is Disallow:, which specifies paths or directories that a user-agent should not access. For example, Disallow: /private/ would instruct compliant robots to avoid any content within the /private/ directory. This can be extended to specific files, query parameters, or even entire subdomains. Crucially, these directives can be tailored to specific user-agents. A User-agent: * directive applies to all robots, while User-agent: Googlebot targets only Google’s primary crawler. This specificity allows for fine-tuned control, enabling administrators to block certain bots from particular sections while permitting others. For instance, an image-crawling bot might be allowed access to /images/ but forbidden from /admin/, while a general search engine bot might be restricted from both. The careful balance of User-agent and Disallow statements ensures that only the desired autonomous systems interact with specific parts of a digital environment.
The Role of Sitemap Directives

Beyond simply restricting access, robots.txt also plays a constructive role in guiding autonomous agents towards valuable content through the Sitemap: directive. While not a blocking or disallowing instruction, Sitemap: provides a direct link to the site’s XML sitemap. A sitemap is essentially a map of all the pages and files on a website that the developer considers important. By pointing robots to this sitemap, site administrators can actively encourage efficient crawling and indexing of their desired content. This is particularly beneficial for large websites, newly launched sites, or sites with complex structures where automatic discovery might be challenging. The Sitemap: directive exemplifies a collaborative approach to autonomous system interaction, providing hints and directions that improve the efficiency of both the robot and the digital property it interacts with.
Implications for Data Management and Operational Efficiency
The seemingly simple robots.txt file has profound implications for data management strategies and the operational efficiency of both digital platforms and the autonomous systems that interact with them. Its principles resonate with broader challenges in managing complex, data-driven systems.
Controlling Access and Protecting Sensitive Information
One of the most critical applications of robots.txt is in controlling access to sensitive data and preventing its exposure through search engine indexing. While it’s not a foolproof security measure (it shouldn’t be relied upon to protect truly confidential data), it serves as a primary layer of defense against accidental public exposure. Websites often contain administrative panels, user-specific data, internal search results, or development environments that are not intended for public consumption or indexing. By disallowing these paths, organizations mitigate the risk of such information appearing in search results, thereby enhancing data privacy and security. This concept of clearly defined access boundaries for automated agents is fundamental in any domain dealing with sensitive information, whether it’s personal data on a website or sensor data collected by an autonomous system in a physical environment.
Optimizing Resource Utilization for Automated Systems
Autonomous agents, especially large-scale web crawlers, consume significant computational resources, including bandwidth and server processing power. An unoptimized or poorly managed crawling process can lead to server overload, slow website performance for human users, and increased operational costs. robots.txt offers a straightforward mechanism to prevent this by directing bots away from resource-intensive pages, dynamically generated content that offers little value to indexing, or duplicate content. For instance, blocking access to internal search results pages prevents robots from endlessly crawling combinations of search queries that provide no unique value. This optimization benefits both the website (by reducing server load and bandwidth usage) and the autonomous agent (by allowing it to focus its resources on more valuable content). The principle of guiding autonomous systems to interact efficiently with their environment, conserving resources while achieving their objectives, is a cornerstone of sustainable innovation across all technological sectors.
The Evolution of Autonomous System Directives
The robots.txt protocol, established in 1994, is a testament to the foresight regarding the need for governance over autonomous systems. Its enduring relevance, even amidst rapid technological advancement, highlights foundational principles that continue to evolve in more complex contexts.
From Simple Rules to Complex AI Governance
The initial robots.txt guidelines were simple, declarative rules for relatively unsophisticated web crawlers. Today, autonomous agents range from advanced AI models capable of complex decision-making to sophisticated physical robots interacting with the real world. While robots.txt remains specific to web crawling, the underlying concept of defining operational boundaries and communication protocols for autonomous entities has expanded significantly. In fields like autonomous navigation, AI-driven data analysis, or remote sensing, developers establish far more intricate “rulesets” or “safe operating envelopes” to govern AI behavior, ensure ethical operation, and manage data acquisition. These modern governance frameworks, while technically distinct, share the philosophical lineage of robots.txt: providing clear, machine-readable instructions to autonomous systems to ensure beneficial and controlled interactions within their respective environments.
Future Directions for Robot Protocols
As technology continues to advance, the complexity and autonomy of robots—both digital and physical—will only increase. This necessitates the evolution of more sophisticated protocols for managing their behavior, data interactions, and resource consumption. Concepts derived from robots.txt, such as user-agent specificity, disallow directives, and sitemap guidance, could see parallels in future frameworks. Imagine autonomous mapping drones being directed by “geo-fencing.txt” files indicating no-fly zones or data-collection restrictions in certain areas. Or AI agents accessing federated datasets being guided by “data-access.txt” protocols specifying permissible queries or usage limitations. The ongoing challenge for tech and innovation will be to develop standards that are robust, flexible, and scalable enough to govern increasingly intelligent and independent autonomous systems, ensuring they operate efficiently, ethically, and in alignment with human intent. The humble robots.txt file, in its simplicity and effectiveness, offers a foundational blueprint for navigating this complex future.