
The landscape of digital creation is undergoing a profound transformation, spearheaded by the remarkable capabilities of Artificial Intelligence (AI) in generating images. What began as a nascent curiosity in machine learning research has rapidly evolved into a sophisticated toolkit capable of producing visuals ranging from photorealistic scenes to abstract art, all from simple text prompts or existing visual cues. This innovation stands as a testament to advancements in computational power, algorithmic design, and the ever-expanding datasets that fuel modern AI. It’s a field that not only pushes the boundaries of digital art but also redefines processes across design, simulation, and communication, marking a significant milestone in technology and innovation.
The Dawn of Algorithmic Creativity
The concept of machines creating art or images has long been a subject of science fiction, but recent breakthroughs in AI have brought this vision into tangible reality. At its core, AI image generation involves algorithms learning patterns, styles, and structures from vast collections of existing images. This learning process enables the AI to synthesize new images that adhere to specified parameters or interpretations of descriptive text. It’s a complex interplay of mathematics, statistics, and neural networks, culminating in a creative output that can often be indistinguishable from human-made work.
Early forays into generative AI were foundational, laying the groundwork for the more advanced models we see today. Initial systems struggled with coherence and realism, often producing surreal or distorted outputs. However, with continuous research and development, particularly in the areas of deep learning and neural network architectures, the quality and control over generated images have dramatically improved. This evolution has democratized artistic creation, allowing individuals without traditional artistic skills to conceptualize and materialize complex visual ideas with unprecedented ease.
Fundamental Principles of Image Synthesis
At a high level, AI image generation models analyze immense datasets of images and their corresponding textual descriptions. They learn to map specific words and phrases to visual attributes, styles, and compositions. When a user provides a text prompt—for example, “a cyberpunk city at sunset with flying cars and neon signs”—the AI model draws upon its learned understanding to construct a novel image that visually represents that description. This process often involves navigating a complex “latent space,” a high-dimensional mathematical representation where different visual concepts are encoded and interrelated. The AI essentially navigates this space, guided by the prompt, to find or synthesize the optimal visual representation. This fundamental capability is what positions AI image generation as a pivotal innovation in modern technology, offering transformative potential across various industries.
Core Technologies Driving AI Image Generation
The spectacular progress in AI image generation is underpinned by several key technological advancements, primarily in neural network architectures. Two dominant paradigms have emerged, each with its unique approach to synthesizing visuals: Generative Adversarial Networks (GANs) and Diffusion Models. Understanding these core technologies is crucial to appreciating the sophistication and potential of AI’s creative capabilities.
Generative Adversarial Networks (GANs)
Introduced in 2014, Generative Adversarial Networks marked a significant leap forward. GANs operate on a unique “adversarial” principle, involving two neural networks: a generator and a discriminator. The generator’s task is to create new images, initially producing random noise that gradually becomes more structured. The discriminator, on the other hand, is trained on a dataset of real images and its job is to distinguish between real images and those generated by the generator.
This setup creates a continuous competition: the generator tries to produce images convincing enough to fool the discriminator, while the discriminator constantly improves its ability to detect fakes. Through this iterative game, both networks improve. The generator becomes adept at creating increasingly realistic and coherent images, and the discriminator becomes a highly sensitive judge of authenticity. Early GANs were instrumental in tasks like generating faces of non-existent people, style transfer, and image-to-image translation. While powerful, GANs often faced challenges with training stability and mode collapse, where the generator might only produce a limited variety of outputs.
Diffusion Models
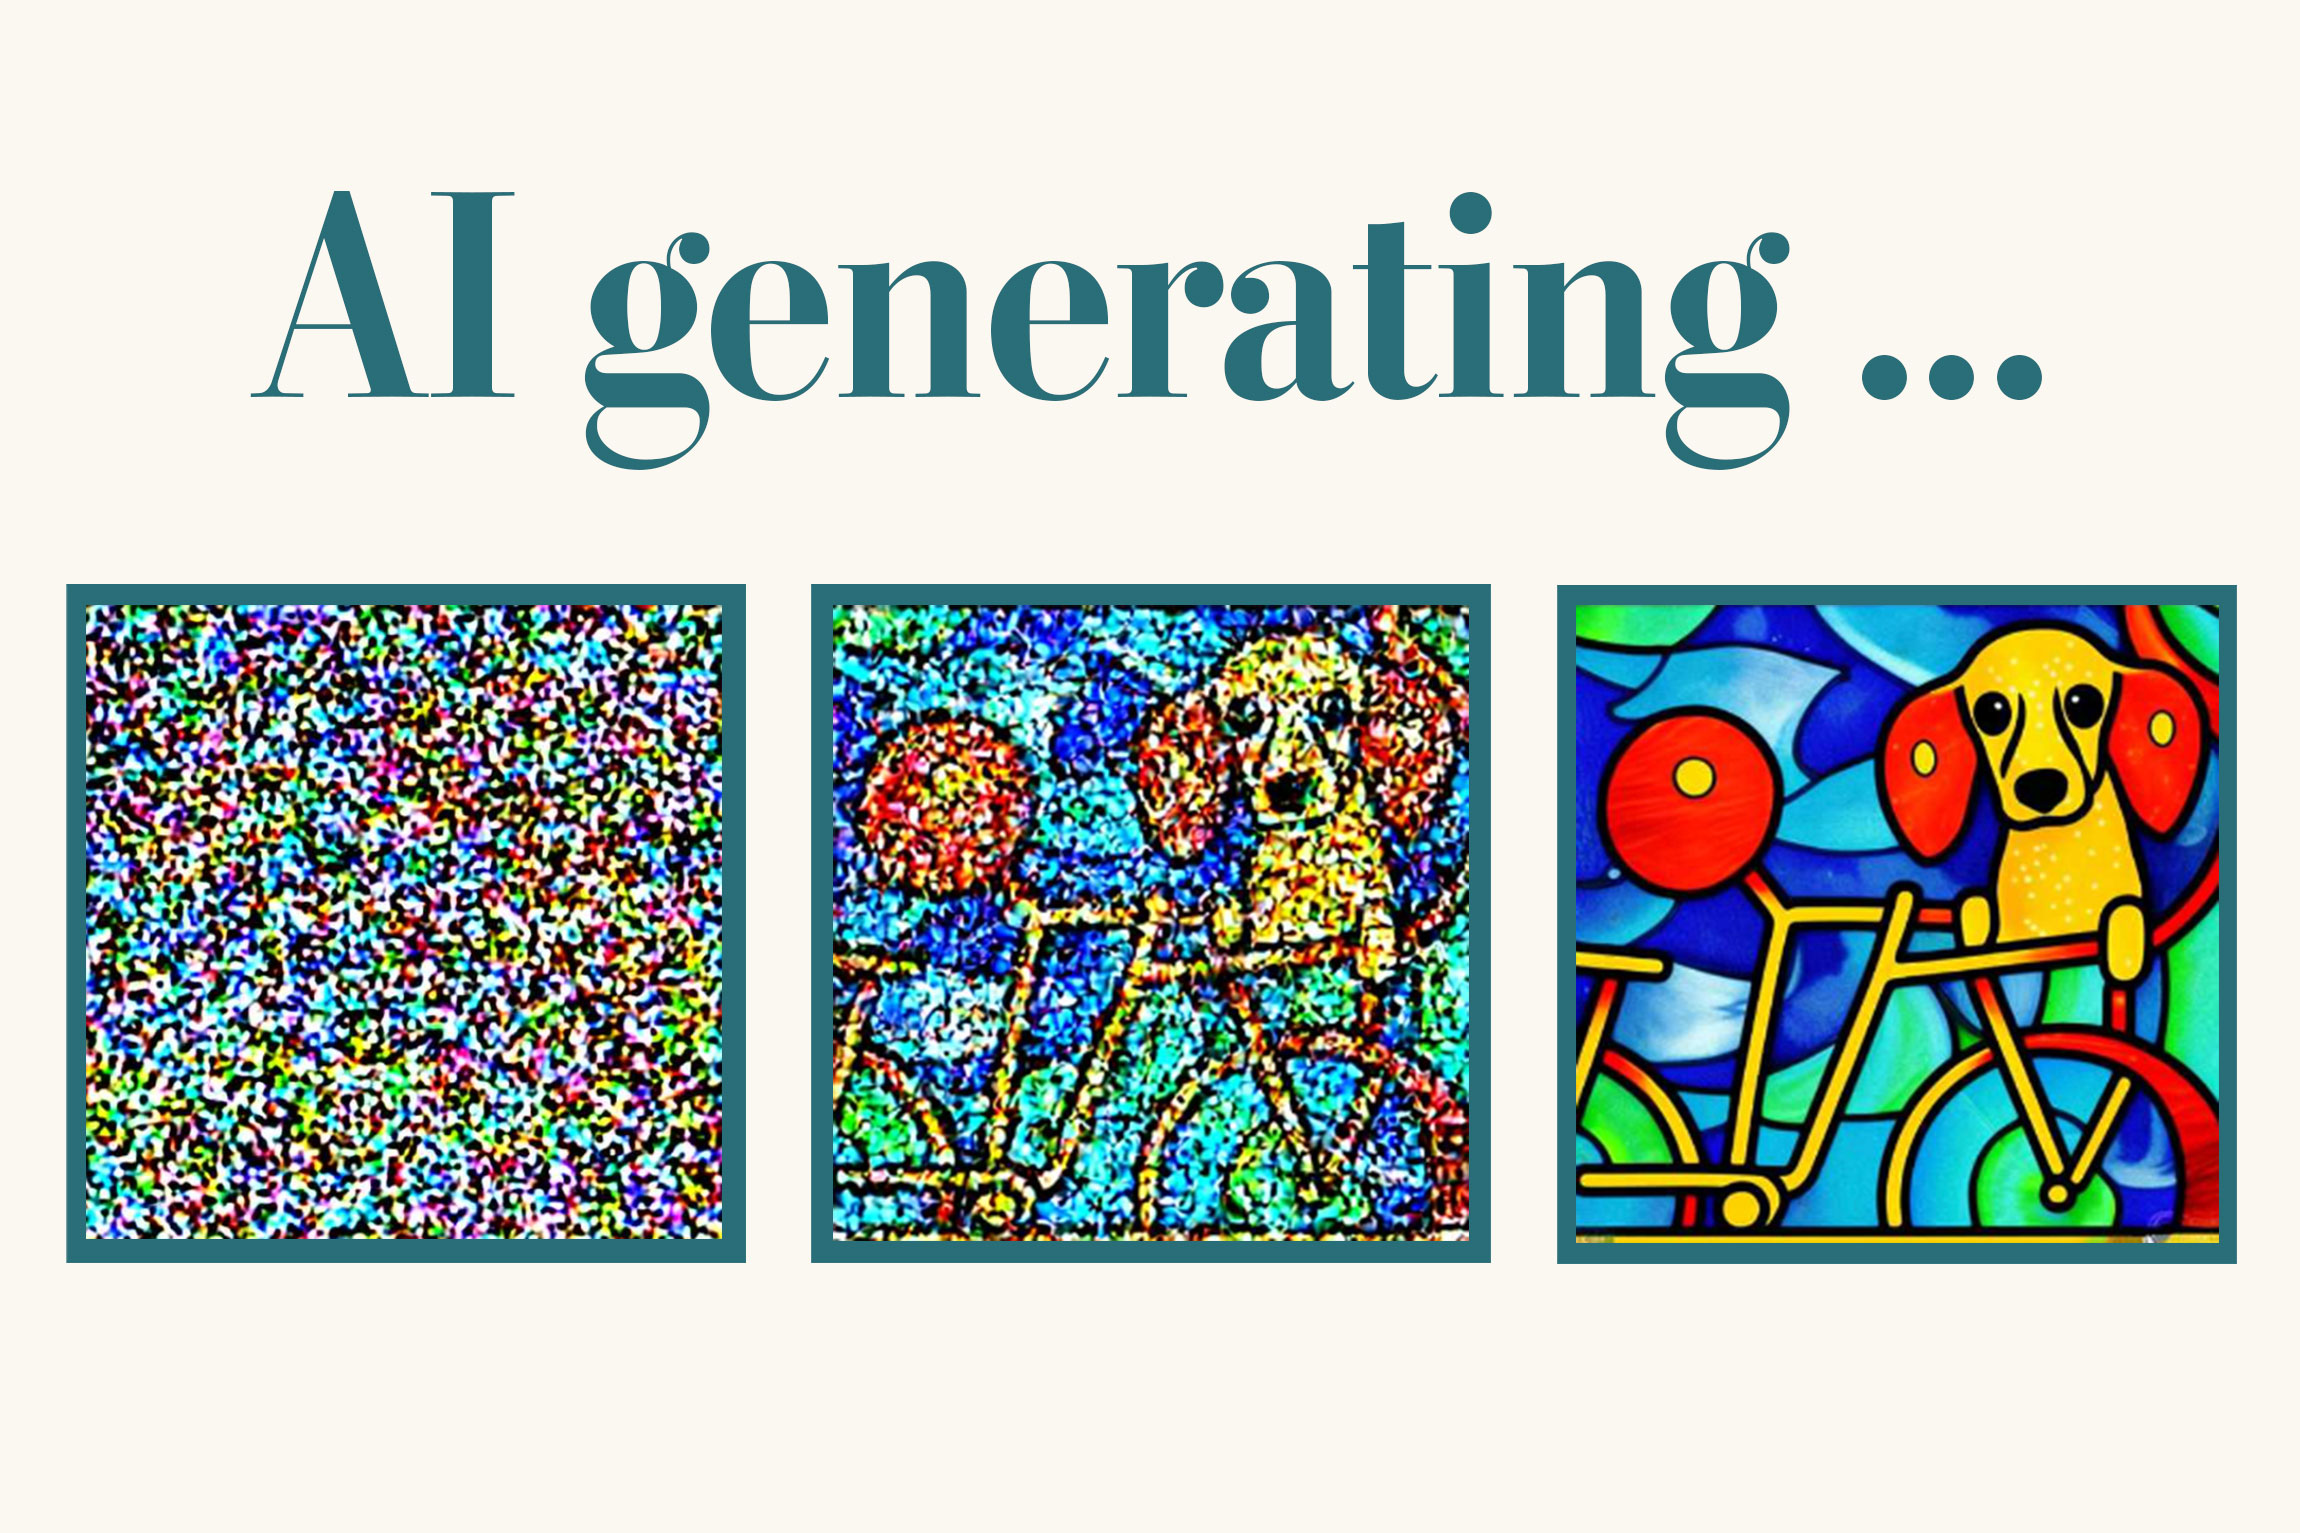
More recently, Diffusion Models have surpassed GANs in their ability to generate high-quality, diverse, and controllable images, becoming the backbone of popular platforms like DALL-E 2, Midjourney, and Stable Diffusion. Diffusion Models work on a principle inspired by thermodynamics: they learn to reverse a gradual process of adding noise to an image.
In the training phase, an image is progressively corrupted by adding Gaussian noise over many steps until it becomes pure noise. The model then learns to reverse this process, step by step, by predicting and removing the noise to reconstruct the original image. During inference (when generating a new image), the process starts with pure random noise, and the model iteratively denoises it, guided by a text prompt, until a coherent image emerges. This iterative denoising process allows for incredibly fine-grained control and results in remarkably high-fidelity and diverse outputs. Their robustness, ability to handle complex prompts, and superior image quality have positioned Diffusion Models at the forefront of AI image generation research and application.
Transformer Architectures and Latent Spaces
Beyond GANs and Diffusion Models, the broader advancements in deep learning, particularly the advent of transformer architectures, have played a critical role. Transformers, initially developed for natural language processing (NLP), enable AI models to understand and process long-range dependencies in data, which is crucial for interpreting complex text prompts and translating them into visual concepts. These architectures help bridge the gap between human language and visual generation, allowing for nuanced and contextually rich image synthesis.
Furthermore, the concept of a “latent space” is central to how these models operate. It’s a compressed, abstract representation of the data where semantically similar images or concepts are located close to each other. By manipulating this latent space—often guided by text embeddings derived from transformer models—AI can explore a vast array of potential images and generate novel combinations of attributes, styles, and themes. This sophisticated interplay of cutting-edge neural network designs is what empowers AI to bring imaginative concepts into visual reality, pushing the boundaries of what’s possible in digital creation and innovation.
Applications and Transformative Impact in Tech

The implications of AI-generated images extend far beyond digital art, permeating various sectors of technology and innovation. Their ability to rapidly produce diverse and high-quality visuals is catalyzing new workflows, fostering unprecedented creativity, and solving complex problems across industries.
Design and Prototyping
AI image generation has become an invaluable tool in the design and prototyping phases across architecture, industrial design, and fashion. Designers can input simple text descriptions or rough sketches to instantly generate multiple design variations, mood boards, and concept art. This accelerates the ideation process, allowing for rapid iteration and exploration of aesthetic and functional possibilities without the need for extensive manual rendering. For instance, an architect can visualize different façade styles or material combinations for a building in minutes, or a product designer can mock up various forms and finishes for a new device. This efficiency significantly reduces time-to-market and fosters a more experimental approach to design.
Content Creation and Marketing
For content creators, marketers, and advertisers, AI image generation offers a paradigm shift in visual asset production. The ability to create unique, high-quality images on demand eliminates the constraints of stock photography and lengthy commissioning processes. Businesses can now generate bespoke visuals for social media campaigns, blog posts, advertisements, and website headers that perfectly match their brand identity and message. This democratizes access to professional-grade imagery, enabling even small businesses or individual creators to produce compelling visual content that stands out in a crowded digital landscape. It also allows for hyper-personalized marketing content, where visuals can be tailored to specific audience segments based on their preferences and demographics.
Data Augmentation and Synthetic Data Generation
In the realm of AI development itself, generated images play a crucial role in data augmentation and synthetic data generation. Training robust AI models, especially for computer vision tasks like object recognition, requires enormous datasets. However, real-world data can be scarce, expensive to acquire, or contain privacy concerns. AI image generators can create vast quantities of synthetic images that mimic real-world scenarios but are entirely artificial. For example, autonomous drone systems often require extensive training data to recognize obstacles, identify landing zones, or perform inspections. AI can generate countless variations of these scenarios—different lighting conditions, weather, angles, and object placements—to augment real datasets, making the trained models more resilient and accurate in diverse operational environments. This capability is critical for accelerating the development and reliability of advanced robotic and autonomous systems.
Enhancing Drone-Related Visuals and Simulation
While AI generates images, it doesn’t do so from a drone’s perspective directly without human input. However, AI-generated images have significant applications for drone technology. They can be used to simulate realistic environments for training drone pilots or testing autonomous flight algorithms in virtual spaces. By generating diverse landscapes, urban settings, and potential obstacles, developers can rigorously test drone software without the risks and costs associated with physical flight tests. Furthermore, AI-generated concept art can be used to visualize futuristic drone designs, potential applications for aerial photography, or even create compelling marketing materials that showcase drone capabilities in imaginative ways. This innovative application bridges the gap between conceptualization and practical application, allowing for rapid visualization and iteration within the drone industry’s tech and innovation spheres.
Challenges, Ethics, and The Future Landscape
Despite the incredible advancements and widespread applications, AI image generation is not without its challenges, ethical considerations, and ongoing evolutionary trajectory. Navigating these complexities is crucial for ensuring the responsible and beneficial integration of this technology into society.
Ethical Considerations
The power of AI to generate highly realistic or even hyper-realistic images brings forth a host of ethical dilemmas. One primary concern is the potential for misuse, particularly in generating deepfakes—synthetic media that can portray individuals doing or saying things they never did. This raises serious questions about misinformation, reputation damage, and the erosion of trust in visual evidence. Copyright is another significant issue; as AI models are trained on vast datasets of existing art, questions arise about intellectual property ownership of the generated output and fair compensation for original creators whose work contributed to the AI’s learning. Furthermore, AI models can inadvertently perpetuate biases present in their training data, leading to generated images that reflect or amplify societal stereotypes, particularly concerning race, gender, and culture. Addressing these biases requires careful curation of training data and robust algorithmic oversight.
Technical Hurdles and Creative Control
While current AI models produce impressive results, technical hurdles persist. Maintaining perfect consistency across multiple images, understanding extremely nuanced or abstract prompts, and accurately rendering complex compositions can still be challenging. Achieving precise creative control, where an artist can dictate every minute detail without extensive prompt engineering or post-processing, remains an active area of research. The models can sometimes “hallucinate” details or misinterpret intentions, requiring iterative refinement of prompts or manual adjustments. Furthermore, the computational resources required for training and running these advanced models are substantial, limiting accessibility for some users.
The Evolving Role of Human Creativity
AI image generation fundamentally redefines the role of human creativity. Instead of solely being a painter, sculptor, or photographer, the human becomes a “prompt engineer,” a curator, or a director of AI. The creative process shifts from direct execution to conceptualization, guidance, and refinement. This evolution opens new avenues for artists and designers, allowing them to explore ideas rapidly and manifest visions that might otherwise be beyond their technical artistic skills. However, it also sparks debates about the definition of artistry and the value of human skill in a world where machines can generate visuals with increasing proficiency. The future likely involves a synergistic relationship, where AI serves as a powerful co-creator and tool, amplifying human ingenuity rather than replacing it.
Future Innovations
The trajectory of AI image generation points towards even more sophisticated capabilities. We can anticipate real-time image generation from prompts, making interactive visual storytelling and virtual environment creation more fluid. The ability to generate complex 3D models and environments directly from text is on the horizon, promising to revolutionize industries like gaming, film production, and architectural visualization. Deeper integration with augmented reality (AR) and virtual reality (VR) systems could allow for dynamic, on-the-fly content creation within immersive experiences. Personalized content generation, tailored to individual user preferences and historical data, will likely become more prevalent in entertainment and marketing. As AI models continue to grow in complexity and understanding, the boundary between what is real and what is synthetically generated will become increasingly blurred, pushing the very definition of visual communication and artistic expression within the broader landscape of technology and innovation.