
In the vast and intricate landscape of modern technology, data is the lifeblood that fuels innovation, drives decisions, and underpins nearly every digital interaction. From complex AI algorithms to the simplest user profile, the ability to store, retrieve, and manage data efficiently and reliably is paramount. At the core of this data management infrastructure, particularly within relational databases, lies a fundamental concept: the primary key. Far more than a mere identifier, the primary key is a cornerstone of data integrity, relationship management, and system performance, embodying a principle of unique identification that is critical for any robust technological endeavor.

The Foundational Role of Primary Keys in Data Management
A primary key serves as a unique identifier for each record within a database table. Imagine a vast library where every book needs a distinct call number, or a global shipping network where every package requires a unique tracking ID. The primary key fulfills this exact purpose for data records. Without a reliable mechanism to distinguish one record from another, locating specific information, updating data accurately, or establishing relationships between different sets of information would be an impossible, chaotic task.
The significance of primary keys extends beyond simple identification. They are instrumental in maintaining data integrity, ensuring that each record is distinct and that relationships between tables are accurately formed. This foundational element is what allows relational databases to function as powerful, coherent systems rather than disconnected silos of information. In the context of “Tech & Innovation,” understanding primary keys is crucial because they are the silent workhorses enabling everything from complex data analytics and machine learning model training to the responsive user experiences we’ve come to expect from modern applications. Every piece of software that relies on structured data — which is virtually all of it — implicitly or explicitly leverages the principles defined by primary keys.
Anatomy and Characteristics of a Primary Key
To effectively serve its purpose, a primary key must adhere to several strict characteristics. These properties are not arbitrary rules but rather essential requirements that guarantee the integrity and reliability of the data system.
Uniqueness and Non-Nullability: The Core Principles
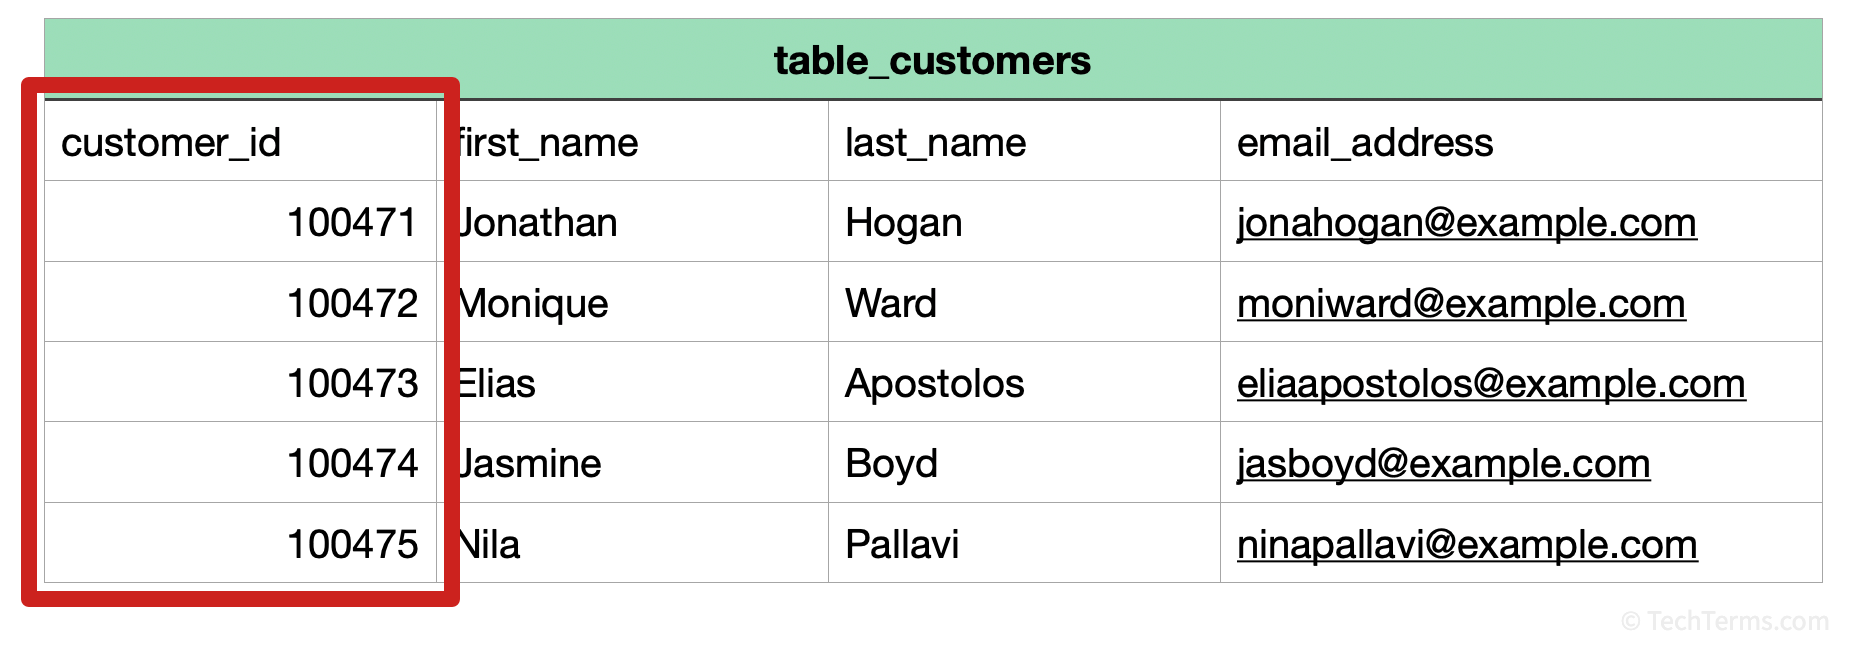
The most critical characteristic of a primary key is its uniqueness. Every value in the primary key column (or combination of columns) must be distinct across all records in the table. This is the very definition of its role: to provide an unambiguous way to identify a single row. If two rows shared the same primary key value, the system would lose its ability to pinpoint a specific record, leading to data ambiguity and potential corruption. For example, in a Customers table, each customer ID must be unique. If two customers had the same ID, their orders, addresses, and personal information could become indistinguishable, rendering the database useless for accurate customer management.
Equally important is the property of non-nullability. A primary key column cannot contain NULL values. A NULL represents the absence of a value, which would contradict the primary key’s role as a definite identifier. If a primary key could be null, it would essentially mean that a record exists without a proper identifier, creating inconsistencies and breaking the fundamental principle of unique identification. Together, uniqueness and non-nullability ensure that every record has one and only one definitive, non-empty identifier.
Immutability: Stability in a Dynamic Data Landscape
While not an absolute rule enforced by all database systems, immutability is a highly desirable characteristic for primary keys. Ideally, once a primary key value is assigned to a record, it should remain unchanged throughout the record’s lifetime. Changing a primary key can have significant cascading effects, especially in relational databases where other tables might reference that key as a foreign key. Such changes would require updates across multiple related tables, increasing the complexity of operations, raising the risk of data inconsistencies, and impacting performance. Designing primary keys that are stable and unlikely to change contributes significantly to the long-term maintainability and reliability of a database system, a crucial consideration in any rapidly evolving tech environment.
Simplicity and Efficiency in Design
Beyond the strict requirements, good primary key design often emphasizes simplicity and efficiency. A primary key should ideally be as short and simple as possible while still fulfilling its unique identification role. Using overly long strings or complex multi-part keys can degrade performance, as these keys are frequently used in indexing, sorting, and joining operations. Simpler keys (e.g., integers) require less storage space and allow for faster comparisons, which translates directly into quicker data retrieval and more responsive applications. This efficiency is critical for scalable tech solutions, where performance under heavy loads can make or break a product.
Types of Primary Keys and Their Implementation
The way primary keys are designed and implemented can vary depending on the data model, application requirements, and database management system. Understanding these variations is key to designing optimized and robust data solutions.
Natural Keys vs. Surrogate Keys: A Design Dilemma
One of the most significant design choices involves opting for natural keys or surrogate keys.
- Natural Keys: These are primary keys derived from existing attributes of the data itself that inherently possess uniqueness and non-nullability. Examples include an employee’s national ID number, a product’s SKU (Stock Keeping Unit), or an email address (if guaranteed unique within the system). The advantage of natural keys is that they are meaningful and directly related to the entity they represent. However, they carry risks: the “natural” attribute might not always be guaranteed unique or stable in the long term (e.g., national ID formats might change, or business rules might evolve allowing multiple employees to share an ID under specific conditions).
- Surrogate Keys: In contrast, a surrogate key is an artificial identifier, typically an integer, generated specifically for the purpose of being a primary key. It has no intrinsic meaning outside of its role as an identifier within the database. Examples include auto-incrementing integers (like
IDENTITYcolumns in SQL Server orAUTO_INCREMENTin MySQL), UUIDs (Universally Unique Identifiers), or GUIDs (Globally Unique Identifiers). Surrogate keys offer superior stability, simplicity, and efficiency. They are guaranteed unique, never change, and are typically compact. The primary drawback is that they lack business meaning, so an extra step might be needed to relate them back to meaningful attributes. In modern tech development, surrogate keys are often preferred for their robustness and ease of management, especially in large, complex systems.
Composite Primary Keys: When Multiple Attributes are Needed
Sometimes, a single column may not be sufficient to uniquely identify a record. In such cases, a composite primary key can be used. This is a primary key that consists of two or more columns whose combined values uniquely identify each row in a table. For instance, in a CourseEnrollments table, neither a StudentID nor a CourseID alone might be unique (a student can take many courses, and a course has many students). However, the combination of (StudentID, CourseID) would uniquely identify a specific student’s enrollment in a specific course. Composite keys are common in junction or linking tables that manage many-to-many relationships. While effective, they are generally less efficient than single-column keys due to increased storage and comparison overhead.
Auto-Incrementing Keys: Streamlining Record Generation
A common and highly efficient implementation of surrogate keys is the auto-incrementing primary key. This mechanism automatically generates a unique, sequential integer whenever a new record is inserted into a table. Features like AUTO_INCREMENT in MySQL, IDENTITY in SQL Server, or SERIAL in PostgreSQL simplify application development by offloading the responsibility of generating unique identifiers to the database itself. This approach virtually eliminates the risk of key collisions and provides a consistent, monotonically increasing sequence that is excellent for performance and management, making it a staple in rapid application development and scalable backend systems.
The Broader Impact: Primary Keys in Relational Database Design
The role of a primary key extends far beyond merely identifying individual records. It is the linchpin that enables the entire relational model, facilitating robust data relationships, enhancing query performance, and ensuring systemic data integrity.
Establishing Relationships with Foreign Keys
The most profound impact of primary keys is their role in establishing relationships between different tables through foreign keys. A foreign key is a column (or set of columns) in one table that refers to the primary key in another table. This link is what creates the “relational” aspect of relational databases. For example, an Orders table might have a CustomerID column that acts as a foreign key, referencing the CustomerID primary key in the Customers table. This allows the system to understand which customer placed which order. Without primary keys to serve as anchors for these relationships, databases would be unable to model complex real-world entities and their interactions, severely limiting their utility for sophisticated applications.
Enhancing Data Retrieval and Performance
Primary keys are almost always indexed by default within a database system. An index is a special lookup table that the database search engine can use to speed up data retrieval operations. Think of it like the index in the back of a book. When you search for a record by its primary key, the database can use this index to quickly locate the specific row without having to scan the entire table. This dramatically improves query performance, which is vital for applications requiring fast access to data, such as real-time dashboards, high-transaction e-commerce platforms, or critical enterprise resource planning (ERP) systems. Efficient data retrieval is a hallmark of high-performance tech solutions, and primary keys are central to achieving it.
Maintaining Data Integrity Across Systems
Primary keys, in conjunction with foreign keys, enforce referential integrity. This means that relationships between tables are consistently maintained. For example, if an order references a CustomerID that does not exist in the Customers table, the database can prevent this invalid insertion or update, thereby ensuring that all relationships are valid. Furthermore, if a customer record is deleted, the database can be configured to either prevent the deletion (if there are associated orders) or to automatically delete related orders (cascading delete). This level of control prevents orphaned records and maintains the consistency and accuracy of the entire dataset, which is critical for trustworthy analytics, regulatory compliance, and the overall reliability of any data-driven innovation.

Beyond Relational: Primary Key Concepts in Modern Data Architectures
While primary keys are a core tenet of relational databases, the underlying principle of unique identification extends to modern, non-relational (NoSQL) data architectures as well. Even in document-oriented databases like MongoDB or key-value stores like Redis, each piece of data or document typically has a unique identifier (often called an _id or similar) that serves a function analogous to a primary key. In distributed systems and big data environments, unique identifiers are crucial for data sharding, replication, and ensuring data consistency across multiple nodes. The fundamental need to uniquely address and manage individual data items remains universal, making the concept of a primary key — regardless of its specific nomenclature or implementation — a timeless and indispensable principle in the ever-evolving landscape of tech and innovation.