
The Architecture of Concurrent Communication Sessions
The intricate dance of digital communication, particularly in real-time video platforms like FaceTime, relies on sophisticated underlying architectural principles to manage concurrent sessions. When an individual initiates a FaceTime call to someone already engaged in another FaceTime conversation, the system doesn’t simply collapse or present a busy signal akin to traditional landlines. Instead, a series of pre-defined protocols and application logic layers spring into action, designed to handle this specific state of simultaneous interaction.
At its core, any modern operating system, whether iOS, Android, or desktop variants, is built to manage multiple processes and network connections concurrently. A FaceTime call, from a technical perspective, is an application process consuming system resources: CPU cycles for encoding/decoding video and audio, memory for buffering data, and network bandwidth for transmitting streams. When a second incoming call attempts to establish a connection, the device’s communication framework first registers this new incoming signal. This isn’t a simple “line busy” scenario because digital communication allows for more nuanced handling. The system doesn’t block the incoming call entirely; rather, it acknowledges it while the primary call remains active.
The innovation here lies in the session management layer. Each FaceTime call establishes a unique session, often leveraging protocols like WebRTC (Web Real-Time Communication) or similar proprietary real-time communication stacks. These stacks manage the entire lifecycle of a call, from connection setup (signaling) to media streaming (audio/video transmission) and session termination. When a second call request arrives, the signaling server routes this request to the recipient’s device. The device’s FaceTime application, already managing an active session, receives this new signaling message.
The immediate technical response is not to interrupt the ongoing data streams of the first call. Instead, the application layer recognizes the presence of an active and incoming call simultaneously. It then prioritizes the ongoing session’s integrity while preparing the user interface and system notifications to present the incoming call as a secondary event. This capability is a testament to resilient network stack design and multi-threading within application development, allowing for continuous media processing for the active call even as new network events are handled. Without such robust architectural considerations, concurrent communication would lead to dropped calls, corrupted audio/video, or system instability. The seamless handling of these parallel states underscores the significant advancements in real-time communication technology, moving far beyond the limitations of single-channel analog systems.
User Experience Design in Concurrent Call Scenarios
Beyond the technical backend, the way an active call recipient interacts with a new incoming FaceTime call while already engaged in another represents a crucial area of user experience (UX) innovation. The design choices made by Apple, and replicated across similar communication platforms, are not arbitrary; they are meticulously crafted to provide clarity, control, and minimal disruption.
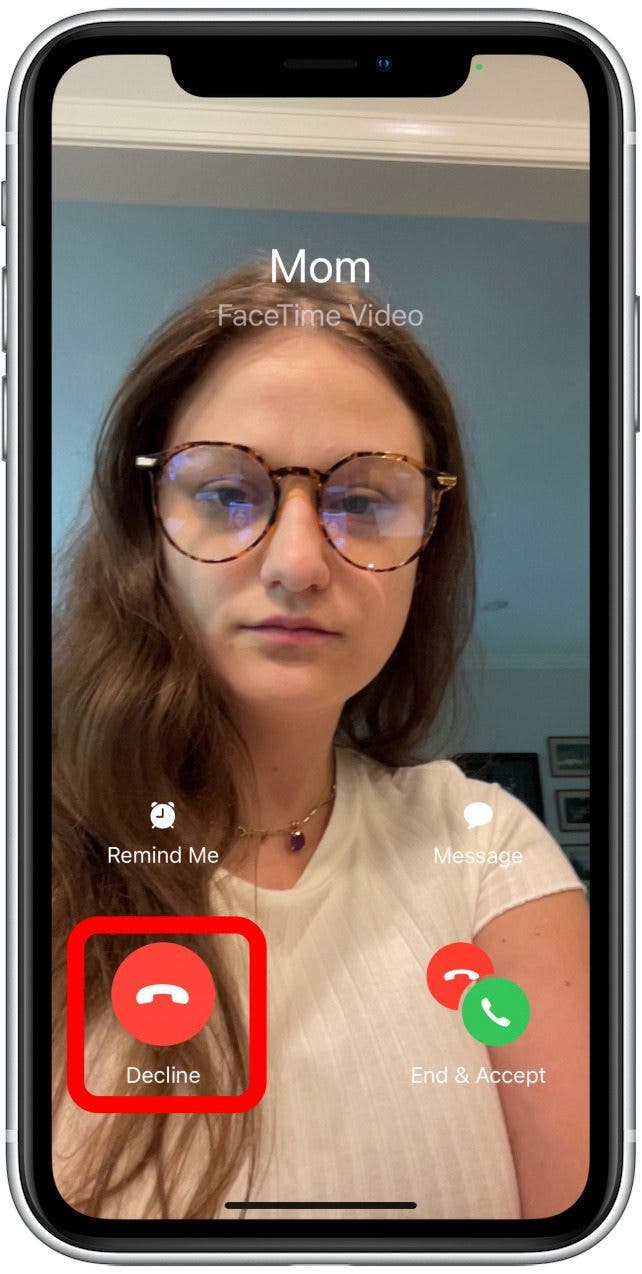
When a user is on an active FaceTime call and receives another FaceTime call, the primary ongoing call is not immediately interrupted. This design decision prioritizes the continuity of the current conversation, recognizing that abrupt disconnections are highly disruptive. Instead, the device typically presents a clear notification of the incoming call. On iOS devices, this often appears as a banner notification at the top of the screen or a smaller, less intrusive overlay, rather than a full-screen takeover that would obscure the current video feed. This visual cue is accompanied by a distinct audio alert, different from the initial incoming call ringtone, signaling a secondary event.
The core of this UX innovation lies in offering the user immediate, actionable choices without forcing a decision. Typically, these options include:
- End & Accept: This option terminates the current FaceTime call and immediately connects to the incoming one. It’s a direct replacement action.
- Decline: This option rejects the incoming call while keeping the current call active. The caller will receive a busy signal or a notification that the call was declined.
- Hold & Accept: This is a more sophisticated option. It places the current FaceTime call on hold (pausing video and audio transmission to that party, though technically the session remains open) and connects to the new incoming call. This allows the user to switch between calls, managing two separate conversations.
The “Hold & Accept” feature is particularly indicative of advanced UX design in telecommunications. It provides flexibility that mimics multi-line phone systems but integrates it into a personal device with visual cues. When a call is on hold, the system must maintain the session state for the held party, often displaying a “call on hold” indicator to them, while simultaneously establishing a new active session. This requires careful management of audio routing, video stream allocation, and user interface elements to clearly indicate which call is active and which is on hold.
The user interface also provides mechanisms to switch back to the held call or merge calls, adding layers of complexity that enhance user control. These design decisions aim to empower the user, allowing them to manage their communications flow rather than being dictated by technology. This focus on user agency, coupled with intuitive visual and auditory feedback, is a hallmark of thoughtful tech and innovation in human-computer interaction, ensuring that even complex multi-session scenarios remain manageable and user-friendly.

Network Protocol Layering and Call State Management
The seamless management of concurrent FaceTime calls is deeply rooted in the sophisticated interplay of network protocol layering and the application’s intricate state management logic. Understanding this technical backbone reveals the ingenious engineering behind modern real-time communication.
At the lowest practical layer for real-time communication, protocols like RTP (Real-time Transport Protocol) and RTCP (RTP Control Protocol) are responsible for transmitting the actual audio and video data streams. Each FaceTime call establishes its own set of RTP/RTCP streams, ensuring the delivery of media packets with appropriate timing and quality-of-service considerations. When a second call is initiated, a new set of these media streams is prepared for establishment, distinct from the first.
Above the media transport, signaling protocols manage the setup, modification, and termination of calls. While FaceTime uses proprietary signaling protocols within Apple’s ecosystem, the principles are akin to industry standards like SIP (Session Initiation Protocol) or WebRTC’s signaling mechanisms. When an incoming call arrives while another is active, the signaling server informs the recipient’s device of a new pending session. The device’s FaceTime application, operating at the application layer, then interprets this signal in the context of its current state.
Crucially, the application maintains a detailed “call state” for each potential and active conversation. For the primary call, the state is “active” or “connected.” For the incoming call, its initial state might be “ringing” or “pending.” When the user chooses “Hold & Accept,” the application transitions the first call’s state from “active” to “on-hold.” This “on-hold” state is not a full termination; it signifies a temporary suspension of media flow and interaction, yet the network connection and session context remain alive. Simultaneously, the new call transitions from “pending” to “active.”
This state management extends to resource allocation. While a call is on hold, its consumption of CPU for encoding/decoding is minimized, and its network bandwidth usage for media might drop significantly or halt entirely, depending on implementation. However, the connection is kept alive, allowing for a rapid resumption of media streams if the user switches back. This minimizes the overhead of re-establishing a full connection. Furthermore, the handling of network address translation (NAT) and firewall traversal, often managed by protocols like STUN/TURN/ICE (Session Traversal Utilities for NAT, Traversal Using Relays around NAT, Interactive Connectivity Establishment), must also account for multiple concurrent sessions, ensuring that media packets for the correct call reach their intended destination without collision or blockage. This layered approach, with robust state machines at the application level coordinating with underlying network protocols, is fundamental to providing a stable and flexible multi-call experience.
Innovations in Multi-Modal and Context-Aware Communication
The current capabilities of handling concurrent FaceTime calls are a foundational step towards a future of even more sophisticated and intelligent communication systems. The experience of managing multiple calls simultaneously hints at broader innovations in multi-modal and context-aware communication, where technology anticipates needs and facilitates interactions with greater fluidity.
One significant area of innovation building upon this foundation is the integration of AI-driven context awareness. Imagine a scenario where, upon receiving a second incoming call while already engaged, the system analyzes metadata from both calls – sender identity, calendar entries, location, recent communication patterns – to offer more intelligent suggestions. Instead of just “Decline” or “Hold & Accept,” it might suggest: “This is your doctor; automatically send a message to current caller saying ‘I’ll call you back in 5 minutes.'” or “This is a recurring meeting; join with current call minimized to audio only.” This moves beyond simple state management to proactive, personalized assistance.
Further innovation will also likely revolve around seamless transition across devices and modalities. Currently, a FaceTime call is tied to a specific device. In the future, the concept of a “call” might become more fluid, easily transferable between a phone, a tablet, a smart display, or even an augmented reality headset without interruption. A user might begin a video call on their phone, receive another call, put the first on hold, answer the second on a smart display in another room, and then merge them or switch back, all with an intuitive gesture or voice command. This “spatial computing” approach to communication unifies the digital and physical interaction environments.
Multi-party, multi-stream integration is another frontier. While FaceTime already supports group calls, the ability to manage private side conversations within a larger group call, or to seamlessly switch between different groups or individuals without ever “ending” a session, represents a powerful evolution. This could involve dynamically allocating screen real estate, managing complex audio mixing for multiple simultaneous speakers, and providing advanced moderation tools that are intelligent enough to discern who needs to be heard and when.
Finally, the underlying network protocols and system architectures will continue to evolve to support even higher bandwidth, lower latency, and greater reliability for these complex, multi-layered communication scenarios. Technologies like 5G and Wi-Fi 6/7 are critical enablers, providing the necessary robust infrastructure. The innovation in handling concurrent FaceTime calls today is a glimpse into a future where communication platforms are not just tools for connection, but intelligent, adaptive extensions of our social and professional interactions, offering unparalleled flexibility and contextual intelligence.